2026-09-27 · 27 min · 3d · point-cloud · computer-vision · video-understanding · slam · benchmarks
Why read this
Notabletop 60%Explains TrackEverything's voxel de-duplication and 3D WAFT, then checks its claims: the 20-point lead is APD-P over one baseline, 10+ FPS excludes geometry.
- Checked against the source
- A lasting reference
- A new technique
3D & spatialNeeds a workstation GPUResearch paper
How this was scored
- Is it new?
- 2 of 3: A real new idea, method or capability
- Can I trust it?
- 3 of 3: Reproduces the headline result, or shows from primary files it is wrong
- Can I run it?
- 0 of 3: Closed, nothing to run
- Will I understand it?
- 2 of 3: Mechanism from first principles with figures
- Can I act on it?
- 1 of 3: General advice
- Will it last?
- 2 of 3: A reference for a year or more
- Does it affect many?
- 1 of 3: A specialist community
- Only here?
- 2 of 3: A teardown or measurement few others did
Score 60 of 100, ranked 394 of 701 rated articles. Each question is answered 0–3 by hand, and a 3 is rare. How articles are scored
A repost on X summed TrackEverything up in five claims. It treats the video as a 3D scene and removes duplicate points. It separates static from dynamic points and tracks the moving ones efficiently. 3D WAFT makes 4D correlation efficient. It runs at 10+ FPS on a 40 GB GPU. It tracks 1000+ frame videos.
The paper is TrackEverything: Long Horizon Dense Tracking via De-Duplicating 3D Scene Representations (arXiv 2609.30222, posted 24 September 2026), by Ayush Jain, Sreeharsha Paruchuri, Ishita Gupta, Fan Zhang, Tanner Schmidt, Jakob Engel, Katerina Fragkiadaki and Adam W. Harley, of Carnegie Mellon and Meta. I read v1 and the project page.
Three hold as written. WAFT does not make correlation efficient; it removes the correlation volume. The frame rate is the tracker's alone: with its geometry model in the loop, the paper's end-to-end figure is 7.2 FPS. The code was not out when I first wrote this; it came out on 20 October, and the section on it checks it against the paper.
The idea underneath is an old one from SLAM: store the world, not the observations. The map in FAST-LIO2 from scratch downsamples each new scan into voxels it already has. TrackEverything does that to a point tracker's memory.
Why dense tracking forks in two
A point tracker takes a pixel at time and returns where that bit of surface is in every other frame. Count what "every point" means for frames of pixels.
- Sparse trackers follow user-chosen points: positions. PIPs, CoTracker3, TAPIP-3D and SpatialTracker-v2 run in sliding windows and refine each point against a correlation lookup (its feature against the features around its current guess). That runs for long videos, but the correlation cost scales with , so stays small.
- First-frame dense trackers make every pixel of frame 0 a query: positions. Linear in , and blind to anything that appears later, like a person who walks in.
- All-frame dense trackers make every pixel of every frame a query: tracks, each with a position in all frames, so outputs. The paper's example is a 512 × 512, 200-frame video at "on the order of predictions" (512 × 512 × 200 × 200 is about 1.05 × 10¹⁰, reasoned). VDPM, TraceAnything and D4RT aim here and stop at clips of 48-64 frames.
Memory grows with length because the representation is frame-local. Every frame arrives as a full grid of tokens whether it shows anything new or not: a camera panning across a desk re-encodes the same desk every frame. Tokens grow as for tokens per frame, and whatever correlates tracks against frames grows faster. RAFT's all-pairs correlation volume for two frames holds similarities, one per pair of feature pixels, hence "4D". At an eighth of a 512 × 512 frame's resolution that is 4,096² ≈ 16.8 million entries, 67 MB in fp32 per pair; at a quarter, TrackEverything's feature resolution, sixteen times that, about 1.07 GB (both reasoned).
The way out follows from what a video is: 2D projections of one 3D world. The desk is one desk. Keep state per piece of surface in world coordinates, and a frame that re-observes the desk adds nothing.
A persistent world-frame scene track
A scene track is a token that stands for a piece of physical surface rather than a pixel. It carries:
- a feature vector, wide;
- its birth: the source frame and the 3D point where it was first seen;
- its current 3D position in world coordinates: the frame of the first camera, scaled once for the whole sequence to unit size, DUSt3R-style;
- a visibility per frame and one static-or-dynamic label.
Persistent means it survives occlusion and leaving the frame: once born, it stays in the scene memory. World frame means a static point does not move when the camera does, so its whole trajectory is one 3D point, not of them. That is where the static/dynamic split gets its savings. For all unique scene points the model outputs trajectories , visibility logits and static/dynamic logits .
How it works
The inputs are an RGB video and a per-frame pointmap, a 3D world point for every pixel, from depth sensors or a feedforward model: VGGT-Ω in the main results (the model WorldCrafter is checked with), Pi3 in some ablations. The tracker never estimates geometry or poses itself (compare Depth Anything 3 in ROS 2, where the metres also come from outside the model).
Encoding one window
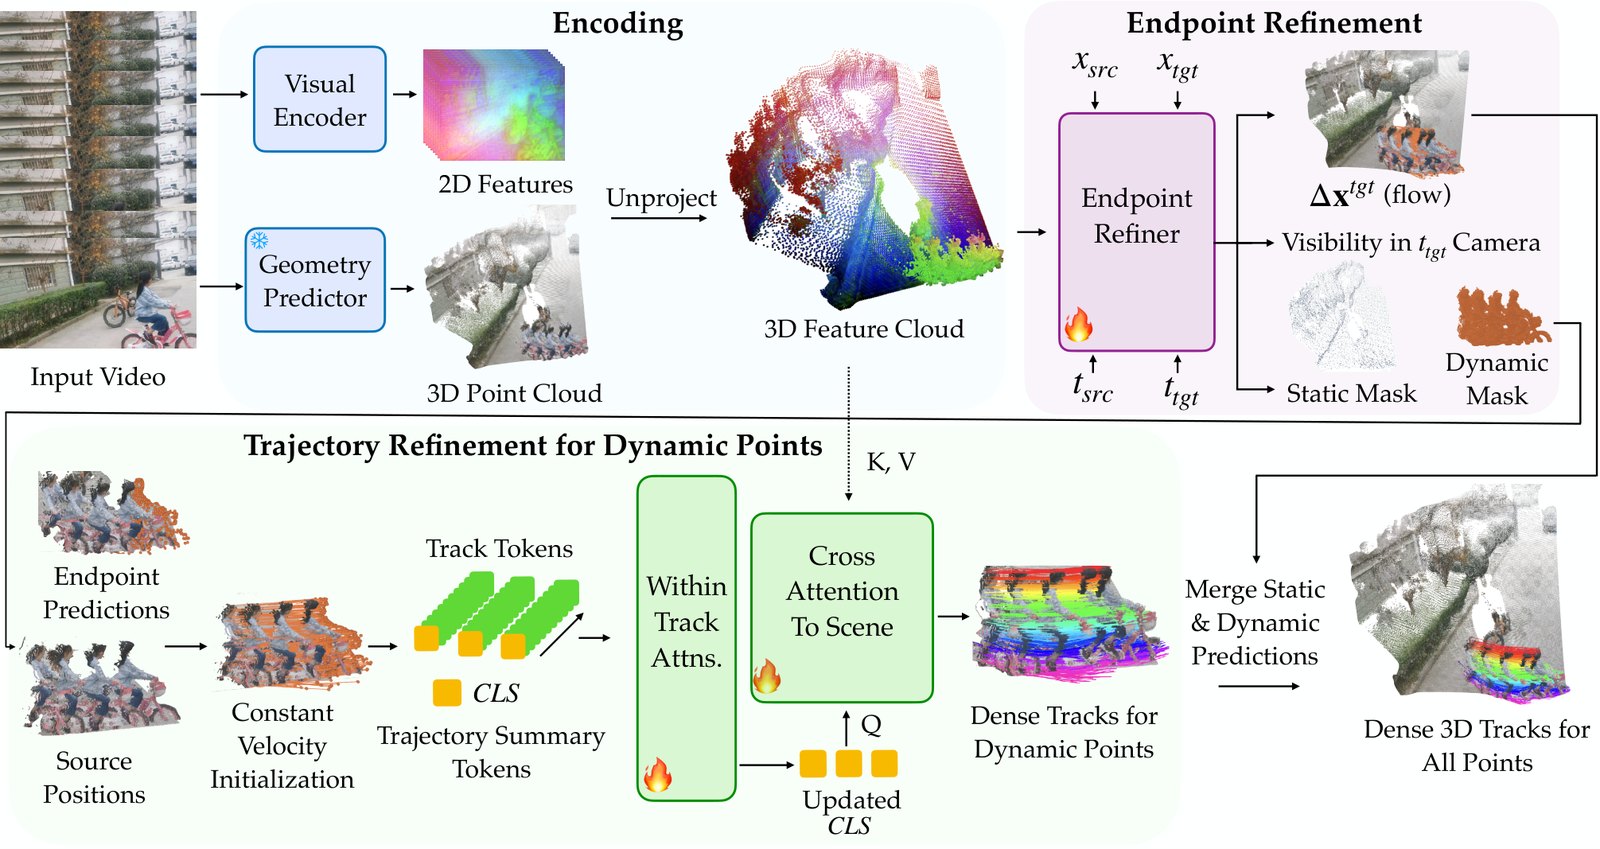
The video is cut into non-overlapping windows of frames. A frozen DINOv3-small (20M parameters) plus a trainable ViT-Adapter head turns each frame into a feature map at a quarter resolution, tokens of width 384. Each token is paired with the 3D point under it from the downsampled pointmap.
Within each frame, tokens are quantised into voxels of size (index ) and tokens sharing a voxel are mean-pooled. Only within a frame: two surfaces can occupy the same place at different times, as when a hand passes where a cup was. The 16 frames' tokens join the tokens carried over from earlier windows (their is ) in one space-time cloud.
The endpoint refiner
To hand points to the next window and merge duplicates, the tracker only needs each point's position at the window's last frame, so it solves that first. At inference the target frame is always .
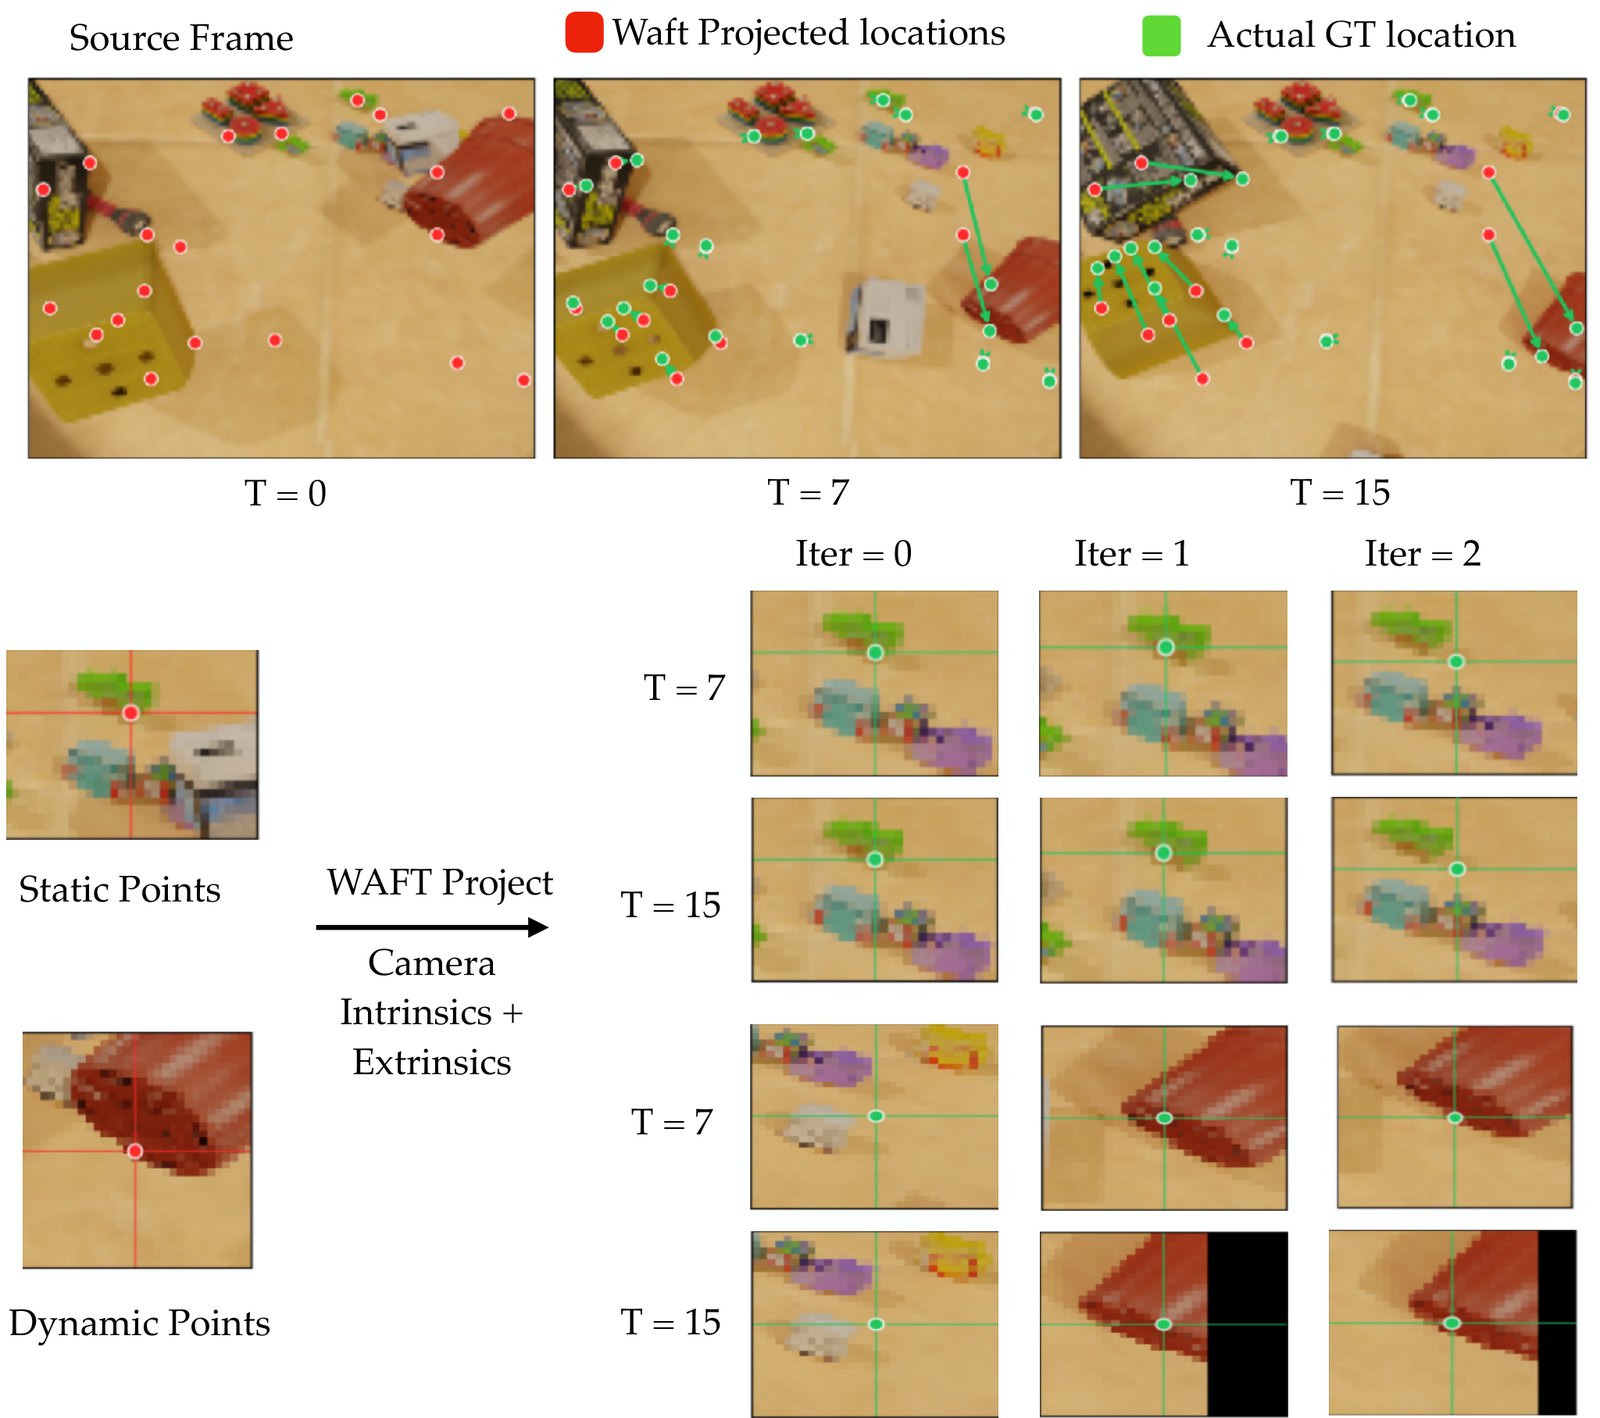
Each point's feature gets four sinusoidal embeddings: source position, current guess of the target position, source frame, target frame. Then 3D WAFT: the 3D guess is projected into frame with that camera's intrinsics and extrinsics, and the feature map is bilinearly sampled there, giving . The feature at the point's birth, , is sampled once. The transformer sees , runs self-attention over the whole cloud, and a small MLP decodes a 3D update , a visibility logit and a static/dynamic logit. The guess moves, is resampled, and the loop runs again. The paper does not state the iteration count; its Figure 6 shows three.
What WAFT is
WAFT, Warping-Alone Field Transforms (Yihan Wang and Jia Deng), is optical flow built like RAFT without the cost volume. Instead of correlating every pixel with every other, it warps the second image's features by the current flow estimate, at high resolution, and lets the network compare them with the first image's. Its abstract reports first place on Spring, Sintel and KITTI at lower memory cost.
In 3D the warp is a camera projection of the 3D guess. The signal is template matching: if looks like , the guess is on the right surface; if not, it must move. Each point costs one feature vector per iteration, not a volume. A guess that projects off-screen is clamped to an extended canvas and sampled with replicate padding; the mismatch is what the visibility head learns to read as "not visible". (The paper expands WAFT as "warp-aligned feature transforms"; the paper it cites is titled Warping-Alone Field Transforms. Same method.)
The trajectory refiner, for moving points only
Only points classified dynamic get a full 16-frame trajectory, starting from constant velocity between source and endpoint. Each timestep's token combines the point's transformer feature, its and a feature sampled at that frame's constant-velocity position, plus a [cls] summary token per track. Layers alternate attention along one track's timesteps with cross-attention from its [cls] token to the scene cloud. Tracks never attend to each other (as in PIPs and D4RT), so training can decode a random subset and inference all of them. Static points keep their position.
Misclassification is cheap one way. A static point called dynamic just gets decoded, and can come back with zero motion. A dynamic point called static is frozen for the window, up to 16 frames of missed motion, and is reclassified in the next.
What one window predicts
- Every active point: its 3D position at frame , a visibility logit, a static/dynamic logit.
- Every dynamic point: a 16-frame 3D trajectory and a visibility per frame.
- Every static point: one position, held for the window.
- Updated features for the next window. The loop across windows is the loop across iterations with a new starting point, which is how a model trained on 32- and 64-frame clips runs on 1000-frame videos.
De-duplication at the boundary
At the end of a window every point sits at the same timestep, and the rule that makes cross-frame merging safe applies: two things cannot occupy the same voxel at the same time. The cloud is voxelised at the predicted positions with in normalised scene units, through a sparse hash over , so there is no bounded grid. Tokens in a voxel are mean-pooled and keep the earliest birth. The survivors are the scene memory the next window's frames join.
Each merge also records which voxel every point went into and its offset , so any pixel's full track can be exported by walking the maps back: . The offset is fixed over time, so everything within a voxel moves together.
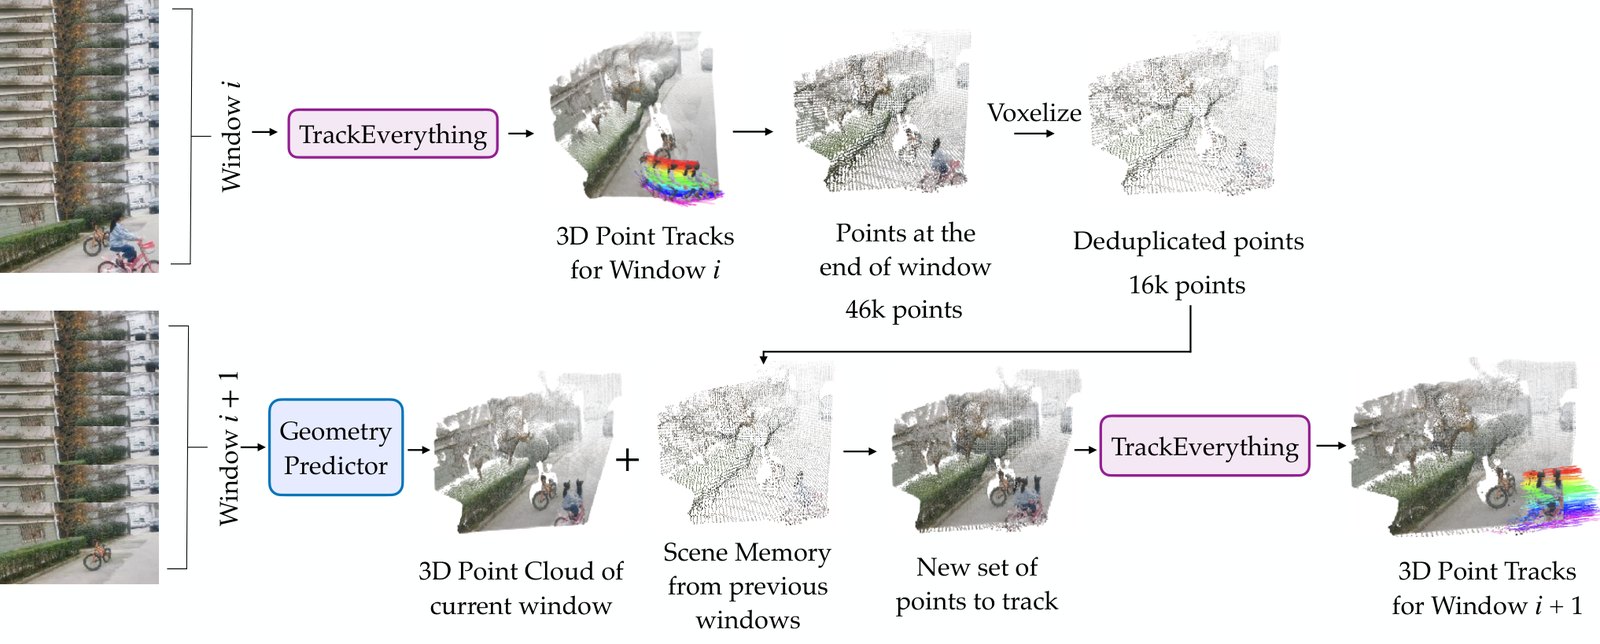
User query points, given as , are never merged. An optional early merge (the
appendix names the switch voxelize_on_endpoints) merges co-located static points after the
first iteration instead of at the boundary; the labels settle in one iteration, so the rest of
the window runs on fewer tokens.
The growth law
Put numbers on it with tokens per frame, windows of , and the fraction of each frame that shows surface never seen before:
is what a frame-local tracker holds, the de-duplicated memory after the last merge, the peak inside the window in flight (memory carried in plus the window's own frames). Both and are linear in ; de-duplication cuts the slope from to . A camera in a room it has already seen has and the memory stops growing. A camera seeing only new ground has , and de-duplication saves nothing.
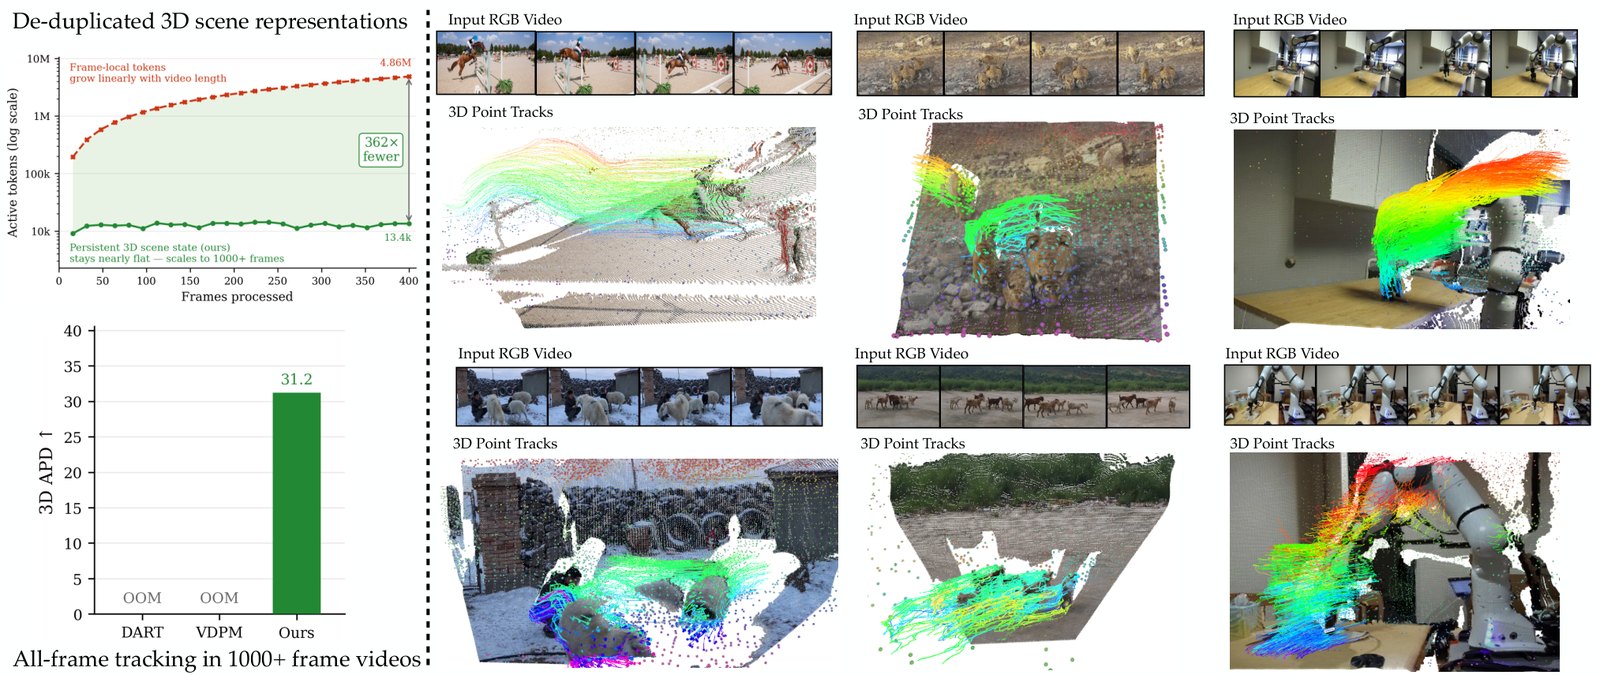
The teaser gives the rate. Its red line reaches 4.86M frame-local tokens at 400 frames, so (reasoned). Its green line ends at 13.4k, 362 times fewer: in this model that clip has of about 0.03%, a camera that reveals very little that is new (reasoned).
At 400 frames and the widget holds 4.86M tokens frame-local, 36.4k in de-duplicated memory and 229.8k at the peak of the last window, 21.1× fewer; at 1,200 frames it is 14.58M against 278.4k, 52.4× (measured in the widget). Two things fall out.
First, the window in flight is a floor: its 16 frames (194,400 tokens at this rate) are held whatever the voxel size, because merging happens only at the boundary. The voxel ablation shows the floor in gigabytes: coarsening from 0.05 to 0.2 moves peak memory only from 11.2 to 10.7 GB (reported). Per-frame voxelisation shrinks it in the real model; the widget leaves that out, so its green lines are an upper bound.
Second, memory still grows with new territory. The limitations section says so ("active memory still continues to expand during perpetual open-world exploration"), and throughput tracks scene extent: the tracker alone runs at 8.4 FPS on Aria Digital Twin's multi-room scenes and 41.5 FPS on Panoptic Studio's single lab (reported).
Checking the results
TAPVid-3D and "over 20% APD"
TAPVid-3D is three datasets: Aria Digital Twin (ADT, egocentric indoor, about 300 frames), DriveTrack (driving, 25-300 frames) and Panoptic Studio (PStudio, about 150 frames), 50 clips each here. Real video has no dense ground truth, so scoring is on annotated query points. APD is the fraction of predictions within a distance of the truth, averaged over thresholds: APD-P uses 1, 2, 4, 8 and 16 pixels unprojected into 3D and is the stricter; APD-M uses 0.1, 0.3, 0.5 and 1.0 m.
On the first 48 frames (paper, Table 1; APD-P per dataset, reported):
| Method | Kind | ADT | DriveTrack | PStudio | Avg APD-P | Avg APD-M |
|---|---|---|---|---|---|---|
| D4RT (closed, its own numbers) | all-frame dense | 40.8 | 41.0 | 49.6 | 43.8 | – |
| VDPM | all-frame dense | 4.8 | 14.7 | 13.1 | 10.9 | 56.8 |
| TrackEverything | all-frame dense | 45.7 | 28.2 | 30.1 | 34.7 | 72.6 |
| DeltaV2 | first-frame dense | 44.3 | 28.4 | 30.4 | 34.4 | 73.0 |
| TAPIP-3D | sparse | 45.6 | 26.7 | 30.0 | 34.1 | 72.2 |
| CoTracker3 | sparse | 43.1 | 29.7 | 29.6 | 34.1 | 72.8 |
Every row but D4RT and VDPM uses VGGT-Ω geometry. What the "over 20% APD" claim is made of:
- It is 34.7 against 10.9, a gap of 23.8 percentage points of APD-P (reasoned). In APD-M the gap is 15.8. So the claim holds for APD-P only.
- The average clears 20 because of ADT (+40.9). On DriveTrack the gap is 13.5, on PStudio 17.0 (reasoned).
- "All open-source all-frame dense 3D trackers" is one method in the table: VDPM. D4RT is ahead by 9.1 APD-P on average, and on DriveTrack and PStudio. The paper says plainly that D4RT has no public code, about 20× the parameters (a 1B backbone and a 144M decoder, against 61M) and private training data.
- Geometry does some of the work; VDPM cannot take external geometry. With Pi3 pointmaps instead of VGGT-Ω, TrackEverything averages 30.2 APD-P (paper, Table 5), 19.3 above VDPM (reasoned), just under the headline.
The more interesting result is the tie. Tracking every point in every frame costs nothing on the annotated points: 34.7 against 34.4 for first-frame DeltaV2 and 34.1 for both sparse trackers.
Long sequences against sparse trackers
On full-length TAPVid-3D (paper, Table 1; all with VGGT-Ω, reported):
| Method | ADT | DriveTrack | PStudio | Avg APD-P | Avg APD-M |
|---|---|---|---|---|---|
| TrackEverything | 40.0 | 26.5 | 27.2 | 31.2 | 72.0 |
| DeltaV2 | 34.7 | 27.3 | 27.7 | 29.9 | 70.7 |
| TAPIP-3D | 37.2 | 24.5 | 27.6 | 29.8 | 71.2 |
| CoTracker3 | 34.5 | 27.4 | 27.1 | 29.7 | 72.1 |
| SpatialTracker-v2 | 36.6 | 28.1 | 23.7 | 29.5 | 71.4 |
- TrackEverything leads APD-P by 1.3 points and trails CoTracker3 by 0.1 in APD-M (reasoned). The lead is ADT. On DriveTrack it is fourth of five; on PStudio, third.
- With Pi3 geometry the order changes: 24.9 APD-P against 25.8 (DeltaV2), 25.6 (TAPIP-3D), 25.2 (SpatialTracker-v2) and 24.8 (CoTracker3), fourth of five (paper, Table 6). "Competitive" is the right word; "matches the state of the art" needs VGGT-Ω.
- "Full length" here means at most about 300 frames. The 1000+ frame evidence is PointOdyssey: 1000+ frame videos scored on all 10k+ labelled points, 31.8 APD-P and 74.5 APD-M, with no baselines because none runs there (Appendix A.1). The teaser's bar chart says "All-frame tracking in 1000+ frame videos", but its 31.2 is the TAPVid-3D full-length average, and it marks D4RT out of memory though the paper says D4RT has no public code to run. It is a summary.
Memory and speed, and on which GPU
The complexity study runs on one L40S (the paper writes L40S-46G) on PointOdyssey, with 384 query points. TrackEverything tracks every point as well; the others track only the 384.
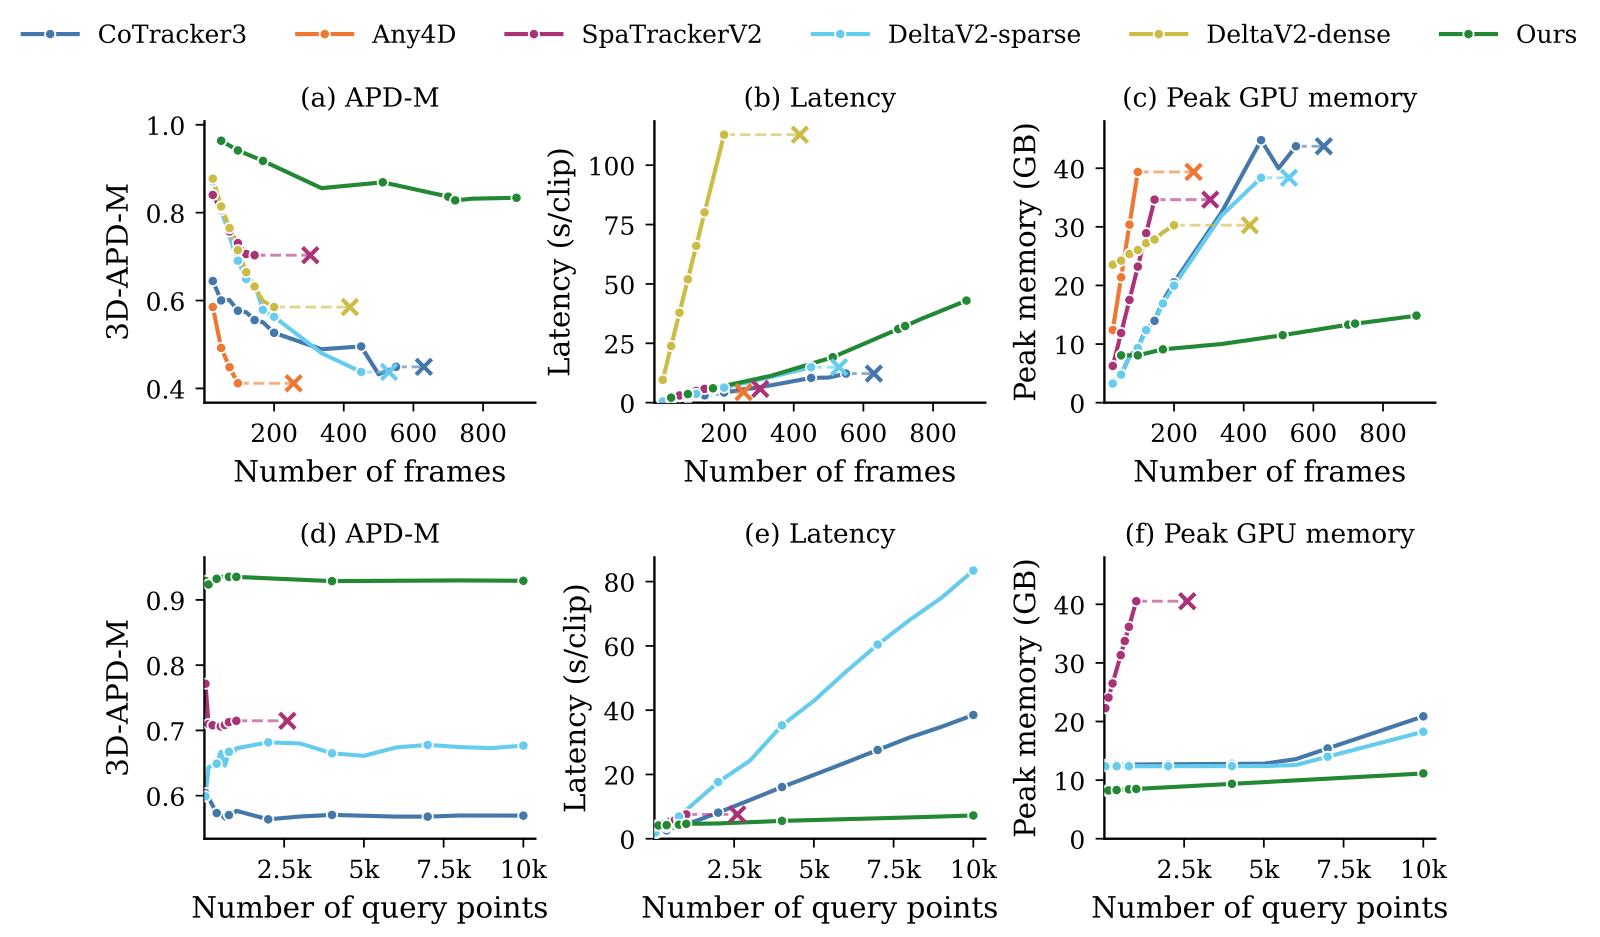
The figure ships as a vector file, so I read the curves off its path coordinates (measured from the SVG). TrackEverything's peak memory is 8.1 GB at 48 frames, 10.0 GB at 336 and 14.9 GB at 896, the last point plotted; its latency is 2.1 s at 48 frames and 43.0 s at 896, about 20.8 frames per second (reasoned). CoTracker3 goes from 4.7 GB at 48 frames to 32.4 GB at 336 and runs out of memory after its 550-frame point. That is roughly 8 MB of growth per frame against 96 MB (reasoned).
The text says memory "remains under 30 GB even at 900 frames"; the plot shows half that. The abstract claims videos "exceeding 1000 frames within 40 GB of GPU memory", but nothing plotted reaches 1,000 frames. Extending the last segment gives about 15.8 GB at 1,000 (reasoned), on this dataset; a scene that keeps revealing new surface would climb faster.
Frame rates come from the appendix (paper, Table 4, full-length TAPVid-3D, reported):
| Configuration | ADT | DriveTrack | PStudio | Avg FPS |
|---|---|---|---|---|
| Tracker only, early merge | 8.4 | 19.5 | 41.5 | 23.1 |
| With VGGT-Ω geometry, early merge | 4.5 | 8.7 | 8.4 | 7.2 |
Without early merge the averages are 12.6 and 5.6 FPS, at 31.2 APD-P against 31.3 with it. The table names no GPU; the paper's other timings are on the L40S. So "10+ FPS on a 40 GB GPU" is half true: the 10+ is the tracker without its geometry model (ADT's 8.4 misses it even then), end to end it is 5.6-7.2, and 40 GB is the paper's memory ceiling, not the card.
Ablations
From the paper's Table 2 (reported):
| Change | APD-P | s/frame | Peak memory |
|---|---|---|---|
| Full model | 31.2 | 0.05 | 9.1 GB |
| Every point through the trajectory decoder | 31.2 | 0.24 | 22.4 GB |
| Without 3D WAFT features | 29.3 | – | – |
| Without iterative refinement | 26.4 | – | – |
| No voxelisation (PointOdyssey) | – | – | out of memory |
| Voxel 0.005 / 0.02 / 0.2 (PointOdyssey) | 31.4 / 30.9 / 23.5 | 0.23 / 0.11 / 0.03 | 24.0 / 15.0 / 10.7 GB |
| Window 8 / 16 / 24 frames | 31.3 / 31.2 / 29.8 | 0.04 / 0.05 / 0.06 | 8.1 / 9.1 / 11.3 GB |
- The static/dynamic split is the cleanest result in the paper: identical accuracy, 4.8× the latency and 2.5× the memory without it.
- Without voxelisation the model runs out of memory. De-duplication is load-bearing, not a tweak.
- The WAFT row removes the sampled features; it does not put a 4D correlation volume back. It shows WAFT is worth 1.9 APD-P. The memory claim against correlation volumes is argued, not isolated: the Figure 3 comparisons are against other trackers that differ in more than one way.
- The text says the default voxel retains peak accuracy "while halving latency and memory" against 0.005. Latency halves (0.23 to 0.11 s); memory drops by 37.5% (24.0 to 15.0 GB, reasoned).
- The classifier is said to reach "93.1 and 92.5 F1" on Dynamic Replica and PointOdyssey. Appendix A.1's full-length PointOdyssey run gives 78.5 F1 for the dynamic class and 92.5 for the static one. The ablation does not say which class its number is for, and the moving class is both the harder one and the one whose errors freeze motion for a window.
What is not in the box
The code (as of 27 September; see the 20 October section below). The repository linked from
the project page, ayushjain1144/trackeverything, was at commit 5ac9cfe (24 September 2026): a README that said "Code release soon (maybe next
week)" and a teaser image. Nothing in the article above the update was checked against code; the only identifier the paper
leaks is the early-merge switch. The release is also to carry the authors' PointOdyssey fixes:
camera poses off by one frame in 16 sequences (about 25k frames), enough to move reprojected
tracks by more than 600 px in fast pans. Anyone training on PointOdyssey wants those.
Merges are permanent. Mean-pooling cannot be undone, so a tracking error that puts two surfaces in one voxel fuses them for good. The paper's mitigation is to pass important points as queries, which are never merged.
There is no eviction. Memory grows with explored space; the authors name spatial cache eviction as the next step for hour-long sequences. FAST-LIO2 deletes map points as its local window moves. This does not, yet. (The release adds an experimental cap, below.)
The tracker is only as good as its pointmaps. On PStudio, APD-P is 23.5 with Pi3 geometry, 30.1 with VGGT-Ω and 71.7 with sensor depth, with no retraining. That is a strength (better geometry is free accuracy) and a dependence: from the two frame rates above, geometry is about 70% of the end-to-end time (reasoned).
The voxel is relative. is in unit-normalised scene coordinates, so its physical size scales with the scene: if normalisation puts the average point 3 m from the first camera, a voxel is about 6 cm across (reasoned, with an assumed scene size).
The model itself is small: 61M parameters, 20M of them the frozen DINOv3-small, trained on eight L40S GPUs for 100k iterations on 32-frame clips and 300k on a mix of 32 and 64, on Kubric, PointOdyssey and Dynamic Replica.
Where it sits
Most 3D work on this site reconstructs things that hold still: the rooms in the 3D reconstruction roundup, the wreck in SurfSLAM, FAST-LIO2's map. TrackEverything keeps a map in which things may move, and pays for motion only where it happens; the voxel as the unit of memory is the move VoxelTTO makes for Gaussians. The result is a tracker whose memory follows the scene rather than the clock, level on the annotated points with trackers that follow a few hundred. The code will say whether the mechanism is as clean as the paper.
20 October: the code is out
On 20 October Ayush Jain posted that
the code and weights are out. The release commit, f0c18dd, adds 208 files to the repository;
a link to a hosted demo followed on 22 October (c86f550, the commit I read).
- license
- CC-BY-NC-4.0
- branch
- main
- tests
- none found
- source
- 1.8 MB
- commit date
- 2026-10-22
by size of tracked source at this commit, file counts in brackets; docs, data and vendored trees excluded
local clone, 2026-10-23 at c86f550 — branch, commit, commitDate, fileCount, hasTests, languages, license, licenseFile
What it contains:
- Inference.
demo.pywrites a Rerun recording and 2D overlays;demo_hf.pyis a Python API whosetracks()returns one track per scene point, , withto_dense()to expand it per pixel. It also takes your own depth, intrinsics and extrinsics, or 2D query points. - Training and evaluation: the Hydra configs, the loss, and evaluation sets for Kubric, Dynamic Replica, PointOdyssey and the three TAPVid-3D subsets, plus scripts that precompute VGGT-Ω or Pi3 geometry. No precomputed geometry or datasets ship; you build those yourself.
- The PointOdyssey fixes, as a manifest: 146 sequences considered, 16 corrected for a one-frame camera offset, one excluded for incoherent extrinsics (read from the file).
- One checkpoint,
model.pthon Hugging Face, 546,083,869 bytes (reported by the Hub).
- task
- keypoint-detection
- library
- trackeverything
- license
- cc-by-nc-4.0
- largest file
- 546.1 MB
- files
- 3
- downloads
- 0
- likes
- 6
- gated
- auto
repo last modified 2026-10-22
Against the paper
The configs agree with the paper where the article could check it (all read from the configs):
16-frame windows, a 0.02 voxel, 384-wide features, three refinement iterations (the paper did
not say; its Figure 6 showed three, and num_iters defaults to 3), 400k training steps (100k on
32-frame clips, then alternating 32 and 64), eight GPUs, PointOdyssey, Dynamic Replica and
Kubric. 3D WAFT is what the paper describes: project the 3D guess with the camera, then
bilinearly sample the feature map, with projections clamped to twice the image size and border
(replicate) padding. Training runs at 384 × 512, which is 12,288 feature tokens a frame at a
quarter resolution, close to the 12,150 I backed out of the teaser earlier (reasoned).
Where it departs:
- Size. Built from the configs, the model has 59,836,043 parameters, 21,601,152 of them frozen (measured). The paper says 61M and 20M frozen; close, not exact.
- The checkpoint carries more than weights. 59.8M fp32 parameters are about 239 MB. Add two AdamW moments for the 38.2M trainable ones and you get 545.2 MB, within 1 MB of the file (reasoned). I could not open it to confirm; see below.
- Early merge (
voxelize_on_endpoints) is off in the training config and on by default at inference. That matches the paper's headline speed rows, which are the early-merge ones. - Voxels round (
round(x/v)) where the paper writes floor: a half-voxel shift. - The learning rate is
5e-5in the config and1e-4in the README's training command. - Eval sets for estimated geometry are named
*_megasam, and their annotator falls back tomegasamunlessANNOTATOR_NAMEis set. The paper's numbers use VGGT-Ω, which the README's training command sets; reproducing Table 1 means setting it too. - New, not in the paper: a
signedlogvoxel mode for scenes whose depth spans orders of magnitude, asparsemode that drops earlier windows' memory, and--compress_memory N, which coarsens static memory once it passes N tokens. That last one answers "no eviction" above; the docs call it "experimental" and "not well tested". The FAQ adds that windows down to 4 frames work and 1-frame online tracking does not.
Licence and access
Code and weights are CC BY-NC 4.0: no commercial use. The weights are gated on Hugging Face;
access is approved automatically, but needs an account and a token. The vendored VGGT-Ω code is
under the FAIR Noncommercial Research License, its weights are gated separately, and the
default checkpoint path for it is a directory on the authors' cluster, so demo.py with default
settings needs --vggt_omega_checkpoint or --geometry_backend pi3 on any other machine.
What I ran
I did not run the released checkpoint: it is gated, and the rules for this site's runs allow no
tokens. Pi3, the open geometry model, is 3.8 GB, too big for the run budget. The repository has
no unit tests. So I built the model from its configs with random weights and ran the inference
path, demo_hf.py with supplied geometry, on a synthetic 16-frame clip at 192 × 256: a textured
plane, a panning camera and a square moving in front. On two threads of a shared 4-core cloud
VM, CPU only, it took 314.4 s, about 0.05 FPS, at 2,356 MB peak memory (measured). That says the
CPU path works end to end and how slow it is; with random weights the static/dynamic split is
arbitrary, so it is not a speed benchmark and says nothing about accuracy. One snag: a stray
from re import T in the point-attention module breaks on Python 3.13 (the README tests 3.10);
I shimmed it from my script.
The paper's accuracy is still unchecked here. The release makes it checkable for anyone with a GPU, a Hugging Face account and the TAPVid-3D data.
How I checked
For the original article I read the paper (v1) and project page and read Figure 3's curves off
its SVG paths. For the 23 October update I read the release post and its replies through the
fxtwitter mirror, cloned the repository at c86f550 and read its README, docs, configs, the
WAFT and projection code and the PointOdyssey manifest, and read the Hugging Face metadata for
katefgroup/TrackEverything (the weights download returned 401, gated). The parameter count and
the CPU run come from the released code with random weights, in a scratch virtualenv with
CPU-only PyTorch 2.8. Not verified: any benchmark number, the checkpoint's contents, and the
FAQ's claims about small windows.