2026-10-06 · 32 min · inference · mixture-of-experts · offloading · speculative-decoding · kernels · cuda · on-device · qwen
Why read this
Notabletop 60%Reads Strata's doorbell, three-way miss split and decayed-LFU cache, then rebuilds the 3090's 97 tok/s: a 0.70-0.86 hit rate, with PCIe, not RAM, the slow lane.
- Original analysis
- Runs on a consumer GPU
- A new technique
Inference & servingMITPractitioner tool
How this was scored
- Is it new?
- 2 of 3: A real new idea, method or capability
- Can I trust it?
- 2 of 3: Measures key facts from files, code or configs
- Can I run it?
- 2 of 3: Open code or weights with real limits
- Will I understand it?
- 2 of 3: Mechanism from first principles with figures
- Can I act on it?
- 2 of 3: A concrete recipe, numbers or comparison
- Will it last?
- 1 of 3: Relevant for months
- Does it affect many?
- 1 of 3: A specialist community
- Only here?
- 2 of 3: A teardown or measurement few others did
Score 63 of 100, ranked 308 of 701 rated articles. Each question is answered 0–3 by hand, and a 3 is rare. How articles are scored
Two posts this week pointed at the same repository. A Chinese post by @Lonely__MH said that "MoE heterogeneous parallelism" runs the 125B Qwen 3.8 Flash Next on 12 GB of VRAM at over 80 tok/s, and ended with "有谁试试吗?我不信": has anyone tried it, I don't believe it. A few days earlier @needmorevram had posted a screen recording of the same engine on one RTX 3090: 97 tok/s on a 2,421-token prompt, 54.1 tok/s on a 142,550-token one, MTP drafts accepted 87% of the time at 3.29 tokens per step.
The site has covered Strata twice. TensorFold and Strata checked the launch numbers against bytes per token and found the 65 tok/s claim real but paired with an untuned baseline. A 200 GB MoE on one RTX 3090 read the 3090 frame and argued that the CPU's arithmetic, not the DDR bus, sets the pace. I will not redo either. This piece reads the code: what happens in one verify window, in what order, with which constants, and what those constants say about the 3090 run.
- license
- MIT
- branch
- main
- tests
- 130 files
- source
- 13.9 MB
- commit date
- 2026-10-06
by size of tracked source at this commit, file counts in brackets; docs, data and vendored trees excluded
local clone, 2026-10-06 at 1735d64 — branch, commit, commitDate, fileCount, hasTests, languages, license, licenseFile, shallow, testFileCount
shallow clone: counts describe the pinned tree, not the history
What changed since 26 September
I cloned the repository with full history at commit 1cbcacb (6 October, 03:07
CEST; I first wrote it down as 1735d64, but upstream the same change, with the same author time, now carries
1cbcacb, committed at 03:12). The first article described 4 commits and no licence. Now (measured,
from git log):
- 1,152 commits, 1,147 of them since 26 September, from 132 author names.
Niko1221 wrote 700. There are 41
v0.1.xtags;v0.1.40is from today. - An MIT licence, added on 28 September.
third_party/ggmlkeeps its own MIT notice. - The cache warning is gone. The first article quoted a start-up message that
said the GPU hit path "is NOT CORRECT". On 27 September the author ran the A/B
the article asked for, in
bench/results/2026-09-27-cache-parity: teacher-forced over 2,557 tokens of three texts, cache on against cache off, the top-1 token agreed at 95.0-97.7% of positions and perplexity moved by -0.005 ± 0.005 nats per token (reported). The flips are near-ties: a GPU expert and a CPU expert sum the same quantized product in a different order. Engine 0.1.8 replaced the warning. - Sampling and a conversation cache. The paper said decoding was greedy and
every request re-read its prompt. Both are fixed; the sampling turns out to use
the same trick as TensorFold (below), and
--prompt-cachekeeps 6 checkpoints of about 118 MB each (src/program/generate.cpp:582). - More hardware: AMD through HIP, an Intel Arc port, multi-GPU layer splits, a low-RAM mode.
Two things did not change. The engine is still 101,329 lines of C++ and CUDA
written around one model's shape (measured, wc -l over src and
include). And the llama.cpp-oracle tests are still left out: CMakeLists.txt:94
says "The test suite and the micro benchmarks live in tests/ and bench/micro/,
which the published source leaves out", and ref/ still holds only load.py.
The byte budget, in code
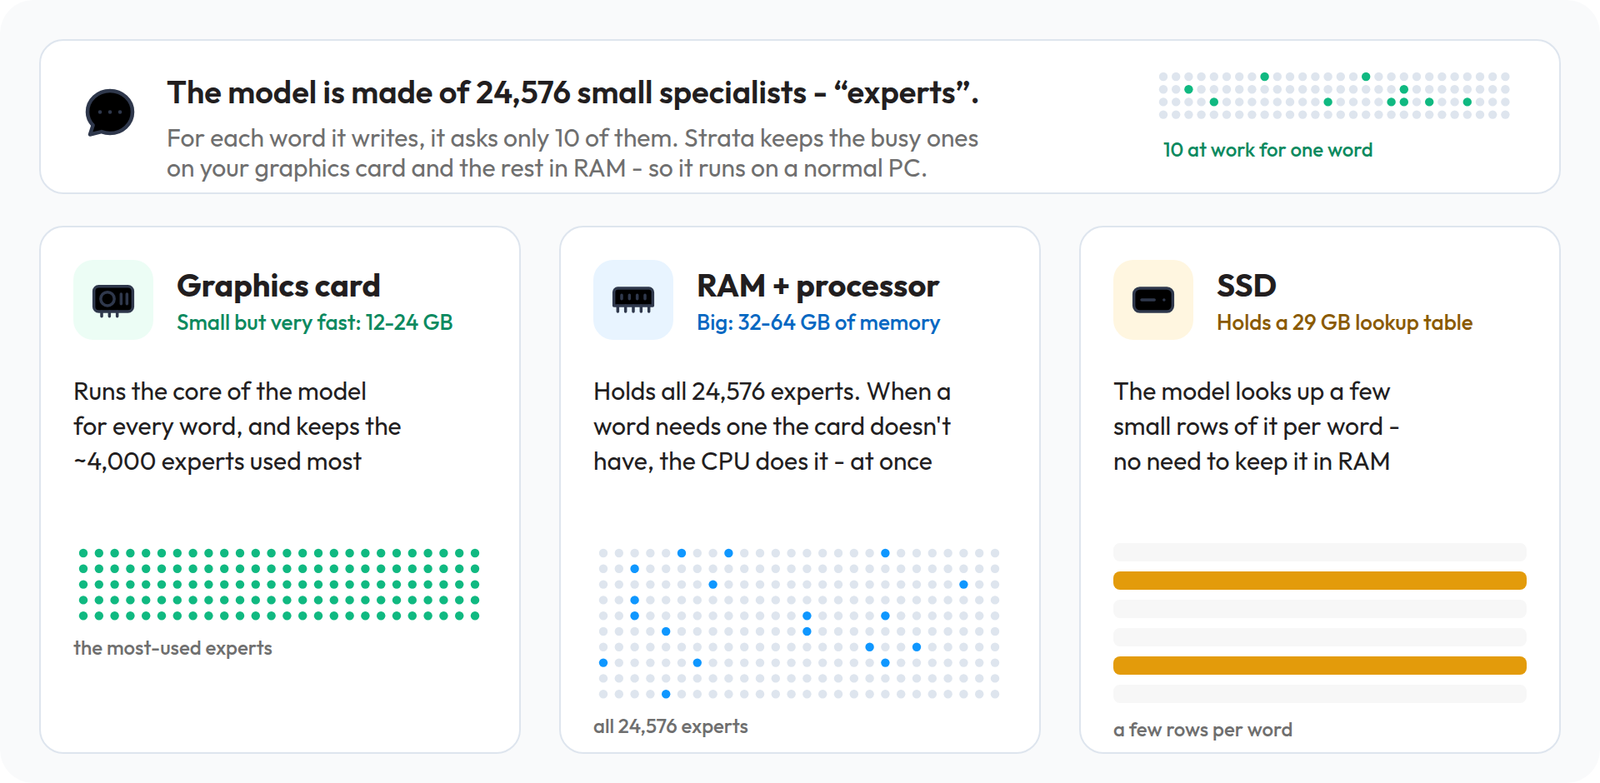
Everything below is sized from four numbers in the source. The model has 48
layers of 512 experts, each 2,560 × 640 for gate, up and down
(include/strata/core/layout.hpp:28-56), and the router picks 10. The Q2_0 format
stores 64 weights as 16 bytes of 2-bit codes plus an fp16 scale, so one expert is
fixed at compile time:
// include/strata/kernels/cpu/expert.hpp:34-45
inline constexpr int H = 2560;      // n_embd
inline constexpr int FF = 640;      // expert intermediate width
inline constexpr int QK = 64;       // QK2_0: weights per fp16 scale
inline constexpr size_t BLOB = 3ull * (H * FF * BB / QK);   // 1,382,400
3 × 2,560 × 640 × 18 / 64 is 1,382,400 bytes, 2.25 bits a weight. The i-quant
packs keep each expert's raw GGUF slices, so their blob size varies by layer.
setup.py lists the arenas: 34.0 GB for Q2_0 and 50.3 GB for IQ3_S, the file the
3090 ran. Divided over 24,576 experts that is 2.05 MB per IQ3_S expert, and one
token's 480 routed experts read 0.98 GB (reasoned). The first article's
0.66 GB for Q2_0 still holds.
One layer: the doorbell
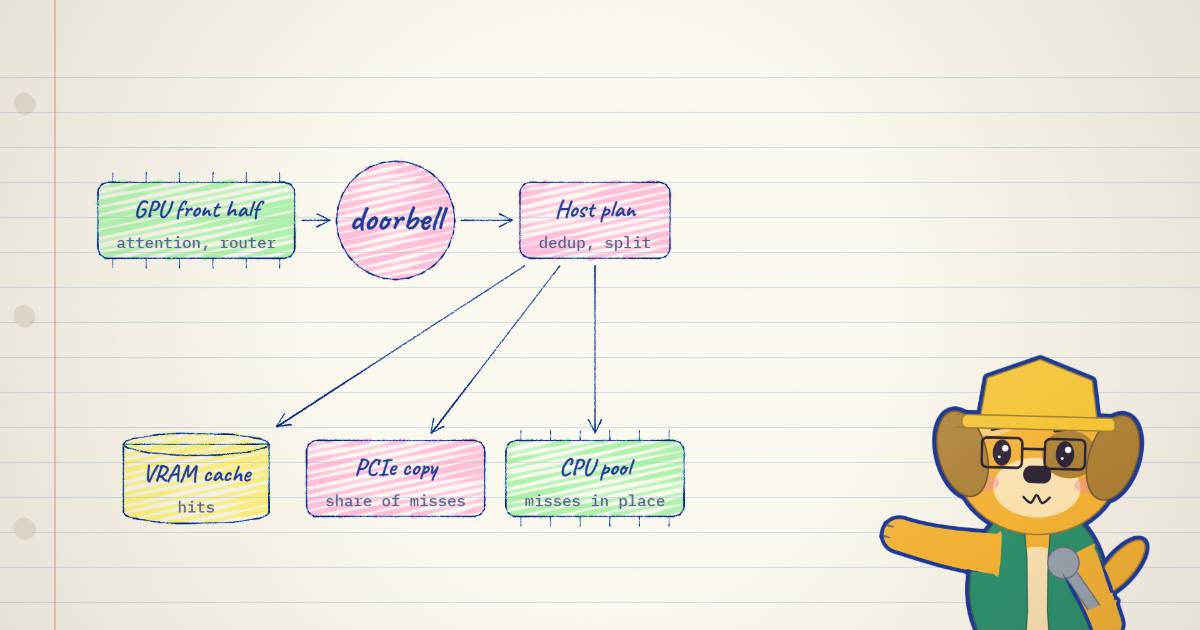
A GPU running a captured CUDA graph does not stop halfway to ask the host for help. Strata needs it to: the router's 10 ids decide which experts the CPU must compute, and the CPU should start before the layer is over. The answer is a "doorbell", a few bytes of mapped pinned memory the graph writes with a kernel. The comment above the struct records how the author got there:
// include/strata/core/layer.hpp:411-419
///   * **THE WAIT MUST POLL THE DRIVER.**  Round 195: a host spin that only reads a memory location never runs
///     the kernel - 5,907,703 spins over 500 ms and the datum flips the instant `cudaStreamSynchronize` is
///     called and never before, because on Windows the driver BATCHES command submission and a memory-only
///     spin gives it no reason to flush.  So `h_seq` is read AND `cudaEventQuery` is called, which is a query
///     and not a blocking sync - P2.X3's "zero synchronization calls in the layer loop" still holds.
///   * **THE WRITE MUST BE CAPTURABLE, AND A KERNEL IS.**  Round 199: `cudaEventRecord` inside a capture is
///     SILENTLY DROPPED - 2 nodes for two kernels plus an event record, and the event never completed across a
///     41 ms graph.  A mid-graph doorbell KERNEL is captured normally, and round 209 measured the host seeing a
///     pinned handoff **0.050 ms** into a 39.8 ms graph.
So each layer is two graphs. block_layer_pre runs attention or DeltaNet, the
hyper-connection read and the router, then rings the bell and computes the shared
expert while the host works. block_layer_post combines the routed outputs with
this layer's own router weights. The header explains why the split is in the
graph and not in time: an earlier version handed layer l's CPU results to layer
l+1 to win overlap, and produced "a finite, fluent, deterministic token that is
not the model's" (layer.hpp:182). The consequence it draws is the design's
thesis: "A per-layer CPU pool cannot be hidden behind a strictly serial residual
chain". The CPU's time can only be shortened, by giving it fewer experts.
The plan: three destinations per expert
When the bell rings, the host runs expert_pool_dispatch_multi over every token
of the verify window at once. It first dedups the window's routed ids, so an
expert two drafts both chose is computed once for both. Then it counts the
distinct misses and gives the GPU a share of them:
// src/core/expert_source.cpp:2473 and 2494
const int m = pcie_ok ? (nmiss * d.pcie_num) >> 8 : 0;
...
if (miss_rank >= nmiss - m && fetches < P.staging_cap && fetches < 64) {
pcie_num is the PCIe share in 256ths. The last m misses in routing order are
copied by the GPU's copy engine into staging slots; the rest become CPU jobs.
Hits are published to the GPU first, so the GPU starts on cached experts while the
DMA and the CPU run. The default share depends on the pack:
// src/program/generate.cpp:550
double pcie_frac = -1.0;   ///< < 0: the model's default (0.2 direct for the Q2_0 pack, 0.55 DMA for native packs)
The reason for the difference is the paper's ninth finding: Q2_0's CPU kernel
already uses the RAM's bandwidth, so DMA would steal from it; the i-quants'
CPU is arithmetic-bound and leaves bandwidth free. Since 0.1.20 a probe measures
the link at start and scales the i-quant share down below 20 GB/s
(generate.cpp:1497: base * min(1.0, gbps / 20.0)), so an x8 slot gets about
half the share. This is FreeToken's split, with a fixed
share per format instead of FreeToken's per-machine optimum.
The window shape matters as much as the split. The verifier's header gives the
union of a window's missed experts as a multiple of one token's: "1.75x one
token's misses for T=2, 2.4x for 3, 3.05x for 4" (include/strata/core/verify.hpp:11,
reported, measured on the author's decode traces). Four tokens share a fifth
of their experts. That is the only sharing the first article's roofline left out.
The widget puts those constants together: the dense read, then three lanes that end with the slowest (GPU experts, the PCIe copy, the CPU's misses), then drafting and commit.
It is a ceiling. With the paper's Table 5 inputs it gives 116 tok/s for Q2_0 against 94.6 measured, and 97 for IQ3_XXS against 65.6 (reasoned). Much of the gap is structure it cannot see: each of 48 layers waits for its own slowest lane, and a sum of maxima exceeds the maximum of sums.
The CPU kernels
Q2_0 on AVX-512. The weights are codes {0, 1, 2, 3} meaning
{-1, 0, 1, 2} × scale. The kernel unpacks 64 of them with one
vpmultishiftqb, multiplies them against int8 activations with one VNNI
vpdpbusd, and removes the offset of 1 with a correction term computed once per
eight blocks:
// src/kernels/cpu/expert.cpp:155-160
inline __m512i unpack64_q2_0(const uint8_t* codes) {
    const __m128i packed = _mm_loadu_si128((const __m128i*) codes);          // 8 u16 = 64 codes
    const __m512i lanes = _mm512_cvtepu16_epi64(packed);                    // 8 qwords, 8 codes each
    const __m512i ctrl = _mm512_set1_epi64((long long) 0x0E0C0A0806040200ULL);
    return _mm512_and_si512(_mm512_multishift_epi64_epi8(ctrl, lanes), _mm512_set1_epi8(3));
}
The comment above it says the 256-bit version "spent ~12 cycles per 64-weight block", compute-bound at about 39 GB/s "while the machine streams 52" (expert.cpp:146-148, reported). Another records that the multishift argument order in Intel's guide gave 43 of 64 wrong codes.
i-quants. IQ3_XXS stores 256 weights in 98 bytes. Each group of four weights
is an 8-bit index into a 256-entry grid, and signs come from a 7-bit index into a
sign table. src/kernels/cpu/iq_avx512.cpp decodes 64 weights as 16 grid lookups
and 8 sign lookups assembled into one 512-bit vector and a 64-bit mask, then
applies them to every token of the window with a masked subtract, a maddubs and
a madd. The header names the point: ggml's kernels are "single-token: every
token re-decodes the weights", here "64 values are decoded once" for up to 8
tokens. A one-instruction gather of the grid was tried and measured "3-5% SLOWER
than the scalar lookups on a Ryzen 5 7600 (Zen 4 gathers are microcoded)", so it
is opt-in there.
The 3090 run's i5-13600K has no AVX-512. It runs the AVX2 forms in
iq_avx2.cpp, with AVX-VNNI where the CPU has it ("the same integer sums, 4-25%
faster rows", docs/DETAILS.md) and a gathered grid decode that turns on
automatically on Alder Lake and newer P-cores. The canonical Q2_0 pack is
AVX-512-only, so that machine runs only the native packs.
The pool. include/strata/kernels/cpu/pool.hpp is a flat batch, not a queue,
because a layer is a barrier. Each phase (gate and up rows, then a requantize,
then down rows) is cut into three tasks per thread so the tail is short, and a
claim is a CAS on one 64-bit epoch | njobs | index word so a worker that woke
late cannot take a job from the next batch. One core is kept for the host thread
that spins on the doorbell, and the comment says why it is pinned: the pool ran
at "36.32 GB/s on 5 workers with nothing else running" and at "26.9 GB/s inside
the host loop" when the host was free to land on a worker's core
(pool.hpp:112-114, reported).
The cache's replacement rule
At start the VRAM tier is filled from a shipped profile that ranks all 24,576
(layer, expert) pairs. Then every routed id bumps a float counter
(expert_source.cpp:2444), and every fourth round the tier swaps:
// src/program/generate.cpp:6736-6748 (per layer)
if (r[e] < 0) { if (u[e] >= 2.0f && ...) cand.emplace_back(u[e], e); }   // a hot non-resident
else vict.emplace_back(u[e], e);                                          // a resident
...
for (size_t i = 0; i < nc; ++i) {
    if (cand[i].first < vict[i].first + 1.5f) break;
    swaps.push_back({cand[i].first - vict[i].first, (int32_t) l, cand[i].second, vict[i].second});
}
In words: per layer, pair the hottest missing experts with the coldest resident
ones; swap only while the newcomer's decayed count beats the resident's by 1.5 and
is at least 2. Across layers, keep the 96 largest gains. After each round every
counter is multiplied by 0.7 (--adapt-decay, generate.cpp:555). The evicted
expert stops being planned for the GPU at once; the new one is planned only once
its copy has landed (apply_pending), which is the paper's tenth finding, worth
91.7 to 94.4 tok/s at 4K (reported).
It is LFU with exponential decay and hysteresis, and it is the reason the paper's
profile-only hit rate of 0.50 becomes 0.72. It also has a cost the docs state
plainly: the GPU and the CPU round an expert differently, so a cache that adapts
to the conversation makes sampled output non-reproducible across runs unless you
pin it with --adapt-every 100000.
Drafting and verifying
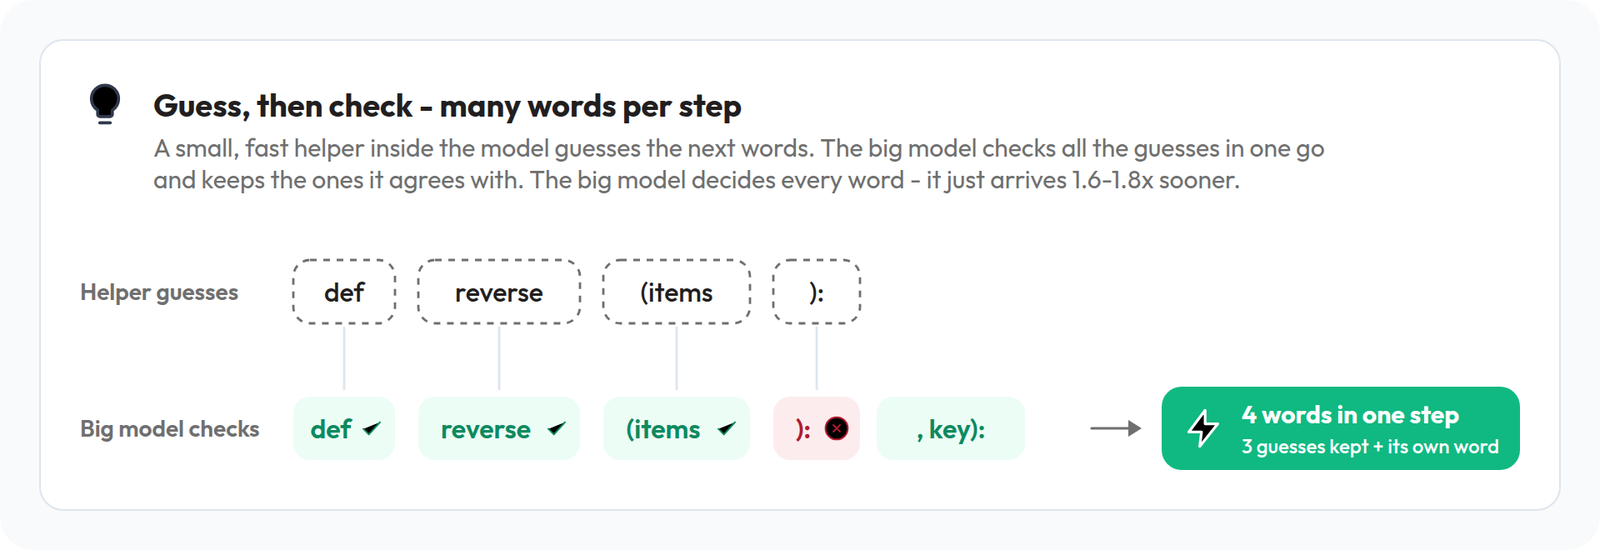
Setup launches the engine with --spec 4 --spec-min-p 0.5 (setup.py:4775): a
window of up to four tokens, the last committed one and up to three drafts, and a
draft enters only while the drafter is at least 50% sure. The drafter is the
model's own MTP layer, fetched from the BF16 checkpoint because the GGUF files
lack it. include/strata/core/mtp.hpp lists what it trades: Q8_0 projections,
dense attention over the last 32,768 cells instead of the sparse selection, and
"all 512 routed experts live in VRAM (708 MB)", so drafting never touches the
CPU. Its head covers a token subset, 106,299 ids by default since 0.1.27 so that
Chinese, Japanese and Korean get drafts too; the same vocabulary trimming the
site traced in HauhauCS FastMTP.
The verifier's contract is the strong one: "Token t's argmax is what plain greedy
decode would produce after token t, BIT FOR BIT" (verify.hpp:5-6). Every
multi-token kernel does per token what the single-token kernel does, so a draft is
accepted exactly when greedy decoding would have produced it.
Sampling keeps that property, and the way it does is worth noting.
include/strata/core/coupled_draft.hpp says the verify row at position p samples
with Philox keyed by the seed and p, and "a draft is kept only when it EQUALS
that row's pick. The output is therefore a function of the seed alone, whatever
the drafts are". That is TensorFold's keyed-Gumbel construction from the first
article, arrived at independently, and it has the same price: an exact-match test
accepts less often than rejection sampling. An opt-in STRATA_SPEC_COUPLED=1
makes the drafter sample with the same uniform the target will draw, to win some
of that back.
How deep to draft is learned. src/spec/draft_policy.cpp:12 starts from a cost shape measured on the 5070, windows of 1, 2, 3 and 4 tokens costing 1.0, 1.35, 1.7 and 2.05 single-token rounds, and replaces it with running averages. Each extra token costs a third of a round because it brings its own misses.
142,550 tokens of context
Only 12 of the 48 layers keep a KV cache; the other 36 are Gated DeltaNet with a
fixed state. Each attention layer has 2 KV heads of 256 dimensions, and
setup.py:120 prices a token at 1,056 bytes per attention layer in 8-bit, 13
layers counting the drafter: 13.7 KB a token. A 142,550-token prompt is 1.96
GB of KV (reasoned), about a tenth of what a 24 GB card has left for experts.
From 64K up, setup streams it: --kv-resident 32768 keeps 32,768 cells in VRAM,
0.45 GB, and the rest in pinned RAM. The paper's sparse attention reads at most
about 2,048 selected positions per query, so decode reads a bounded slice
whatever the length; what streaming buys is room for experts. On the 5070 at 262K
it raised the cache from 1,589 to 3,872 experts and Q2_0 from 50.9 to 62.6 tok/s
(reported, docs/DETAILS.md). In the 3090 thread, needmorevram tells another
user "You can get more speed by adding kv resident 32768": that is this flag.
The 3090 run, rebuilt
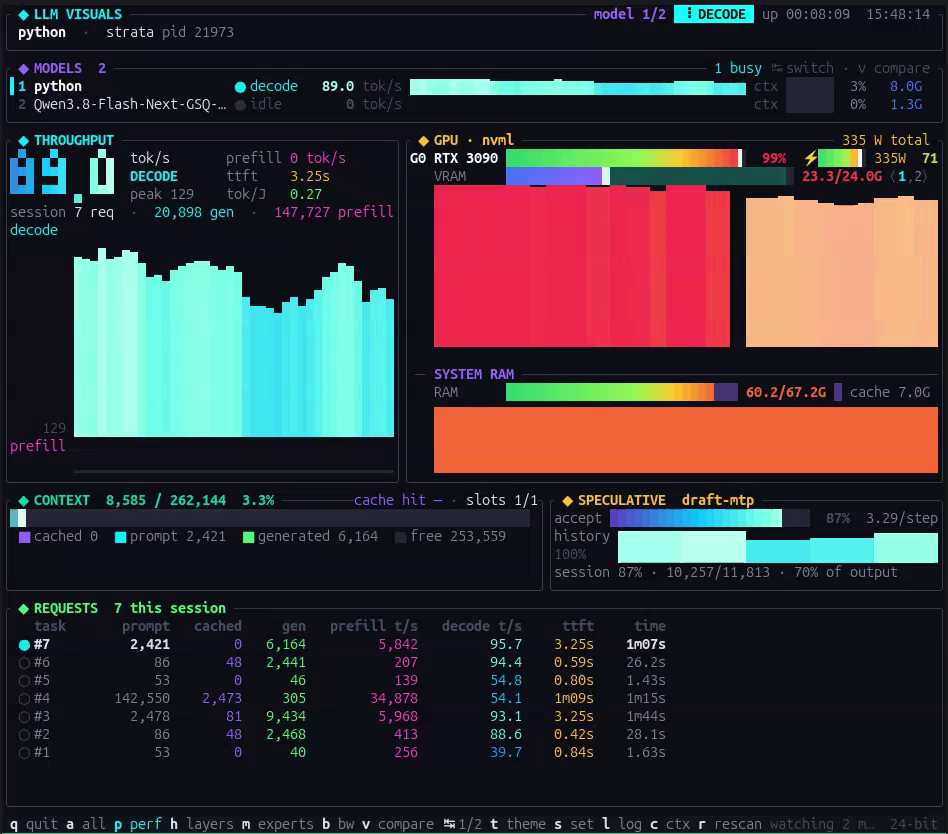
Read off this frame (reported): the drafter accepted 10,257 of 11,813 drafts, 86.8%. At 3.29 tokens per step that is 2.29 accepted drafts a window, so about 2.63 offered: most windows were full four-token windows (reasoned). The 142,550-token request generated only 305 tokens, so its 54.1 tok/s is a short sample. Its time to first token was 1 minute 9 seconds for 140,077 fresh tokens, about 2,030 tok/s of real prefill; the 34,878 in the prefill column is the error the author mentions (reasoned).
Now the window. At 97 tok/s and 3.29 tokens a step, a window takes 33.9 ms. Four
tokens route to 3.05 × 480 distinct experts, 2.99 GB of IQ3_S. With the 0.55 PCIe
share, PCIe and CPU at 25 GB/s each, the dense read at half of 936 GB/s (the Q2_0 file's 3.54 GB; the IQ3_S file's dense bytes are not published) and the paper's 6.3 ms of drafting and commit, the widget's 3090 preset lands at 97.9
tok/s with a hit rate of 0.70 (reasoned). If the 3090 sits as far below
its ceiling as the 5070 did (0.82 for Q2_0, 0.67 for IQ3_XXS), the hit rate is
0.79 to 0.86 instead. Setup's own sizing rule leaves a 24 GB card about 19 GB
for experts (setup.py: VRAM minus 5 GB), about 9,300 IQ3_S experts, 38% of them.
The paper's profile-only curve gives at least two thirds at that size, and the
adaptive tier adds to it, so the range is plausible. Nobody has published the
number; the server's /metrics endpoint reports it as hit_rate.
The frame also answers the DDR question. In this solution the slowest lane is PCIe, 19.7 ms, with the CPU at 16.1 ms close behind, and the two together read RAM at about 27 GB/s. Dual-channel DDR4-3200 offers 51.2 GB/s at peak and DDR5-5200 83.2, so neither bus binds (reasoned). That is why "the difference was so tiny". The two levers left are the ones the paper names: more VRAM for the cache, and cheaper i-quant arithmetic on the CPU.
Other runs fit the same shape and are unverified (reported): a 4090 with 64 GB at 95 tok/s and a 3080 10 GB at 10, in replies to the Chinese post, and a 4090 D with an i9-14900KF on IQ3_S at a p50 of 111.7 tok/s (ferstar's log).
What the 80+ is, and one thing it is not
The README's own table, on the author's RTX 5070, 12 GB and Ryzen 5 7600, says 94 tok/s for Q2_0 at 4K on engine 0.1.36, and 79 for IQ2_XS and 53 for IQ3_S on 0.1.26 (reported). So "12 GB and 80+" is true for the 2-bit files at short context, on a CPU with AVX-512. It is not true for IQ3_S, the file the 3090 ran, and the same card at 128K gives 76.4 for Q2_0 on 0.1.36.
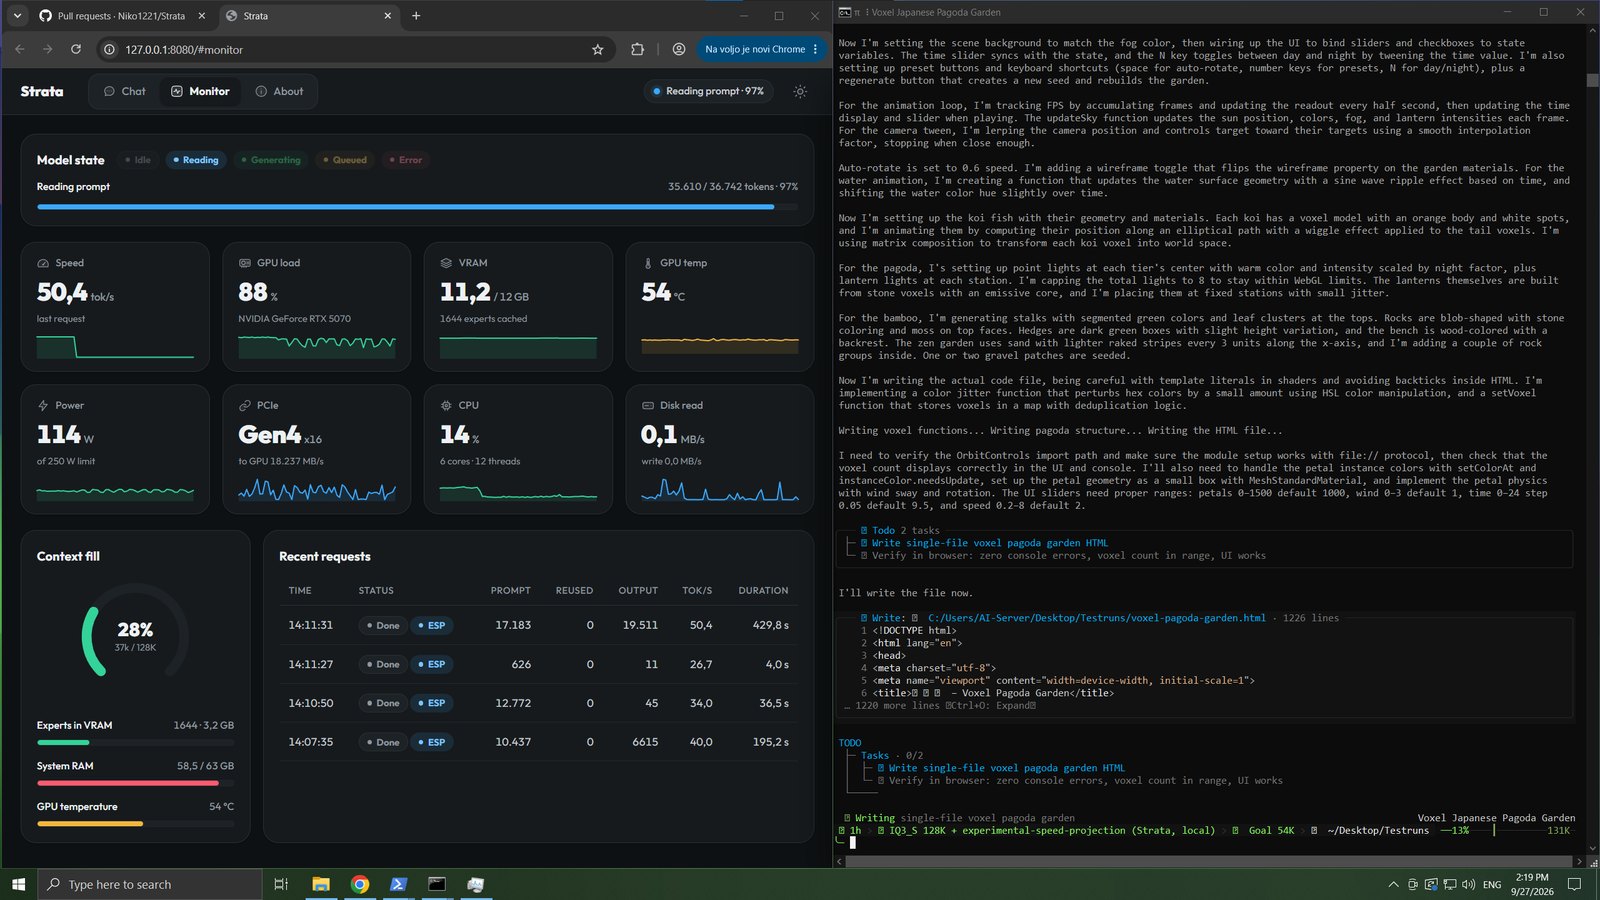
The Monitor tags those requests ESP, the "experimental speed projection". It
is off by default, and its own section of docs/DETAILS.md is candid about what
it is: a control vector that projects one direction out of the residual stream in
layers 4-44, which its package describes as "a refusal-direction projection".
It costs 0.2-0.4% per token rather than saving any, moves the top-1 token at 10%
of positions, and raises perplexity on code by 15% (reported). The name says
speed; the mechanism is a safety change. The docs say so, and the replies to the
Chinese post show some users run it for that reason. A tok/s figure taken with it
on is a measurement of a different model.
Update: one V100, a 2016 Xeon and the 4-bit file
On 6 October @Oluwaphilemon1 wrote up a result that was not his own: the same 111 GB Qwen3.8-Flash-Next file, Unsloth's UD-Q4_K_XL, on a 2016 Xeon with one 16 GB V100, at about 20 tok/s on Strata against about 9 on llama.cpp. The run belongs to @VectorCrossProd, who posted it on 1 October as a five-post thread with more in it than the repost carried: the prompts, the RAM budget, a crash he fixed on the way, and a reply a day later saying he had reached 50.
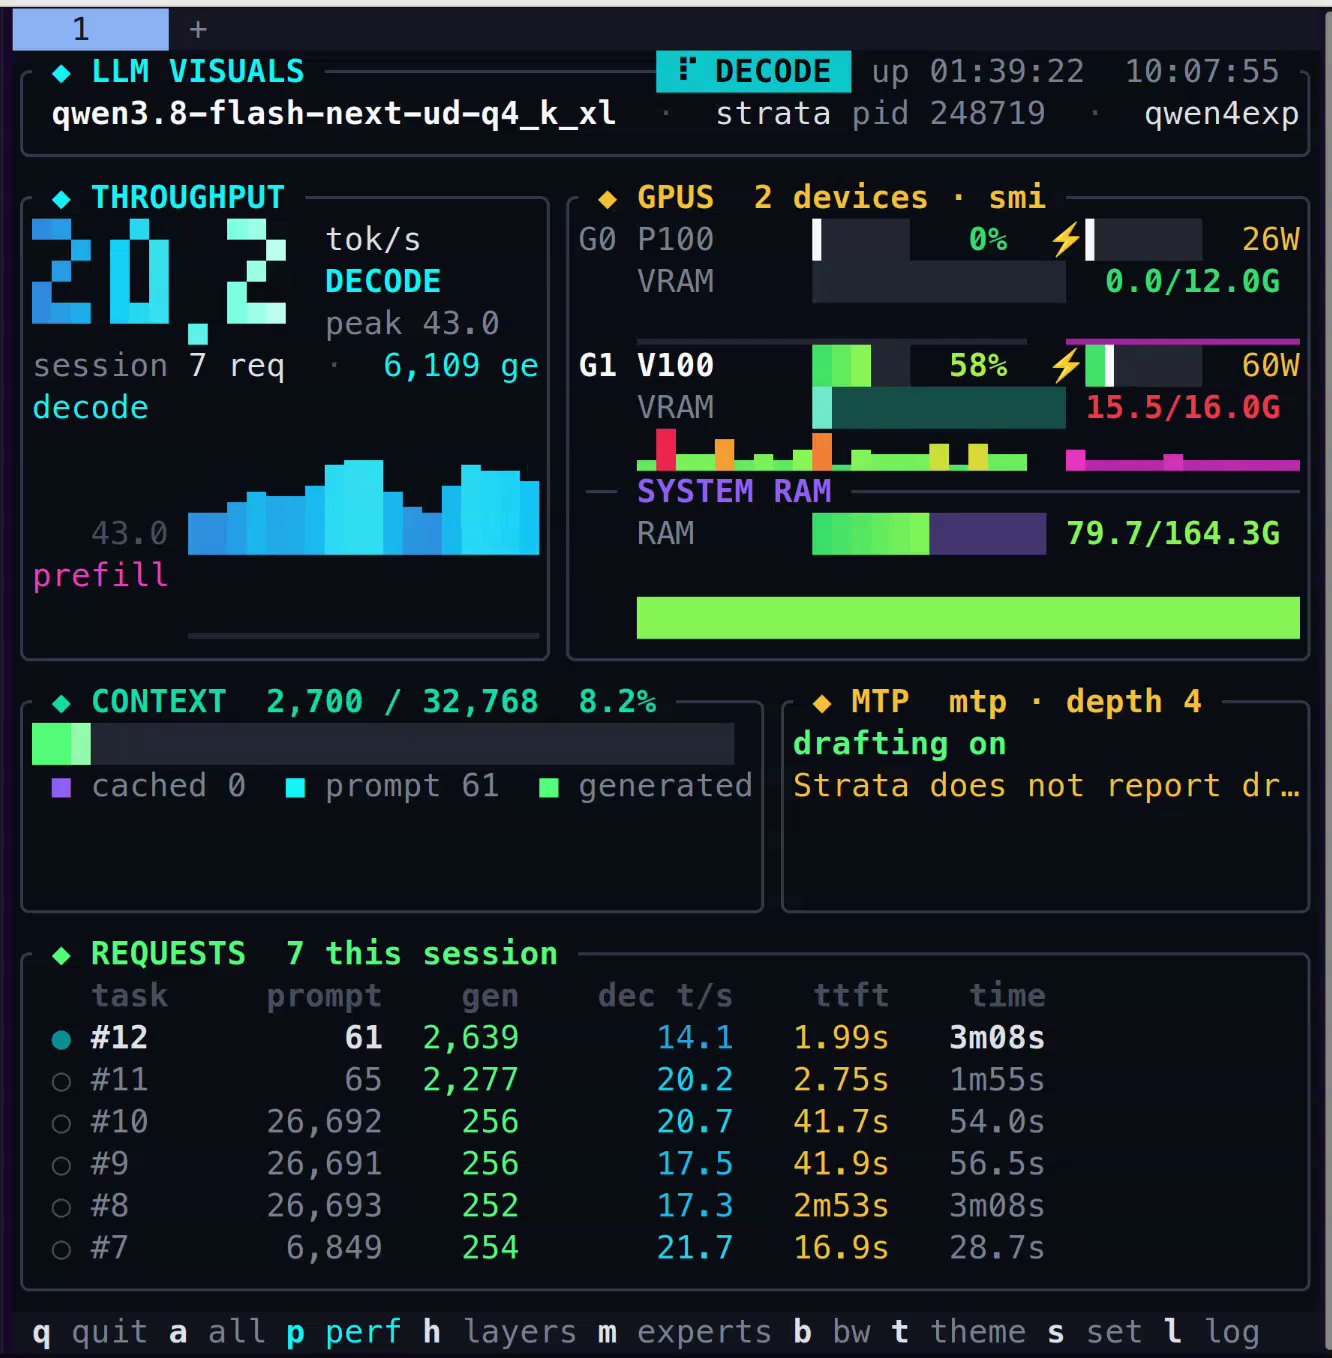
The frame and the thread agree with each other, which is a good sign for a screen recording. The thread says a 6.8K prompt reads at 403 tok/s and a 27K one at 639; the dashboard has a 6,849-token prompt with 16.9 s to its first token, 405 tok/s, and a 26,692-token one with 41.7 s, 640 tok/s. The "~20" is the middle of the decode column, not its best row. A 2,639-token answer still running had slowed to 14.1.
Nothing in this week's code explains it
I expected to find a V100 change between the commit I read and today. There is none. Upstream is now at
82f46a8, seven commits past 1cbcacb, and all seven are fixes to the Python server. Everything this run
uses landed between 30 September and 3 October, before the code the rest of this article reads:
- Engine 0.1.31 (1 October, 06:27) made UD-Q4_K_XL run at all: GPU kernels and ggml CPU paths for its Q4_K,
Q5_K, Q5_1 and Q8_0 experts, read in place from the GGUF shards, behind a RAM budget,
--resident-budget-gib.docs/UNSLOTH_Q4.mdstill calls the file experimental and credits the loader and kernels to eddoursul's fork. - Volta was admitted by an experimental build flag on 30 September (
cd677f7, issue #236).docs/NVIDIA_V100.mdcalls it community-tested: CUDA 12.x only, because CUDA 13 dropped sm_70, and no ready-made engine. - The crash VectorCrossProd hit is fixed in
6aa51c2(1 October, 20:47). His thread describes it exactly: the host checked only the major compute capability, so a V100 at 7.0 passed for a Turing card and ran a tensor-core kernel that is a__trap()stub below sm_75. The fix compares10 * major + minoragainst 75 (src/kernels/cuda/qsa_prompt_attn.cu:982-999). The commit cites issue #371, not his PR #360, and I can't open the PR from here, so I don't know whether his patch was merged or rewritten. - On 3 October a Volta tensor-core kernel for prompt attention (
mma.m8n8k4) made prompts 15-18% faster on a V100-32GB. The same report says decode, 38-51 tok/s there on the 4-bit IQ4_XS file, did not move.
VectorCrossProd adds the last piece himself: going from 0.1.26 to 0.1.31 "changed nothing for IQ3_S on the V100". So the factor of two is not a V100 feature. It is the three-lane design from the rest of this article meeting a file twice as heavy as the ones it was tuned on.
The file, in bytes
The parts of the file matter more than its total, so I read the tensor tables out of the headers of the three data shards with HTTP range requests, 8 MB each. They sum to 111.32 GB: 77.02 GB of routed experts, the 28.80 GB PLE lookup table, a 0.68 GB token embedding, and 4.83 GB of everything else (attention, DeltaNet, shared experts, routers, the 0.68 GB output head). The routed experts are Q4_K for gate and up, 4.5 bits a weight, and Q5_1 for down, 6 bits; layer 2 uses Q5_K and five layers use Q8_0 for down. An ordinary expert is 3,072,000 bytes, the average over all 24,576 is 3.13 MB, and one token's 480 routed experts read 1.50 GB. The IQ3_S file the 3090 ran reads 0.98 GB.
Only the 4.83 GB is read in full on every pass. The PLE table and the embedding are read a row per token. The experts are the problem, and where each of them lives decides the speed:
| Where an expert is read | Bandwidth | One 3.13 MB expert |
|---|---|---|
| V100 HBM2, at the half of peak the paper's GPUs reach | 900 GB/s peak | about 7 µs |
| PCIe Gen3 x16 into the GPU | 15.75 GB/s on paper, about 12 in practice | about 260 µs |
| The CPU, computing it in place from DDR4 | 76.8 GB/s per socket peak, about 14 achieved (below) | about 220 µs |
A VRAM hit is more than 30 times cheaper than either way of serving a miss. On this machine the GPU's bandwidth is almost irrelevant: 4.83 GB at 450 GB/s is 10.7 ms, and everything else is a question of how many of the 480 experts per token have to cross PCIe or go through the Xeon.
The CPU row needs two assumptions, stated once. VectorCrossProd doesn't name his Xeon; a 2016 server part with 164 GB of RAM is a Broadwell-EP E5 v4, with four channels of DDR4-2400 per socket (76.8 GB/s) and AVX2 but no AVX-512. And his reply about pinning memory "to each CPU" means two sockets. On that CPU Strata's codebook kernels are no help for this file. Its Q4_K experts go through ggml's own per-token dot product, the same code llama.cpp runs, because Strata's multi-token Q4_K kernel stays off by default:
// src/kernels/cpu/native_expert.cpp:115-117
// Unsloth UD-Q4_K_XL's Q4_K gate/up: the multi-token kernel is bit-exact against ggml's per-token dot (any group
// size, no #152 rule).  Opt-in, STRATA_KQ256=1: measured no faster in the engine (a window's expert groups hold
// ~1.4 tokens and the weights stay in L1 across ggml's per-token calls; 1.01-1.13x in native_expert_parity).
That makes the comparison cleaner than it looks. Both engines do the CPU's arithmetic with the same kernels on the same cores, so whatever separates them is in how many bytes each sends to the CPU.
Where the factor of two comes from
llama.cpp's usual recipe for a model this size keeps the dense weights on the GPU and the routed experts on
the CPU (-ngl 99 with -ot exps=CPU, or --n-cpu-moe). Every token's 1.50 GB of experts then goes through
the Xeon. At 9 tok/s that is 13.5 GB/s, under a fifth of one socket's peak, which is about what an AVX2
Broadwell manages on Q4_K dot products when its threads on both sockets read pages that landed wherever the OS
put them.
Strata on the same box splits the same bytes three ways. VectorCrossProd gave it a 100 GiB RAM budget, and the
thread says "the 63.6 GiB of experts the GPU can't hold sit in pinned RAM". The experts total 71.7 GiB, so by
his numbers the V100 caches 8.1 GiB of them: about 2,775 experts, 11% of the 24,576. The paper's Figure 3 curve gives a
profile-ranked cache of that size a hit rate of about 0.38, and the adaptive swapping only adds to that. The
budget is pinned, so the GPU also copies a share of the misses over PCIe: the probe rule from earlier gives
0.55 × 12/20 = 0.33 on a Gen3 x16 link.
I added two presets to the window widget above for this machine. Both use the same CPU speed, 14 GB/s, so the only differences are the ones the engines make. The experts-on-the-CPU preset lands at 8.4 tok/s. The Strata preset, with a 0.38 hit rate, lands at 19.1. Taking it apart in the same model: the cache alone gets 8.4 to 12.8, adding the PCIe lane gets 17.7, and drafting adds the last 1.4. Both reported numbers come out of one CPU speed without fitting anything else, which is the best evidence I have that the explanation is right.
Drafting matters less here than on the 3090, and the reason is in the window arithmetic. A four-token window routes to 3.05 tokens' worth of distinct experts and commits about three, so when the CPU lane is the slow one the bytes per committed token barely change. On a fast card with a 0.70 hit rate the dense read is a much bigger share of the window, and that is what drafting amortizes.
The cache does the most work, and its placement policy is what llama.cpp lacks. llama.cpp can put experts on
the GPU too, but by tensor name, which means by layer. 8.1 GiB holds about five layers' experts at 1.57 GB a
layer, a tenth of the experts, and since every layer routes the same 10 per token it catches a tenth of the
lookups. Strata spends the same VRAM on the 11% of (layer, expert) pairs that its profile ranks hottest, and
the curve says those serve about 38% of lookups. Same memory, nearly four times the hits.
How fair is it
Fair enough for the 2x, with one hole. Same file, same box, same GPU, and the thread's method line (three
prompts, greedy, 256 tokens out) is at least stated, although the table under it compares IQ3_S with the 4-bit
file on Strata; for the llama.cpp side the thread says only "same box". Strata's own docs check that the outputs belong to the same
model: on this file, against llama.cpp, the top token agrees at 97.5-99.0% of positions in short answers and at
90-91% after a 16K prompt, with the differences at near-ties. The hole is that nobody posted the llama.cpp
command. Whether the dense weights were on the GPU, how many threads it used, whether it ran with --numa distribute and whether it used mmap would each move a two-socket result, and I can't check any of them.
The 50 tok/s is a different matter. VectorCrossProd says the first 20 was "user error", and that pinning the
memory to each CPU got him to 50, "so basically 5x". Strata has no NUMA code that I could find: a search for
numa over src, include, docs, serve and setup.py returns nothing, and its pool pins worker threads
to physical cores while leaving memory placement to the OS. So the fix was his, at the OS level, and
llama.cpp, which has its own --numa options, was never re-run with it. The 5x compares a tuned Strata with
an untuned llama.cpp, the same pattern the launch numbers had.
The 50 is plausible, and the arithmetic shows why NUMA is where it would come from. At about three tokens a window, 50 tok/s is a 60 ms window; take off the 10.7 ms dense read and ~10 ms of drafting and the misses have about 40 ms. PCIe carries 0.48 GB in that time. At a 0.38 hit rate the CPU must clear 2.36 GB in 40 ms, 59 GB/s; at 0.6, 34 GB/s. Either is 2.4 to 4.2 times the 14 GB/s the 20 tok/s run fits, and far beyond what one socket can pull across two QPI links of about 19 GB/s each way. It only works if each socket's threads read their own memory. I couldn't confirm which file the 50 was measured on; his reply doesn't say, and IQ3_S had already run at 42 on that machine, so treat it as a lead.
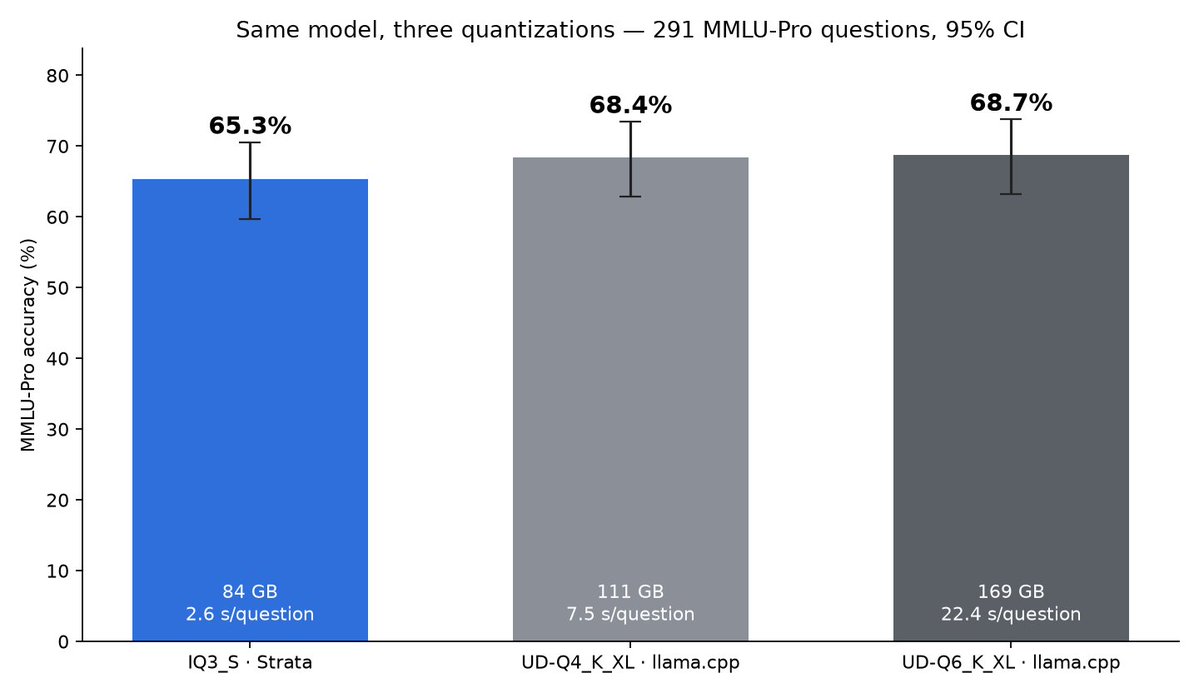
His own chart is worth reading before downloading 111 GB. The 4-bit file scores 68.4% on 291 MMLU-Pro questions against 65.3% for IQ3_S, and at that sample size each bar carries about ±5.4 points of 95% interval, so the two overlap across most of their width. On Strata the price of those three points is about half the decode speed (19.5 against 42 tok/s) and prompts read 34-41% slower (137 against 222 tok/s at 900 tokens, 639 against 966 at 27K). On llama.cpp, he says, the same three points cost four to five times the speed. I would keep IQ3_S on a 16 GB card and switch only for a task where I had measured the difference.
Two practical notes from the thread. The engine's 60-second watchdog killed the first long prompt, because
prompt reading pulls rows from the 28.8 GB PLE table and random reads off spinning disks are slow; reading the
table into the page cache first (62 s with dd) and STRATA_WATCHDOG_S=300 fixed it. And startup takes about
ten minutes off the RAID.
What I would take from it
The engine has a habit worth copying: the measurement that justifies a line is written in the comment above it. Reading those comments is the fastest way to understand it.
Three constants carry the design. The doorbell lets a captured graph hand work to the CPU mid-layer in 0.050 ms. The plan sends each distinct missed expert to one of three workers, with a PCIe share fixed per format and scaled by a probe. The cache is decayed LFU with hysteresis that trades reproducibility for 22 points of hit rate. Everything else, the kernels, the drafter, the KV streaming, exists to make one of those three cheaper or to give the cache more room.
What would change my mind
3 claims above, and what would falsify each
The 3090 run at 97 tok/s implies a VRAM hit rate between about 0.70 and 0.86.
Read
hit_rateandpcie_sharefromGET /metricsfor the 2,421-token request. Below 0.65 would mean the CPU or PCIe lanes are faster on that box than the paper's 25 GB/s.On the i-quant files, RAM speed barely matters because neither the PCIe lane nor the CPU's codebook arithmetic is limited by the DDR bus.
STRATA_DECODE_TIMING=1prints the window split. If the CPU pool's time drops by a third between DDR4 and DDR5 on the same i5-13600K, the CPU is bandwidth-bound after all.On the two-socket V100 box, Strata's 2x over llama.cpp comes from the VRAM cache and the PCIe lane, with drafting adding little.
Run Strata there with
--spec 1(no drafts), and then with--expert-cache 100, which truncates the ranked list to 100 experts (0means auto, not off). If--spec 1loses more than a fifth of the speed, or the tiny cache keeps it well above 9 tok/s, the split in the widget is wrong.