2026-10-06 · 26 min · video-generation · image-generation · diffusion · lora · fine-tuning
Why read this
Notabletop 60%How an IC-LoRA puts a clean reference in the generator's own sequence, two LoRAs sized from their bytes, and demos showing both redraw what the input lacks.
- Original analysis
- A lasting reference
- Concrete numbers to act on
Image & video generationNeeds a workstation GPUMixed licencesPractitioner model
How this was scored
- Is it new?
- 1 of 3: An incremental tweak
- Can I trust it?
- 2 of 3: Measures key facts from files, code or configs
- Can I run it?
- 2 of 3: Open code or weights with real limits
- Will I understand it?
- 2 of 3: Mechanism from first principles with figures
- Can I act on it?
- 2 of 3: A concrete recipe, numbers or comparison
- Will it last?
- 2 of 3: A reference for a year or more
- Does it affect many?
- 1 of 3: A specialist community
- Only here?
- 2 of 3: A teardown or measurement few others did
Score 63 of 100, ranked 319 of 701 rated articles. Each question is answered 0–3 by hand, and a 3 is rare. How articles are scored
Two LoRAs came out in the last week of September, and on the surface they have nothing in common. Lightricks' LTX-2.5 Restore IC-LoRA takes archive video, "low-resolution web rips, low-bitrate broadcast transfers, tape, sepia or black-and-white film scans", and renders the same shot clean and in colour. RunningHub's Qwen-Image-2.1 lighting LoRA takes a product pasted onto a background and, in the repost's words, removes reflections and glare, enhances specular highlights and adds natural shadows.
Underneath they are the same move. A model trained to generate from noise and text is shown a picture, clean, inside its own token sequence, and a small set of extra weights teaches it to treat that picture as the thing to redraw. This piece explains that move from the matrix up, then checks each release against what can be read without a GPU: the cards, the safetensors headers over HTTP range requests, the LTX-2 trainer and pipeline code, DiffSynth-Studio, and ComfyUI's loader.
One constraint shaped the work. The Lightricks repository is gated behind a click-through, and this box has no Hugging Face token, so its weights, its README and its example videos all return 401. The card text is public on the model page, the file sizes are public in the API, and the comparison clip is in the repost. Everything about the restore weights below is therefore reasoned from a byte count, and labelled so.
- task
- video-to-video
- library
- ltx
- license
- other
- safetensors
- 1 shard
- largest file
- 1.71 GB
- files
- 9
- downloads
- 1.4K
- likes
- 51
- gated
- auto
- languages
- en
Gated; weights not read. The file is 1,711,643,914 bytes (measured from the Hub API), which matches rank 128 on all six attention modules of all 48 blocks, 855,638,016 parameters, to within 9,127 bytes of header (reasoned). Trained on LTX-2.3, tested on LTX-2.5 unchanged (reported). The validation sources also appear in training under other degradations (reported). LTX-2 Community License.
repo last modified 2026-09-29
- task
- text-to-image
- safetensors
- 1 shard
- largest file
- 167.8 MB
- files
- 5
- downloads
- 0
- likes
- 64
Measured from the header: 448 BF16 tensors, rank 32 on seven linear layers in each of 32 blocks, 83,886,080 parameters, 1.18% of the 7,115,124,736-parameter denoiser. Metadata: trained on ModelScope with DiffSynth-Studio settings, learning rate 3e-05, 2,000 steps, trigger word pengyu. The card describes no data, metrics or licence of its own; the base model's is the non-commercial Qwen Research License.
repo last modified 2026-09-30
A LoRA is a low-rank diff
Fine-tuning a layer means changing its weight matrix , of size . LoRA (Hu et al., 2021) freezes and learns the change as a product of two thin matrices:
is the rank, a fixed scale chosen at training time, and the strength slider in ComfyUI. starts at zero, so the adapter starts as a no-op. The cost is parameters per layer instead of . For a 4,096 by 4,096 projection at rank 128 that is 1,048,576 numbers against 16,777,216, 6.25% of the layer (reasoned). At rank 32 it is 262,144, or 1.56%.
The bet is that the change a task needs lies in a few directions per layer. Restoration and relighting are good candidates: the base model already knows what a steam locomotive or a glass bottle looks like under daylight. The adapter has to teach it something narrower: where to look for the layout, and what to do differently once it has.
Both files set , so and the strength slider is the only scale. The
restore card states rank 128, alpha 128. The relight file has no alpha tensor, and DiffSynth-Studio's
add_lora_to_model defaults lora_alpha to the rank; ComfyUI applies a scale of 1 to a file with no
alpha (all measured from the sources).
What is in the two files
The relight header is 58,240 bytes of JSON, read with two range requests. It lists 448 BF16 tensors:
an A and a B for to_q, to_k, to_v, to_out.0, img_mlp.gate_layer, img_mlp.proj and
img_mlp.out in each of 32 blocks. Each attention projection is 4,096 square; the two MLP inputs go
4,096 to 12,288 and the output comes back. That is 2,621,440 parameters a block and 83,886,080 in
all, and 8 + 58,240 + 2 x 83,886,080 is the file's size to the byte, 167,830,408 (measured).
The restore header cannot be read. What can be read is the base model. The LTX-2.3 transformer header lists 21,005,004,544 parameters and six attention modules in each of 48 blocks: video self-attention, video-to-text cross-attention, audio self-attention, audio-to-text cross-attention, and the two cross-modal modules, audio-to-video and video-to-audio (measured). The LTX-2 paper's own diagram shows them:
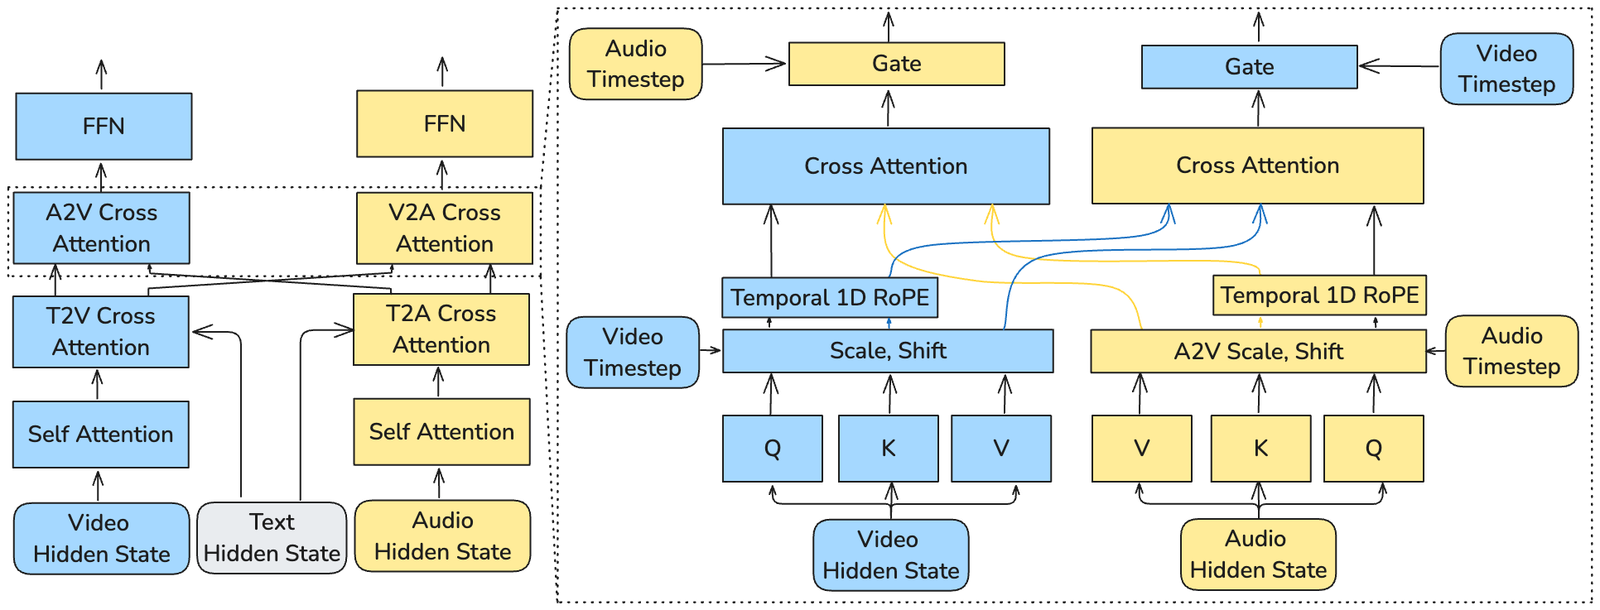
The card says the restore LoRA "targets to_q/to_k/to_v/to_out". In the LTX-2 trainer that is a
suffix match, and the trainer's configuration guide warns that the short patterns "will match all
attention modules including attn1.to_k, audio_attn1.to_k, audio_to_video_attn.to_k, and
video_to_audio_attn.to_k" (measured from the docs). At rank 128 over all six modules of all 48
blocks, that is 855,638,016 parameters, 1,711,276,032 bytes of BF16. Rebuild the header those
tensors would need, with the licence text the ungated Union-Control LoRA carries as metadata, and the
predicted file comes to 1,711,634,787 bytes. The real file is 1,711,643,914: 9,127 bytes apart, less
than one part in 180,000 (reasoned). Video attention alone would be 805,306,368 bytes, half the file,
so the short patterns are what was used.
That has a consequence the card does not mention. The restore run trained on video; the card lists
"Audio: Not trained for audio generation". With no audio in the batch, the LTX-2 transformer skips
the audio and cross-modal branches entirely (run_ax, run_a2v and run_v2a are false), so their
LoRA B matrices get no gradient and keep their zero initialisation. If that is what happened, 452,984,832
of the 855,638,016 parameters, 53%, are zeros that load, cost memory, and change nothing
(reasoned from the trainer code; not checked against the weights).
The calculator below rebuilds every one of these files from the measured layer shapes. Pick a base, tick the layer groups, slide the rank. It reproduces the two ungated LTX-2.3 IC-LoRA headers I read (Lightricks' Union-Control at rank 64, 327,155,712 parameters, and a community colourizer at rank 32, 163,577,856, both on video attention and the video feed-forward) and both Qwen-Image-2.1 LoRAs on this site exactly.
On Qwen the same layer budget can be spent two ways. Qwen-Image-2.1's MLP input is one fused
gate_up weight in ComfyUI and ai-toolkit, but two separate 12,288-wide layers in diffusers and
DiffSynth-Studio. ausboss's outpaint LoRA targets the fused
one: one rank-32 adapter, 79,691,776 parameters. The relight LoRA targets the halves: two independent
rank-32 adapters, 4,194,304 parameters more (measured). ComfyUI's loader has a branch for exactly
this, mapping gate_layer and proj onto the two halves of the fused weight, and accepts PEFT's
lora_B.default.weight naming, so the file loads as shipped (measured from comfy/lora.py and
weight_adapter/lora.py at commit d49e888).
In context: the reference rides in the sequence
A LoRA changes weights. It does not, by itself, give a text-to-video model a way to see an input
video. That is what the "IC" adds. The name comes from Alibaba's
In-Context LoRA, which tiled related images into one canvas;
Lightricks' version is more direct, and the LTX-2 trainer spells it out in
training_strategies/video_to_video.py (measured from the code):
- Encode the target clip and the reference clip with the same video VAE. The VAE compresses 32x in height and width and 8x in time, and the patch size is 1, so a 960 x 544 x 97 window is 30 x 17 x 13 = 6,630 tokens.
- Noise only the target. The reference stays clean, and its per-token timestep is 0.
- Concatenate the two into one sequence and give both the same position grid. At downscale factor 1, reference token (t, h, w) and target token (t, h, w) carry the same rotary coordinates.
- Run the transformer over the lot, with ordinary bidirectional self-attention.
- Compute the flow-matching loss on the target tokens only.
At inference VideoConditionByReferenceLatent does the same thing: it appends the reference tokens
with a denoise mask of 1 − strength, so a guide strength of 1 keeps them clean at every step. The
order differs from training, reference first there and appended here, which attention does not care
about: it sees positions, not order (reasoned).
That is the whole mechanism. There is no encoder for the reference and no new input channel. The target attends to the reference in every layer of the same network, and because the two share coordinates, "the matching pixel in the archive clip" is one rotary rotation away from every target token. What the LoRA learns is how to use that path: which parts of the reference to copy (layout, motion, structure) and which to override (grain, cast, blur, the absence of colour).
The cost is plain in the token count. At downscale factor 1 the reference is as long as the target,
so every linear layer processes twice the tokens and self-attention four times the pairs: 13,260
tokens for one 960 x 544 tile of 97 frames (reasoned). Lightricks offers a cheaper variant elsewhere:
the Union-Control LoRA's metadata says reference_downscale_factor 2, a quarter of the reference
tokens, with positions scaled back up to the target's grid. The restore LoRA's card says factor 1,
which makes sense for a task whose whole point is detail at the target's scale.
There is also a dial between full and no attention. Wrap a reference in
ConditioningItemAttentionStrengthWrapper with strength s below 1, and build_attention_mask
writes s into the target-to-reference blocks, 1 inside each reference, and 0 between two different
references. The float mask becomes an additive bias of on the attention logits, so s = 0.5
halves the unnormalised weight of every target-reference pair (measured from mask_utils.py and
transformer_args.py). At s = 1 no mask is built at all.
Qwen-Image-2.1 edits the same way with a different mask. Its reference image is a prefix in one
stream of 32 blocks, modulated from t = 0, and the mask is block-causal: the target reads the
reference, the reference never reads the target, as
the release piece covers.
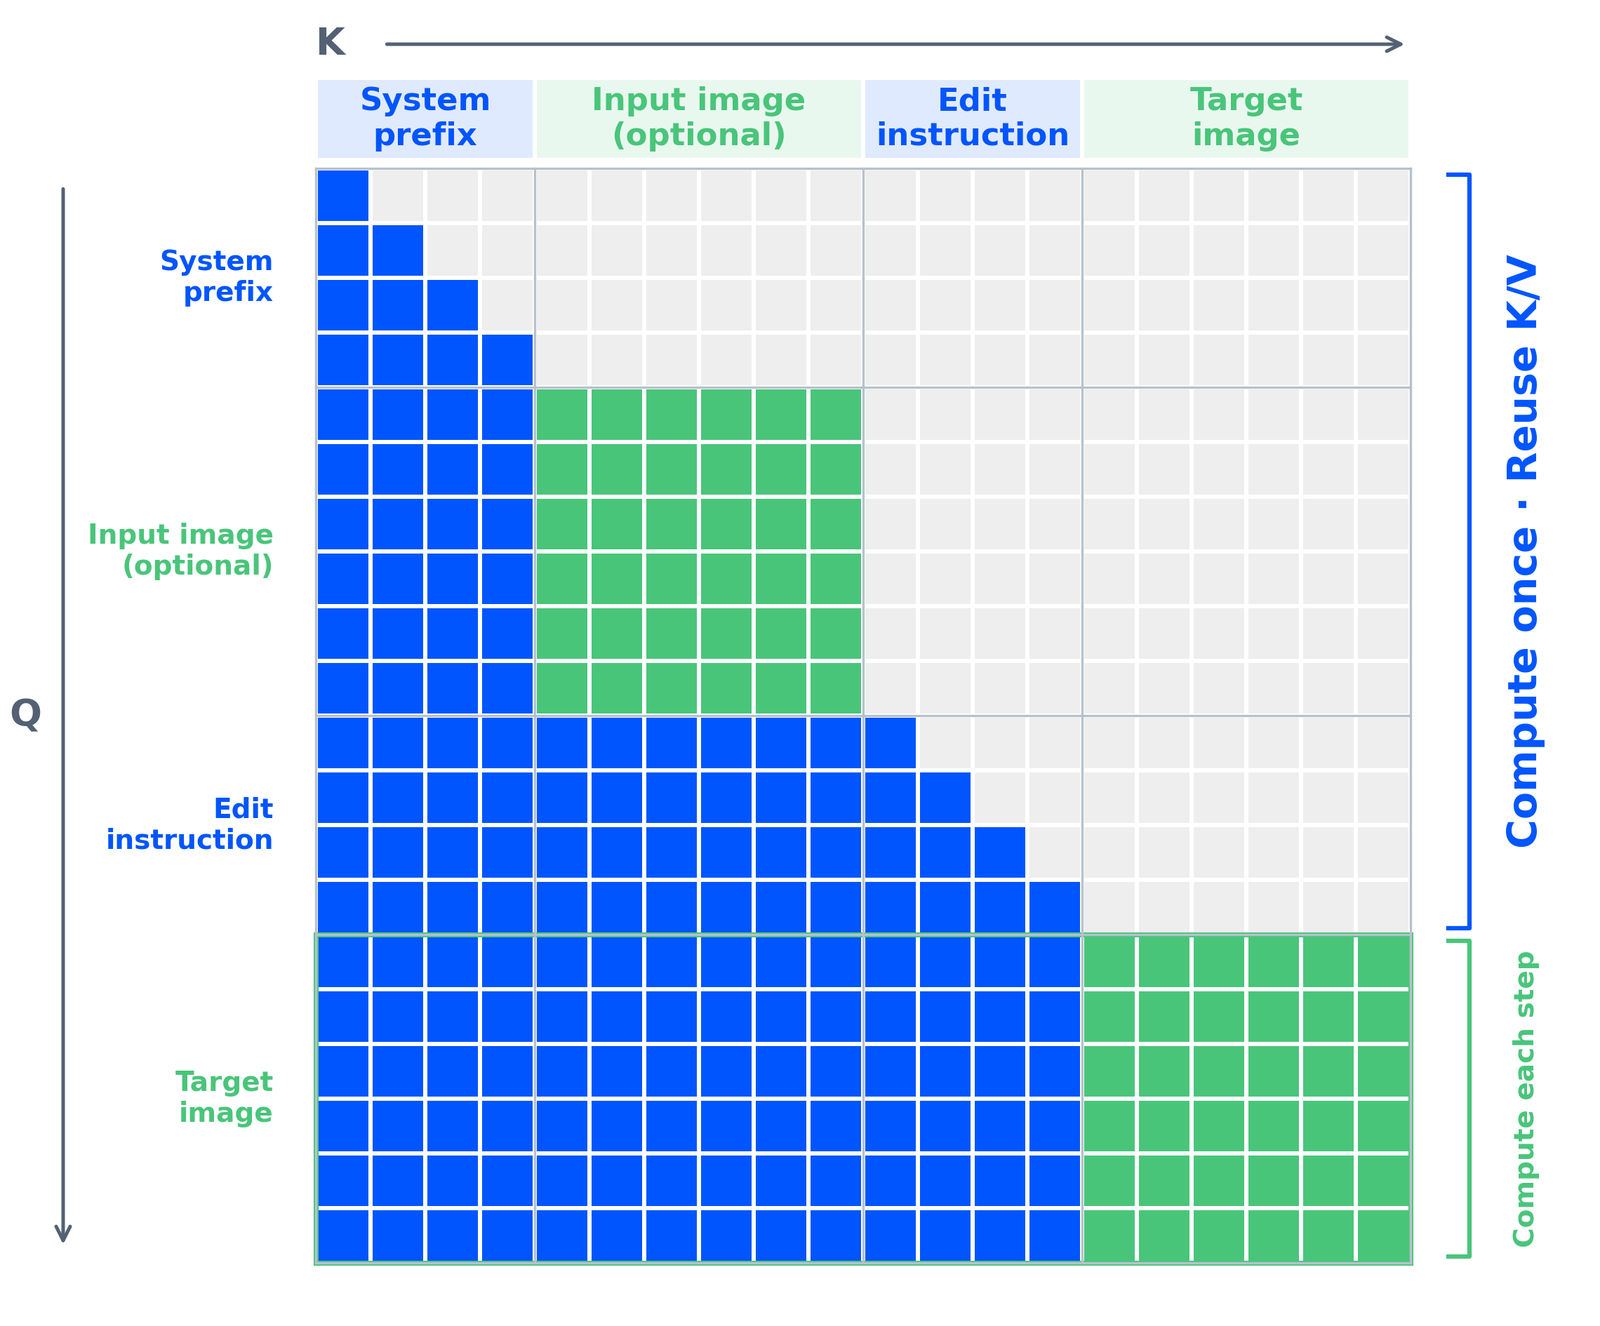
So the relight LoRA is in-context too, in everything but name. The difference that matters is in the arrow: LTX's reference and target see each other, Qwen's reference is read-only, which is what lets Qwen cache it.
How the restore LoRA was trained
The card is unusually complete about this, and it is the part to read before using it.
Synthetic pairs. "A clean 1080p clip was turned monochrome or tinted (neutral broadcast, cool tape, warm sepia), blurred as a period lens would, downscaled to 240p to 360p, encoded at a low bitrate one to three times over, sometimes denoised, scaled back up, and given film damage." The degraded clip is the reference and the clean clip the target. There are 151 training pairs and 8 held out, 97 frames at 24 fps, one shared caption (reported).
The recipe. The LTX-2 trainer's flexible strategy: the degraded video always present as the reference, the first frame given clean with probability 0.25, and the first 17 frames given as a prefix with probability 0.5. Rank 128, alpha 128, the Prodigy optimiser at learning rate 1.0, a cosine schedule, batch 1, 4,000 steps, buckets of 960 x 544 at 97 and 49 frames (reported). The prefix training is what lets a long clip be restored as chained 97-frame windows, each starting from the previous window's last 17 restored frames.
The settings it wants. Eight steps on the distilled model, guidance 1.0, LoRA strength 1.0, and the clip upscaled with lanczos to the working canvas before it becomes the guide, so "the model never sees the small scan". The canvas is cut into overlapping 960 x 544 tiles, the trained size, fused at every step, even for a full-HD output. The distilled sigmas are 1.0, 0.99375, 0.9875, 0.98125, 0.975, 0.909375, 0.725, 0.421875 and 0.0, so five of the eight steps run above 0.9 (reasoned): most of the schedule is spent where layout and colour are decided. Strength "behaves as a switch: at 0.7 the restoration turns off and the clip stays monochrome; 1.4 over-tints" (reported).
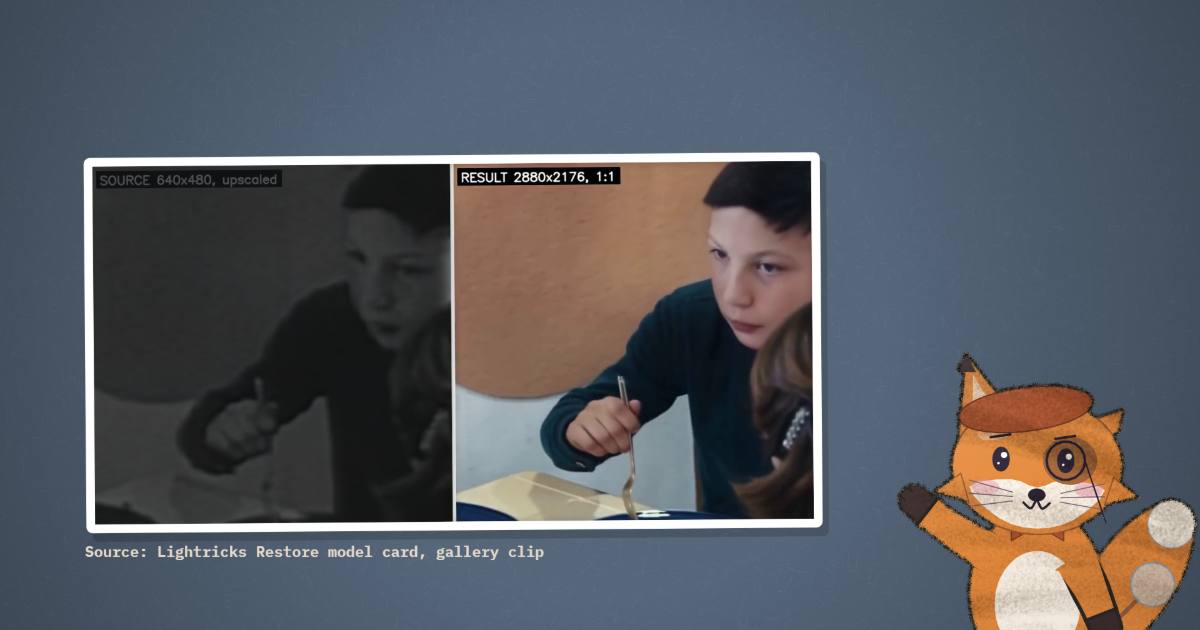
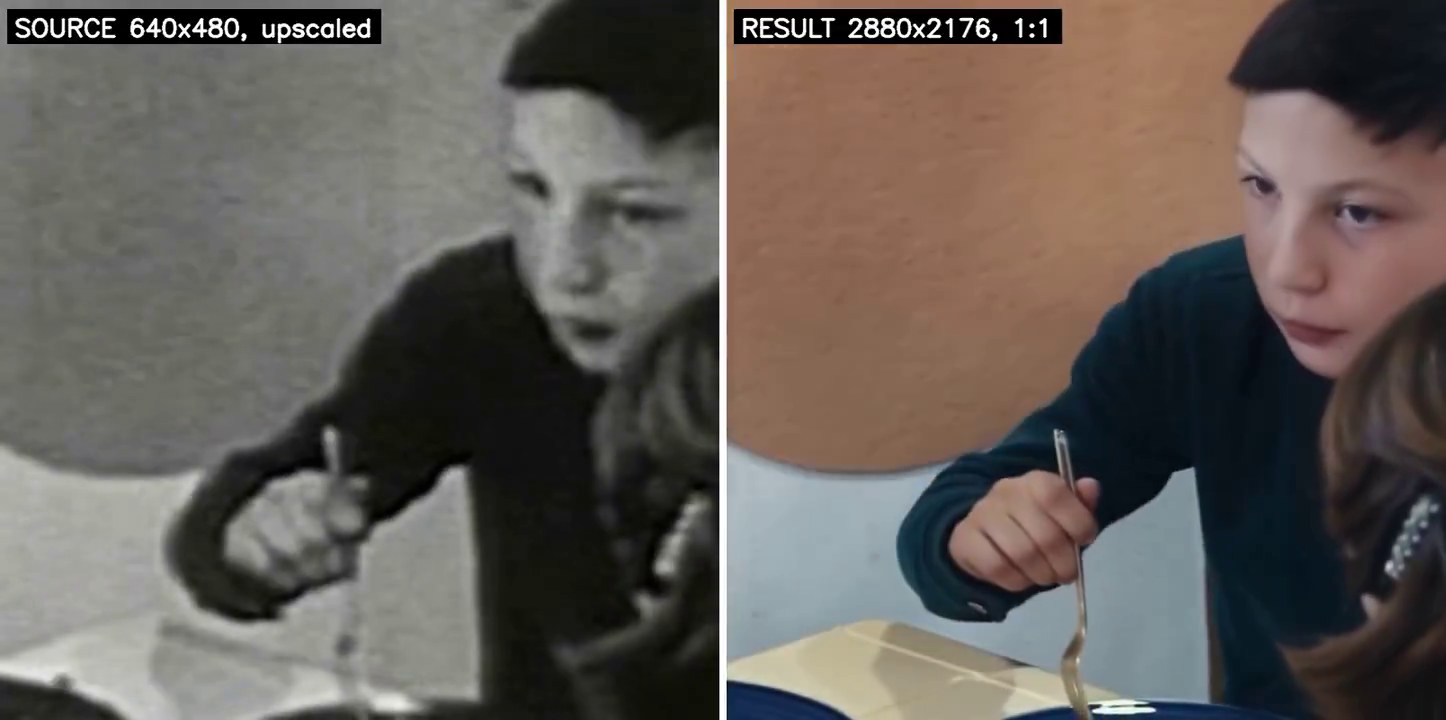
The card's gallery is three public-domain clips: a 1954 family meal, the Lumière train and the Hindenburg. Two of them, as they appeared in the repost:
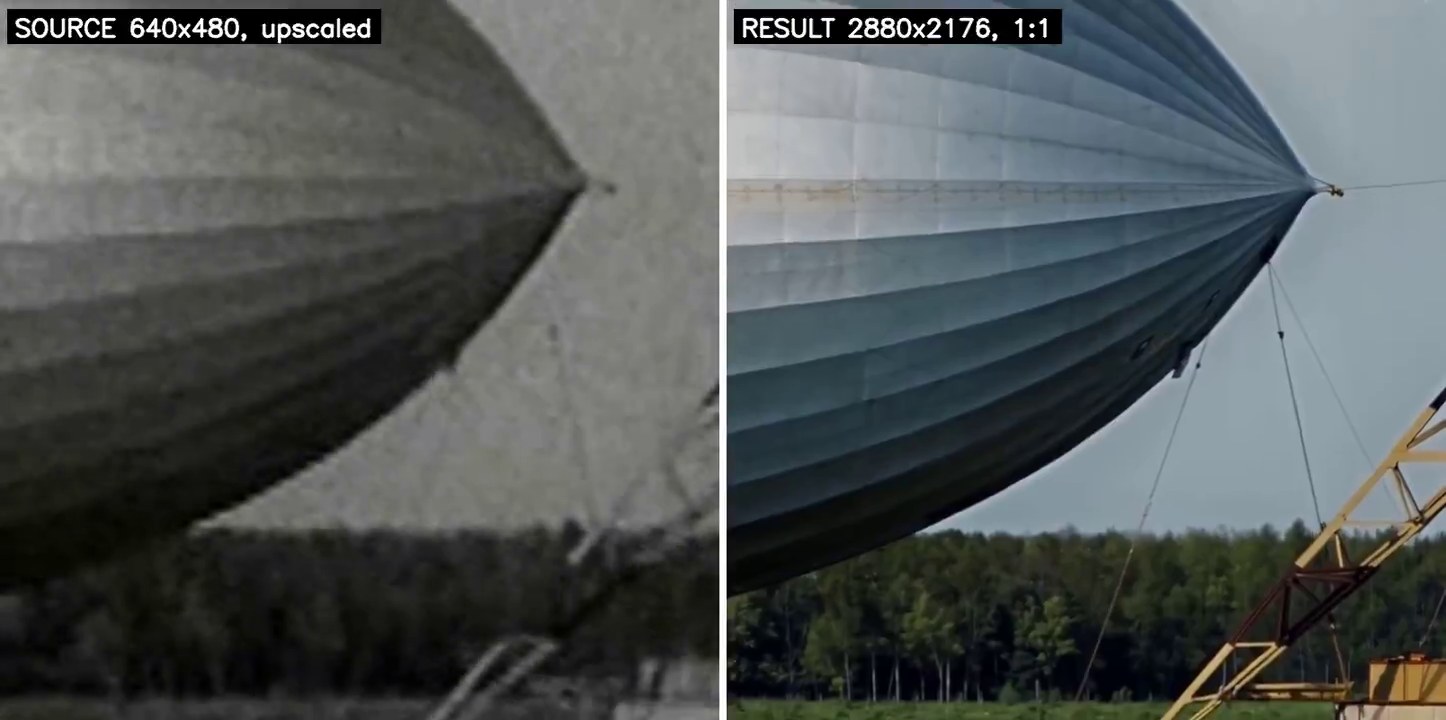
The numbers. On 8 validation pairs at 1920 x 1056, 97 frames, stage 1 only: PSNR +2.0 dB over the degraded input, a Lab colour error from 24 to 16, and high-frequency energy from 61% to 85% of the target, against +0.8 dB and 75% for the previous version (reported). Read the fine print next to them: those 8 pairs' "sources also appear in training under other degradations". The model has seen those clean frames. On clips whose sources it never saw, the card says, it "does not beat the aligned input on pixel PSNR; judge those by eye". That is the honest version of the claim, and it is Lightricks' own.
A reference image helps where it exists. Real crops of a sign, a logo or a face, placed over their own region on a grey canvas and attached at frame index −1, raised the sign region by 4.6 dB and the faces by 4.0 dB against the truth on one street clip (reported). It is the one mechanism here that adds information instead of inferring it.
What "restore" means here
Count what the model is given. The source is 640 x 480, one channel. The output is 2880 x 2176, three channels. That is 20.4 times the pixels, and two of the three colour channels have no source at all (reasoned). Everything between the scan's samples is drawn by a video generator conditioned on them.
The card says so in its own words. On the train clip, "the station side of the frame holds almost no information in the scan, so the model rebuilds it: the buildings, the hillside and the porter's cart on the left are period-plausible reconstructions, not recovered detail." Faces "can read slightly beautified on very degraded sources". Colour "is inferred from content, or from a reference image", and it is out of scope to recover a creative grade from monochrome. Every tile receives the whole prompt, so a named object "can be painted into a tile that does not contain it"; with modern objects in the negative prompt, empty regions come back as period-plausible background instead of shipping containers.
The replies to the repost were less polite: "It alters the reality of the original image. It's not a restoration." Several pointed at a fork in the boy's hand that they read as a spoon in the scan. I cannot settle that from a 640-pixel crop, which is the point.
So the defensible uses are the ones the card lists: delivering old footage at HD to 4K for a documentary or a remaster, where the audience knows it is looking at a treatment. For archival work it is a rendering, not a record. Keep the scan, ship the two side by side, and caption the colour as inferred, as the card does. When a likeness or a sign matters, give the model a real photograph at the −1 token rather than trusting it to guess.
The relight LoRA: a thin card, a talkative header
RunningHub's card is a few lines: a Chinese title, 光影溶图 ("light-and-shadow blending"), a trigger word and one prompt. The prompt is the instruction the model was trained on:
pengyu Apply consistent lighting to the product or object, enhance specular highlights,front-back spatial relationship,add natural contact shadow, and blend it seamlessly into the background。The header's metadata says more than the card. It names the author's ModelScope repository, the
source "Modelscope X MuseAI", base model Qwen/Qwen-Image-2.1, lora_rank 32, learning_rate
3e-05, training_steps 2000, max_pixels 1048576 and remove_prefix_in_ckpt pipe.dit.
(measured). Those last two are the arguments of DiffSynth-Studio's Qwen-Image-2.1 training script,
whose commented edit recipe feeds an edit_image beside each target (measured from the repository).
So this is an edit LoRA in the usual Qwen-Image-2.1 sense: the composite goes in as the reference
image, the relit picture is the target, at up to 1 MP, and at 0.3 times the script's default learning rate
of 1e-4.
What the training pairs were, the card does not say. A natural recipe is to cut a product out of a real photograph, flatten or alter its lighting, paste it back, and ask for the original; the demos' white sticker borders look like that kind of input. That is a guess, not something any file states.
The demos, from the repost's clip, show the claim and its edges.
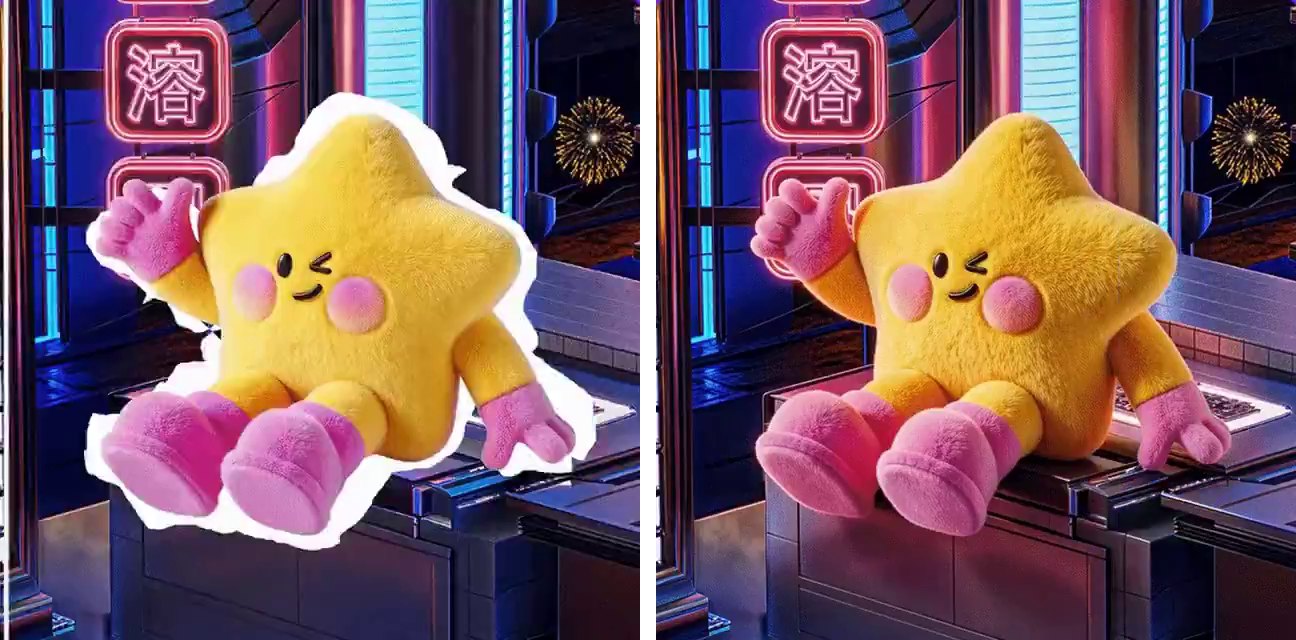
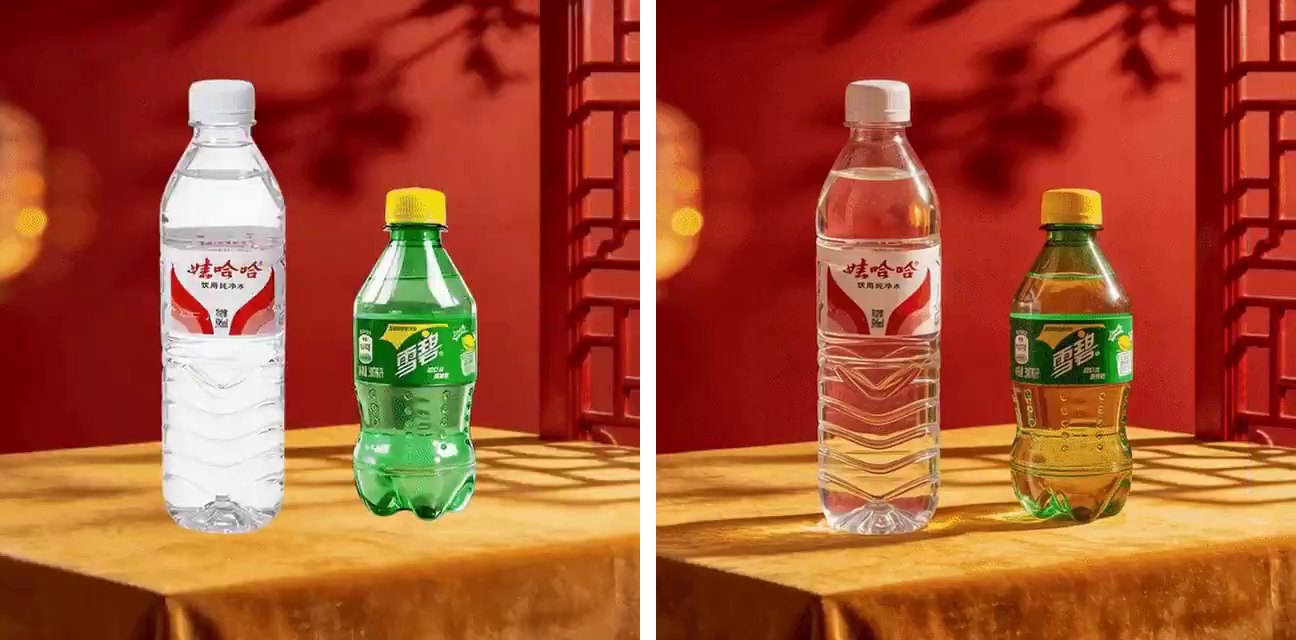
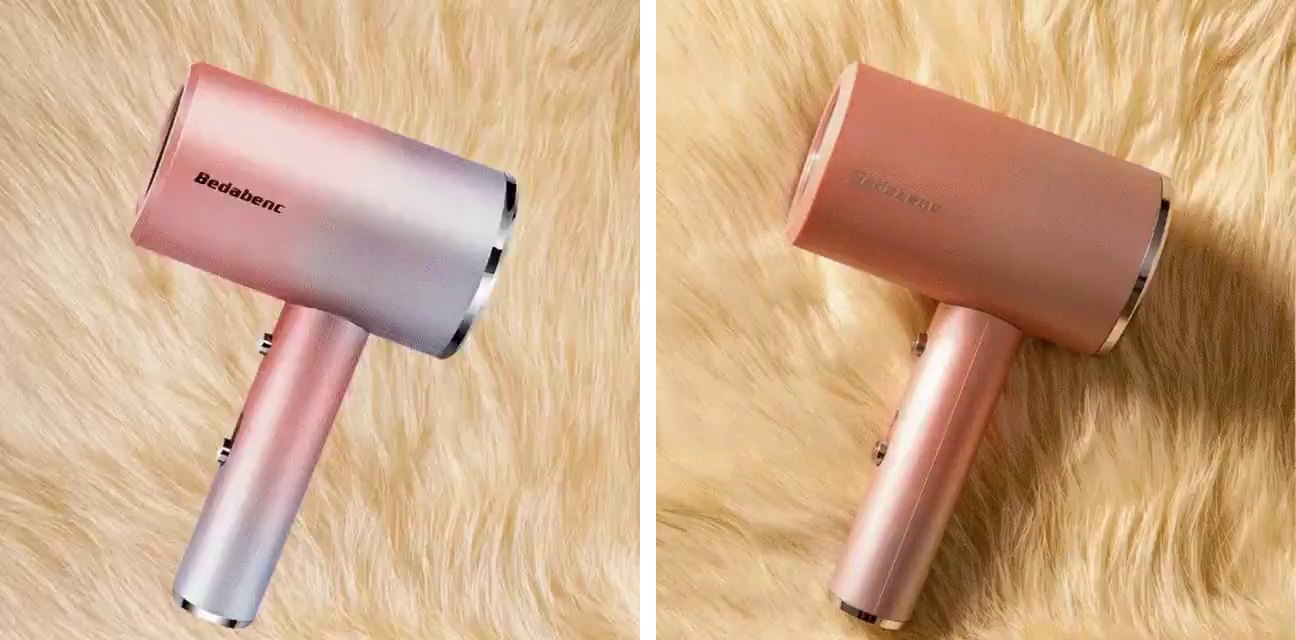
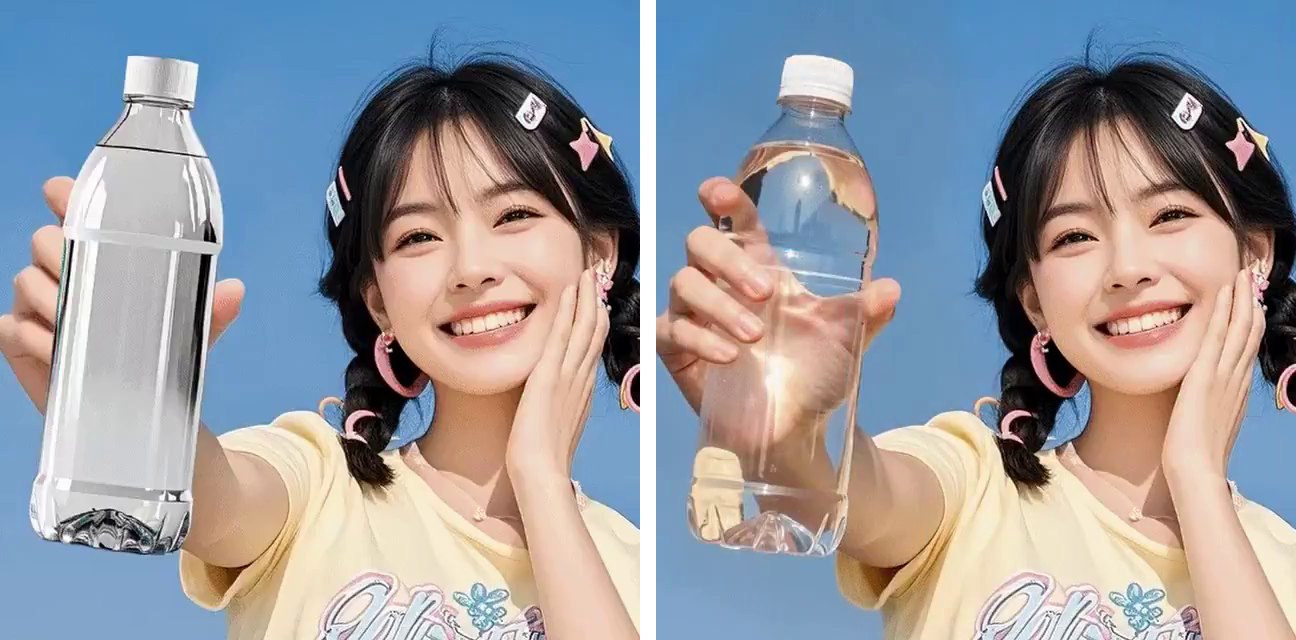
I measured what can be measured from the clip, six input-output pairs at 640 x 640 after X's re-encoding. Phase correlation finds zero global shift in all six, so the poster's "无偏移" ("no offset") holds for the frame. The local change is large: the share of pixels that moved by more than 30 of 255 levels runs from 9.3% (a serum bottle) to 42.7% (the hair dryer, whose fur background is relit too) (measured). The figures show what those pixels are. The model does not composite light onto the product; it redraws the product. Sometimes that is the point, a white-filled bottle becoming glass. Sometimes it is the product's own finish, a legible logo, or the colour of the drink inside.
For product photography that distinction is the whole job. A reply put it in one line: "Great lighting but changing the geometry of a product is really bad." The practical fix is the one every outpainting workflow already uses: keep the model's lighting and shadows outside the product, and paste the original product back on top. Whether the relit highlights survive that paste depends on the shot.
The licensing is unclear in a way that matters for the same audience. The card says to "follow the original project or upstream license", and the upstream is Qwen-Image-2.1's non-commercial research licence.
A week later: the same file, a different job
On 7 October RunningHubAI posted
a second Qwen-Image-2.1 LoRA,
and @wildmindai's repost sold it as a seamless blending LoRA that "locks subject position and size;
tilts background angle to match subject vanishing point". The card credits the same RunningHub
author page as the relight LoRA, and its file name says what it is for: 纠正背景透视溶图v2.0,
"correct the background perspective, blend, v2.0". The trigger word is pysj666 and the prompt is,
again, the training instruction:
pysj666 keep the subject position and size unchanged, adjust the background perspective angle to align with the subject's vanishing point. seamless blending between subject and background.I expected a fine-tune of the relight file, given the shared author and the "v2.0". The header says
otherwise. It is 58,224 bytes of JSON and lists the same 448 BF16 tensors in the same shapes, rank 32
on to_q, to_k, to_v, to_out.0 and the three MLP layers of all 32 blocks, 83,886,080
parameters. The file is 167,830,392 bytes, 16 bytes shorter than the relight file, and the whole
difference is in the header's metadata, which drops the trigger_word field. The metadata that differs is the
interesting part. The ModelScope account is a different one, the learning rate is 1e-4 (the training
script's default, 3.3 times the relight run's), and the run is 5,000 steps instead of 2,000, finished
on 4 October.
Then I range-read three tensors from both files and compared them. The lora_A of block 0's
to_q, which PEFT initialises at random, correlates at 0.003 between the two; two lora_B matrices
correlate at 0.008 and 0.012. A run that continued from the relight weights would keep most of its
A. This one started from its own seed. And it moved further: across nine layers I sampled (q, v and
the MLP output in blocks 0, 15 and 31), the Frobenius norm of is 2.6 to 4.6 times the relight
LoRA's. The higher rate and longer run show up as a bigger diff from the same base. "v2.0" therefore
numbers this blending line, whose first version is not on the Hub; I could not find a v1.0.
Nothing in the file explains the behaviour, and nothing could. The architecture is identical down to the byte, so the subject lock and the perspective change come from what the training pairs looked like and from the instruction. The mechanism is the one above: the composite rides in the sequence as the reference image, the target reads it, and 2.6 million parameters a block learn which parts to copy and which to redraw. Here the lesson is to copy the foreground and re-shoot everything behind it. The card says nothing about the data. A plausible recipe is a product photographed in a real room as the target, and as input the same product cut out and pasted onto a background generated or shot from another camera height, but that is a guess.
- task
- text-to-image
- safetensors
- 1 shard
- largest file
- 167.8 MB
- files
- 5
- downloads
- 0
- likes
- 16
Measured from the header: the same 448 BF16 tensors as the relight LoRA, rank 32, 83,886,080 parameters. Metadata: ModelScope, learning rate 1e-4, 5,000 steps. Trained from its own initialisation, not from the relight file. No data, metrics or licence of its own; the base model's licence is non-commercial.
repo last modified 2026-10-07
The card's poster and the repost's clip show the same three products as wipes, before and after. I took the end frames from the 1,024-pixel clip.
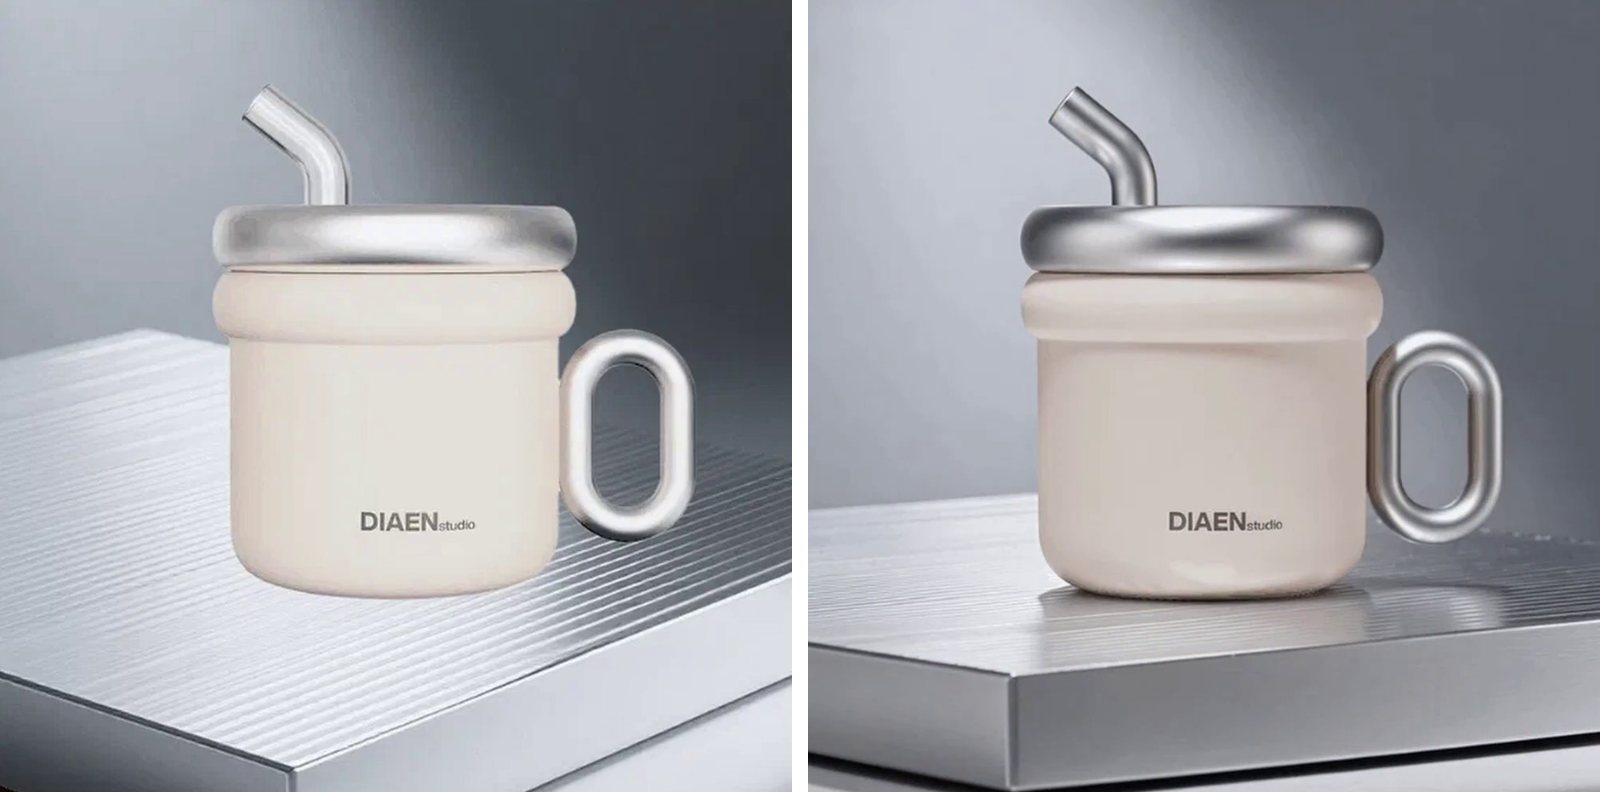
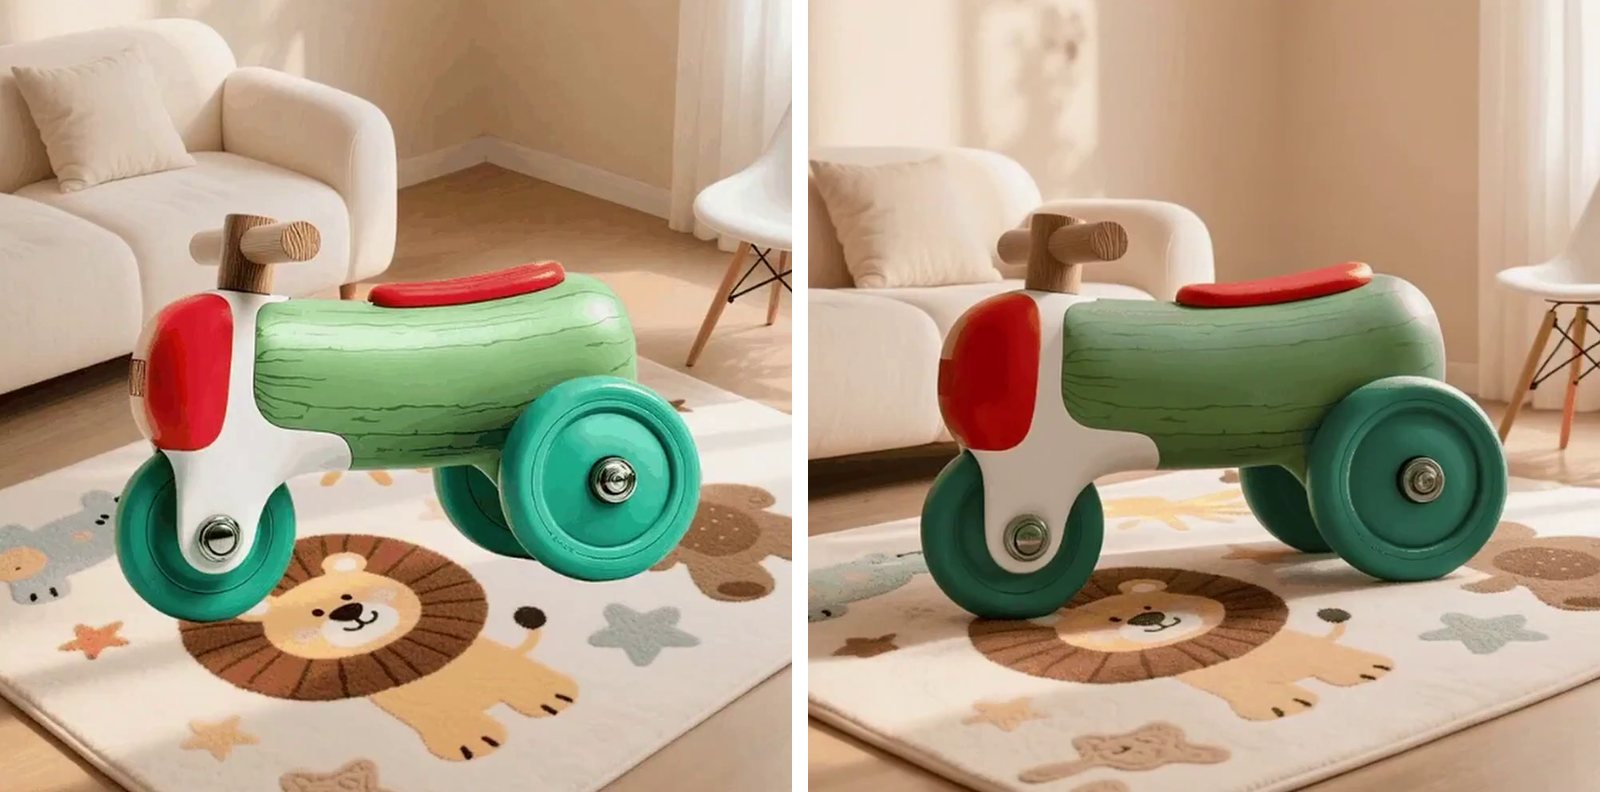
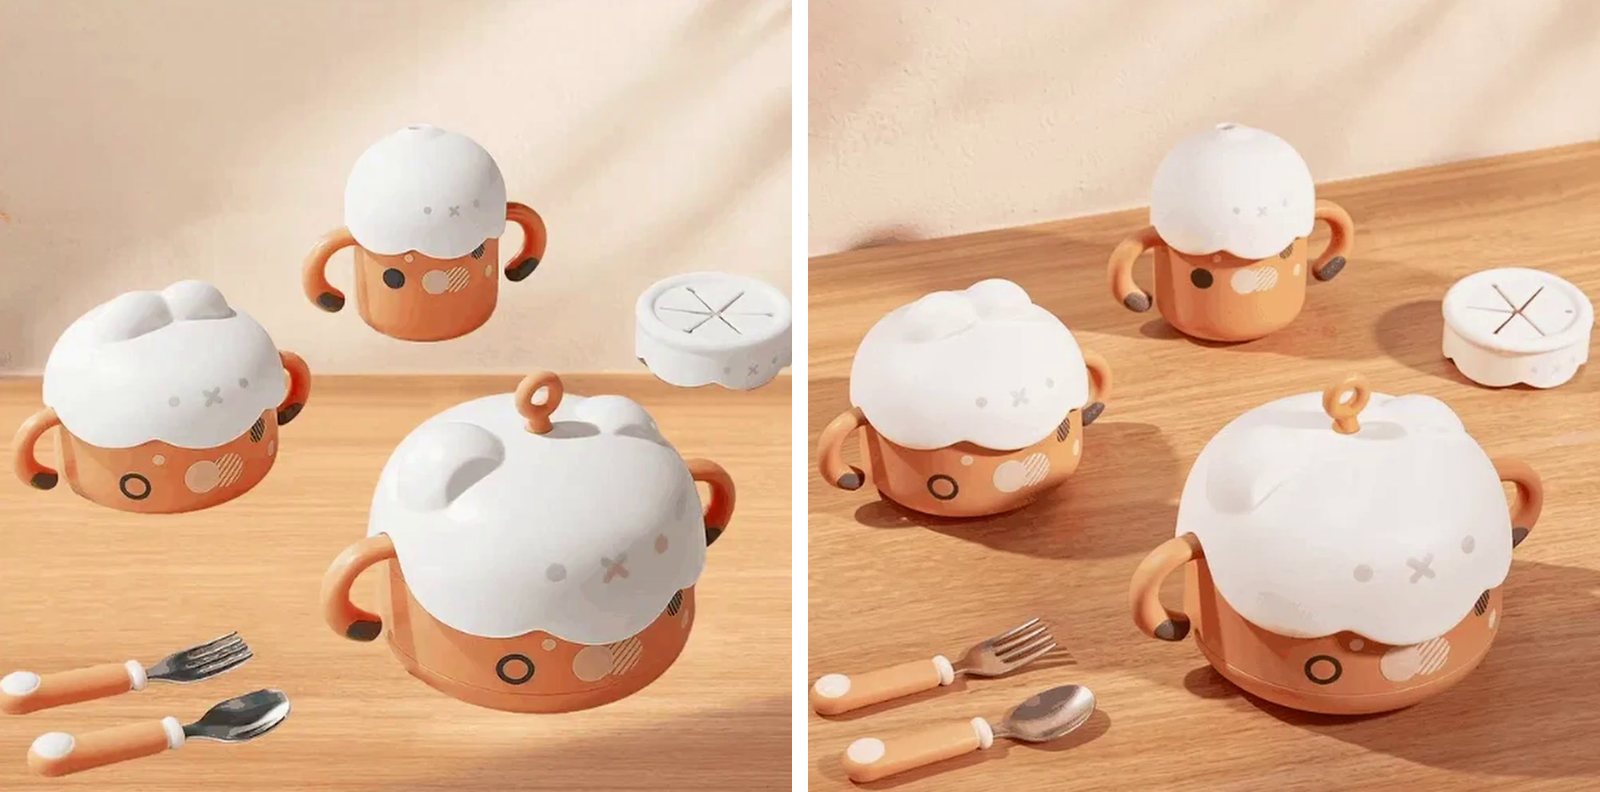
The claim holds in the way it is stated. Phase correlation finds zero global shift on all three pairs, and laid over each other the outlines of the cup, the trike and the bowls land where they were. The perspective claim holds by eye: each output lowers or raises the camera on the background until the floor or table plane agrees with the camera the product was shot from. That is the right fix for the most common tell in a pasted product shot, and it is something the relight LoRA never attempted.
It also redraws a lot. Between 47.7% and 56.5% of each frame's pixels move by more than 30 of 255 levels, against 9.3% to 42.7% for the relight demos, which is what re-shooting the whole background costs. And "locks the subject" means position and size, not pixels. The cup's clear straw becomes steel, the trike's greens go flat, the bowls' printed faces change. The advice from the relight section applies unchanged: keep the model's background and shadows, and put the original product back on top. With this LoRA that paste is easier, because the product has not moved.
Running them
Neither fits this site's CPU box in a useful time, so this piece runs nothing. For reference, the
paths are short. The restore card's ComfyUI route is the LTX-2.5_V2V_TiledFusion_Upscale.json
workflow from ComfyUI-LTXVideo with the LoRA swapped in at 1.0, tile 960 x 544, output FullHD, and a
second pass with the Detail Refine IC-LoRA at tile 1024 x 576 for 4K. The order matters: "refining
first sharpens the damage and desaturates the colour". The relight LoRA loads with an ordinary LoRA
loader on Qwen-Image-2.1 in ComfyUI, with the trigger prompt above and the composite as the reference
image, and so does the blending LoRA with its own trigger; the card ships no workflow for either. For the memory side of running a 22B video model at all, see
the WanGP piece; for few-step Qwen sampling,
the few-step piece.
The take
An IC-LoRA is a small idea with a large reach. Put a clean reference into the generator's own sequence, on the same coordinates as the output, and a low-rank diff teaches the model a mapping from one to the other: degraded to clean, pasted to lit, gray to filled. Lightricks ships more than twenty of these for LTX, from deblur to day-to-night, and RunningHub's file shows the same trick on an image editor, trained in 2,000 steps.
What the trick cannot do is add information. The restore LoRA draws twenty times the pixels it is given and every colour, and its card is candid that the result is a reconstruction. The relight LoRA redraws products along with their light, and its blending sibling re-shoots the room while keeping the product in place, though not its every detail. Both are strong editing tools. Neither is a measurement of what was there. For the block both sit on, see the diffusion transformer explainer, and for how shared rotary coordinates line a reference up with its target, the RoPE explainer.