2026-10-06 · 37 min · ecosystem · benchmarks · calibration · multimodal · on-device · inference · fine-tuning
Why read this
Notabletop 60%Recomputes d1's launch chart from its own JSON (exact, but 'four of six' only at rounding) and reads llama.cpp's six decision readouts from source.
- Analysis found nowhere else
- Runs on a consumer GPU
- Concrete numbers to act on
LLM architectureMixed licencesPractitioner roundup
How this was scored
- Is it new?
- 1 of 3: An incremental tweak
- Can I trust it?
- 2 of 3: Measures key facts from files, code or configs
- Can I run it?
- 2 of 3: Open code or weights with real limits
- Will I understand it?
- 2 of 3: Mechanism from first principles with figures
- Can I act on it?
- 2 of 3: A concrete recipe, numbers or comparison
- Will it last?
- 1 of 3: Relevant for months
- Does it affect many?
- 1 of 3: A specialist community
- Only here?
- 3 of 3: The only place this analysis exists
Score 64 of 100, ranked 282 of 701 rated articles. Each question is answered 0–3 by hand, and a 3 is rare. How articles are scored
Week two was seven open decision models and the discovery that most "beats Jev" numbers stood on JevBench's public items. Week three was the most serious architectures yet and the thinnest evaluations: not one new model on a sealed or independent board.
Updated 12 October: a section on THX-01, a fine-tuned Laya that claims to run on a phone and has a free API.
Week four is four posts, and none is mainly about a better model. All four
are about where a decision model runs: behind a closed API that now accepts images (Liquid's
d1), as open weights in six sizes loaded through Transformers (vLLM Semantic
Router's Decision 2.0), natively on a Mac through Core ML (FluidUse), and
inside llama.cpp's server behind the same /v1/systemone endpoint as Jev
itself.
The evaluation story inverts. The one publisher that shipped its raw results is the closed one. The open family leaves Jev out of its tables; the on-device port checks that it matches upstream, never whether it is right; llama.cpp makes no accuracy claim and tells you to calibrate your own cutoffs.
Measured means I read it from a file, a safetensors header or source code, or recomputed it from a published file; reported means the publisher's figure, which I could not re-run; reasoned means my inference from the other two. Code was read, never executed. All checked on 2026-10-06.
The one idea, again
A decision model answers a schema of typed questions — choice, score,
noul (yes/no) — by returning a probability for every option, read in one
forward pass, with no tokens generated and nothing to parse. The full
treatment is in what Jev actually is, why
any model can be Jev and what decision models
cannot do; and Jev is not
deterministic is why "one pass" does not
mean "same answer every time."
The open ones still sort into three readout families: a letter readout (options become letters, read the letters' next-token logits), a pointer (each option's end-token hidden state is scored against the question's, as in Kev), and a joint scorer (a trained head scores everything at once, as in clef). This week (measured, from configs and code): d1 is closed and undisclosed; Decision 2.0 is a pointer with one head design across six sizes; FluidUse re-implements that pointer in Core ML; and llama.cpp is not a model but six readouts behind one endpoint.
d1 with vision (Liquid): the best receipt of the week is a JSON file
Liquid launched d1 as a text model on 29 September. The week-four post adds images: "images, text or both as inputs," tested "against GPT-6.1 Sol and Claude Opus 5.5 on six real applications," matching or beating GPT-6.1 Sol "on four of them," at "19x to 200x less" cost (reported).
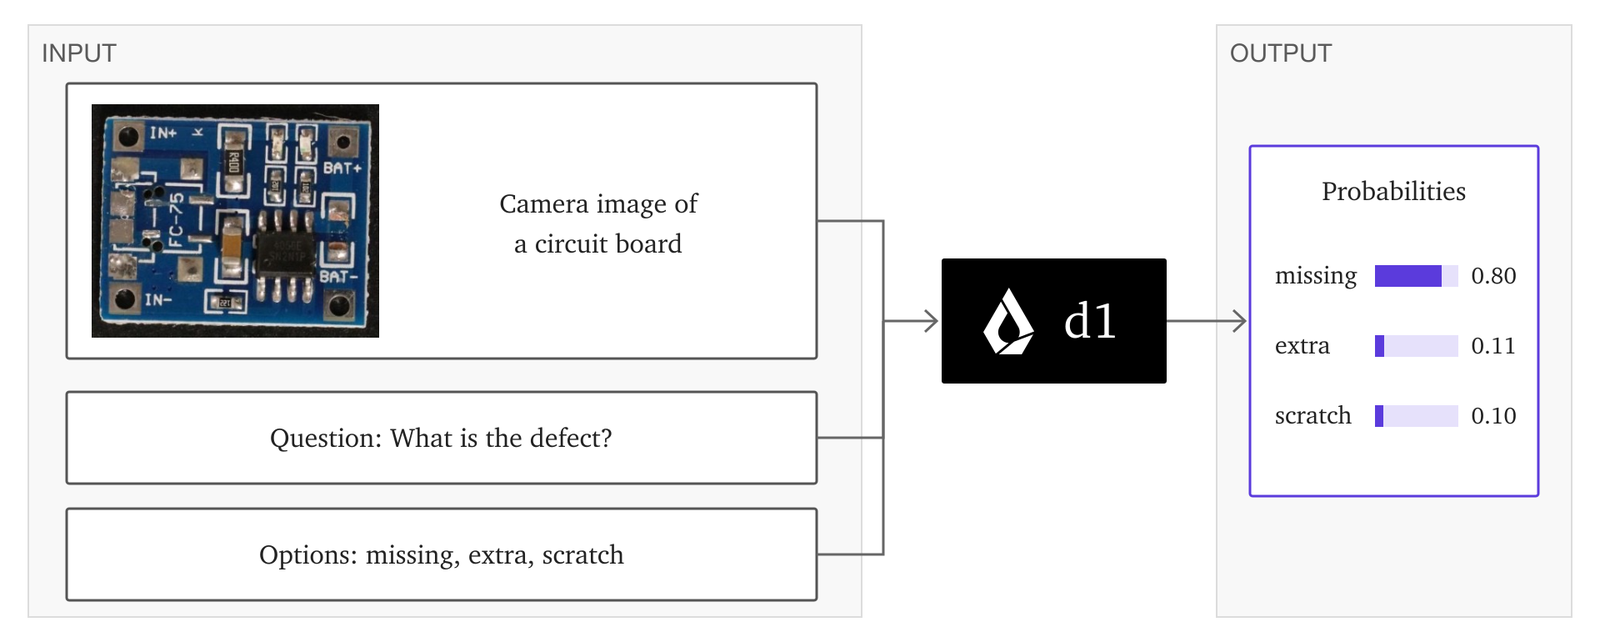
What can be checked is the interface. The request goes to
https://api.liquid.ai/decisions/v1/systemone, the docs install TypeSafe's own
typesafe-sdk and point its base_url at Liquid, and the question types are
Jev's noul, choice and score — so d1 is a drop-in for Jev's wire format,
the same thing week three watched
SGLang and Unsloth build. Billing is input tokens only, at $0.04 per million.
An image costs 1.5 tokens per 32×32 patch, so a 1024×1024 image is 1,536
tokens, and "every question is charged for its text and all the images again"
(measured, from the docs). That last clause matters for vision: ask five
questions about one photo and you pay for the photo five times. Requests take
up to 8 images and 10,000 patches.
The chart, and the file behind it
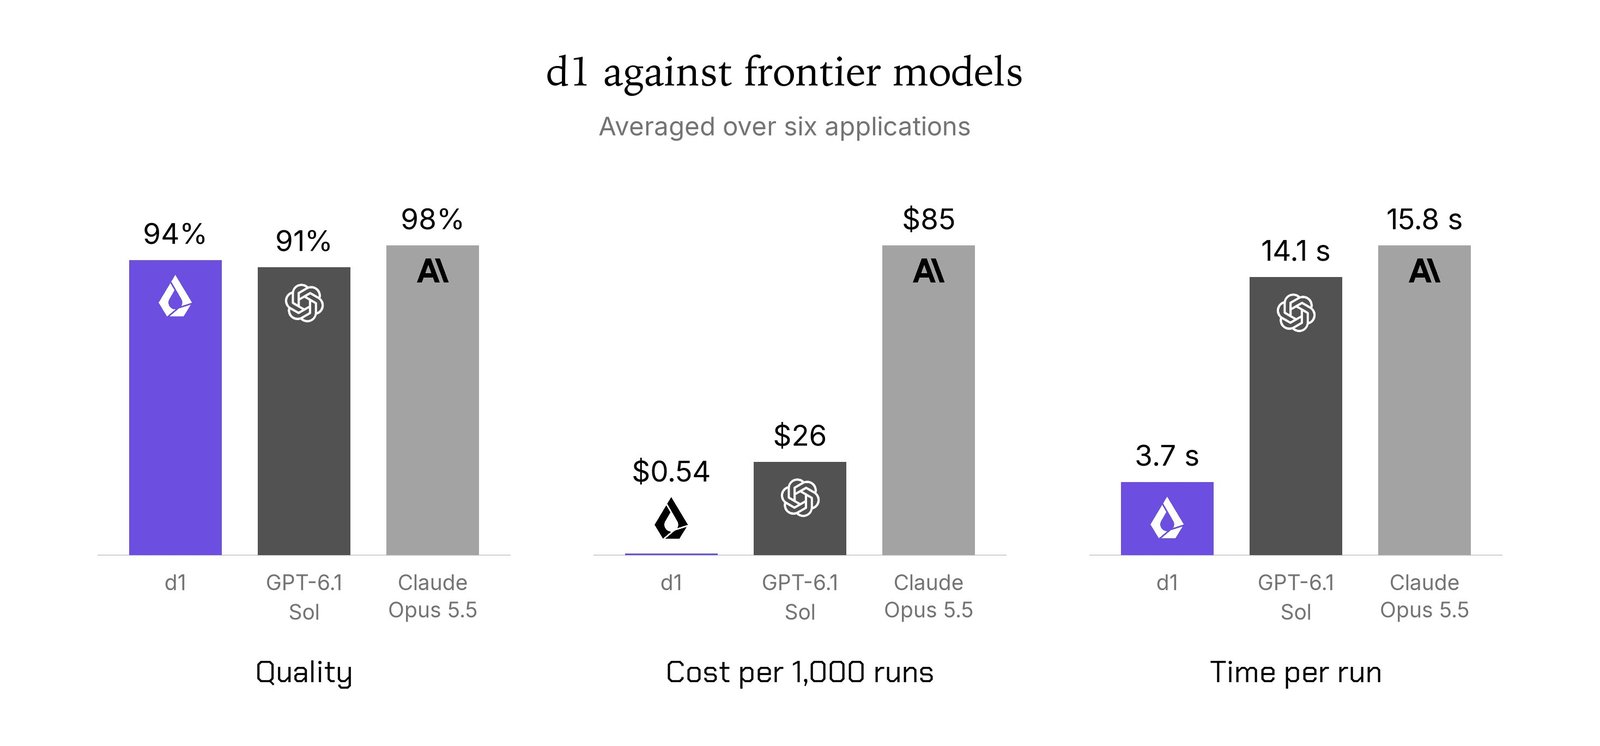
The d1 playground is a static site, and its comparison panel loads
demos/data/compare.json: per application and per model, quality, cost,
seconds, request counts and token counts, stamped "measured 2026-10-05". I
recomputed the chart from it (measured):
- Quality averages to 93.6%, 91.3% and 98.2% — the chart's 94, 91 and 98.
- Time averages to 3.74, 14.15 and 15.75 seconds — the chart's 3.7, 14.1 and 15.8.
- Cost reproduces only one way. With Smart Folders' cost taken per passage (the file stores it per 105 passages) and every other application per run, the means are $0.54, $25.5 and $84.7 per 1,000 runs — the chart's $0.54, $26 and $85. The blog's methodology confirms that Smart Folders' "cost is per 1,000 passages."
So the chart is honest arithmetic over an odd unit: "cost per 1,000 runs" averages a coding session, a passage, a 150-ticket query, a photo, a question and a web goal, and Code Search and Smart Filter make up most of the frontier models' averages (reasoned). The per-application cost ratios are the cleaner number: GPT-6.1 Sol costs 18.7x d1's on context compaction and up to 56.5x on Smart Folders; Opus costs 61.4x on compaction and 200.1x on Code Search (measured, from the file). That is exactly the post's "19x to 200x."
"Matches or beats GPT-6.1 Sol on four"
Per application (measured, from the file):
| application | d1 | GPT-6.1 Sol | Claude Opus 5.5 | sample |
|---|---|---|---|---|
| Context Compaction | 7 of 7 | 6 of 7 | 7 of 7 | 7 needed outputs |
| Visual Inspection | 90.6% | 82.3% | 91.7% | 96 photos |
| Web Agent | 7 of 7 | 7 of 7 | 7 of 7 | 7 goals |
| Smart Filter (F1) | 94.7 | 95.2 | 97.6 | 150 tickets |
| Smart Folders | 96.2% | 98.1% | 100% | 105 passages |
| Code Search | 12 of 15 | 13 of 15 | 15 of 15 | 15 questions |
d1 beats GPT-6.1 Sol on two (compaction, inspection), ties on one (web), and loses on three. The fourth "match" is Smart Filter, where the file's own display string rounds both F1 scores to "95%" — 94.7 against 95.2 unrounded. That is within any reasonable noise for 150 tickets, so "matches" is defensible; it is also the generous reading. Against Opus, d1 ties on compaction and web and trails on the other four.
Each application was run once, on seven to 150 items. Liquid's methodology note adds something most launch posts never do: "We wrote six of the 15 code questions and two of the four compaction sessions after d1's pipeline was set." That is a disclosure in d1's favour — those items were not tuned against — and a reminder of how small the sets are. The chat models answered in batches (48 requests for Smart Filter against d1's 900) at list prices without prompt caching. The chart's 3.7 seconds is per run with "up to 8 requests in flight"; the post's "text decisions in 200 to 300 ms" is a separate claim this file cannot check (reported).
The inspection result, and the threshold it needs
"85% to 97% accuracy across four VisA inspection tasks… without task-specific
training" (reported). The weights were not trained on VisA. The decision cut
was fitted per line. The playground's inspection/index.json stores, for each
production line, a threshold "calibrated at … on … good and … defective parts
that are not shown here" (measured, from the file and the page code):
| line | threshold on noul | calibration parts | balanced accuracy at calibration |
|---|---|---|---|
| circuit boards | 0.484 | 98 good, 88 defective | 0.952 |
| candles | 0.453 | 98 good, 87 defective | 0.902 |
| cashews | 0.126 | 48 good, 88 defective | 0.900 |
| chewing gum | 0.725 | 49 good, 88 defective | 0.960 |
Two things follow (reasoned). First, a noul of 0.5 does not mean the same
thing on every line: the cashew line calls a part defective at 0.126, the gum
line only at 0.725. Liquid's docs say the model "returns calibrated
probabilities"; a per-line cut ranging from 0.126 to 0.725 says that, for
defect detection at least, you still fit your own threshold on labelled
examples, and the demo did. Second, every model in the comparison also sees "a
good part from the same line next to the part to inspect," so this is
reference-based inspection, not zero-shot anomaly detection. The 85–97% range
itself I could not reproduce from these files: the calibration accuracies run
90–96%, and the comparison file's d1 figure over all 96 photos is 90.6%.
The games are reported and uncheckable without the harness: Tetris from 70 to 81 cleared lines when the screen is added to a text description, Wordle 12 of 12 solved in 3.8 guesses from screenshots, and Quick, Draw! at 5.2 of 6 doodles named among 62 words (random: 0.6).
The blog calls d1 "the first to extend these capabilities to images." It is
not: Jev-Omni went
multimodal first, clef and JEMM read images in week three, and a reply to the
launch post points at Mapika/decider-2b-vision, an Apache-2.0 vision decision
model on Hugging Face since 16 September (measured, from the Hub API). Its card
reports Visual7W 0.89. The one comparison to Jev, the chart above, is Liquid's own
run, and the release has no calibration number. Open weights are promised only
for "upcoming models."
Decision 2.0 (vLLM Semantic Router): six sizes, one head
The post is one line: "our newest state-of-the-art decision models, open in every size from 0.6B to 27B." The collection has six, each named, each Apache-2.0:
| model | base | backbone parameters (measured) | head parameters (measured) |
|---|---|---|---|
| Kai-0.6B | Qwen3-0.6B-Base | 596,049,920 | 1,053,184 |
| Eos-0.8B | Decision 1.0 Eos | 752,393,024 | 1,053,184 |
| Sol-2B | Decision 1.0 Sol | 1,881,825,088 | 2,105,856 |
| Nox-4B | Qwen3.5-4B-Base | 4,205,751,296 | 2,632,192 |
| Lux-9B | Decision 1.0 Lux | 7,936,684,544 | 4,211,200 |
| Vega-27B | Qwen3.8-27B + LoRA | rank-512 LoRA, 3,735,289,856 | 5,263,872 |
Backbone counts are safetensors index and header sums; head counts are the
decision_head.safetensors headers, read by range request.
- architecture
- Decision2Model
- task
- feature-extraction
- library
- transformers
- license
- apache-2.0
- safetensors
- 2 shards
- largest file
- 1.50 GB
- files
- 36
- downloads
- 725
- likes
- 29
Every weight of Qwen3-0.6B-Base fine-tuned plus a new 1,053,184-parameter FP32 endpoint head; the release is a uniform average of six fine-tunes (two recipes, three seeds). Raw probabilities at temperature 1, no calibration file. Apache-2.0.
repo last modified 2026-10-03
The head, from the code
The repositories ship their runtime as remote code, and
decision2/_vendor/dev2model/decision_model.py is short enough to read whole
(measured). Each question becomes its own prompt:
Context:
<state>

Task type: choice
Question:
<instructions>
Options:
<option>
{"key": "returns", "description": "Refunds, replacements and damaged deliveries"}
</option>
...

Select the single option best supported by the context and instructions.
Decision:
The model runs that through the backbone once. It keeps the last hidden state
of each </option> block (the "candidate endpoints") and the hidden state of
the final token (the "global query"). The CandidateHead scores each option as
a bilinear term plus a small MLP term:
where and are the layer-normed option and query states and every projection is 256 wide. A softmax over the is the answer. The head is identical across sizes; only its input width changes (1,024 for Kai up to 5,120 for Vega), which is why it grows from about one to about five million parameters.
This is the pointer family. Because the backbone is causal, an option sees the options listed before it and not those after, so option order can still move the answer; there is no reverse-and-average in the runtime. The cap is 255 options. Every question is a separate prompt, but the questions share their context prefix, which is what lets the Core ML port below run them together.
Two more things the files say (measured). config.json carries "calibration": null, and the manifest calls the output "raw probabilities (temperature 1; no
calibration file)," with fixed offsets for five-level score questions; the
loss has an optional Brier term, so calibration is something training may push
toward, not something fitted after. And the releases are soups: Kai averages six
full fine-tunes, and Vega averages LoRA adapters with their "factors
concatenated along the rank," which is how a rank-512 adapter holds 3.7 billion
parameters.
The 27B's card says "29.37B" parameters. That is the Qwen3.8-27B text model's 25,624,600,064 plus the 3,735,289,856-parameter LoRA plus the head, which sum to 29,365,153,792 (reasoned). Merge the LoRA, as you would to serve it, and it is a 25.6B model with a 5-million-parameter head.
What the evaluation leaves out
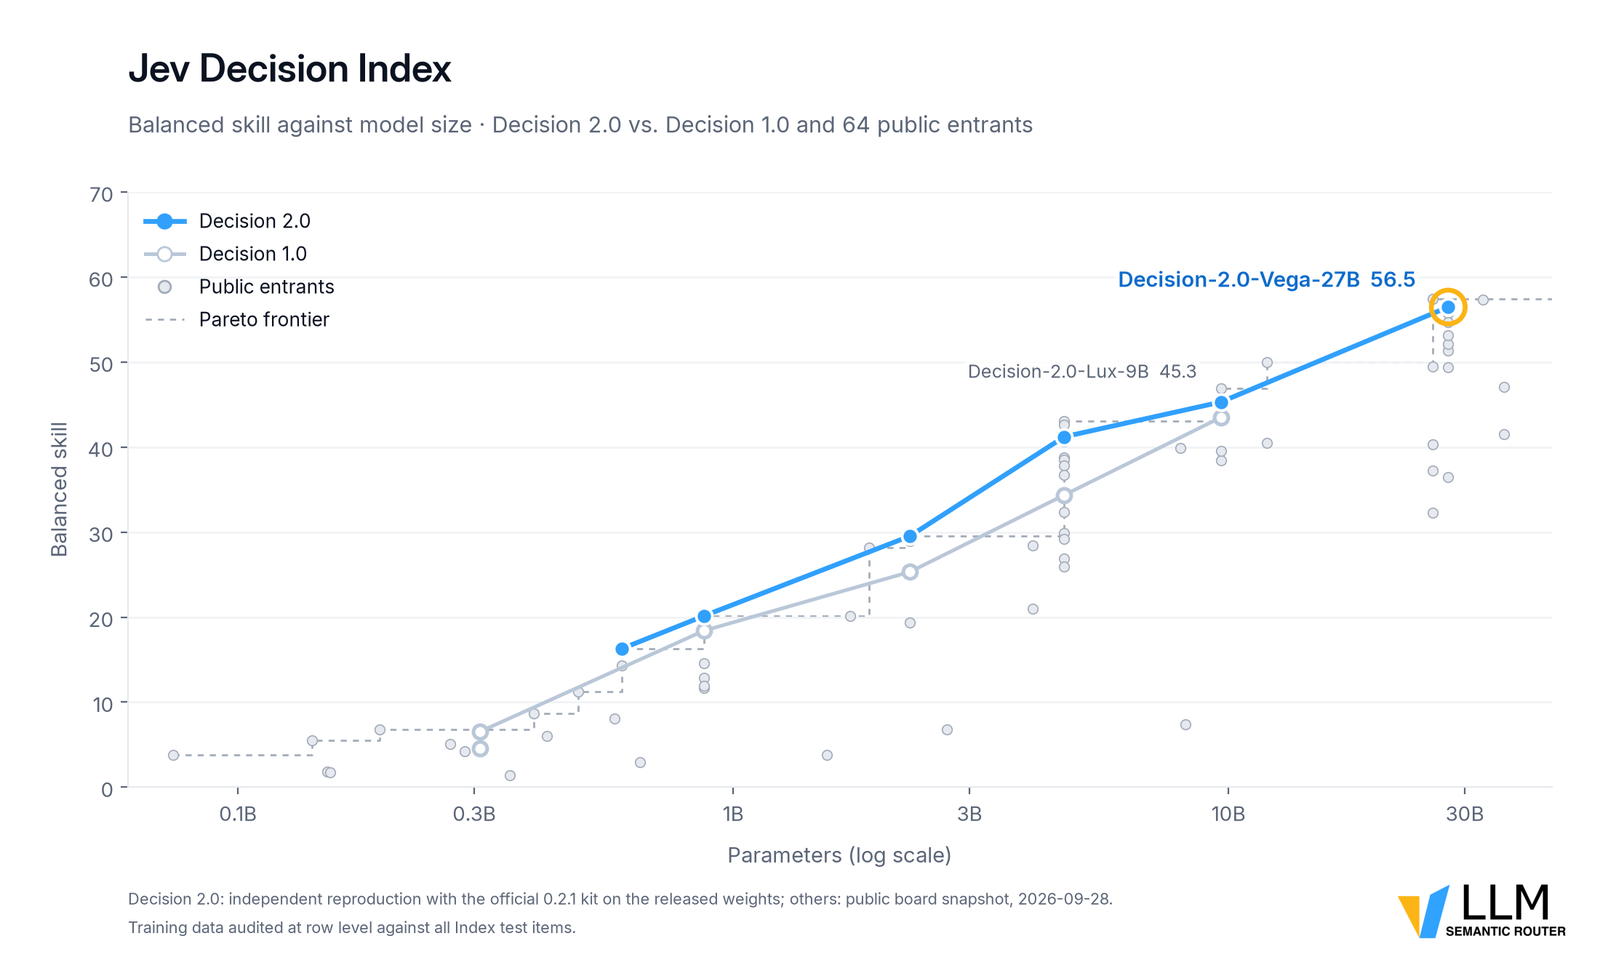
Each card has three columns: JevArena, a "human-labelled transfer" median over 15 tasks, and the Jev Decision Index. Every size leads the same-size models it chose to list (reported): Kai 48.6 on JevArena against GLiNER2.5-Decide's 42.5, Nox 63.6 against Decider 4B's 61.9, Vega 74.0 against AutoJev-27B's 72.1. The cards are careful about the close calls — Nox and Vega are "statistically level" with the runner-up, their words.
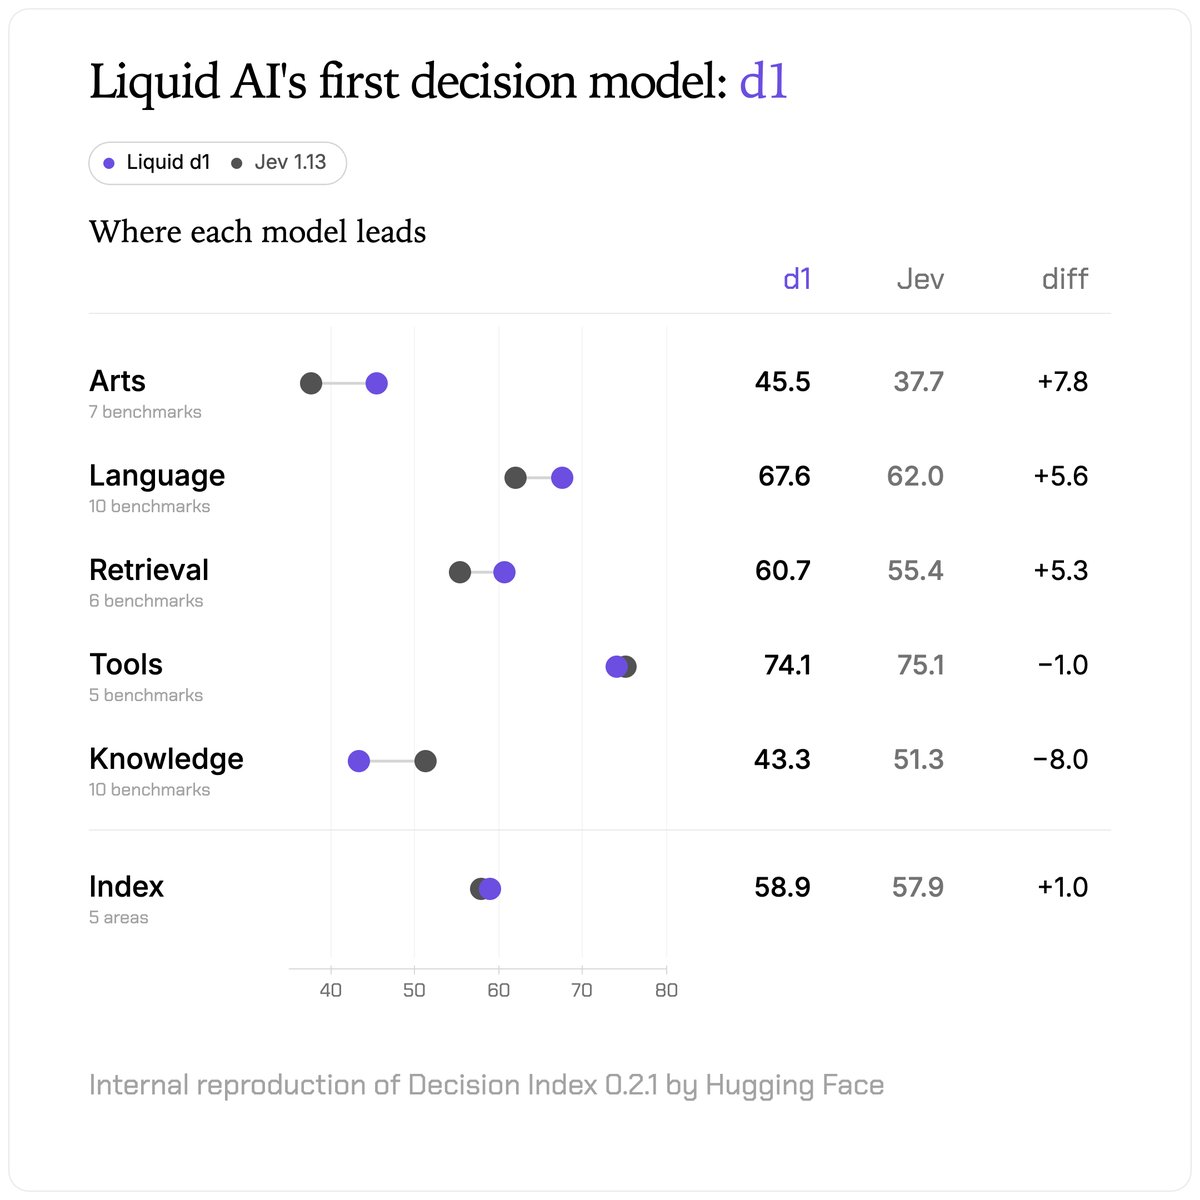
What none of the six tables has is a row for Jev. The nearest you can get is to line up numbers from different runners on the same Index version (all reported): Vega's 56.5, Liquid's run putting Jev at 57.9 and d1 at 58.9, and the decider README placing a stock Gemma-4-31B read through its letter readout at 57.33. On that basis the largest Decision 2.0 model sits just under Jev and just under a stock checkpoint with a temperature fitted per option count (reasoned, from three separate runs). The Pareto figure says the same thing in its own picture.
Smaller things: Lux's card gives 46.3 on the Index while Vega's card puts Lux at 45.3 (measured); "training data audited at row level against all Index test items" is a contamination claim I cannot check without the data; and latencies are medians "on a single GPU," unnamed, from 4.9 ms for Kai to 71.4 ms for Vega (reported).
- architecture
- Decision2Model
- task
- feature-extraction
- library
- transformers
- license
- apache-2.0
- safetensors
- 2 shards
- largest file
- 14.94 GB
- files
- 35
- downloads
- 389
- likes
- 55
A rank-512, alpha-1024 LoRA (3,735,289,856 FP32 parameters, a uniform soup of several adapters) for Qwen3.8-27B, plus a 5,263,872-parameter endpoint head. The card's 29.37B counts the unmerged adapter. Apache-2.0.
repo last modified 2026-10-03
FluidUse: Decision 2.0 on a Mac, at 15 issues a second
FluidInference's port is the week's best engineering, and as with their GLiNER-2.5 port and SigLIP 2 port — both FluidUse, both covered — the write-up is precise about what it checked.
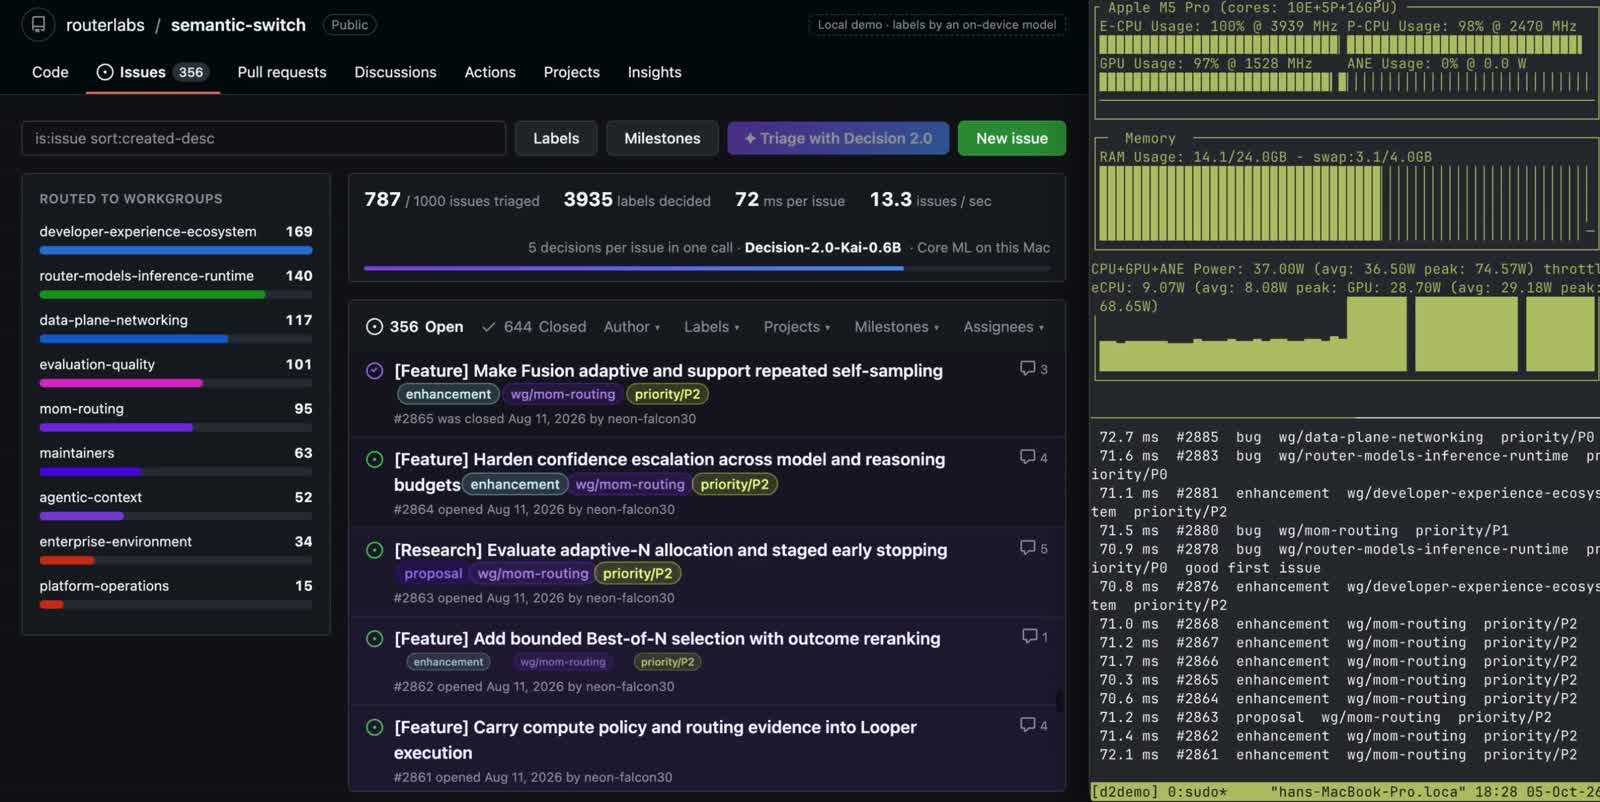
The port. Kai and Eos become fp16 Core ML packages of 1.1 GB and 1.4 GB that run on the GPU; the Neural Engine was slower, 72 ms against 28 ms on Kai's quickstart (reported). The clever part is the packing. All questions of a request go in one call: the shared context is the prefix, each question's tokens follow, and the mask lets a question see the prefix and itself but not the others, so "every question therefore sees exactly the prompt it would see alone." Eos is harder, because its Gated DeltaNet layers carry a recurrent state rather than a cache; the port runs the prefix once and restarts each question from its final state.
Parity, measured properly. On 400 requests (2,000 decisions) from the
typed-decisions test split: 0 token mismatches, 5 flipped answers for Kai and
4 for Eos, all near-ties with an upstream top-two margin of at most 0.009, and a
largest probability difference of 0.0082 (reported, with the script to
reproduce it). On an M5 Pro a five-question request takes 63 ms on Kai and
113 ms on Eos, against 418 and 1,595 ms for the upstream PyTorch runtime on MPS.
The demo. IssueTriageDemo takes 1,000 real issues from
vllm-project/semantic-router, strips their labels, and asks five questions per
issue in one call: type, owning workgroup, priority, needs-info and
good-first-issue. Its README: 66.8 ms per issue, 15.0 issues a second, 5,000
decisions in 67 seconds (reported). Its check is that the labels "match the
Python Core ML reference demo on every issue compared (626 of 626)" — the port
agrees with itself across languages. It never compares the labels with the
real ones it stripped, so the demo says nothing about whether the triage is
right (measured, from the code and README).
Two details in TriageModel.swift say more (measured). The priority question's
score "ranks issues well but its argmax is P0 for most issues," so the demo
cuts it at this repository's 90th and 50th percentiles (1.452 and 1.251): about
10% of issues come out P0 by construction. And the yes/no flags fire at 0.6, a
hand-set cut.
The one accuracy number. The parity tables are the only accuracy figures in the release, and the cards say plainly they "are not the model card's benchmark protocol." On that split, Kai answers 0.423 of choice questions, 0.628 of yes/no and 0.398 of score questions correctly; Eos 0.430, 0.598 and 0.379 (reported). A yes/no accuracy of 0.628 is not far above a coin's half (reasoned), on a held-out set that is not this model's own benchmark. It is also the only number for these two models that someone other than vllm-sr produced.
- license
- apache-2.0
- largest file
- 1.19 GB
- files
- 23
- downloads
- 0
- likes
- 0
Decision-2.0-Kai-0.6B as one fp16 Core ML multifunction package (1.1 GB, four fixed shapes), GPU-only by measurement. Parity with upstream on 2,000 decisions: 0 token mismatches, 5 near-tie flips. Apache-2.0.
repo last modified 2026-10-05
llama.cpp /v1/systemone: one endpoint, six readouts
The any model can be Jev piece found that
llama.cpp had no decision endpoint, and that the nearest primitive returned the
top-N tokens rather than the ones you asked about. That is now out of date.
ggml-org's blog post of 2 October announces /v1/systemone in the server,
"follows the System One format introduced with TypeSafe's Jev," and lists six
supported models (reported): Julia-1 (144M, mmBERT-small), Laya (421M,
ModernBERT-large), Kev-4B, lev (4B), OpenJev (27B, reads images) and Clef (27B),
at a median 3 ms to 43 ms per question on one RTX PRO 6000.
Its design is the opposite of SGLang's (measured, from the server code and
README). SGLang turns any chat model into a letter readout with a flag.
llama.cpp serves only native decision models whose GGUF carries
<arch>.decision.* metadata — "a language model that classifies with prompts
does not get decisions" — and it implements each family's own readout:
type in common.h | how an option is scored | used by |
|---|---|---|
OPENJEV | logit of one label token per option, at the last prompt token | OpenJev |
LEV | the same; noul read from a rating scale; choice run in two orders and averaged | lev |
NIMBLE | the same, with every question listed in the prompt | Bespoke Nimble |
KEV | dot product of the last token's hidden state with each option's end token | Kev-4B |
LAYA | one output column per question type, at each option's marker token | Laya, Julia-1 |
CLEF | all questions in one prompt; option i's score at output row i | Clef |
Decision 2.0's bilinear-plus-MLP head has no type here, so none of this week's open family runs on llama.cpp yet (measured).
After the scores, every family goes through the same format_answer: divide by
a temperature stored in the GGUF (per question type and, where the file
provides them, per option-count bucket), softmax, average the variants, and report. choice
confidence is TypeSafe's formula, ; score is the
expected level. The blog's example response checks against it exactly
(measured): billing at 0.9049 of three options gives confidence
; the urgency probabilities 0.036, 0.1937,
0.2225 and 0.5478 give an expected level of 2.2821 and a score confidence of
0.2821. That last pair is not a coincidence: with the mode on the top of four
levels, the score confidence reduces to the score minus two (reasoned, from the
formula).
"One forward pass" is true with qualifications, and the code is explicit about
them. Questions are answered independently, each in its own prompt, except on
Clef, which decides them jointly; for Kev, lev, OpenJev and Nimble the server
groups the prompts so the shared state is evaluated once. And lev's choice
runs twice, the second time with the options reversed, "to cancel the
preference for the first label." The widget above shows what that does and does
not cancel (reasoned): a first-slot bonus lands on the first option in one order
and the last in the other, so averaging splits it between the two ends rather
than removing it, and with three or more options the middle loses.
The choice cap depends on the model: "52 for openjev, 255 for laya and
clef" (measured, README). And the server's docs end the way SGLang's did: "The probabilities are scaled with the temperatures stored
in the model file. They are not guaranteed to be calibrated for your data." The
blog makes the same point by example: a vague ticket "scored 0.25 with Julia-1
but 0.80 with Kev-4B." A cutoff belongs to a model, not to the endpoint.
What week four measured
Deployment is solved four ways: a closed API, Transformers remote code,
Core ML, and llama.cpp — and d1, Decision 2.0's system_one() and llama.cpp
all answer in the same System One JSON (reasoned).
The receipts came from the closed lab. Liquid published the file behind its chart, which items were written late, and the per-line thresholds its demo needs. Decision 2.0's comparisons stop at same-size open models. FluidUse proved its port faithful, not right. llama.cpp claimed only speed.
Calibration is still the gap. Liquid's docs call d1's outputs calibrated and publish no reliability number, and its own demo fits a threshold per line. Decision 2.0 ships raw temperature-1 probabilities. llama.cpp applies whatever temperature the GGUF carries and disclaims the result. Nobody this week shipped an ECE.
If you are choosing this week
All reasoned, from the evidence above:
- Images, and you do not need the weights: d1, with the per-line threshold work its own demo did, and remembering each question re-bills each image.
- Open weights at a size you can pick: Decision 2.0, Apache-2.0 from 0.6B to 27B, one head design. Measure it against Jev on your data, because its cards do not.
- On a Mac: FluidUse's Kai port, 63 ms for five questions, faithful to upstream. Check accuracy on your labels; the demo did not.
- Local, behind the Jev API, today: llama.cpp with Kev-4B, Laya, lev, OpenJev or Clef. Set the confidence cutoff per model.
The take
Week four turned decision models into infrastructure: an image-reading API, six open sizes, a native Mac runtime and a llama.cpp endpoint, all within days. The best-documented claim of the week came with its own JSON file, and checking it took ten minutes: the averages are exact, the "four of six" is generous by half a point, and the "never trained for this" inspection result needs a threshold fitted per production line.
The open releases did the expensive engineering and skipped the expensive comparison: six sizes with no Jev row, a fast demo with no accuracy, an endpoint that tells you to calibrate. All useful. None, yet, tells you how often it is right.
THX-01: Laya's multilingual checkpoint, trained on tickets
Added 12 October 2026.
Six days after this piece went up, a post on X introduced THX-01, an Azerbaijani-first decision model from HAL-X AI: "An open-source decision model with 322M parameters that beats Jev on some benchmarks... Runs locally on a PHONE... And now has a FREE API?!" Two of those three claims are about where the model runs, so it belongs in this week's piece. Someone in the replies linked Laya, and the poster answered "Laya is great too!", which reads like two unrelated projects. They are not unrelated, and that turned out to be the most interesting thing in the release.
- architecture
- THXDecisionModel
- task
- text-classification
- library
- thx01
- license
- apache-2.0
- safetensors
- 1 shard
- largest file
- 643.8 MB
- files
- 71
- downloads
- 41
- likes
- 39
- languages
- az, en, ru, tr, de, fr
repo last modified 2026-10-08
What is in the 322M
The model card gives jhu-clsp/mmBERT-base as the base model, and the NOTICE file
credits mmBERT and nothing else. The safetensors header agrees on size: 170 tensors,
321,908,998 values, all fp16. The 256,000-by-768 token embedding table holds 196.6M of
them, the 22 encoder layers 110.3M, a two-layer transformer head 14.2M, the option scorer
0.59M, a small "act" head 198,402, and there are three temperatures. So the 322M is real,
and 61% of it is a lookup table. The arithmetic per token is a 110M encoder's.
Laya ships a checkpoint of exactly that shape. Its Hub repo has a multilingual/ folder
holding mmBERT-base with Laya's head, 322M, in a 643,835,514-byte file; THX-01's is
643,835,524 bytes. Same tensor names, same shapes. Matching shapes prove nothing on their
own, since anyone can put Laya's head on mmBERT-base, so I fetched the same byte ranges from
both files and compared values. A head trained from a fresh random initialisation would
correlate with Laya's at about zero. These don't:
- the act head's 198,402 values are bit-identical, and so is the temperature buffer (1, 1, 1);
- the two head layers and the scorer correlate at 0.975 to 0.983 with Laya's, after a change of about a fifth of their norm;
- the encoder layers correlate at 0.9987 (about 5% change), and the token embedding at 0.999999, which fits the card's note that the embedding matrix was frozen.
THX-01 is Laya's multilingual checkpoint, trained further. The card's benchmark tables have a column called "initialisation" that it never defines; it starts AG News at 94.1%, which no freshly initialised head would do. My reading is that the column is Laya.
The library says the same thing. pip install thx01 fetches version 1.0.0, uploaded on 8
October, and the wheel's twelve modules are byte-identical to the thx01/ folder in the
Hub repo. I diffed six of them against Laya's package at commit 682ac67: presets.py is
Laya's line for line, shortlist.py shares 92% of its lines, common.py 85%, lang.py
66%, agent.py 56% and email.py 51%. The RLCD reward that the card writes out as a
formula is Laya's proper_reward, unchanged down to the -9.21 log floor, and the head class
is Laya's without the export patches Laya added since. One comment gives the game away:
# thx01/common.py:224-227, also laya/common.py:820-823
# A fitted temperature below 1 sharpens the logits instead of softening them. The shipped
# `choice:11+` bucket is 0.1006, which multiplies them ~10x: a 0.24 top probability is published as
# 0.99, so a caller gating on confidence is told a coin flip is a certainty. No honest calibration
# needs to sharpen this hard, so refuse to apply one that does.
THX-01's own config stores 2.55 for that bucket. The 0.1006 is Laya's, the value the llama.cpp piece read out of Laya's GGUF. The comment describes a checkpoint THX-01 does not ship, because it came along with the code.
Both projects are Apache 2.0, so none of this is forbidden, and fine-tuning someone's open
checkpoint is what open checkpoints are for. What I object to is the credit. The NOTICE
says "the batched runtime, tournament decoding, the REST server, the Doom demo and all
benchmarks are by HAL-X AI", the base_model field skips a generation, and the post let
"Laya is great too!" stand. A reader comparing decision models should know that THX-01 and
Laya-multilingual are one model at two points in its training.
What HAL-X did add is real. The training data is theirs: the card lists eight training
stages on top of Laya, with routing, roughly 600 business taxonomies, the support-ticket set,
and 29k number and 14k excerpt questions checked by three teacher models. So are four
modules with nothing in common with Laya: number.py, excerpt.py, compat.py and
server.py. Those four are the part worth reading.
Numbers and excerpts, compiled into choices
The card lists number, excerpt and cite as "native THX-01 capabilities". I expected a
new head. There isn't one. Each is a front end that turns the question into ordinary
choice or noul calls on the same head, and the model never writes anything.
For number, a regex finds every number written in the document. A separator followed by
exactly three digits gets both readings, so "1.200" offers 1.2 and 1200, while "48.3" stays
48.3. A following word in English, Azerbaijani or Russian ("million", "mln", "млрд")
multiplies it, and both values are kept. Each candidate becomes an option labelled with the
seven words before it and the four after, and one more option says the value isn't stated:
# thx01/number.py:69-79
def number_options(doc: str) -> List[Tuple[float, str]]:
    seen, out = set(), []
    for m in NUM.finditer(doc):
        mult = MULT.get((m.group(2) or "").strip().lower().rstrip("."), 1.0)
        desc = _window(doc, m.start(), m.end())
        for v in sorted(_readings(m.group(1))):
            for val in sorted({v, v * mult}):
                k = round(val, 6)
                if k not in seen:
                    seen.add(k); out.append((val, f"{fmt(val)}: …{desc}…"))
    return out
excerpt is four choices in two rounds. The document is cut into sentences and clauses of
at most 28 words; one question asks which part holds the first word of the answer and
another which holds the last, then two more pick the words inside those parts, and the span
between them is sliced out of the document. cite asks one yes/no question per part:
does this part answer the question?
I like this design. "It cannot contain invented text" is guaranteed by construction, by the
regex and the slicing, not by trusting a model. It also has the limits you would predict
from the code: a number written as a word ("forty") never becomes a candidate, an excerpt
costs four forward passes (their 1,357 excerpt questions took 52.9 s, about 39 ms each), and
a citation costs one pass per sentence. One small trap: the multiplier table maps min, the
Azerbaijani "thousand", to 1,000, so "5 min" offers both 5 and 5,000. The model has to pick
the right one from context, and usually will, but it is the kind of thing to know.
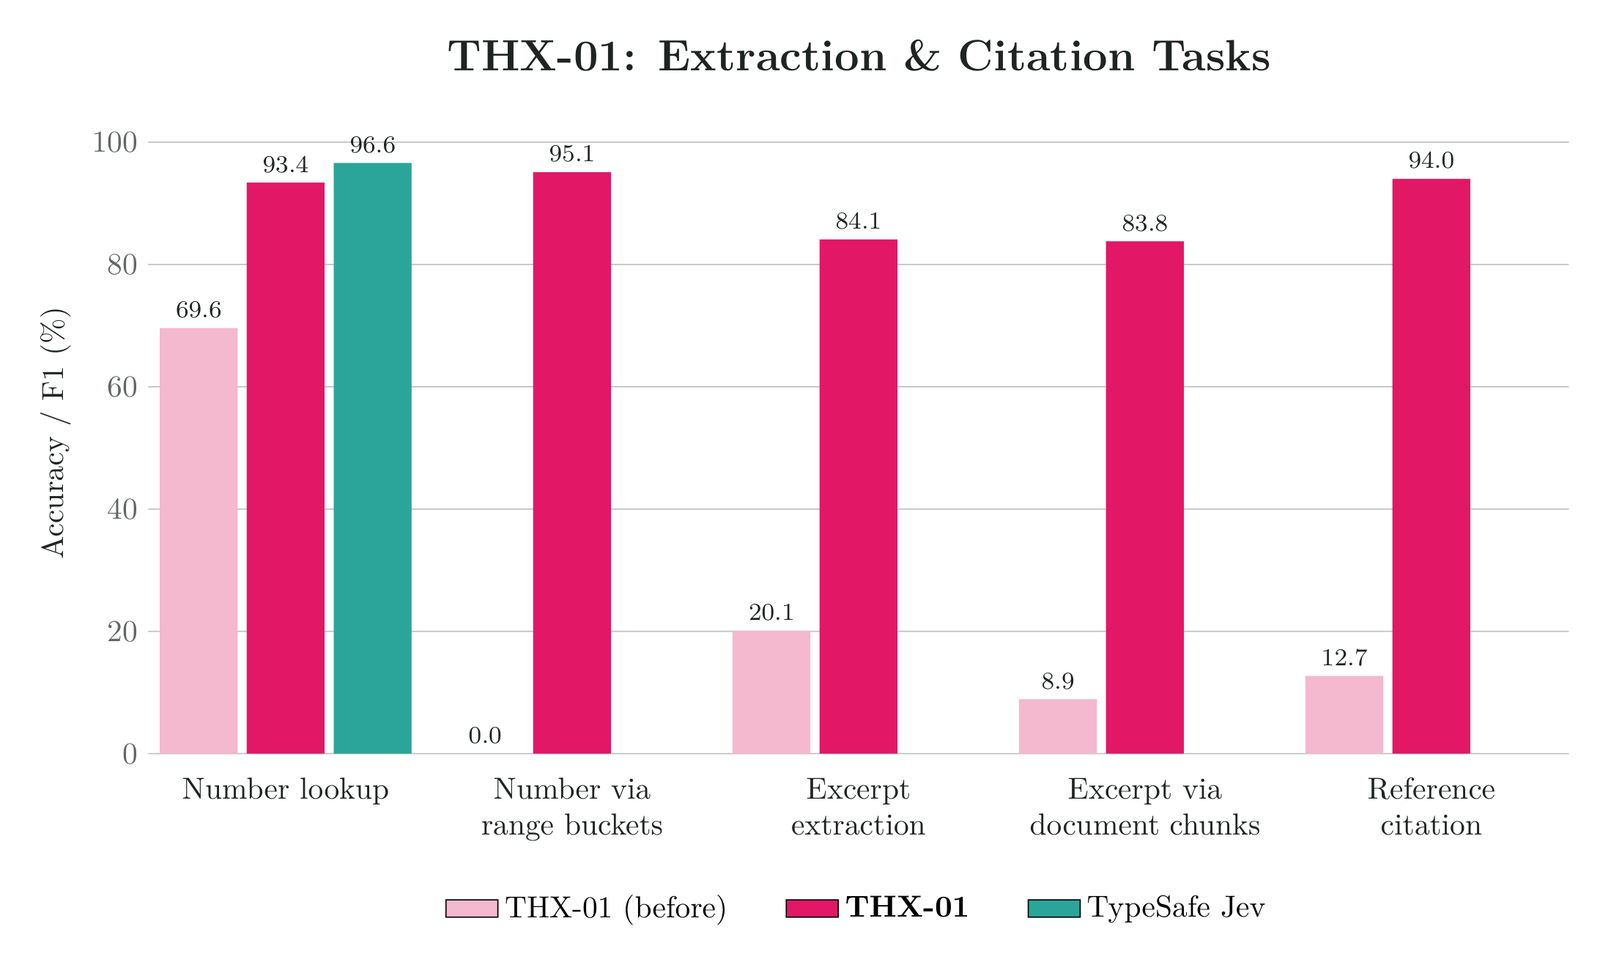
The card mentions the Jev number in a sentence under its table: "On number lookup over the same documents, TypeSafe Jev 1.13 reaches 96.6%." That is 3.2 points above THX-01's 93.4%, on 1,824 questions. It is the only extraction comparison with Jev, and Jev wins it.
"Beats Jev on some benchmarks"
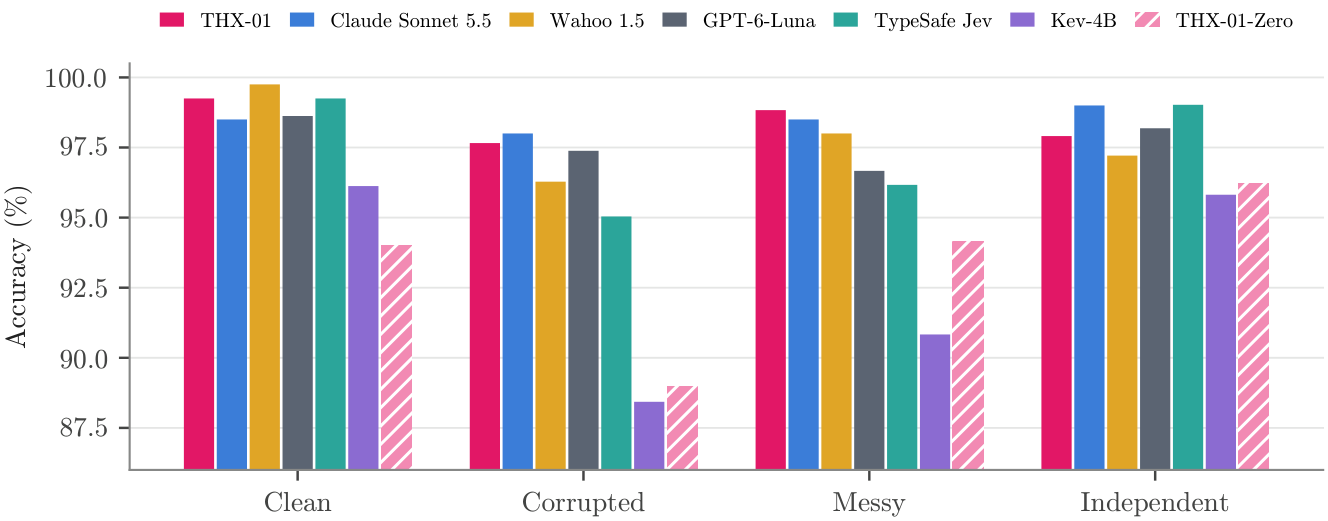
The headline comparison is a support-ticket arena: 15 categories, four test sets, 2,843 tickets. The card's table averages them: THX-01 98.4%, Jev 97.4%. Set by set, from the results file the release ships, THX-01 ties Jev on Clean at 99.25% (794 of 800 each), wins Corrupted 97.7% to 95.0% and Messy 98.8% to 96.2%, and loses Independent 97.9% to 99.0%.
Then I read where the four sets come from. The docstring of bench/arena.py says Clean is
"Wahoo-written", Corrupted is "programmatic", Messy is "Wahoo-written messy", and
Independent was written by GPT-6-Luna and "never trained on". The training config describes
stage 5 as "clean+messy messages (Wahoo, GPT-6-Luna, Claude Sonnet 5.5), programmatic
translit / no-diacritics / typo corruptions, 15-category support-ticket taxonomy". Same
taxonomy, same writers, same corruption code. The card says the test items and their
near-duplicates were kept out of training, and I have no reason to doubt it, though the
ticket generator and data aren't in the repo, so I couldn't check. But that is the
train-split pattern reproducing Jev described: a model fitted
to a distribution, scored on held-out items from it, beside a model that has never seen it.
THX-01 wins on the two sets made by its own pipelines, and loses on the one written by a
different hand.
The card's own robustness chart makes the point better than I can. It includes a bar called
"THX-01-Zero", which the card never explains; its four numbers match the results file's
checkpoint system01_v8 exactly, and it sits below Jev on every set, Corrupted by six
points.
There is a second thing in that file. It holds 18 THX checkpoints, every one scored on the
same four test sets, from early stage-5 runs through weight soups and test-time-augmentation
variants to the row the card prints, thx01_v10c_s15. Scoring candidates on the test set
and publishing one is a mild form of selection, not a scandal; it is how most cards are
made. It does mean the set no longer works as a clean holdout for the choice between them.
And on Independent, none of the 18 reaches Jev.
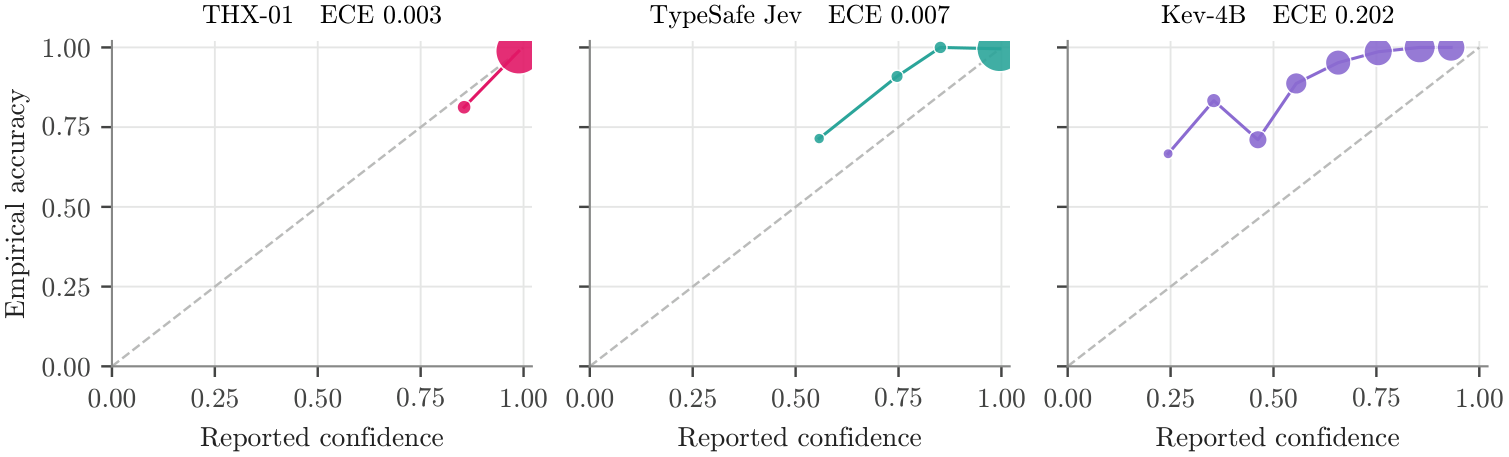
The calibration claim has the same shape. The card prints an ECE of 0.003 against Jev's 0.007, and footnotes that it is measured on Independent. Per set, from the same file, THX-01 is better on Clean (0.011 against 0.012) and Independent, and worse on Corrupted (0.030 against 0.019) and Messy (0.018 against 0.014). At 98% accuracy almost every prediction lands in the top confidence bin, so a ten-bin ECE has little to measure; the reliability chart shows THX-01 with two points.
The repo also holds comparisons the card leaves out. bench/plots_v2.py draws a chart
titled "THX-01 vs TypeSafe Jev on the same public datasets", which is not among the card's
images. Filled in with the card's own THX-01 numbers and the third-party Jev figures the
script hard-codes, it reads: AG News 92.3% against 91.0%, SMS spam 87.3% against 93.0%, DAIR
Emotion 44.6% against 48.0%, Banking77 65.9% against 76.3%. The samples differ, so treat it
as a rough comparison, but it is one win in four. And results/jev_suites_system01.json runs
an earlier checkpoint on nibzard's benchmark suites, which
the script says are hash-verified to be the items Jev was scored on: 57.7% on Banking77 against Jev's 76.3%, 88.3% on spam against
93.0%, and an option-order flip rate of 27% against Jev's 13%. It is a pre-release
checkpoint, so it doesn't settle anything about the final model, but nothing newer replaced
it in the repo.
The 39-task suite tells the same story from the inside, once you sort its rows by what training saw. The 19 rows built from MASSIVE and Azerbaijani app reviews, whose train splits are in stage 1, go from 53.5% to 88.6% on average. The five synthetic tasks, held-out schemas from the same generator as the training data, go from 49.6% to 93.4%. The 14 public sets that were held out entirely (SIB-200 in ten languages, AG News, Banking77, SMS spam and DAIR Emotion) go from 69.9% to 73.8%, and AG News goes down, 94.1% to 92.3%. To its credit, the card puts Banking77 and DAIR Emotion under Limitations rather than hiding them.
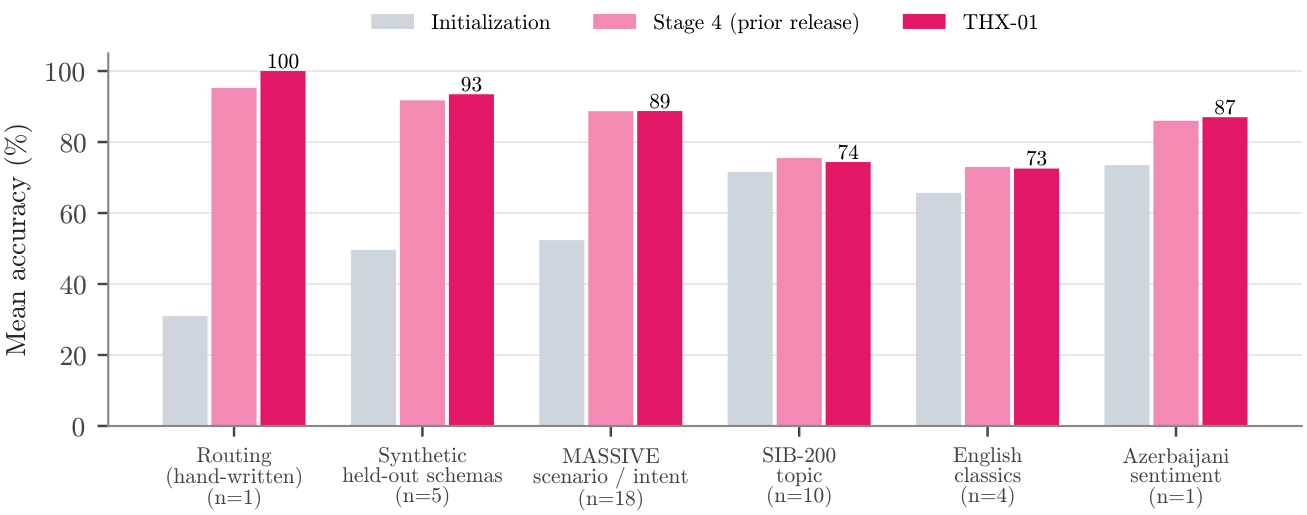
So the sentence in the post is true. THX-01 beats Jev on some benchmarks: two of four ticket sets that share its training pipeline. On every public or third-party comparison in its own repository, it loses.
On a phone, and free
Nothing in the card, the API docs, the package or the repo shows THX-01 running on a phone.
There is no ONNX, Core ML, GGUF or quantised file, only 644 MB of fp16 safetensors; the
package depends on PyTorch and picks CUDA, then Apple's MPS, then the CPU. Every latency in
the release, the 10 ms included, is from one RTX 4090. One reply asked "No gguf?" and got no
answer. Could it run on a phone? Probably. It is Laya-multilingual's architecture, and Laya
has already been ported to MLX and Core ML and is among the models
llama.cpp's /v1/systemone loads, so the same paths should take it, possibly unchanged. That
is my inference from the weights, not something anyone has shown.
The free API is real, and its rules aren't written down. The docs say "Every request needs a
HAL-X API key"; the poster told a reply "You don't need API key, just send request there." I
sent one harmless request with no key. It came back 200 with a decision, a latency_ms of
25.39, and headers x-halx-tier: public and x-ratelimit-limit-decisions: 200. The docs page
has no terms, privacy policy or retention statement. The only policy on HAL-X's site is for
chatHAL, a different product run by Mergen AI LLC, and its zero-training and zero-retention
promises are written about that workspace, not this endpoint. Until HAL-X says what it keeps,
I would not send it a real customer's ticket. The weights are Apache 2.0, so run it yourself.
Would I use it?
For support routing in Azerbaijani, Russian or English, typed the way people
actually type it, THX-01 is probably the strongest open option, because that is what it was
trained on and its ticket numbers, read carefully, say so. I would run it locally, measure it
on my own tickets, and set the confidence cutoff from my own data rather than from the 0.003.
For general decisions, Laya-multilingual's later training buys little, by the card's own
held-out rows. The idea I would take from it, whatever model I used, is the extraction front
end: turning "what is the revenue?" into a choice among the numbers that are actually on the
page works for any decision model with a choice type.
Sources, read on 2026-10-06: Liquid AI's d1 launch post, decision-model docs and the d1 Playground with its demos/data/compare.json and demos/data/inspection/index.json; the Decision 2.0 collection, including vllm-sr/Decision-2.0-Kai-0.6B and vllm-sr/Decision-2.0-Vega-27B, and vLLM Semantic Router; FluidInference's FluidUse (branch feat/decision-2.0 at e080acd), decision-2.0-kai-coreml and decision-2.0-eos-coreml; ggml-org's decision models in llama.cpp and llama.cpp at 43fe9c6 (tools/server/server-decision.cpp, server-context.cpp, common/common.h); and Mapika/decider with decider-2b-vision. Parameter counts are safetensors header and index reads; no third-party code was executed. Figures are reproduced for commentary from Liquid AI's blog and launch posts, the Decision-2.0-Vega-27B model card (Apache-2.0), FluidInference's demo video and the ggml-org blog; the two interactives are original.
THX-01 section, read on 2026-10-12: the X post and its replies; doofz/THX-01 at its 2026-10-08 commit (model card, config.json, rl_agent_config.json, the model.safetensors header and selected tensor byte ranges, bench/, results/, train/, gen/); the thx01 1.0.0 wheel from PyPI, read and not installed; convaiinnovations/laya multilingual/model.safetensors (header and the same byte ranges, for comparison) and NandhaKishorM/laya at 682ac67; nibzard/decision-model-benchmark results/v3/v3.md; the THX-01 API docs and one keyless request to /v1/systemone with a made-up sentence; and the chatHAL privacy policy linked from hal-x.ai. Tensor correlations are over the first 1M values of each tensor (all of it when smaller). Figures are reproduced for commentary from the THX-01 model card (Apache-2.0); the ticket ledger is original and drawn from the release's results/thx01/tickets_arena.json.