2026-10-06 · 31 min · ocr · document-parsing · multimodal · tool-calling · calibration · asr
Why read this
Notabletop 60%Hash-matches 76 of 79 weight files to public checkpoints, reads the OCR stitcher, and shows word confidences in the open code are just the line score.
- Original, source-checked analysis
- Concrete numbers to act on
- Open code or weights
Vision & multimodalNeeds a workstation GPUMixed licencesPractitioner model
How this was scored
- Is it new?
- 0 of 3: Repackaging or news of a known thing
- Can I trust it?
- 3 of 3: Reproduces the headline result, or shows from primary files it is wrong
- Can I run it?
- 2 of 3: Open code or weights with real limits
- Will I understand it?
- 2 of 3: Mechanism from first principles with figures
- Can I act on it?
- 2 of 3: A concrete recipe, numbers or comparison
- Will it last?
- 1 of 3: Relevant for months
- Does it affect many?
- 1 of 3: A specialist community
- Only here?
- 3 of 3: The only place this analysis exists
Score 64 of 100, ranked 276 of 701 rated articles. Each question is answered 0–3 by hand, and a 3 is rare. How articles are scored
Interfaze announced interfaze-1-lite as "the first general open-weight model for deterministic work": OCR, speech-to-text, extraction and classification, with "confidence scores and metadata like bounding boxes on every run". The second post in the thread names the design: "Mixture of Architecture (MoA)", where "each specialist model is a dedicated architecture built to solely process a single task", and the whole thing runs on one H100.
That is a claim about structure, and structure is checkable. A Hugging Face repo is a list of files with sizes and SHA-256 hashes, every safetensors file starts with a JSON header naming each tensor's shape, and the routing code ships alongside because the model needs trust_remote_code=True. I read all of it without downloading the 44 GB of weights, then read the GitHub server that wraps it. No third-party code was executed.
- architecture
- InterfazeLiteModel
- task
- image-text-to-image
- library
- transformers
- license
- apache-2.0
- safetensors
- 68 shards
- largest file
- 10.59 GB
- files
- 130
- downloads
- 6
- likes
- 32
- languages
- en, zh, es, fr, de, it
A bundle, not one network: eight upstream checkpoints in named folders plus routing code. 27.78B of its parameters are the Qwen3.8-27B-FP8 core, counted from the safetensors headers.
repo last modified 2026-10-05
| Weights | interfaze-ai/interfaze-1-lite, read at commit 1bfa94c (2026-10-05, tagged Apache-2.0) and again at 5ff65f3 (2026-10-07, tagged license: other) |
| Server | InterfazeAI/interfaze-1-lite, commit b7c642c, an OpenAI-compatible service over vLLM |
| Launch post | The First Open Weight Model for Deterministic Work |
| Bundle size | 44,289,111,287 bytes across all files (measured, Hub API) |
| Hardware | one 80 GB GPU, compute capability 8.9 or newer (reported) |
What "mixture of architectures" means here
Start with what it is not. A mixture of experts is one network whose feed-forward layers are split into experts, with a learned router choosing a few per token, trained end to end. Nothing in interfaze-1-lite is trained jointly, and there is no learned router. The routing is a 27B vision-language model deciding which tools to call, the way any tool-calling agent does.
The model card says as much, plainly: "Interfaze 1 Lite is not one network. It is a reasoning core plus specialists, each chosen for the task it is best at, connected by tool calls." The launch blog draws it the same way.
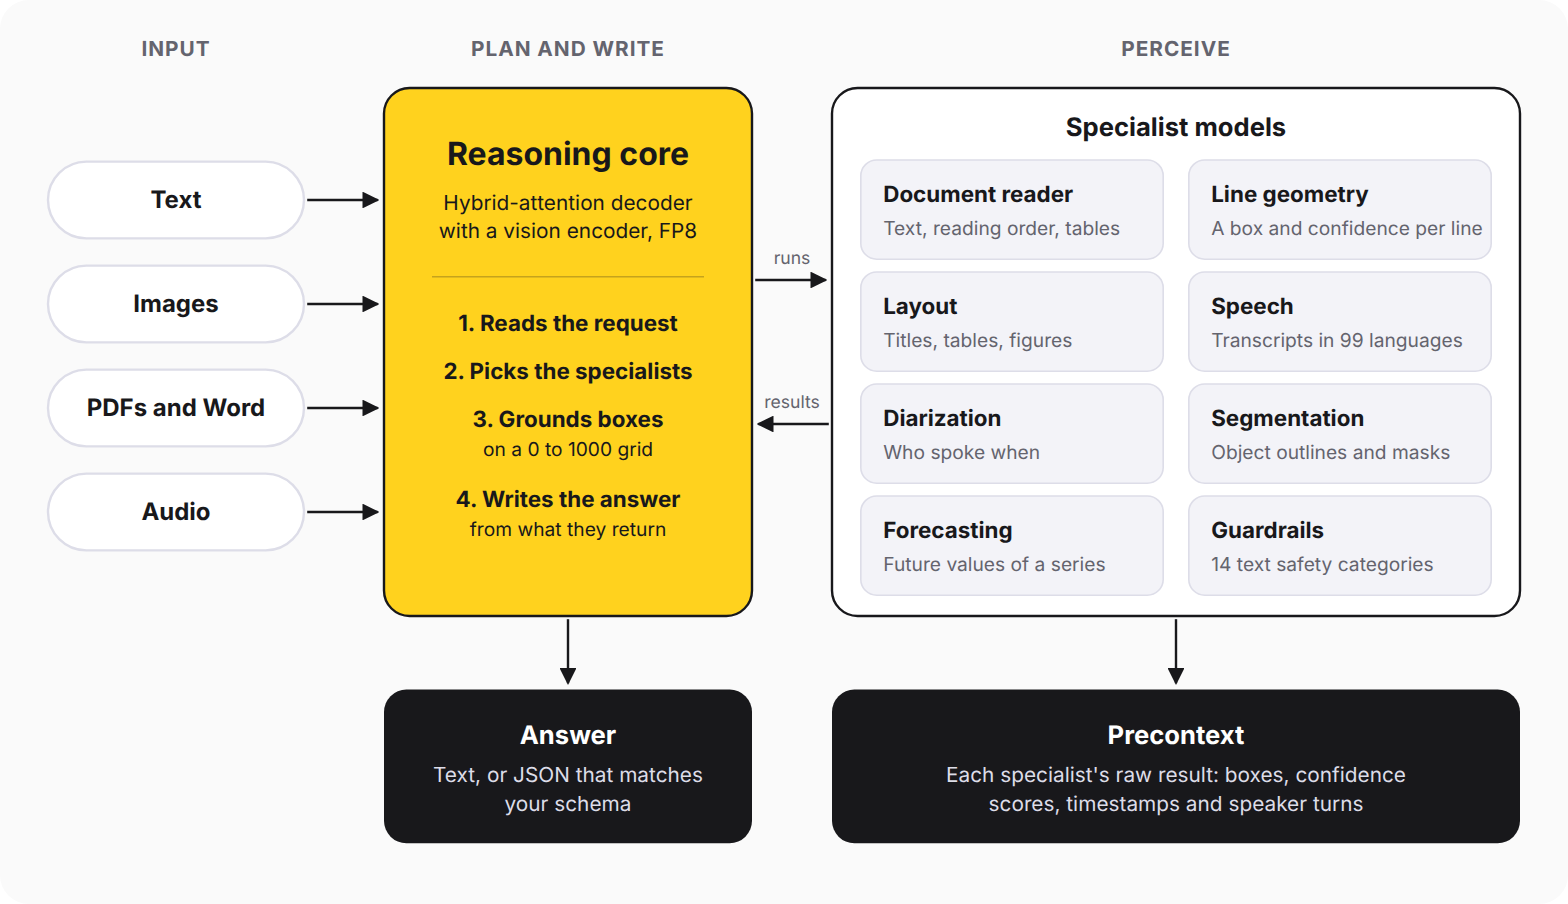
What the diagram does not say is where the specialists come from. The card's architecture table describes each by type only ("Vision-language model trained for page reading", "Encoder-decoder speech recognizer"). The configuration file goes further and says it on purpose: the capability-to-component mapping "is supplied by the deployment (COMPONENT_<CAPABILITY>), so this file declares which capabilities exist without naming what provides them."
The names are elsewhere, in three places that agree:
- The card's closing "Thank you" credited "inspiration from these models" when I first read it (the wording changed on 2026-10-07; see below): Qwen3.8 27B, Chandra OCR 2, Whisper large-v3 turbo, pyannote's
speaker-diarization-community-1, SAM 2.1, Llama Guard 3, TimesFM 2.5, and PaddlePaddle's PP-OCRv5 detection, PP-OCRv5 recognition and PP-DocLayout. - The GitHub repo's
components.env.examplelists the defaults "the hosted interfaze-1-lite runs":COMPONENT_BRAIN=Qwen/Qwen3.8-27B-FP8,COMPONENT_OCR_VLM=datalab-to/chandra-ocr-2,COMPONENT_ASR_FALLBACK=openai/whisper-large-v3-turbo, and so on throughCOMPONENT_FORECASTER=google/timesfm-2.5-200m-pytorch. - The bundle's own config files:
brain/config.jsondeclaresQwen3_5ForConditionalGeneration,asr_fallback/config.jsondeclaresWhisperForConditionalGeneration, the Paddle folders carry"model_name": "PP-OCRv5_server_det","en_PP-OCRv5_mobile_rec"and"PP-DocLayout_plus-L", andsegmenter/config.yamlbuilds asam2.modeling.sam2_base.SAM2Basewith a Hiera trunk of stages[2, 6, 36, 4].
"Inspiration" undersells it. The Hub API returns the LFS SHA-256 of every large file. I pulled the same listing for the ten upstream repos and compared hashes. 76 of the bundle's 79 LFS files are byte-identical to an upstream file (measured): 44.23 GB of the 44.27 GB of large files. The three that differ are the banner image and two tokenizer.json files; the document reader's is one byte longer than Chandra's. Every weight file is someone else's checkpoint, unmodified.
That is not a criticism of the engineering. It is a correction to the framing, and it has a licensing edge worth knowing. At the commit I first read, the repo was tagged Apache-2.0 and shipped one LICENSE file, the plain Apache text. Chandra OCR 2's card says license: openrail, but the file it links is stricter than that tag suggests: an "AI PUBS OPEN RAIL-M LICENSE (MODIFIED)" with use restrictions, a share-alike clause and commercial limits on who may use the weights at all. pyannote's diarization pipeline is CC BY 4.0 behind a Hub gate that asks for your contact details. The configuration docstring itself says bundled mode comes with "the obligation to carry every upstream licence"; read each upstream licence before you build on the bundle. The section on the dispute below quotes the relevant clauses. "Each specialist model is a dedicated architecture built to solely process a single task" is true. It is also true that none of them was built by Interfaze.
Folder by folder
The bundle has one folder per component. Counting parameters from the safetensors headers takes two range requests per file: 8 bytes for the header length, then the header itself.
The numbers, with how each was obtained:
brain/: Qwen3.8-27B-FP8, 27.78B parameters (measured from 66 headers: 64 per-layer shards,outside.safetensorsandmtp.safetensors). Of those, 24.70B are FP8 E4M3 with 128x128 block scales and 3.08B stay BF16. 0.46B are the vision encoder and 0.43B the multi-token-prediction layer. 30.89 GB on disk. My sum is 27,781,427,952, exactly the figure the Hub's metadata gives forQwen/Qwen3.8-27B-FP8.ocr_vlm/: Chandra OCR 2, 5.30B parameters, BF16, 10.61 GB (measured). Its config is the same Qwen3.5-family hybrid as the brain at half the width: 32 layers, hidden size 2560.asr_fallback/: Whisper large-v3 turbo, 0.81B, FP16, 1.62 GB (measured). 32 encoder layers, 4 decoder layers.segmenter/: SAM 2.1 Hiera-Large, 0.90 GB; 224M parameters per its upstream repo's metadata (reported).layout/,line_detector/,line_recognizer/: PaddlePaddle inference files, about 32M, 22M and 1.9M parameters (reasoned:.pdiparamsbytes divided by 4 for float32).diarizer/: pyannote's segmentation and embedding models plus a PLDA transform, about 8M parameters together (reasoned, same way).
The brain is 70% of the bundle by bytes (reasoned). Its text stack is Qwen3.8-27B's hybrid design, the one Cinference's speed claim turns on: 64 layers, of which layer_types marks 48 as linear attention and 16 as full attention, one full layer in every four (measured from brain/config.json). That is what the card means by "hybrid-attention decoder", and why it warns that without flash-linear-attention, "generation slows to minutes per page".
Two specialists are not in the bundle
config.json sets "bundle_weights": true, and the loader's docstring says what that means: "component weights live in this repo under the prefixes below." The configuration code lists eleven capabilities, guard and forecaster among them. The file listing has no guard/ folder and no forecaster/ folder (measured). moderate() needs Llama Guard 3 1B and forecast() needs TimesFM 2.5; neither ships.
Reading _repo(), a bundled load of either asks snapshot_download for guard/* or forecaster/*, gets an empty pattern match, and hands the path to from_pretrained. I expect that to fail, but I did not run it, so treat it as unverified. The Docker path in the GitHub repo avoids the question: it pulls each component from its upstream repo and requires an HF_TOKEN because, in its own words, "the diarization and guard models are gated". The card's "Self-contained. One repository, one GPU, runs offline" holds for OCR, speech, detection and chat. It does not hold for the two capabilities whose weights are gated or absent.
One more thing is optional. The config keeps a list of "the 25 languages the fast recogniser TDT v3 covers", and components.env.example names nvidia/parakeet-tdt-0.6b-v3 behind ENABLE_FAST_ASR=1. Off by default, so the default speech path is Whisper alone.
The orchestration is the product
If the weights are borrowed, the work is the Python around them: 4,552 lines in the bundle's nine .py files and 9,329 in the GitHub server's package (measured, wc -l). Some of it is careful.
The tool loop. chat() runs agent.run: the brain sees the user's files as ref-0, ref-1, … and four tools, ocr, stt, object_detection and gui_detection. It gets up to six tool-calling turns. If a file is attached and the brain answers without calling anything, it is reminded once ("answered by eye, the text is invented"). The images themselves are shown to the brain only after a tool has read them: "shown an image first, the model transcribes it by eye and invents text." Every tool's full result goes back to the caller as precontext, next to the answer.
Direct calls skip the brain. ocr(), transcribe(), moderate() and forecast() never load the 27B core; components load lazily on first use, so "a caller who only wants OCR never pulls the 28 GB brain." For the deterministic jobs the announcement leads with, the reasoning core is not in the loop at all.
Detection is the brain, segmentation is SAM. detect() prompts the brain to write boxes as text on a 0-1000 grid, parses them, and passes each box to SAM 2.1 for an outline. ground() is the brain alone, tiling large screenshots. RefCOCO's 83.8 (reported) is therefore a Qwen3.8 score with a prompt and a parser around it (reasoned: ground() and detect() boxes come from the brain alone).
Speech is Whisper with its own guards. Audio past 120 s is cut at quiet points into windows of at most 30 s and decoded 16 at a time; the card reports a 95-minute recording in about 90 seconds. Speaker labels come from pyannote, with each word assigned to the turn it overlaps most. The comments are worth reading: greedy decoding alone "looped '5-5-5' for 60 s of a card number", so the code restores Whisper's reference-decoder fallbacks. The site's piece on Whisper's hallucinations covers why those guards exist, and Nemotron 3 Diarization covers the speaker side.
OCR: two readers, one page
OCR is where the design earns its keep, and it is the one place the confidence claim is fully backed. Three jobs run on every page at once: Chandra OCR 2 reads the page, the PP-OCRv5 detector and recognizer find and read every line, and PP-DocLayout labels the blocks.
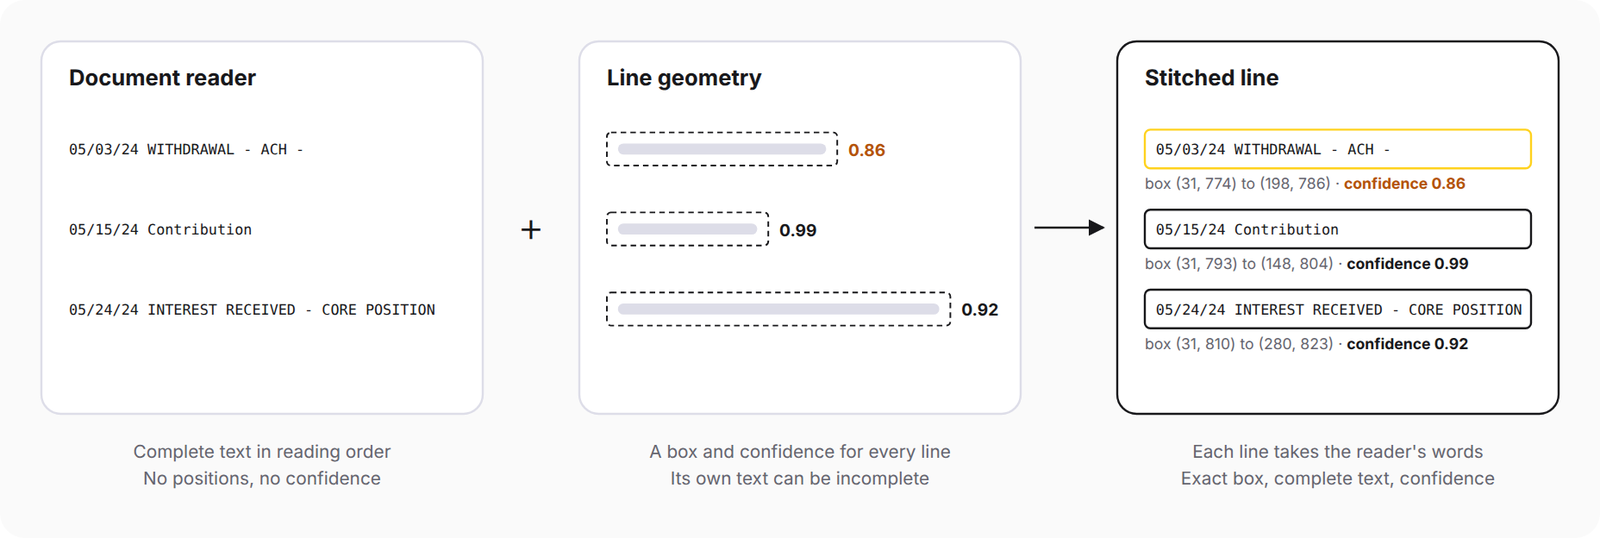
The division of labour, from the stitch() docstring: "the reader owns the page's text -- reading order, tables, structure -- and the detector owns every box and confidence." Chandra emits HTML with data-bbox attributes, but the code does not trust those boxes: on portrait pages they "came back squeezed toward the left", and matching by position "dropped 62 of a memo's 98 lines". So lines are matched by what they say. For each detector line, PageText.read searches the reader's flattened text with rapidfuzz.partial_ratio_alignment, widens the hit to whole words, and accepts it at a fuzzy score of 88 or more (100 for lines of four characters or fewer). Best matches claim their span first, so three near-misses cannot all take the same "Dependent 1". A line with no match keeps the recognizer's own text.
There are pragmatic guards on top. A page whose mean line confidence falls below 0.75 is re-read at a denser pixel budget, up to about 8.4 MP; images under about 2.1 MP are read at twice their size, after a phone photo of a receipt came back with "EARBUDDS" and "DIL" for OIL. These are numbers measured by the authors on their own documents and written into comments (reported).
Where the confidence comes from
The confidence on each OCR line is the PP-OCRv5 recognizer's rec_score for its own reading of that line crop (measured from line_runtime.py and _detect_text_lines). That is a legitimate, roughly calibrated signal; it is what made classic OCR pipelines gateable. It comes from a recognizer with about 1.9M parameters.
Two details follow from the code, and both matter if you gate on it.
First, the score is for the recognizer's text, and the line shows the reader's text. When the stitcher replaces a line's words, it keeps average_confidence=line.average_confidence. A long line is accepted at a fuzzy-match score of 88 out of 100, so the two readings can disagree on several characters and the line still carries the recognizer's score for its own version. A reply under the launch post made this point; it is correct as written.
Second, in the released code, word scores are not per-word. split_words() divides the line's box among its words by character count and gives each word confidence=confidence, the line's own value. That applies to stitched lines and to the detector's raw lines alike. The launch blog's worked example shows something richer, so try the two views:
In the blog's output (reported, from the hosted API), the withdrawal line's words score 0.99, 0.99, 0.92, 0.99 and 0.42. Their mean is 0.862 (reasoned), which rounds to the line's 0.86, and the gate at 0.9 sends that one row of ten to a person. The row-level gate works the same with the open code. The per-word explanation does not: run locally, all five words would read 0.86 (measured from split_words, not run). The hosted service may compute word scores differently; the GitHub server's package has the same split_words and I found no other source of word scores in it.
Confidence elsewhere
"Confidence scores … on every run" is an OCR claim. Elsewhere in the code:
transcribe()returns timestamps and no confidence. Itslanguage_detectedcarries"confidence": 1.0, hard-coded.detect()andground()return boxes with no score; SAM's mask scores are read into_scoresand dropped.forecast()keeps TimesFM's point forecast and discards the quantiles in the same way.moderate()is the exception: it computesunsafe_probabilityfrom the guard's softmax over the words "safe" and "unsafe" and only blocks at 0.8 or above, because plain file requests "came out unsafe S8 at 0.59-0.73".
How "deterministic" is meant
The blog's definition is about the task, not the arithmetic: work "where there's one right answer", with outputs read by an if statement rather than a person. Its table puts "Same input, same output" under consistency.
The code does decode greedily. Every generate() call on the brain and the guard passes do_sample=False, and the vLLM path sends "temperature": 0.0 to the document reader. That is despite brain/generation_config.json shipping Qwen's sampling defaults (do_sample: true, temperature 1.0, top-k 20), which the code overrides. The brain also runs with enable_thinking=False.
Greedy is not the same as bitwise reproducible. Floating-point reductions depend on batch composition and kernel choice, so the same input in a different vLLM batch can flip a near-tie token; a reply under the launch post asked exactly this and got no answer. And Whisper's guards are a temperature ladder, (0.0, 0.2, 0.4, 0.6, 0.8, 1.0): a window that looks like a loop or scores below a log-probability of -1.0 is re-decoded with sampling, which varies run to run unless seeded (reasoned). "Deterministic" here means typed outputs, greedy decoding and a schema. It is not a reproducibility guarantee, and nothing in the repo claims one.
The benchmarks
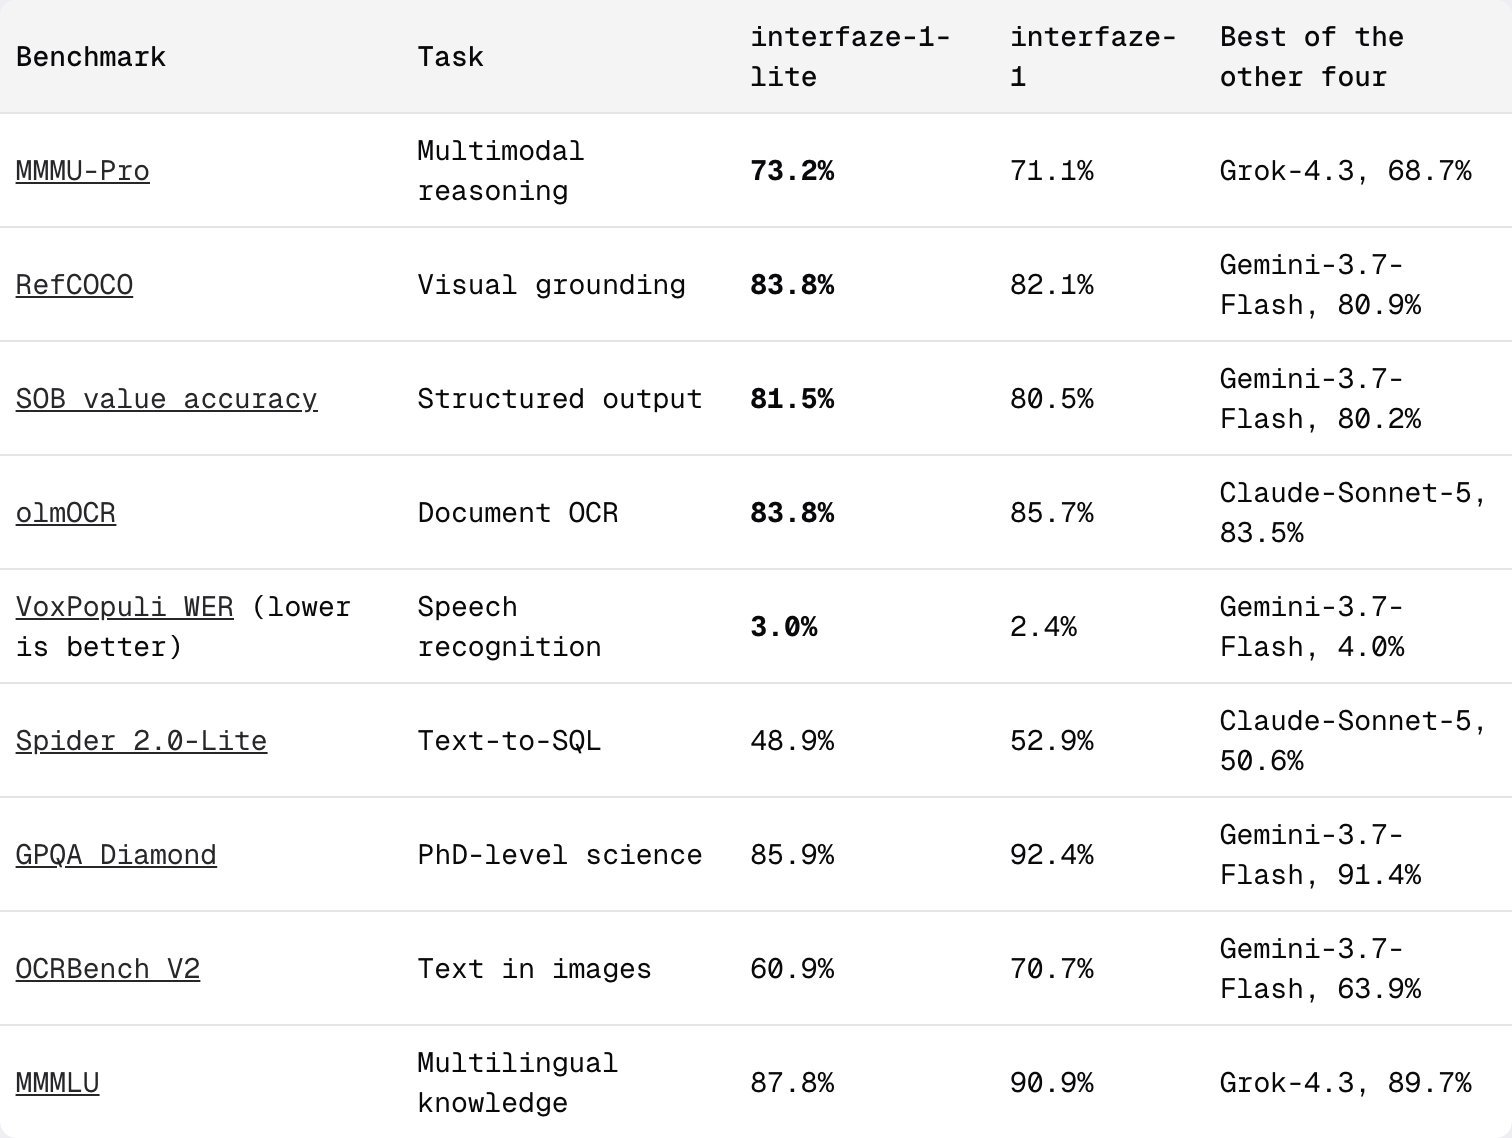
All of these are reported: Interfaze scored Lite itself "with each benchmark's official scorer" and took every other model's score from its own leaderboard. I re-ran none of them. Two things are worth knowing before you quote them.
The comparison set changes between documents. The model card compares against Claude-Sonnet-4.6 and Gemini-3-Flash; the blog compares against Claude-Sonnet-5 and Gemini-3.7-Flash. On olmOCR-Bench, the card's best rival is Grok-4.3 at 81.9, and the blog's is Claude-Sonnet-5 at 83.5. Lite's own numbers are the same in both. The context window also varies: 131k tokens in the card, 128k in the blog, and max_context: 262144 in config.json.
Since the weights are public, the fair baseline is each component alone. On the olmOCR leaderboard, Interfaze lists Chandra OCR 2 by itself at 84.3% and Lite at 83.8% (both reported, same page). Lite's OCR is Chandra OCR 2 plus the Paddle stitcher, and the stitched pipeline scores half a point below its own document reader. By category on that board, Lite gains on tables (88.8 against 87.9) and old scans (51.3 against 49.2), and loses on headers and footers (90.0 against 92.5), long tiny text (91.9 against 93.9) and multi-column pages (80.1 against 81.3). Datalab's own card reports Chandra 2 at 85.8 ± 0.8 in its own harness, with tables at 92.1, so the table "gain" exists only against Interfaze's run of Chandra; the section on the dispute below works through why the two boards differ. The stitcher is not there to raise the text score; it is there to attach boxes and scores, and on this benchmark that costs a little.
The same reading applies to the reasoning rows. Lite's GPQA Diamond of 85.9 comes from byte-identical Qwen3.8-27B-FP8 weights; Qwen's card reports 89.2 for Qwen3.8-27B (reported). The gap is plausibly the enable_thinking=False setting I found in the transformers path, but the evaluation harness is in a separate repository I did not read, so that is a guess (reasoned). And VoxPopuli's 3.01% WER is Whisper large-v3 turbo's number with long-form windowing.
Jina-OCR-v1 is the other OCR release I have taken apart at the header level; the difference is that its new piece was a trained speculative-decoding head, and here there are no new weights at all.
What it costs to run
The card's hardware line is one 80 GB GPU with compute capability 8.9 or newer. The loader's comments put numbers on that. Through transformers, the FP8 brain is dequantized to BF16 because the FP8 kernels "computed nonsense" on a receipt question, "for about 54 GB of memory" (reported). 27.78B parameters at 2 bytes is 55.6 GB (reasoned), so that checks out. Add the 10.6 GB document reader and a chat that touches both holds about 66 GB of weights before activations or KV cache (reasoned). It fits; it is not roomy, and the card itself warns that large PDFs "can spike in significant use of CUDA memory". The vLLM path in the GitHub repo keeps the brain in FP8 and is the one to use for throughput.
The API alternative is priced at $0.85 per million input tokens and $1.50 per million output tokens (reported).
What I'd take from it
The useful idea here is old and sound: let a general model plan and write, and let small specialist models do the perception, because the specialists already produce the metadata a pipeline needs. A 1.9M-parameter line recognizer gives you a per-line score that a 27B VLM does not. Interfaze's stitcher, which matches text by content rather than trusting a VLM's boxes, is a good piece of engineering with honest comments about what broke.
What it is not is a new model. "Mixture of Architecture" names a deployment: ten public checkpoints, eight of them in one repo, wired together by a tool loop and a few thousand lines of careful glue. If you want the confidence scores, call ocr() directly, gate on the line score, and remember whose reading that score belongs to.
Chandra's maker reads the same hash
A day after I published this, the licensing point stopped being a footnote. On 2026-10-07 Vik Paruchuri, who founded Datalab and whose team trained Chandra OCR 2, quoted Interfaze's launch post:
Looks like you copied Chandra OCR 2 into your repo, renamed it, changed the license, and made the output worse (your olmocr score is 83.8 vs our 85.8).
His image puts two Hugging Face file pages one above the other. The top one, headed "interfaze-1-lite (theirs)", is interfaze-1-lite / ocr_vlm / model.safetensors at commit 1bfa94c with a "License: apache-2.0" badge. The bottom one, "Chandra OCR 2 (ours)", is chandra-ocr-2 / model.safetensors at af93b47 with "License: openrail". Both read 10.6 GB, and both SHA-256 values, boxed in red, are 0804568be9f099d6479fad9ed77a4da4611f3c1e7bc6e009af7dce45e8aa3847.
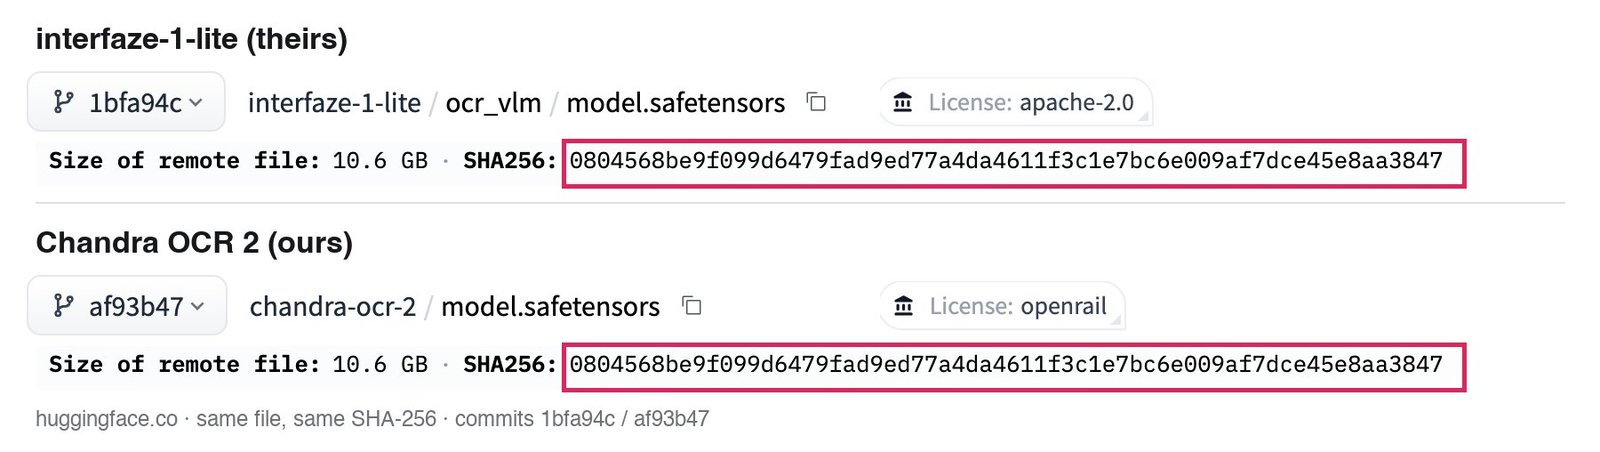
That is the same match my hash table found the day before, and his Interfaze commit, 1bfa94c, is the one I read. Yoeven, Interfaze's CEO, replied eight minutes later:
I think you're confused, we used a wide range of models and we did credit them in the repo. We thought Chandra was great and literally linked you guys there. Along with Qwen and a bunch of other models that was used to develop it. we weren't trying to hide that fact hence why everything is open and linked.
Vik answered twice: "I'm glad you guys liked the model. 'Inspiration' does not let you copy the model, rename it, and change the license", and "There are likely also issues with how you're using the pyannote model and llama guard." Later in the thread Yoeven made the rest of Interfaze's case. To a reply saying a licence had been removed: "No license was removed, we linked the exact repo used with their license there. The code literally references to their model so I don’t see how we’re trying to copy anything." To one asking how the hashes could match: "we never said we didn’t use the model, we did and we referenced in the readme and even in the code it’s linked to a bunch of different weights. So the SHA is suppose to match". And to Vik: "We linked every model used exactly to the repo so users can references the related license which are all different."
Both sides are describing the same facts. Interfaze never hid where the weights came from; the card linked every upstream by name, and the server's components.env.example names datalab-to/chandra-ocr-2 outright. What Vik objects to is what the repo said about the licence of those weights, and on that the record is plain: the card's metadata said license: apache-2.0, the only licence file was Apache's, the blog still says "The weights are Apache 2.0", and the credit called the upstreams "inspiration". The post drew a large response; when I read it the next morning it had 92,934 views and 1,699 likes, against 9,654 views and 22 likes on Yoeven's first reply.
What the repo looks like now
I pulled the Hub API again on 2026-10-08. The commit list has four new entries, all on 2026-10-07 between 21:52 and 23:00 UTC, two and a half to three and a half hours after Vik's post, all by the same account:
f3ec43dand337b3f2rewrite the credit line. "We are grateful for the inspiration from these models and the teams behind them" became "We are grateful to the teams behind the models and open-source projects whose work we use and build upon". The list of ten models and their links is unchanged.3ab4c59rewritesLICENSE. It now opens "THIRD-PARTY LICENSES" and says each third-party component "remains subject to its respective upstream license. The Apache License 2.0 for Interfaze 1 Lite does not replace or supersede the license of any third-party component." It groups the ten upstreams by licence (Apache 2.0, MIT, CC BY 4.0, the Llama 3.2 Community License, and "MODIFIED OPENRAIL-M LICENSE" for Chandra, which it says "are subject to the upstream modified OpenRAIL-M license"), with a link for each, and keeps Apache 2.0 for "The original work developed by Interfaze".5ff65f3changes the card's metadata fromlicense: apache-2.0tolicense: other,license_name: interfaze, pointing at that file.
Nothing else moved. The tree at 5ff65f3 has the same 142 paths as at 1bfa94c, and every one of the 79 LFS files has the same hash; only README.md and LICENSE differ. The ocr_vlm/ folder is still there with its ten files, and still holds no licence or notice of its own. No NOTICE file was added. The GitHub server repo is still at b7c642c from 2026-10-05, Apache-only, with the old "inspiration" wording.
So I re-ran the comparison at 5ff65f3. ocr_vlm/model.safetensors is 10,591,220,088 bytes with SHA-256 0804568b…aa3847, identical to model.safetensors in datalab-to/chandra-ocr-2 at af93b47, the commit Vik showed. Across the bundle the count is unchanged: 76 of 79 LFS files match an upstream byte for byte. One thing changed on pyannote's side: the Hub now masks the LFS hashes of its gated repo to anonymous callers, so I matched the four diarizer/ files on their git blob IDs instead. Those are hashes of the LFS pointer files, which contain the SHA-256 and the size, and all four are identical (6347697…, e61936e…, b8079f3…, e3b91de…).
What the three licences say
This is my reading of the licence texts as written, not legal advice.
Start with Chandra OCR 2. My first version said the card "declares license: openrail", which is true of the metadata and too gentle about the file. LICENSE in Datalab's repo is the "AI PUBS OPEN RAIL-M LICENSE (MODIFIED), Version 0.1". Redistribution is allowed, on conditions. Paragraph 4(b): "You must give any Third Party recipients of the Model or Derivatives of the Model a copy of this License". Paragraph 4(a) requires the use restrictions to be carried "as an enforceable provision" in whatever licence governs the distribution, with notice to recipients. And paragraph 8, the share-alike: "You agree to apply this License (to the exclusion of all others) to any and all copies of the Model". An Apache-2.0 tag over an unmodified copy of the weights cannot be squared with paragraph 8, and the repo as of 1bfa94c did neither 4(a) nor 4(b). The new LICENSE fixes the labelling: it names the licence, links it and says the Chandra weights are subject to it. It still links rather than includes the text 4(b) asks for, and ocr_vlm/ itself carries nothing.
The part that matters most for users is Attachment A, the use restrictions. You may not use the model, its derivatives or its output:
(a) for any purpose if You (your employer, or the entity you are affiliated with) generated more than two million US Dollars ($2,000,000) in gross revenue in the prior year, except where Your Use is limited to personal use or research purposes;
(b) for any purpose if You (your employer, or the entity you are affiliated with) has raised more than two million US dollars ($2,000,000) in total equity or debt funding from any source, except where Your Use is limited to personal use or research purposes; or
(c) for any purpose if You (your employer, or the entity you are affiliated with) provides or otherwise makes available any product or service that competes with any product or service offered by or made available by Licensor or any of its affiliates.
Datalab's card says the same in one line: "free for research, personal use, and startups under $2M funding/revenue. Cannot be used competitively with our API." Whether those clauses reach Interfaze's own hosted service depends on its funding and on whether a hosted OCR API competes with Datalab's hosted OCR API; I don't know the first, and the second is for the two companies to settle. What is clear is that the clauses travel with the file. Pulling the weights from Interfaze's repo does not get you out of them, whatever tag the repo carried on the day.
pyannote's speaker-diarization-community-1 is simpler. The card's metadata is license: cc-by-4.0, and the gate text reads: "This pipeline is released under the CC-BY-4.0 license and will always remain freely accessible. By providing your details, you agree that we may email you occasionally with important news about pyannote models". CC BY 4.0 allows redistribution. Its condition, Section 3(a), is attribution: if you share the material you must "indicate the Licensed Material is licensed under this Public License, and include the text of, or the URI or hyperlink to, this Public License", along with credit and a link. At 1bfa94c the bundle credited and linked pyannote but labelled everything Apache-2.0, which misses that clause; since 3ab4c59 the licence file names CC BY 4.0. What remains is the gate. Interfaze's copy serves the same four files with no gate, so nobody who takes them there gives pyannote the contact details its own repo collects. I can't find a clause in CC BY 4.0 that the ungated copy breaks; the gate is pyannote's condition for access on the Hub, not a term of the licence. If Vik's "likely issues" means that, it is a fair complaint about pyannote's funnel rather than a licence breach as the text reads.
Llama Guard 3 1B is the odd one, because it isn't in the bundle. Meta's repo is gated (manual) under license: llama3.2. There is still no guard/ folder, so Interfaze's Hub repo does not redistribute Meta's weights, and the copy and notice duties in the Llama 3.2 Community License's 1.b.i(A) and 1.b.iii are not triggered by it. Two other clauses are worth reading. Section 1.b.i says that if you "make available ... a product or service (including another AI model) that contains any of them", you must "prominently display “Built with Llama” on a related website, user interface, blogpost, about page, or product documentation". components.env.example says its defaults, including COMPONENT_GUARD=meta-llama/Llama-Guard-3-1B, "are what the hosted interfaze-1-lite runs". I found no "Built with Llama" on the Hub card, the GitHub README, the new LICENSE or the launch blog. The same clause adds that a model created, trained, fine-tuned "or otherwise improve[d]" with Llama Materials must "include “Llama” at the beginning of any such AI model name". A model that calls Llama Guard at run time was not trained with it, so I would not read the naming clause as applying, but "otherwise improve" is loose wording and Meta is the one who reads it.
None of this touches the other seven upstreams, which are Apache 2.0 or MIT and are correctly listed as such in the new file.
Where 85.8 comes from
The two numbers in Vik's post come from two different leaderboards. 83.8 is Lite's score on Interfaze's own olmOCR board, the one I quoted above. 85.8 is from Datalab's model card, which reports Chandra 2 at 85.8 ± 0.8 on olmOCR-Bench, sourced "Own benchmarks"; the card's history shows it was 85.9 until a commit on 2026-06-26 titled "Adjust scoring 85.9 -> 85.8". The official olmOCR repository's leaderboard has no Chandra 2 row at all. Its only Chandra entry is "Chandra OCR 0.1.0" at 83.1, marked as self-reported.
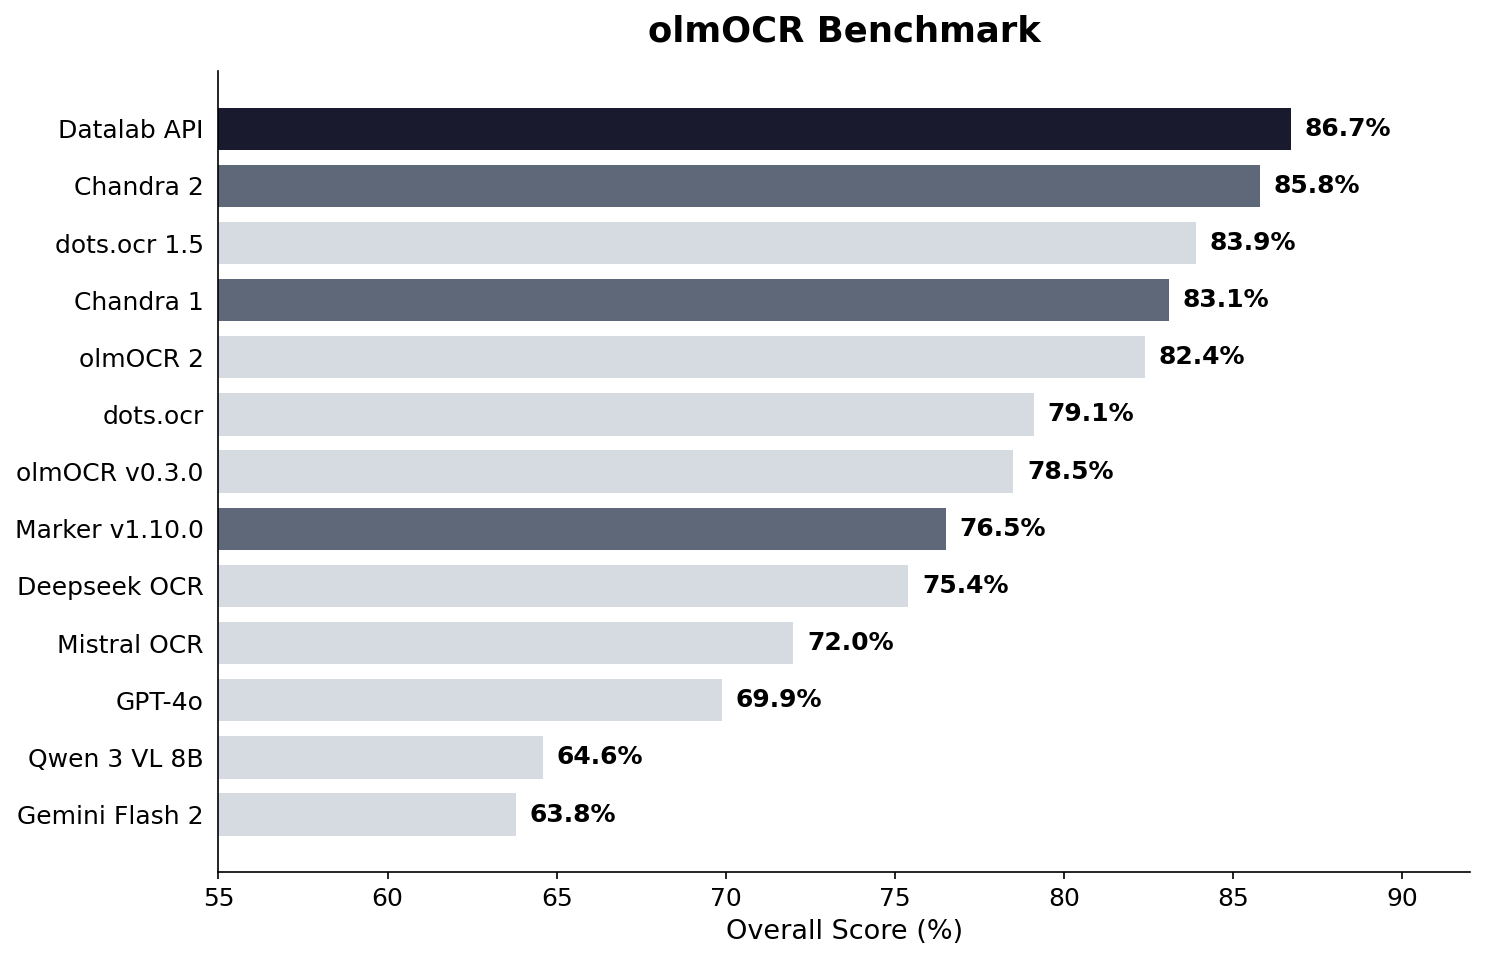
Both boards take the overall score as the plain mean of the eight categories. The eight Datalab numbers average to 85.79, and Interfaze's row for Chandra averages to 84.28, so the 1.5-point gap is entirely in the per-category scores. Interfaze's Chandra row carries no self-reported marker, which I read as Interfaze having run Chandra 2 itself; the page does not say with what settings. Most of the gap sits in two categories. Old scans with math is 83.0 on Interfaze's board against 89.1 on Datalab's, worth 0.76 points of the overall on its own, and tables are 87.9 against 92.1, another 0.53. Headers and footers and long tiny text go the other way by a point or less. Those two categories are the ones scored on rendered math and table structure, where prompt, output format and post-processing matter most, so a harness difference is the likely cause; I can't check that without either side's run.
So Vik's comparison crosses boards, and the like-for-like gap on one board is half a point (84.3 against 83.8), not two. Both comparisons point the same way, though: the stitched pipeline scores below the document reader it is built on, and on Datalab's own numbers Lite's 88.8 on tables is three points short of Chandra's 92.1. None of the figures I quoted earlier were wrong as citations; I have corrected the one sentence that read a table gain off Interfaze's board without saying whose run of Chandra it was.
If you use the bundle
Treat it as ten licences in one repo, and read the folder, not the tag. brain/, segmenter/, layout/, line_detector/ and line_recognizer/ are Apache 2.0 upstreams; asr_fallback/ is MIT; diarizer/ is CC BY 4.0, which needs attribution if you pass it on; Llama Guard and TimesFM are pulled by you from their own repos, under the Llama 3.2 Community License and Apache 2.0, if you enable them. The nine Python files and the configs are Interfaze's and Apache 2.0. ocr_vlm/ is Chandra OCR 2 under Datalab's modified OpenRAIL-M, including its revenue, funding and competition limits.
If you pulled the repo before 2026-10-07, your copy's card says Apache-2.0 and its LICENSE is only Apache's. That label was never Interfaze's to give for ocr_vlm/. If your organisation is past the $2M revenue or funding line, or sells something that competes with Datalab, and your use is not personal or research, the Chandra weights are not licensed to you under that text. Delete ocr_vlm/ or point COMPONENT_OCR_VLM at a reader whose licence you can meet, or talk to Datalab about a commercial licence. If you redistribute the bundle, carry the Chandra licence text itself and pyannote's CC BY attribution, not just links in a card.
How I checked
Everything above comes from reading files, not running them. I listed the Hub repo through its API with LFS SHA-256s, read each component's config and the routing code, and counted parameters from safetensors headers fetched with HTTP range requests; no weights were downloaded and no third-party code was executed. Benchmark numbers are the publishers' own, quoted from the pages named below.
On 2026-10-08 I went back for the dispute: the X thread under Vik Paruchuri's post and Yoeven's replies, read through the fxtwitter mirror (view and like counts as returned then); the repo's commit list and the tree at 5ff65f3, diffed path by path and hash by hash against 1bfa94c; README.md and LICENSE at every commit in between; the Chandra OCR 2 card, LICENSE and .eval_results/olmocrbench.yaml at af93b47; pyannote's card metadata and gate text and the CC BY 4.0 legal code; the Llama 3.2 Community License from Meta's llama-models repository (Llama Guard's own copy is gated); the official olmOCR README; and a fresh clone of the GitHub server.
Sources, read on 2026-10-06: interfaze-ai/interfaze-1-lite (model card, config.json, every component config, modeling_interfaze_lite.py, contracts.py, agent.py, guard.py, and the safetensors headers of brain/, ocr_vlm/ and asr_fallback/ via HTTP range requests); InterfazeAI/interfaze-1-lite (components.env.example, docker-compose.yml, README.md); the Hub file listings of Qwen/Qwen3.8-27B-FP8, datalab-to/chandra-ocr-2, openai/whisper-large-v3-turbo, facebook/sam2.1-hiera-large, PaddlePaddle/PP-OCRv5_server_det, PaddlePaddle/en_PP-OCRv5_mobile_rec, PaddlePaddle/PP-DocLayout_plus-L, pyannote/speaker-diarization-community-1, meta-llama/Llama-Guard-3-1B and google/timesfm-2.5-200m-pytorch; the launch blog, the leaderboards and the olmOCR board. Added on 2026-10-08: Vik Paruchuri's post and its replies, the repo's commit history, Chandra OCR 2's LICENSE, the CC BY 4.0 legal code, the Llama 3.2 Community License and the olmOCR repository. Figures are reproduced for commentary from Interfaze's launch blog and thread, Vik Paruchuri's post and Datalab's model card; the two interactives are original.