2026-10-08 · 192 min · math · theory · algorithms · agentic-coding · verifiers
Why read this
Solidtop 85%The whole κ race in one place: where the exponent comes from, all 44 PRs timed, PR #13's certificate re-run and recomputed, and why it changes no runtime.
- Original analysis
- A new technique
- Explained from first principles
Agents & harnessesRuns on a laptop CPUApache-2.0Research paper
How this was scored
- Is it new?
- 2 of 3: A real new idea, method or capability
- Can I trust it?
- 2 of 3: Measures key facts from files, code or configs
- Can I run it?
- 1 of 3: API-only, gated or restrictive licence
- Will I understand it?
- 2 of 3: Mechanism from first principles with figures
- Can I act on it?
- 1 of 3: General advice
- Will it last?
- 1 of 3: Relevant for months
- Does it affect many?
- 1 of 3: A specialist community
- Only here?
- 2 of 3: A teardown or measurement few others did
Score 56 of 100, ranked 497 of 701 rated articles. Each question is answered 0–3 by hand, and a 3 is rare. How articles are scored
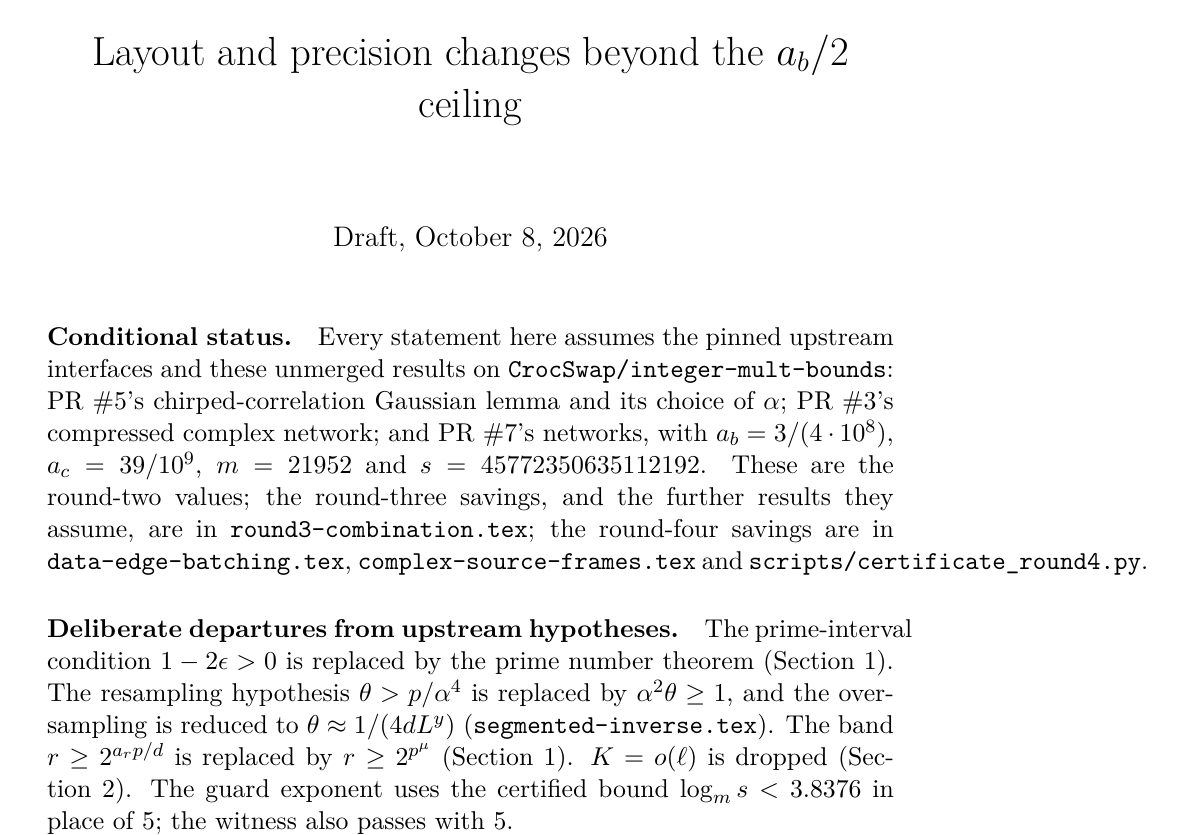
The site owner sent me a link to CrocSwap/integer-mult-bounds with the note "something crazy going on in this repo". When I opened it, the headline said . By the time I had read the pull requests, the best open claim was , a little above . When I started writing this paragraph, PR #45 had just arrived. By the time I finished the article, #48 had nudged the claim to , and Swapnil Jain, racing in a separate repository, had reached with its arithmetic checked in Lean.
Then, at 15:18 UTC, the story changed shape. Colkitt merged Rohan Arun's PR #39 into main, with , after an audit he published alongside it. For the first time a community number is the maintainer's number. It is still conditional on OpenAI's unrefereed manuscript, and the audit was Colkitt working with Codex, not a referee; the section on the merge goes through exactly what it checked. The open PRs had already moved past it: Rohan's own #49, under twenty minutes later, claims .
And it kept going after I thought I had finished. By 18:35 UTC main had moved twice more and stood at , after a new idea broke the plateau I describe below; the open PRs reached an hour later. Aurel Prosz, one of the contributors, built a live dashboard of the whole thing. And Ryan Shea took Jain's network across to a second OpenAI problem, the exact discrete Fourier transform, and claimed a saving 730 million times OpenAI's. The evening and the Fourier transfer have their own sections near the end.
Then, overnight, the plateau broke for good. Between 23:12 UTC on 8 October and 05:06 the next morning, icekylinx's PRs replaced the shape of the network itself, and main jumped ninefold to , about . Jain followed twenty minutes later at , by building on the same cover, and the open PRs were at when I stopped, at 11:00 UTC on 9 October. The ninefold night explains what changed, and why κ is still nowhere near 1.
The afternoon was quieter in ratio and busier in every other way. At 12:57 UTC Colkitt moved main again, to . Ten minutes later Jain posted round eleven at , which led every claim anywhere for nineteen minutes, and said he needed an arXiv endorser for a paper collecting the proofs. By 18:50 UTC the best open claim was , and several contributors had stopped chasing κ to prove how far the current designs can go at all. The afternoon covers all of that.
Overnight the Fourier side overtook the multiplication side in the one way that matters. Jacob Sussman, working with Claude agents, proved in Lean that a fixed program computes the exact Fourier transform of every length in steps, on OpenAI's own Lean statement with only the exponent changed, and Chafik Boukhalfa pushed it to . Ryan Shea's paper now carries that number. On the multiplication side a layout from the same Lean work, five stages instead of three, took the open claims to , and Colkitt announced a merge that GitHub still doesn't show. 10 October has it all.
Then the multiplication side found a new shape too. Around midnight UTC on 11 October contributors swapped in a small Lean-checked unit of Sussman's built on 120 labels the agents named E8, first on the complex side and then on the bit side, and the open claims went from to past by 07:09 UTC and to by the evening. main had moved once, to . 11 October explains what E8 is doing there, checks the leading claim, and looks hard at Rohan Arun's statistics, one of which is 261 million lines of code.
And then the maintainer caught up. On the evening of 12 October Colkitt posted a reviewed checkpoint of , , from Jeremy Kothe's helpers that stop short of the full frame. By the time I cloned the repository the next morning main had moved four more times, to , and for the first time in the race no open PR claimed more. 13 October covers the eight moves, the two mechanisms worth understanding, and how one maintainer merged 116 PRs in a day and a half.
By the afternoon main had moved twice more, by 0.0195% and then 0.00017%, to , and Rohan Arun proposed that every repository like this one carry an auto-research.md prompt and an auto-research/ folder for failed experiments. 13 October (evening) reads the proposal, the Leech and Barnes–Wall screens, and his PR statistics.
Some background. Two days ago OpenAI's math release included a 73-page manuscript, Integer multiplication below n log n (result family 109), which claims a multitape Turing machine that multiplies two -bit integers in steps with . I covered it briefly in the openai/math roundup, and it has a tile on the AI breakthroughs in mathematics wall. Doug Colkitt (@0xdoug, the founder of CrocSwap/Ambient) forked the argument into a "research draft" and started tightening the constants. Then other people joined in. Counting as the start, the exponent saving has grown by a factor of about in forty hours.
That sounds like a story about multiplication getting faster. It isn't one, and the reason is the most interesting part. What follows covers what is, where it comes from in the construction, what each step of the race actually changed, what I could re-run myself, and why the very funny "linear time by tomorrow" chart that went round on X is wrong in an instructive way.
- license
- Apache-2.0
- branch
- main
- tests
- 33 files
- source
- 500.5 kB
- commit date
- 2026-10-08
by size of tracked source at this commit, file counts in brackets; docs, data and vendored trees excluded
local clone, 2026-10-08 at 1a74950 — branch, commit, commitDate, fileCount, hasTests, languages, license, licenseFile, shallow, testFileCount
shallow clone: counts describe the pinned tree, not the history
What measures
Schönhage and Strassen multiplied -bit integers in steps in 1971 and guessed that was the true answer. Fürer got within a factor of it in 2007. Harvey and van der Hoeven reached exactly (Annals of Mathematics, 2021), and most people took that to be the end.
The OpenAI manuscript claims a bound of
So is the power of you get to divide out. At you have Harvey–van der Hoeven. At you would have linear time, which is the floor, since just reading the input takes steps. Every value in between is a strictly faster growth rate than . For the question "is optimal?", is as good an answer as : any refutes the conjecture.
The machine model matters. The theorem is about a deterministic Turing machine with a fixed finite alphabet and a fixed number of one-dimensional tapes, the model in which Schönhage and Strassen stated their conjecture. On a tape, moving data costs time proportional to the distance it travels, so even rearranging bits at each of FFT levels costs . The manuscript says this outright: "Scanning an array of stored bits at each of transform levels already costs . We therefore need savings in both movement and arithmetic" (upstream/build/sections/00-introduction.tex).
Nobody had ever proved an lower bound in this model. The best result is conditional: Afshani, Freksen, Kamma and Larsen (2019) showed that a circuit lower bound would follow from the network-coding conjecture, and a time- Turing machine only gives circuits of size about , so even that does not transfer. The FFT section of the roundup goes through the same gap for the Fourier transform, where the release's family 130 reuses this manuscript's finite gadget. The point to keep in mind is that was a barrier nobody knew how to cross, not a proven wall.
Where comes from
The pipeline is Harvey–van der Hoeven with every change of representation charged on tape: digits go onto prime cyclic axes by a Chinese-remainder map, Gaussian resampling turns those into power-of-two axes, and a phase twist turns the last axis into polynomials modulo , where multiplying by a root of unity is just a signed shift.

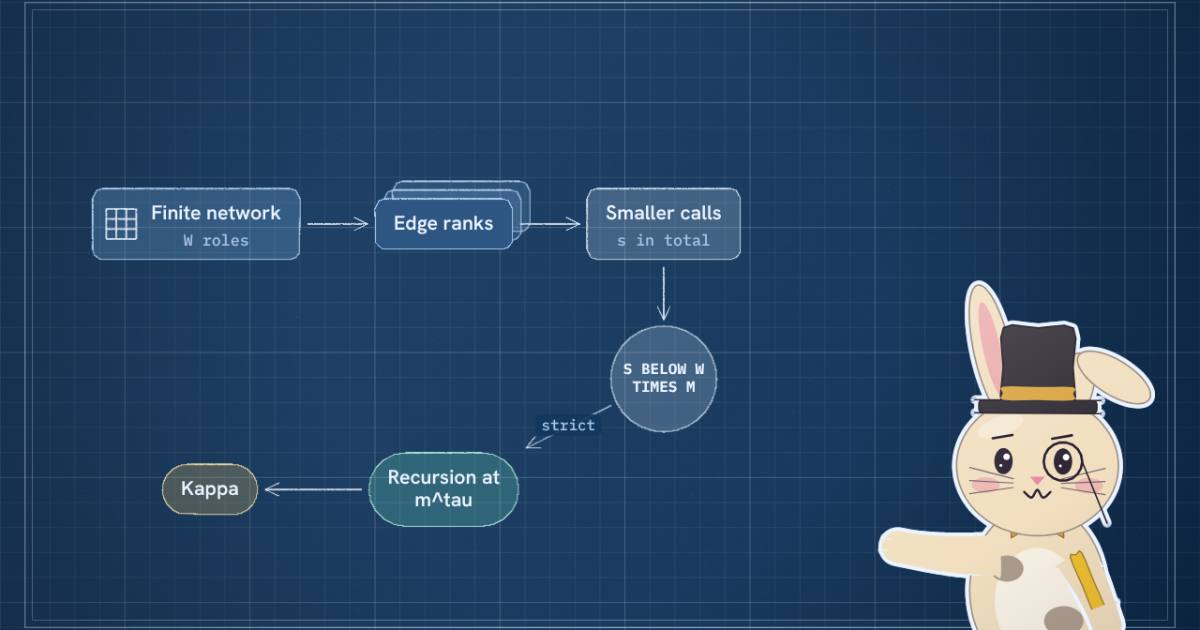
The new part is two tape procedures built from fixed linear networks. One swaps two address fields of an array; the other applies a layer of butterflies to selected coordinate bits. Each network is a finite circuit on "roles" (wires), it exchanges two banks of values while restoring every scratch value, and each edge of the circuit is carried out by smaller recursive calls of the same procedure. The decisive count is the total number of those smaller calls. If , then multiplying the problem parameter by multiplies the normalized cost by , and the recursion runs at with . The manuscript: "This strict inequality is the source of the power saving."
How much below it lands is tiny. In the original construction the relative deficits are (upstream/build/sections/03-motifs.tex:673-678)
at , so the honest savings are about and . The manuscript then rounds them down to and calls its constants "deliberately conservative; no optimization is claimed". Remember that sentence. A lot of what happened next is people taking it at its word.
Those network savings feed a cost table. With the working precision, the paper divides every operation's cost by the data volume and gets a power of . Seven rows dominate, and each has a margin below 1:
The total time is times to the largest power, so the exponent saving is the smallest margin, minus a sliver of slack to absorb stray factors. The upstream parameters are , and , so , and the paper says "Thus " (08-assembly.tex:866). That is where comes from: three small numbers multiplied together, then halved.
The repository's checker transcribes the same seven margins as exact fractions (scripts/certify.py:136-147):
def margins(p, *, layout_model="adjacent", assembly_model="original"):
require(assembly_model in ("original", "tight-gaussian"), "Unknown assembly model")
e, c, t = p.epsilon, p.c, p.tau
return {
"g1": 1-e*(1+c),
"g2": e*c*(1-t),
"g3": e*(1-p.lamp),
"g4": 1-t-e*(layout_degree(layout_model)-t),
"g5": Q(1, 4)-p.delta-(Q(5, 4) if assembly_model == "tight-gaussian" else Q(3, 2))*e,
"g6": 1-p.delta-e,
"g7": e,
}Once you see as a product of factors, the race is easy to follow. Every improvement attacks one of the factors: it makes the network saving bigger (better circuits), lets grow (better routing, better Gaussian resampling), lets grow (cheaper control movement), or changes the recurrence so the same circuit counts for more (batching). The widget below shows the seven margins on a log scale for the original paper, Colkitt's checkpoint and PR #13. In the original, sits at and nothing else comes close. By PR #13, , and are all balanced at about , which is what a tuned parameter set looks like.
There is also a ceiling built into this shape. Since and , the smaller of the two is at most whatever you choose, and is at most the bit network's saving . In every witness I checked, sits just under that network saving: against at the checkpoint, against in PR #13, and against in PR #44. To get anywhere near linear time this method would need finite networks whose recursive calls nearly vanish, and nothing here suggests that is possible. The overnight witnesses of 9 October keep the same shape: in PR #144's assembly two margins are balanced against each other so that , where is the weaker network's saving, and that saving is in turn about the network's relative rank deficit divided by how far below full width its average child sits on a log scale. The section on the ninefold night works through the numbers. By 11 October the assembly had changed to balance at , with the weaker network's saving (the ceilings, a day later).
Of everything in that chain, the part that steers the race day to day is a minimum. From the three-shear cover on, the assembly is fed a single network saving, the smaller of the bit network's and the complex network's, and whatever the stronger side has beyond that goes unused. Contributors call the binding side the wall. I found it easier to hold as an instrument than as a formula, so I drew it as a bench stop gauge. Each network gets a rod with a clamp collar set at its certified saving, the bit network in front and the complex network behind. A steel band off a spring drum pulls the carriage toward larger savings, and the carriage comes to rest against whichever collar is nearer. That collar is the wall, and it is lit. Moving the other collar changes nothing until it overtakes. The carriage's index foot reads the saving on a ruler in units of , with a long line at , and its dial turns once per , as a dial caliper's does. A pin on the ruler marks main at that moment. itself sits a hair under the stop, at in #144's assembly and in the one in use on 11 October; at #144 that is 0.09% under, which is too close to draw.
The ten witnesses on it are the ones where this article gives both sides' savings, and stepping through them, the wall changes sides seven times in four days. At #144 the bit network binds at against the complex . Jain's round ten, on his own track, leaves the complex side behind ( against ), and round eleven hands the wall back to the bit side by a whisker ( against ). On 11 October #346's Design T leaves the complex supplier as the wall, Sussman's E8 unit in #352 lands 9.3% past the bit side and gives , the E8 bit word in #370 flips it back, and by #467 the two collars sit almost level, at and , with the carriage past the line and main's pin still back at . #390, the first PR past , isn't a stop here because I only have its complex side. The last three stops are from main itself on 12 and 13 October, so the pin sits right under the carriage: #535 at 13:11 UTC on 12 October, where the bit side binds by 0.16%, Jeremy Kothe's #596, the checkpoint Colkitt posted that evening, where the complex side binds with the bit word 2.4% ahead, and #799 the next morning, at with 4.1% to spare on the bit side (13 October). To fit them I stretched the ruler to . The figure is drawn with the site's copy of the isometric-figures skill, which is Ryan's Anatomy, and every collar is set from the numbers in the sections below.
Colkitt's day and a half
Colkitt's own checkpoints are on main (the last one is also on release/ternary-30). Each came with an X post from @0xdoug, and each post's ratios check out against the exact witnesses.
| commit (UTC) | what changed | |
|---|---|---|
5cf29ec Oct 7 02:22 | , between and | parameters only: same network, sharper recurrence comparison |
52ce3be Oct 7 13:35 | direct nonadjacent axis swaps: layout from to | |
bcd4ebd Oct 7 19:27 | paired circuits with shared sums, tighter guard and Gaussian width | |
6e56487 Oct 8 00:27 | compact dirty controls instead of spaced windows | |
1c09a58 Oct 8 01:10 | compressed complex network, binary phase frames | |
1a74950 Oct 8 13:10 | ternary five-subset bit circuit over |
The first note is the most honest thing in the repository. With the paper's cost accounting left alone, it finds and also proves a ceiling of for that family, so the witness is within 1% of the best that accounting allows. Colkitt's post said so: "Surpassing this ceiling would require improving the network bounds or cost analysis from the original result."
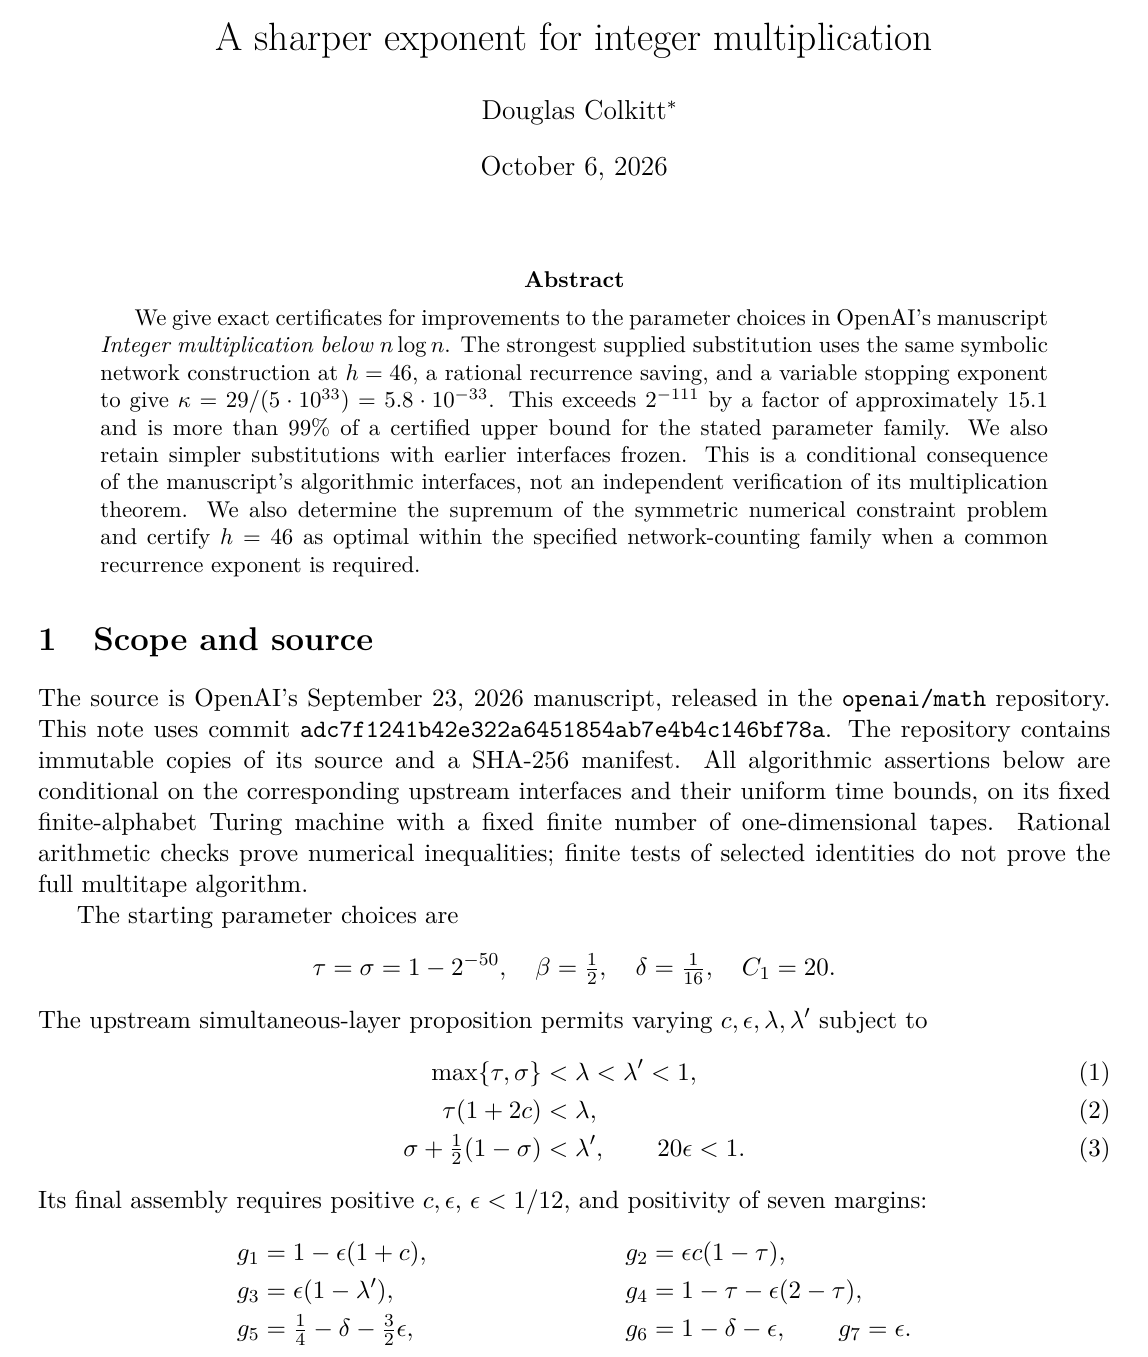
So the next morning he changed the accounting. The original layout row costs because it reverses axes with adjacent swaps; the manuscript already allowed nonadjacent swaps, and using them directly makes it . That changes to , which no longer forces to be smaller than the network saving. The result-history page explains the consequence: the original layout "forced epsilon < a, yielding a cubic constraint kappa < a^3", and the new schedule makes the saving scale "quadratically in a" (docs/research/result-history.md:253-256). Going from to when is how you gain thirty-odd powers of two in one commit.
The step improved the network itself, which raises : rectangle incidence circuits, then shared intermediate sums, cut the side roles per invocation from 41,122,620 to 2,394,438 and then to 577,576 at , and paired-block circuits at reach 509,194. Fewer roles for the same rank deficit means a larger relative deficit, so a larger .
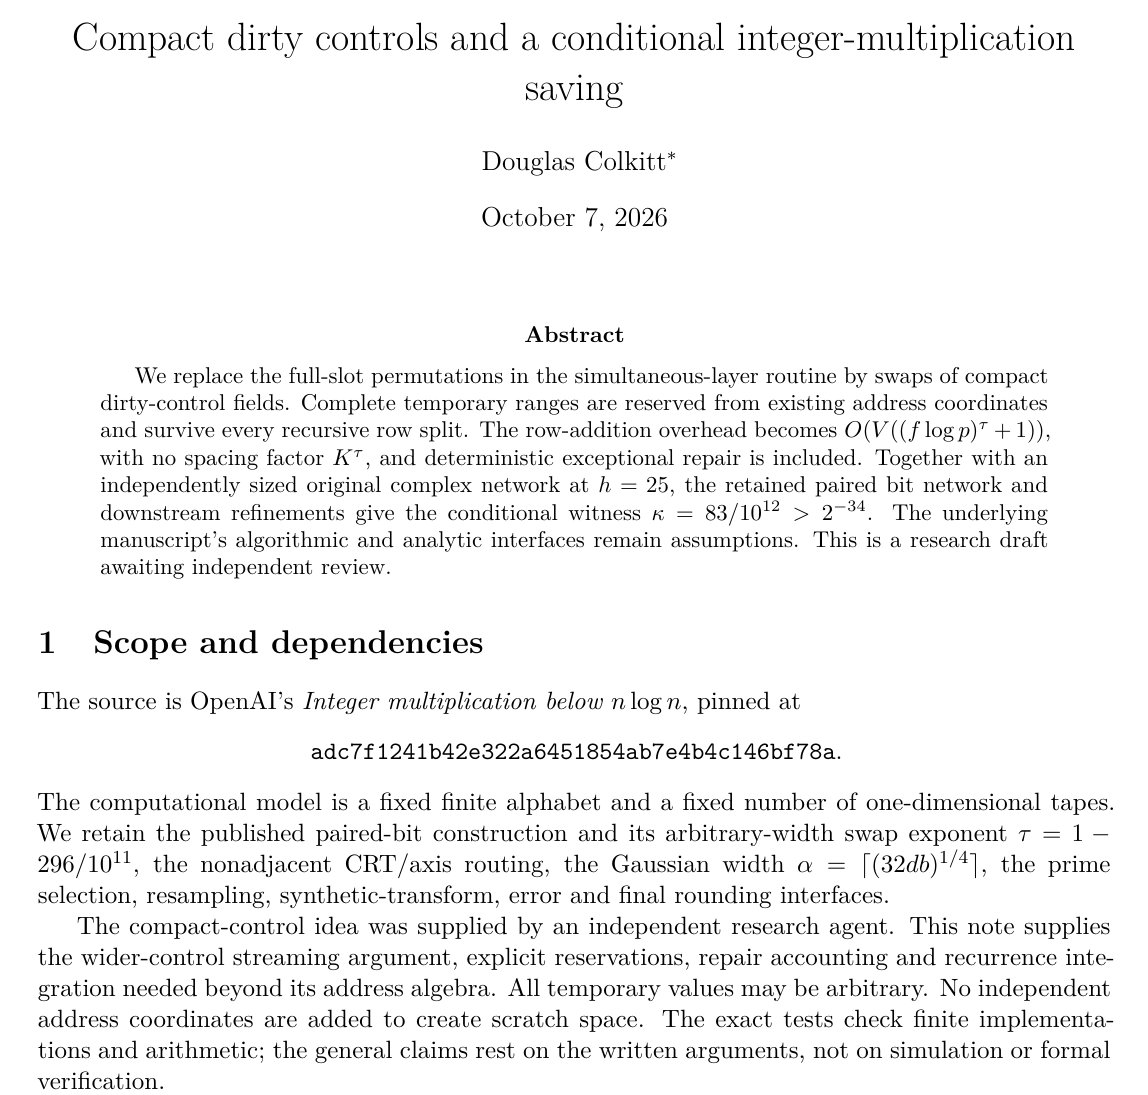
The compact-control step at attacked . Moving whole spaced windows had a spacing penalty that forced to be of order ; moving only compact control fields removes it, so and becomes roughly times . His post that night put it in two sentences: "The improvement came from removing the spacing penalty behind the quadratic bottleneck. This was done by moving compact control bits instead of entire windows." Its "roughly 48 million fold improvement over the previous result" checks out against (about ), and so does "a 2¹⁴⁸ fold improvement over original OAI result" (). Here the README discloses that the idea did not come from Colkitt: "The compact-control proposal originated with a separate research agent; the supplied note develops its tape, layout, repair and assembly arguments" (README.md:138-140).
The last two checkpoints moved the bottleneck between the two networks. At a compressed complex network (, ) overtook the bit network's , so the bit side became binding. The checkpoint then replaced the bit circuit with one that computes over .
The trick is pretty enough to show. Label the circuit's wires by the five-element subsets of 29 points, of them, and let be the incidence matrix of five-subsets against pairs. Then , and for intersection sizes those residues are . So , where is the adjacency of subsets meeting in exactly two points, and the "side" map is just . A central factor of size plus a correction that only touches intersection-two neighbours gives exactly the identity. I checked the residue identity by brute force over all 126 five-subsets of nine points; it holds.
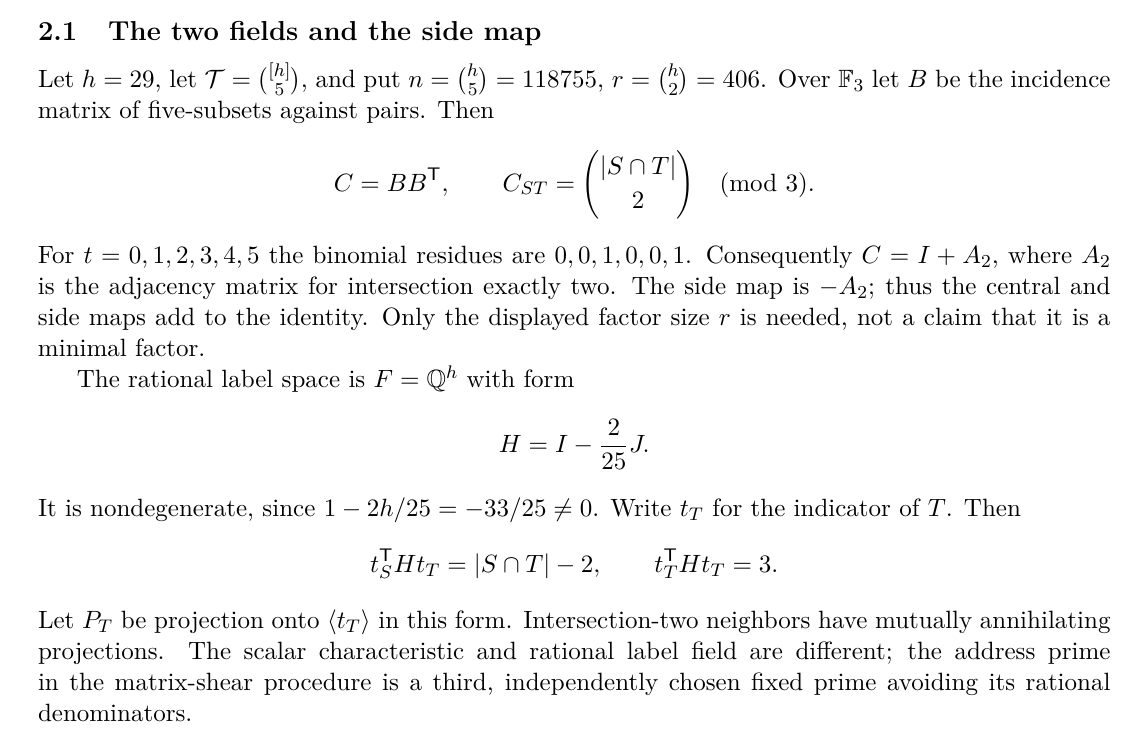
The full circuit has 19,593,239 active additions and 20,780,789 side roles per invocation, and the exact count gives with a relative deficit of . I recomputed the implied saving from the certificate's , and : , just above the certified . The final minimum margin is , which exceeds by about 0.194% of the claimed saving.
That checkpoint was not first, and its README says so: "Zhihao Chen's earlier PR #7 introduces the same ternary five-subset motif with a different circuit and stronger claimed bound. This release records a separate implementation and conditional checkpoint; it makes no priority or strongest-known-bound claim."
Everyone else shows up
The first outside PR arrived at 20:58 UTC on October 7. Between 02:23 and 14:24 UTC on October 8, 42 more arrived, from about ten people. By 11:00 UTC on October 9 there were 179, by 11:30 UTC on October 10, 301, by 19:40 UTC on October 11, 485, and by 07:20 UTC on 13 October, 843. The chart has all of them that state a κ: Colkitt's checkpoints in red, OpenAI's starting point in grey, the community PRs coloured by author, a green step line for the best claim open at each moment, and a red step line with a square at each move of main (#39 at 15:18 UTC, #49 at 16:47, a reviewed batch at 18:35, and icekylinx's #144 at 05:06 the next morning, then fourteen more, twelve of them on 12 and 13 October). Everything after is squeezed into a sliver at the top, so the zoom button redraws everything from 10:00 UTC on October 8 on its own. Jain's separate track is the purple diamonds, with a ring on the rounds whose arithmetic is checked in Lean; more on that below. The dotted green line is , first passed on 11 October, and the hollow circles are claims that rest on a step another contributor has challenged (11 October). Click a point (or use the dropdown) for its title and link.
A few PRs changed the shape of the problem rather than its constants, and those are the ones worth understanding.
Start with eumemic's #3 and #5. #3 compressed the complex network, cutting its side wiring from 3,693,800 roles per invocation to 108,195 and taking its saving from to . That made the bit network binding, and the next limit was the Gaussian resampling row: its cost forced and capped below . #5 rewrote the resampling as chirped correlations evaluated by the existing multiplier and bounded the Neumann series more tightly, which let approach . That one change of analysis was worth a factor of about 2.5 on its own.
Zhihao Chen's #7 is the five-subset construction, at , posted at 06:12 UTC, seven hours before Colkitt's independent version. Chen's PR credits "GPT-6 Astra (OpenAI Codex)" for "research, proof-development and implementation assistance" and asks that future work "explicitly acknowledge Zhihao Chen (jacklightChen), cite this PR and its accompanying note". The maintainer did.
icekylinx's #10 is the structural break you can see on the chart: from to in one PR. Upstream, every edge of the network costs singleton recursive calls, one per unit of rank. #10 shows that a contiguous block of address fields from a projector can be done as one recursive call of width , given a common controlled basis. The recurrence condition stops being a count and becomes a moment: with rank-mass weights on calls of relative width , you need . A singleton call has and costs the full ; in #13's profile, a block covering 195/196 of the fields costs almost nothing extra. The same PR fixes an error-enclosure gap it found in #5's fast Gaussian argument, with no change to the exponent.
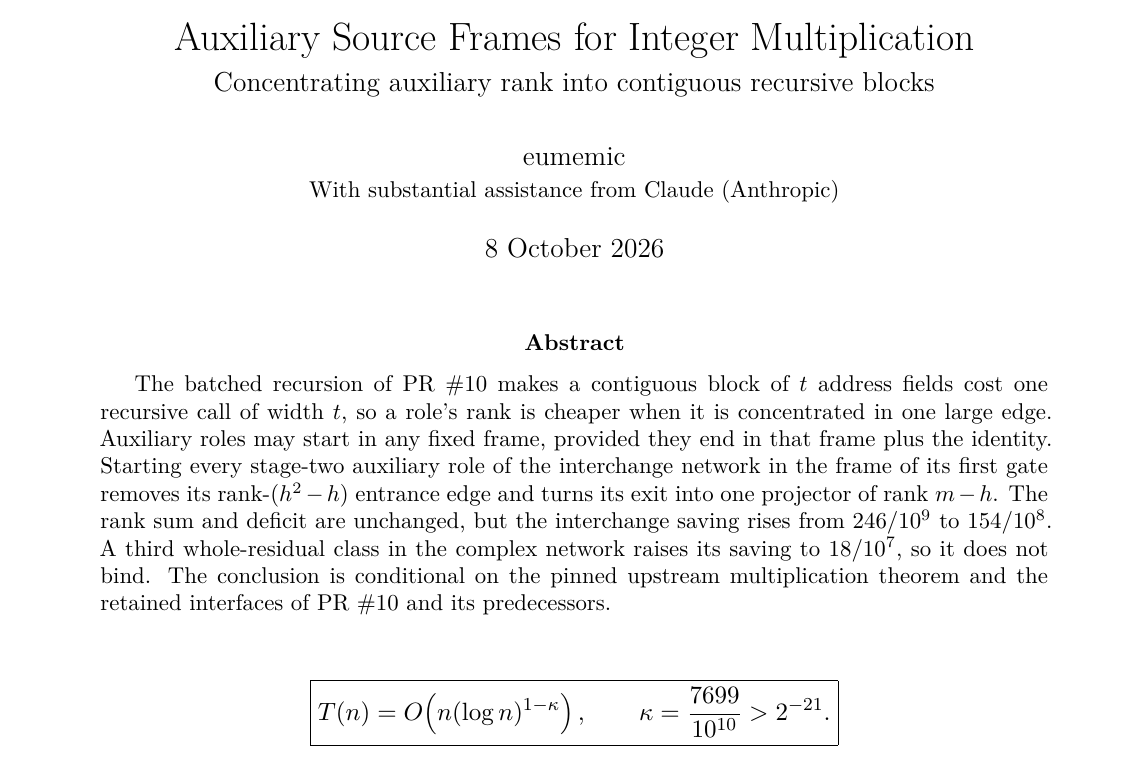
eumemic's #13, the one the site owner pointed at, is a neat idea. The network's correctness condition only needs each role's endpoint frames to differ by the identity: . A scratch role does not have to start in the zero frame. It can start in any fixed frame as long as it ends in . Starting every stage-two auxiliary role in the frame of its first gate deletes its rank-756 entrance edge and turns its exit into one projector of rank . That projector compiles to singleton pivots plus one contiguous block of fields. The total rank is unchanged. What changes is where it sits: out of singleton calls costing each and into one block. Under #10's moment, the interchange saving goes from to , and with a third whole-residual class on the complex side, goes from to , a factor of 6.26. Since , the claim is about ; the title's "" undersells it.
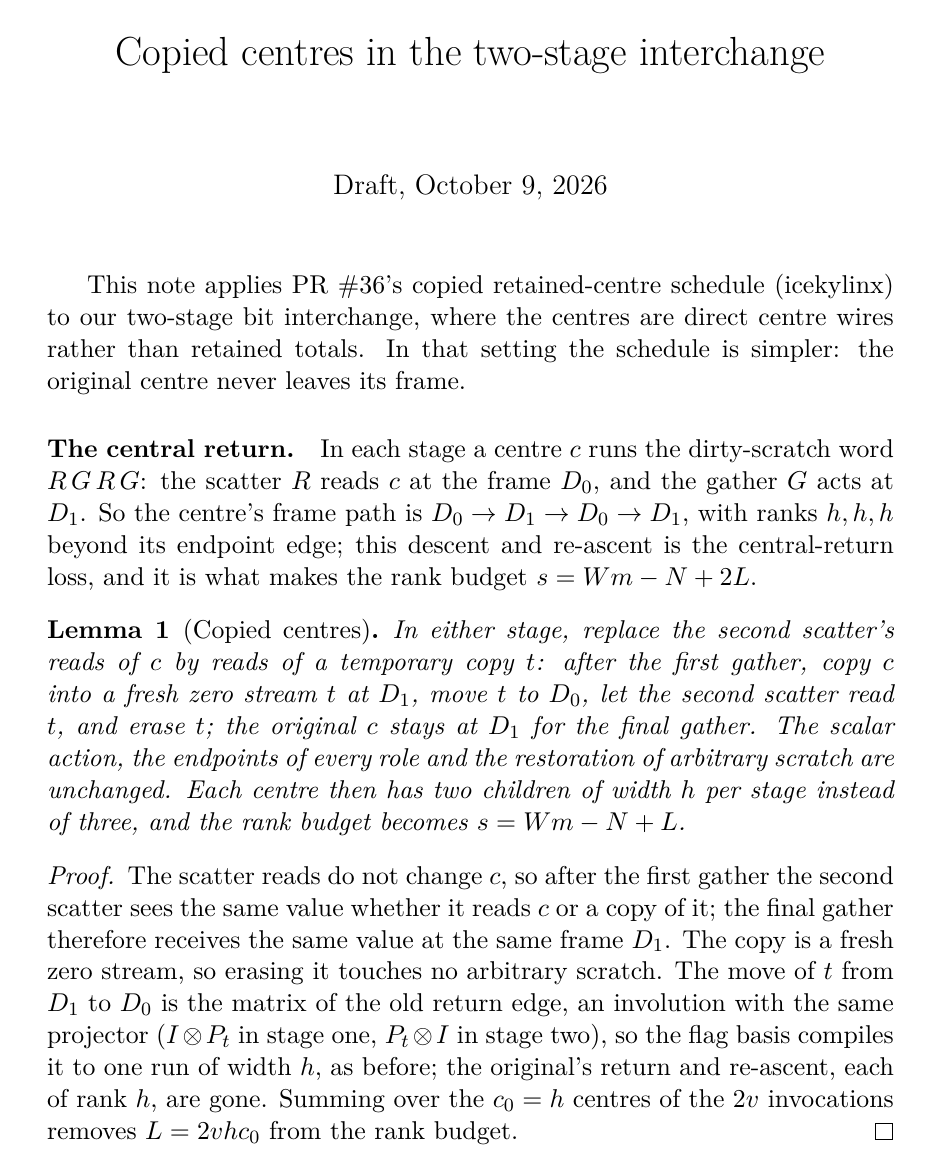
After #13 the tempo picks up. #15 brought a smaller producer, #18 partial swaps, and #21 and #23 translated frames and "semantic precision", reaching . #29 introduced a two-stage topology from Aurel Prosz's work and reached . #36 added copied retained centers, which halve one rank term ( becomes ) and jump to . Everything after that is composition and tuning: fixed local bases, reversed corners, carrier matchings. PR #44 claims , which it describes as "approximately 0.02681% above #43". The last three PRs are within 0.03% of each other. Three more arrived while I was writing: chafreaky's #46 adds 0.0000048% to #44, Rohan Arun's #47 adds 0.109% with hill-climbed producers, and chafreaky's #48 reorders the leave-one-out sums to save 847,550 wires and reach . Then Rohan's #49, at 15:36, started from #48's orderings and hill-climbed them the way #47 had, for , 0.127% more. The step line flattens around after 12:30 UTC.
When I first wrote this section I called that flattening the most informative thing on the chart, and said it was what you would expect if the cheap structural moves inside this family of constructions had mostly been made. Three hours later Avi Eisenberg's #53 jumped 9.2% in one PR, and the step line climbed again to . Use the zoom to see both plateaus; the evening section explains the move that broke the first one. I'd still read the flat stretches the same way, only with less confidence about how long any of them lasts.
Re-running PR #13
The brief asked me to check the claims, and these are certificate checks I could actually run: pure Python with fractions, plus a small C++ helper on the PR branches, no network. On a shared 16-core machine at nice 19:
On main at 1a74950, the focused verification from the README. scripts/audit_ternary_side.py builds the full DAG (about 21 million addition nodes) and finished with PASS ternary side construction and conditional 2^-30 assembly. in 176 s at 1.6 GB peak memory. make_ternary_patch.py took 17 s, the 12 focused tests passed in 39 s, the patch applied to the pinned upstream source, and the regenerated certificate and patch were byte-identical to the committed ones.
On PR #13 at 3ef246f, scripts/source_frame_network.py runs in 0.1 s and prints the witness:
PASS kappa=7699/10000000000 > 2^-21
bit saving=77/50000000; complex saving=9/5000000
bit moment gap=4.69651719166272e-10
complex moment gap=3.899666592614166e-09
minimum margin=3849992299500001/5000000000000000000000; gap=492299500001/5000000000000000000000The regenerated certificates/source-frame-network.json compared equal to the committed one. The six tests in tests/test_source_frame_network.py, including an exact model in which the new exit is checked to be an idempotent of rank with exactly corner pivots, passed in 20 s. The full make verify on the PR branch took 432 s: 172 tests passed, all 19 manuscript patch checks applied, and the certificates and patches regenerated without a diff. Those numbers match what the PR description claims.
Then I recomputed the arithmetic myself, without the repository's helpers. From the certificate's parameters (, , , , ) the margins are , and , all about ; and are about , and and about . The minimum is , which beats by . So the claimed does follow from the margins.
The bit-moment check is the step that carries the new idea, so I redid it at 80-digit precision rather than with the script's bound. Here is how the script does it (scripts/source_frame_network.py:54-62 on PR #13):
def moment(weights, ratios, a):
"""Upper bound for sum_i w_i ratio_i^(-a), using exp(x) <= 1/(1-x)."""
logs = []
for r in ratios:
simple = SIMPLE_LOGS[r]
require(log_upper(1/r) < simple, 'Rational logarithm bound failed')
require(0 <= a*simple < 1, 'Exponential upper-bound range failed')
logs.append(simple)
return sum((w/(1-a*ell) for w, ell in zip(weights, logs)), Q(0)), logsThe four classes have weights of about 0.0044 (singletons, relative width ), 0.4934 (width ), 0.0076 () and 0.4946 (). With the moment is , below 1 as required, and bisection puts the largest saving this rank profile supports at about . PR #13's leaves about 0.6% headroom.
None of this checks the hard part. The certificates confirm that the counts, ranks and inequalities are what the notes say they are. They do not confirm that a contiguous projector block really can be executed as one recursive call on a fixed-tape machine, that the controlled basis exists at full size (the review guide for #10 says it is "established by the existence argument, not by materializing every h28 factorization"), or that the upstream theorem is true. Colkitt's own review index was clear, that morning, that this was still open: "These changes appear to cross the singleton-rank recurrence limitation; the headline alone does not establish that step." By the afternoon his audit had worked through those obligations for the one chain he merged, #39's (below). For #13's own construction and every PR outside that chain, the sentence still stands.
A second race, one repository over
While those PRs were landing, Swapnil Jain (@SJ_Swapnil_Jain) was running a race of his own. He never opened a PR on Colkitt's repository; none of the 13 accounts that did is his. He kept Swapnil-jain/integer-mult-kappa, posted six numbered updates on X between 07:20 and 14:03 UTC, and the sixth ended with a sentence nobody on the CrocSwap side could write about their frontier: "Both interchange certificates and the full assembly are checked in Lean's kernel." I cloned it and read all of it, and I wanted to know two things. Is this really a separate result, and what exactly did Lean check?
- license
- Apache-2.0
- branch
- main
- tests
- 6 files
- source
- 253.3 kB
- commit date
- 2026-10-08
by size of tracked source at this commit, file counts in brackets; docs, data and vendored trees excluded
local clone, 2026-10-08 at f2176bc — branch, commit, commitDate, fileCount, hasTests, languages, license, licenseFile, shallow, testFileCount
shallow clone: counts describe the pinned tree, not the history
I lined the six posts up against what was open on CrocSwap at the same minute. The witnesses are the exact rationals from the commit each post announced; they are the purple diamonds on the chart above.
| post (UTC) | Jain's | best open CrocSwap claim then | what was new |
|---|---|---|---|
| 07:20 | #7, | the "ε → 1 stack" | |
| 08:15 | #9, | Gaussian correction inverted block by block | |
| 10:05 | #18, | batching on a two-stage bit network | |
| 11:10 | #28, | PR #24's bit network, complex source frames | |
| 12:39 | #37, | his own bit network on one flag basis; first Lean file | |
| 14:03 | #43, | copied centres; both savings and the assembly in Lean |
So he held the lead twice: for about an hour after his first post, until icekylinx's #10 at 08:26, and for nineteen minutes after his third, until Zhihao Chen's #21 at 10:24. His fourth post went out one second after #28 was opened. From round five on, the CrocSwap side was ahead, by 2.5 times at 12:39 and by about 12% at 14:03. His own ratios check out: round six is 2.37 times round five, and to is a factor of . The one soft spot is the first post's comparison with Colkitt's ("a roughly 60 fold improvement"): by then Colkitt's main was already at , so against the newest checkpoint it was about ten.
"Independent" is the wrong word for it, and Jain doesn't use it. His NOTICE pins Colkitt's 6e56487 and cites fourteen open CrocSwap PRs (#3 through #36) plus Aurel Prosz's fork. Round four reads PR #24's published network counts from a JSON file pinned by SHA-256. Round six's copied centres are, in the first sentence of his note, "PR #36's copied retained-centre schedule (icekylinx)" applied to his network. The traffic went the other way as well. Chen's #29 and Rohan Arun's #31 credit "Swapnil Jain for the linked two-stage batching development", icekylinx's #36 links Jain's round-three commit with the line "no source code imported from this repository", and #44 and #47 list him with everyone else. These are two forks of the same argument, reading each other's work all morning.
What is his is the part of the stack that turns a network saving into . Through PR #13, sat at about half the bit network's saving: against . His README explains why. A few costs tie the saving either to the number of axes or to the axis width , with , so the saving gets split between them, and the Gaussian resampling's precision budget, about , has to fit inside , which keeps below . His first round made five changes at once. The coefficients become bits long instead of about , so precision no longer competes with address length. The Gaussian correction is inverted block by block (every block is "the same Toeplitz matrix up to a geometric rescaling, so one stored inverse serves the whole line", as the second post puts it). Each axis becomes one chunk, only the low bits of an axis are moved for resampling, and the axis reversal reuses Colkitt's selected-bit additions. With all of that, can go almost to 1, and that is the "ε → 1" in every post.
I recomputed the round-six witness from the numbers in his certificate, without his code. The bit saving is , the complex saving , so and . He sets . Of his five cost margins, , minus a -sized term, and all come to and a bit; is the smallest; and itself is about 1. The claimed sits under the binding margin. The tidy way to say it: is chosen so that , which makes to eleven digits. Every bit of the network's saving reaches .
The CrocSwap side got to the same place by another road. RaD/hipotures' #20 and Chen's #23, at 10:20 and 10:43 UTC, used "completed-child semantic precision" and bulk resampling, and neither cites Jain. Round four is a neat accidental experiment. Jain and Dominik Scholz's #27 took the same PR #24 bit network, with , put it through their two different assemblies, and got and . Both stacks now pass essentially the whole network saving through, so the 12% gap between 3.67 and 4.12 is entirely the bit network: here against #48's .
The ε → 1 stack also has a price that the headline hides. With near 1, the coefficient-depth guard needs . Round six uses the crude guard (from ), so and each coefficient is bits long. In round five the same rule gave . That is legal, because is fixed and the volume stays , and his certificate says as much ("The exponent is huge but fixed, so the O() statement holds", scripts/certificate_round3.py:15). It is one more reason the runtime section below holds for this track too. The stack notes also list "deliberate departures from upstream hypotheses": the prime number theorem replaces the manuscript's explicit interval lemma, the resampling hypothesis is weakened, and so on. So this track rests on more than the CrocSwap PRs do: the manuscript, the fourteen PRs it cites, and its own replaced hypotheses.
What the Lean files prove
There are two, lean/Round5.lean and lean/Round6.lean, and neither is written by hand. lean/gen.py emits them from JSON files that dump.py and dump6.py write out of the Python certificates. They are core Lean 4: no import, no Mathlib, no lakefile and no lean-toolchain, so no version is pinned; make lean runs lean lean/Round6.lean with whatever is on the PATH. Rationals are pairs of naturals with a hand-written gcd normalisation, is a 30-term atanh series with a geometric tail bound, and each file ends in five theorems. Round six's, from lean/Round6.lean:74-81 with the histogram lists cut:
theorem bit_rank_sum : rankSum bitHist = 78410006675 := by decide
theorem bit_moment : momentOK bitHist (36667, 1000000000) 529 148225616 = true := by decide
theorem cx_rank_sum : rankSum cxHist = 119453132304 := by decide
theorem cx_moment : momentOK cxHist (36926111, 500000000000) 576 207387136 = true := by decide
theorem kappa_assembly : kappaOK (36667, 1000000000) (36926111, 500000000000) (1, 1000)
(2499908335861049, 2500000000000000) (14695, 1) (14694, 1)
(3666565558019, 100000000000000000) 576 119453132304 = true := by decide +kernelThere is no sorry, no axiom and no native_decide in either file. Both decide and decide +kernel end in a proof term that the kernel checks; +kernel only skips the elaborator's own evaluation first. native_decide would have compiled the decision procedure and trusted the compiled code, and it isn't used. The kernel does use GMP for natural-number literals, which is part of Lean's normal trusted base. So yes, it really is the kernel.
The more important question is what the theorems say. They say that three particular Boolean functions return true on particular lists of numbers. They do not say those lists are the child-width histograms of the networks; gen.py pastes them in from Python. They do not say lnUp bounds the logarithm or that the moment sum controls the recurrence. The generator's docstring is explicit: "The analytic facts behind (2) and (3) -- the atanh tail bound and (m/w)^a <= 1/(1 - a ln(m/w)) -- are premises, not checked here: Lean core has no real logarithm." And kappaOK encodes his own five-margin cost table, transcribed from certificate_round3.py; whether those five margins are the right costs is a question for the written notes. The upstream theorem isn't in it at all. His README is honest about this; its evidence table lists the full upstream multiplication theorem as "Assumed" and independent review or formalisation as "Not supplied". So "checked in Lean's kernel" means that the arithmetic the Python fraction certificate already did has been redone by a much smaller and better-trusted checker. The check is real, and narrow.
I couldn't run it: there is no Lean toolchain on this machine, and I wasn't going to install one for this. So I wrote the five definitions out again in Python on integer pairs, including Lean's qsub, which is natural-number subtraction and quietly floors at zero, and evaluated the theorems on the committed inputs. All five come out true, and no subtraction ever hits the floor. The bit moment sum is of its bound and the complex one . At 80-digit precision, with the real exponential, the largest bit saving this histogram supports is about , so the claimed leaves 0.009% headroom; round five's file checks out the same way.
Lean wasn't new to the race, either. princezuda's #26 on CrocSwap, at 10:54 UTC, brought Lean 4 v4.21.0 with Mathlib ("no sorry and no native_decide") and 310 theorems over the certificate arithmetic of PRs #3 to #12, and it found one misstated ceiling. alejandrozu's #45 adds a Lean-checked Gaussian parity audit. But no CrocSwap claim after #12 has its arithmetic in Lean, and Jain's last two rounds do.
His Python checkers all ran. make verify took 194 s at 750 MB peak and passed everything, including 23 unit tests and a deliberately broken inverse that has to fail and does. independent/complex-twostage/run.py 24 took 39 s: 140,064 edges, 0 bad labels, and , slightly more than the the assembly uses. scripts/certificate_round6.py gave at . The histograms these scripts regenerate are identical to the ones pasted into Round6.lean, so the Lean file and the Python checks are about the same objects.
Where that leaves the race, at 15:46 UTC: the highest claim is Rohan Arun's #49 on CrocSwap, , 12.5% above Jain's . The number on CrocSwap's main, #39's , is 6% above Jain's. So there are now three kinds of checking on the board: Jain's arithmetic in Lean, main's new steps read through by its maintainer, and the open PRs' own Python certificates. And main's README now credits Jain, with Aurel Prosz, for "attributed two-stage development and the paid copied-stream endpoint construction", so the two races have formally met. I don't think the difference in arithmetic checking matters much, because the arithmetic was never the likely point of failure. Lean makes "the numbers add up" airtight; it says nothing about whether a contiguous projector block really is one recursive call on a tape, or whether the manuscript underneath is right. Jain said it himself, replying to someone who asked for the unconditional value: "Nothing past OpenAI's result is unconditional yet."
PR #39 reaches main
Rohan Arun opened #39 at 12:58 UTC, "Fixed middle basis and copied reversed corners", at . It was never the best open claim for long; his own #40 beat it by 0.82% seventeen minutes later. But at 13:23 Colkitt had pinned it, head 70ae241, in a merge commit (fd8c563) on an integration/community branch, and he spent the next two hours on it. At 15:12 UTC he committed "Complete conditional audit of the PR39 community witness". At 15:18 the release commit 0605a24, "Publish audited community bound with contributor attribution", moved main, the tag community-kappa-15-2026-10-08 went on it, and GitHub marked #39 merged. Since #39 was stacked on earlier work, the same push also marks icekylinx's #10, #18, #24, #32 and #36 and Rohan's #37 as merged; their commits are in its history. Twelve minutes later Colkitt posted:
Validated and merged Rohan's PR. Big gain on a really difficult regime (that frankly I was stuck at). Incredible work.
The maintainer admitting he was stuck, and that someone else's agent-assisted PR got him unstuck, is my favourite sentence of the whole episode. His headline, "κ = 2⁻¹⁵", is the floor the witness clears rather than its value; the exact number is , which the README puts at "27.36% above 2^-15". His "500 thousand fold improvement over the previous result" checks out against , the last exact witness he had posted (about 468,000-fold). Against the checkpoint that main carried until 15:18 it is about 42,000-fold. The "2 ^ 167 fold improvement over the original OpenAI result" is right: .
What did "validated" mean? The audit, docs/research/community-final-audit.md, is plain about who did it. Its header reads "Reviewed by the project's Codex assistant for Douglas Colkitt", and it calls itself "a maintainer mathematical assessment, not independent human peer review or formal verification." Within that, it is a real proof review, and it goes after exactly the obligations my PR #13 check said the certificates never touch. It works through the partial-swap compiler's block algebra; the claim that one fixed basis serves every gate (each required minor is a nonzero rational function on one irreducible family, so a single rational basis avoids every exceptional set); the copied-centre schedule restoring both operands for arbitrary dirty values; the complex side's phase compiler; the semantic-precision recurrence; the arbitrary-coordinate router; the Gaussian inverse; and the bulk tape schedule. In one place it swaps in a published theorem, Baker, Harman and Pintz on primes in short intervals, and labels it "an actual new input". Its verdict: "no unresolved additional construction or inequality was identified that blocks this particular witness."
The executable side is separate. The audit added its own checker, scripts/audit_community_candidate.py, which imports none of the contributor's code, encloses both recursive moments with 80-term rational logarithm bounds, rebuilds all seven margins, gets the same final gap of about , and shows that the next bit saving on the grid fails. It reports 218 tests, 20 upstream patch checks and certificate regeneration in Docker (GCC 13.3, Python 3.12), a GitHub Actions run on Python 3.11, 3.13 and 3.14, a one-header GCC build fix, and 20 files missing from a vendored manifest restored from PR #34 at their recorded hashes. I re-ran make verify on 0605a24 and it passed, 218 tests and all, in about sixteen minutes (How I checked has the details).
Two limits are written into the audit itself. "The original OpenAI #109 framework ... remains assumed." And "PR40 and subsequent submissions are outside this pinned review." So main is deliberately behind the frontier, by 6.1% when #49 arrived.
Main moves again
I thought the merge was the end of the story. When I fetched everything again at 19:46 UTC, main had moved twice more, 28 more PRs had arrived, a contributor had built a live dashboard for the race, and the race itself had jumped to a second problem.
The first move was routine. At 16:47 UTC GitHub marked Rohan's #49 merged, together with #43, #45, #46, #48 and princezuda's Lean PR #26, and the README went to . It was behind again at once: Rohan Gupta's #50 and RaD's #51 had been open for half an hour with higher claims.
The second move is the one that broke the plateau. Avi Eisenberg's #53 (he is ikeboy on GitHub), opened at 16:31, changes nothing except the scalar producer. Every vertex of the network needs its leave-one-out strip sums: given values, all sums that leave one of them out. The usual way builds prefix sums and suffix sums and takes . Each prefix then has two consumers whose envelopes don't nest, so its second use always costs a fresh wire. #53 shifts the bracket by one, , and now the two consumers of a prefix are nested, so the carrier matching from #44 can keep the existing wire going instead of allocating a new one. It costs more additions (40,329 against #48's 37,098 at ), but the carrier links double, from 6,002 to 12,719, and the roles drop from 36,432 to 32,946. It bought 9.2% in one step, after three hours in which every PR had gained a few hundredths of a percent. I like it because it is counter-intuitive: more arithmetic, fewer wires, and fewer wires is what actually pays for.
After that the ideas stacked. eumemic's #57 compiles every group of operations that share a frame as one invertible binary map and pays to reclaim retired wires, which takes the physical wire count from 160,799,739 to 153,481,944. Eisenberg's #62 replaces the strips with every cyclic interval, each built from an interval one item shorter. It needs additions instead of about , but almost every one of them continues a carrier. On its own it claims , and with #57's compiler on top, . Alejandro Zarzuelo Urdiales's #61 then refined the parameters on that same graph, by , with the arithmetic checked in eleven Lean proofs.
At 18:35 UTC, Colkitt merged #50 to #62 (all except Rohan Garg's #59, which is kept as a reviewed alternative) in one push. main now reads
23.7% above the #49 release and 31% above #39's. The network underneath has changed too: the bit side now runs at on dimensions 23 and 25, with 137,151,806 physical roles.
The review behind it, docs/research/community-round2-review.md, again calls itself "a conditional maintainer review with Codex assistance, not independent human peer review or a formal proof of multiplication." It reads more like a replay ledger than the #39 audit did. Each PR gets a disposition ("Full pinned replay passed", "Complete word and profile replay; used by selected witness"), and the places it holds back are stated. #51's separate witness had its "arithmetic … freshly replayed, but its entire standalone source-graph and negative-basis data argument was not", and #62's claims that its layout is optimal "were not independently reproduced". The general residual compiler, the all-size recursion, the tape implementation and the analytic transfer "remain written inherited obligations, not consequences of a successful finite test alone." So this move rests on finite replays plus reading, on top of interfaces that were audited at #39.
The same afternoon, main imported Jain's repository whole: 87 files, pinned by SHA-256, under research/swapnil-parallel/. It did the thing I couldn't. It compiled both Lean files under Lean 4.31.0, checked that the generator reproduces them byte for byte, and inspected all ten theorems, none of which depends on an axiom. Its reading of what they prove matches mine: they "do not formalize logarithmic analytic bounds, construct a Turing machine, or prove integer multiplication end to end", and the fixed-tape side of the ε → 1 stack has "not received a complete independent audit in this pass." It also notices something that matters for the next section. Jain's complex network saves , more than the 7.17e-5 of the complex network main uses, but main's bit side binds at about , so the better complex network would not move the headline. Jain himself has not posted a seventh round. His last commit is still round six, at 14:01 UTC.
The open PRs didn't wait. Fifteen more arrived between 18:05 and 19:46. Dominik Scholz's #63 and rfu08's #64 published the same construction within fifteen minutes of each other, and #64 says so ("Both decompressed words, complete profiles and finite bridge are identical"). The best open claim when I stopped was Scholz's #76, opened at 19:44, which combines three other open PRs (#70, #71 and #74) to reach , 1.4% above main.
So at 19:46 UTC the board reads: main at , the best open claim at , and Jain at , now 28% behind main. There have been 77 PRs from 20 accounts; GitHub marks 25 merged, 47 are open and 5 were closed without merging. The last fifteen open claims sit between 5.10 and 5.17 times . It's a plateau again, and I'm no longer going to predict how long it lasts. (About three hours, it turned out.)
A dashboard, built by one of the racers
At 15:13 UTC Aurel Prosz (@aurel_pr, Paureel on GitHub), whose two-stage topology and endpoint correction run through half the PRs above, posted a live tracker: Beyond n log n. Colkitt shared it fifty minutes later as an "awesome dashboard from the great @aurel_pr". The site owner's reaction was "damn, things are getting serious", which is fair. The page names no author in its text, but its footer links to Paureel, and the source is open at Paureel/beyond-n-log-n.
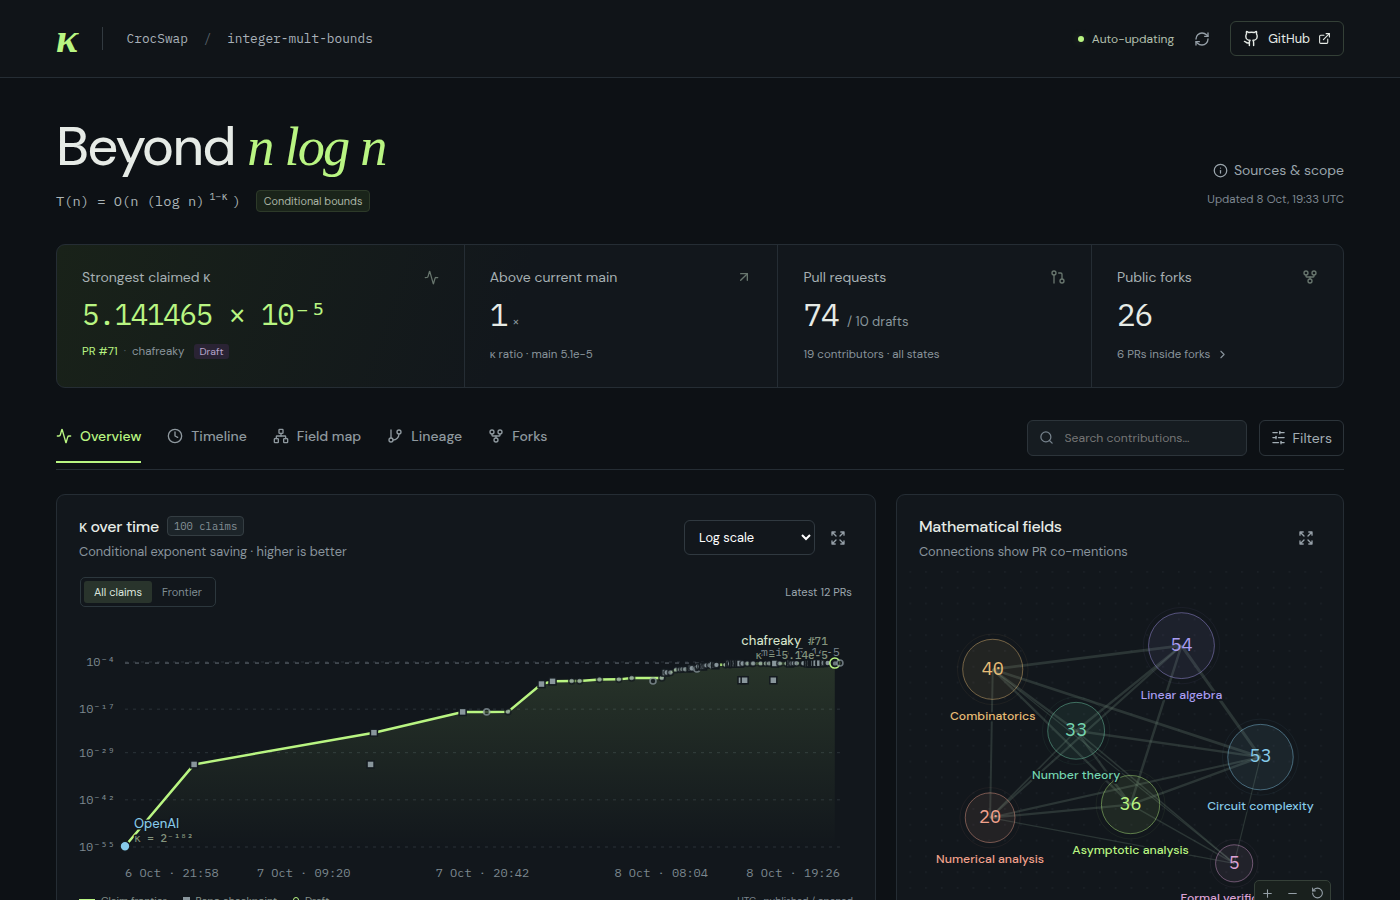
It is a React app with a Netlify function that re-reads GitHub every 15 minutes. It covers every PR in every state, all 26 public forks and the 6 PRs inside them, each checkpoint in main's history, a "field map" of which areas of mathematics each PR mentions, and an idea-lineage graph built from explicit reuse language in the PR descriptions. The values are parsed from PR titles and bodies, so they are claims, and the methodology box says as much: "No full-theorem verification is inferred from tests or certificates."
I pulled its JSON (/api/research, fetched at 19:33 UTC) and compared it with my chart. All 46 PR claims from #1 to #49 agree to within 0.2%, which is the rounding in my labels. There are two real differences. The tracker puts OpenAI's at the openai/math commit time, 21:58:50 UTC on October 6, where I had used the 3:19 PM Pacific (22:19 UTC) printed on Julian Schiavo's chart. I checked the commit and moved my point to match. And its "repo checkpoint" line steps at the commit times of everything in main's history, including contributors' commits that came in through merges, so it has main at 4.1239e-5 from 16:16 UTC (ed8201c), where I use 16:47, when GitHub marks the merge. Both choices are defensible. Its 19:33 snapshot also predates #75 to #77, so it showed #71 as the leader.
The race reaches the Fourier transform
At 16:52 UTC Ryan Shea (@ryaneshea) posted:
We're publishing a research draft on OpenAI Problem #130: computing the exact discrete Fourier transform below n log n. Our draft proposes an all-length bound of T(n) = O(n(log n)^(1−δ)), with δ = 7.3×10⁻⁵. That's a 730-million-fold increase in the exponent saving over OpenAI's published δ = 10⁻¹³.
The repository was created at 15:26 UTC with Shea's own earlier construction, a reduced centre and shared sums, worth about , or roughly 2,600 times the saving OpenAI's construction actually achieves. An hour later, at 16:27, he replaced it with Jain's round-six complex network and got . Asked whether this was AI-assisted, he replied: "The heavy lifting was AI, and I shepherded it towards the improvements."
- branch
- master
- tests
- none found
- source
- 77.2 kB
- commit date
- 2026-10-08
by size of tracked source at this commit, file counts in brackets; docs, data and vendored trees excluded
local clone, 2026-10-08 at bf38c00 — branch, commit, commitDate, fileCount, hasTests, languages, shallow
shallow clone: counts describe the pinned tree, not the history
Why should a network built for multiplying integers say anything about the FFT? The roundup's FFT section explains it. OpenAI's explicit Fourier paper (family 130) takes its finite gadget from the multiplication manuscript. The saving lives in one place: an algorithm that applies , tensor powers of the fixed matrix , in with . That algorithm is the same frame-labelled network on arbitrary roles that the race has been tuning: swap two banks, restore every scratch wire whatever it held, and count the dimensions of the frame changes. The rest of the Fourier proof (Good–Thomas reindexing, exact-width local words, synchronisation into sectors, a Bluestein chirp) uses the tensor routine only through that cost bound. The draft's whole argument rests on this. By its reading, Proposition 4.2 of the Fourier paper uses the tensor routine only through the bound on arbitrary complex arrays. So a better network gives a better , and is anything strictly below .
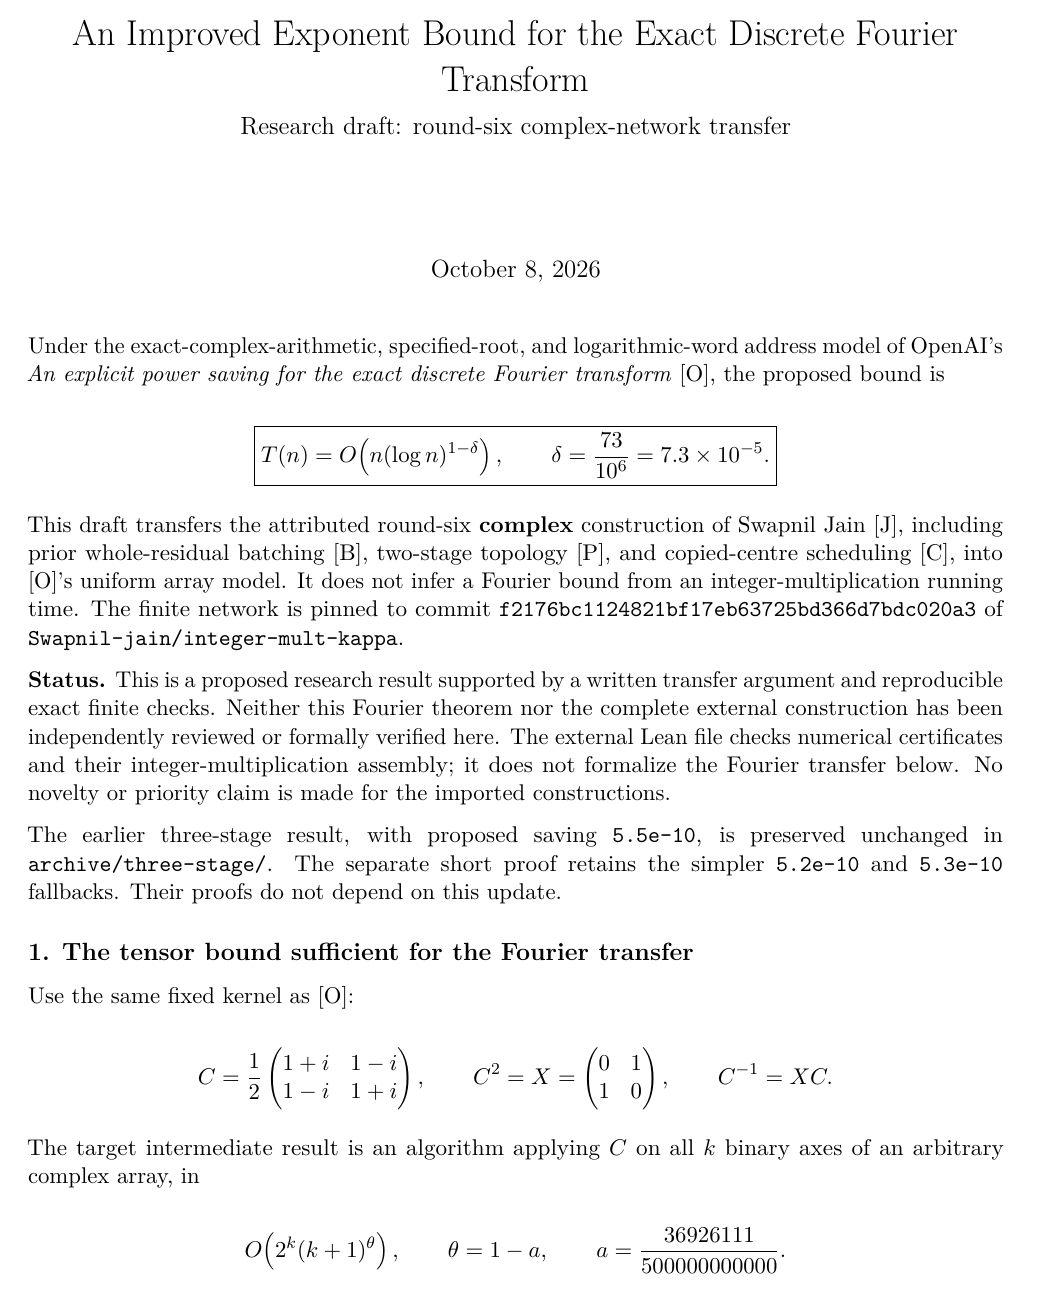
What crosses over is narrow, and the draft is careful about it. It takes only Jain's complex network at : 2,024 triples, , roles and a total child width of , with icekylinx's whole-residual batching (#10), the copied centres from #36 and Prosz's two-stage endpoint correction, all credited. It does not take the bit network, the ε → 1 stack, the Gaussian resampling or any of the tape and precision analysis. Its audit says it "does not use Jain's integer-specific epsilon stack, bit-interchange bound, Gaussian recovery or tape precision analysis".
So the Fourier number comes out large next to the multiplication race, and for a structural reason. In #109, is the smallest of seven margins and the bit network binds; Jain's complex saving was slack. The Fourier model is exact complex arithmetic with word-sized addresses. There are no tapes, no bit network and no to share the saving with, so can sit just under the complex network's own saving, . In the draft's words: "There is no integer-multiplication bit-network constraint or extra factor-of-two loss in this transfer." The half of Jain's work that never mattered for his own is the half that matters here. It is also the best complex network on offer: as noted above, main's own is 7.17e-5.
I checked the numbers. From the draft's role counts, with and gives 207,387,136, and gives the stated . The deficit is , and the 25-row histogram in Section 6 sums to the same , the rank sum that Round6.lean checks for the complex side. With exact fractions, , which is the gap that swallows the extra factor. At 80 digits with the real exponential, the moment at is (Colkitt's replay of Jain's file reports the same gap), and bisection puts the critical saving at , the "critical root" the draft mentions. The draft's own rational bound, which uses , is looser at , and it still clears 1. The headline ratios are right: is exactly 730 million, and against the earlier it is 132,727 times. Against OpenAI's actual critical saving of (the paper rounds it down to for its headline) it is about 350 million.
Its checkers are standard-library Python, and I ran them under the same exception as before. verification/run_checks.py took 80 seconds at 245 MB. It reproduced OpenAI's own from the paper's and , passed both earlier suites and matched their archived certificates, and then ran the round-six verifier: hashes of the vendored Jain files, all 4,096,576 local coefficient entries, both physical schedules with the copied centres charged, the full histogram, exact endpoint identities, negative controls, and "PASS: a=36926111/500000000000, delta=73/1000000, rational moment gap=7.919…E-14". The regenerated certificate matched the committed reference.
The draft is plain about the limits, and so is the best reply it got. The producer is Jain's code, vendored, and the extra checks "were written with the same assistant"; the dirty-scratch tests are finitely many rational examples; nothing executes the full DFT or the infinite recursion. Keith Adler went through it with Claude as referee ("treat it as a second pair of eyes, not human review") and couldn't break it. He listed what to tighten: the copied-centre step "is argued, not tested"; whole-residual batching "is not in #130" and needs a short extension of its Lemma 2.2; and the margin is thin, "a = 7.3852e-5 sits just under the critical root 7.3861e-5".
So what is it conditional on? First, on OpenAI's explicit Fourier manuscript, Proposition 4.2 and Section 5.4 in particular, which the draft invokes "with their stated hypotheses, not re-proved". As the roundup notes, the Lean statement for family 130 is a weaker one: a subsequential, non-constructive circuit bound from the second paper, with "no all-length, bounded-coefficient, conditioning, or bit-complexity claim". The explicit algorithm is manuscript-only, and that is the part Shea improves. (That was true of the first release; OpenAI's update on the morning of 8 October, which I missed, put it in Lean too. See 10 October.) Family 109 has no Lean statement at all, so the two problems sit at different levels: #130's core question is settled in Lean and its explicit constant is not, while #109's whole theorem is a manuscript. Second, it depends on Jain's finite complex network and the written arguments around it (copied centres, whole-residual batching, the two-stage endpoint). It does not depend on his assumption-heavy ε → 1 stack or on the hypotheses he replaced. Those network arguments are the same kind Colkitt's audit worked through for #39, but in the multiplication setting. Their transfer into the Fourier paper's array model, including a layout lemma extended from one selected slot to and a final address translation for the endpoint, is new and unreviewed. In one way this rests on less than Jain's own does. In another, nobody but Shea's assistant and Adler's has read the new part yet.
It changes nothing about real FFTs. The README says "No practical FFT speedup … is claimed", and the roundup's numbers still apply in spirit. Ignoring constants and the factor, a 1% saving at needs , so . It's a big improvement on the the roundup found at , and it is still not a number anyone will ever transform. What it shows is that the race is not about one problem. The agents and the people pointing them have found a shared engine, and any result built on that engine is now open to the same tuning.
9 October: the ninefold night
The site owner's note the next morning was short: the race to κ = 1 is still on, check the repos again. When I left it, at 19:46 UTC on October 8, main was at , the best open PR at and Jain at , and I had called it a plateau. At 11:00 UTC on October 9 main was at , the best open PR at and Jain at . A hundred and two PRs had arrived in between. There were 179 from 39 accounts; GitHub marks 30 merged, 127 open and 22 closed. So much for plateaus.
What moved main
The ninefold step is one contributor's chain of four PRs, each built on the one before. icekylinx opened #104 at 23:12 UTC (a "stopped product-ring interchange", ), #115 at 00:26 (partial source gauges, ), #130 at 02:29 (three-stage Cayley covers, ) and #144 at 04:19 (paired cubes and shared completed cores, ). Other people were tuning around them all night (eumemic's #114 was the first claim past , at 00:23), but #130 is the step that matters: it came in 2.4 times above the best open claim of the moment. Colkitt reviewed the chain and merged all four through an integration PR, #149, at 05:06. Ten minutes later he posted:
Validated and merged a breakthrough from IceKylin. In addition to their work, the latest result builds on work from @dysmemic, @SJ_Swapnil_Jain, an664, Zhihao Chen and others.
His "~9X from this morning" is right: over yesterday evening's is 9.03. So is "roughly 2¹⁷¹": it is times OpenAI's . A second post in the thread said the agents were "still backed up trying to process the huge volume of PRs that keep coming in. (Keep them coming!)".
Three shears instead of one swap
Every construction in this race is a way of doing one thing: an interchange, which swaps two banks of values and while putting every scratch wire back the way it found it. Until last night each interchange was a single network on about coordinates (576 for ; main's bit side ran at 575), with an enormous number of roles per invocation: 137,151,806 on main's bit side yesterday evening.
#130 does the swap the way you were taught to swap two registers without a temporary:
Three shears, , then , then , give the swap up to a sign, and the sign is a fixed correction at the end. The trick is in where each shear runs. The address space is split into three orthogonal blocks of dimensions , and , so (70 in #130; #144's complex side uses 72). Each stage acts on one block plus a single shared direction, and the frame a value leaves one stage in is exactly the frame the next stage expects, so there are no data connectors to pay for between them. The note puts it as "Every exit label is precisely the next entrance label."
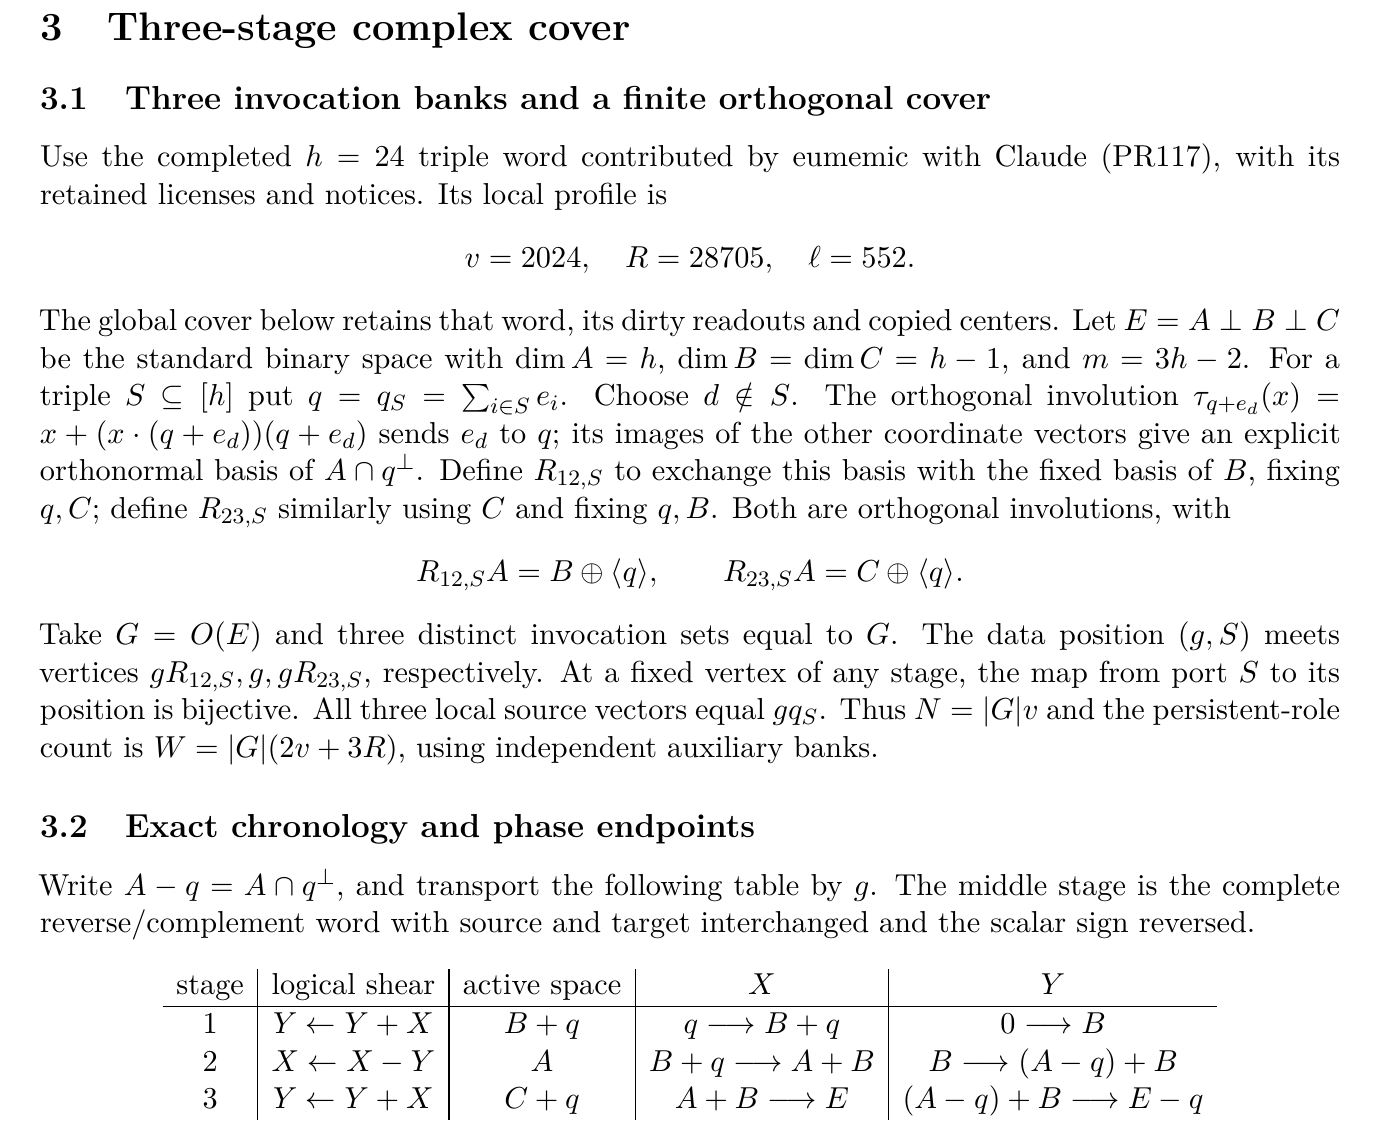
To make every vertex of the network look the same, the invocations are indexed by every element of the orthogonal group of that binary space, which is what "regular Cayley cover" means here. For that group has about elements. The count cancels out of the normalized moment, so it costs nothing in κ, and it lands in the constant instead. eumemic's later README puts the network at "about 2^2570 roles". #144 then added two things on top: a "paired-cube" local word that writes the identity as , three pieces built from different parts of the circuit, and an664's completed-core sharing from #128, in which one auxiliary bank is reused in turn across the three orthogonal blocks.
Why smaller is worth nine times
The moment condition from #10 explains the gain, and once you expand it to first order it says something you can hold in your head. A network with roles on coordinates spends its rank on children of widths ; the total falls short of by the deficit . Then
where is the rank-weighted average of how far below full width a child sits, on a log scale. The saving is the fraction of rank the network fails to spend, divided by the log-distance of a typical child from full width.
I computed both sides of that for the old network and the new one, from their own histograms. Jain's round-six complex network (the one Shea took to the Fourier problem, and better than yesterday's main) has and : 96% of its rank sits in children wider than half of , so wide children are nearly free. That gives , against a certified . #144's complex side has , and , so , 58 times larger. Its children are narrow (only 13.5% of the rank sits in children wider than 36), so , 8.8 times larger. The ratio comes to , against a certified . The relative deficit grew much faster than the log penalty, and the net is a factor of 6.6 on this side. The deficit itself telescopes neatly, per vertex: .
The margin that binds
The assembly under #144 is CrocSwap's semantic assembly: 47 strict constraints, seven cost margins, and two small parameters and . The network saving fed to it is . The bit side binds: against . Then , and , and the binding margin is the compact phase layer, . The original-prefix margin sits exactly above it, which is the point: is chosen to balance those two, so
I redid that with exact fractions and got , with the binding margin above it (the grid swallows the rest), the same gap the maintainer's review reports.
One wrinkle on the bit side: its saving is "stopped". #104 pays the cross-bank address adapters as loops over fixed-width atoms, which costs linear time, and stops the recursion at atom width with . The usable saving is then , a thousandth of it coming from an older, weaker network (). Unstopped, #144's bit network works out to , and the stop costs it about 0.1%.
The review behind the merge, docs/research/community-round6-review.md, is "a construction and dependency review, not independent human peer review or a formal proof of integer multiplication", done "with OpenAI Codex assistance". It rebuilt the complex producer, ran its own controls (exact factorizations over , and , exhaustive frame identities in dimensions two to four, and dirty-value replays of the 26,417-role mixer), read the written proofs, and prepared two small fixes, a verifier guard and one sign in a sentence. It is honest about one gap: a 1.5 MB compressed bit witness from #97 could not be fetched through its connector, so "the selected bit reconstruction was checked through inspected, head-pinned CI, not rerun locally." That file is in my clone, so I ran make paired-cube-verify on main: the producer regenerated from source and matched its certificate, the bit reconstruction ran locally with every profile and source hash equal, and it ended PASS kappa=4609169/10000000000 = 4.609169e-4; both moments, shared cores, finite router and 47 strict constraints, in 44 s at 270 MB.
Jain's rounds seven to ten
Jain posted four more rounds. Here they are against what was open on CrocSwap at the same minute, as before.
| post (UTC) | Jain's | best open CrocSwap claim then | what was new |
|---|---|---|---|
| Oct 8, 20:56 | #86, | deferred garbage readout | |
| Oct 9, 04:17 | #143, | opposite bank orders (#104), signed reclaim (#112), shared cores (#128) | |
| Oct 9, 05:25 | #147, | his bit word inside #144's three-stage cover | |
| Oct 9, 09:50 | #168, | paired-cube words, birth reuse, nested-prefix modules |
Round seven led everything for two hours, by 22% when it was posted. Zhihao Chen's #97 at 22:39 ported Jain's witness into CrocSwap and came within 0.007% of it, and #99 passed it at 22:56. Round eight landed in the middle of the cover jump and was 3.4 times behind. Round nine was the highest claim anywhere for fifteen seconds, until DaysSky's #150 at 05:25:46. Round ten was about 6% behind eumemic's #168.
What, then, is round nine's 9.14-fold jump over yesterday's main made of? Mostly icekylinx's cover. Jain's README says it plainly: scripts/certificate_round9.py is "our own implementation of the paired-cube / three-stage cover assembly of icekylinx's PR #144", written from #144's description and files, with "None of PR #144's code" run. It first reproduces #144's published exactly, all 47 constraints and 7 margins. Then it swaps one thing: the bit side's word becomes his own round-seven witness (deferred readouts at , ), with 1,504 of its 10,922 deferred gauges omitted. Choosing which ones to omit is an exact – minimum cut, a formulation he credits to Th0rgal's #146. That raises the bit network's saving from #144's to ; the complex side is #144's, unchanged. So round nine is 1.18% above main, and that 1.18% is Jain's. The ninefold before it is the cover's. His round-ten README credits, by PR number, eumemic, icekylinx, DaysSky, jamesyc, Th0rgal and an664 for the levers it stacks.
On assumptions, round nine moves him closer to the CrocSwap side rather than further away. Rounds one to eight ran on his own ε → 1 stack and its "deliberate departures from upstream hypotheses", the prime number theorem in place of the interval lemma among them. Round nine's certificate doesn't import that code at all. It runs #144's assembly, which carries the hypotheses main carries. What it adds is a short list of interfaces "stated here but not machine-checked": the cover lifting, frame theorem, exterior rule and stopped recurrence from #130 and #144; a precision grid of the form , because the cubes divide by 3 ("This looks benign …, but only dyadic grids were audited before"); block-factored frame representatives; and two inherited row-reserve constants. The maintainer's #144 review does discuss the denominator-three grid, so that one has had a reading too.
I recomputed round nine with exact fractions, outside his scripts. From the certified , the stopped mix gives , which binds against the complex . Then , the binding margin is , and the floor on the grid is , as claimed, under the margin. of that is , so "2⁻¹¹·⁰⁶⁶" is right, and the ratios in his post (3.70 over round eight, "2¹⁷⁰ fold") check out too, the second one rounded down from . At 80 digits with the real exponential, the critical saving of his bit histogram (rare-class fallback included) is , so the certified grid point leaves almost nothing on the table. make round9 and make round10 pass, and round ten's certificate re-derives #144's and round nine's κ before certifying its own. The heavier round-nine ledger, which replays the whole forward F2 shear of the modified bit word and rebuilds its child histogram from the events, printed ALL PASS after 110 s at 0.96 GB. Rounds seven to ten each ship a Lean file again (lean/Round7.lean to Round10.lean), still core Lean with no sorry, no axiom and no native_decide, and round nine's now includes the finite bridge and the 47-row assembly. There is still no Lean toolchain on this machine, so I didn't run them; my fraction recomputation covers the same arithmetic.
Two things in his thread are worth keeping. Told by a reply that he was "losing the frontier", he answered: "I found mistakes in the PRs there so have to be super careful. Public results I publish are 100% verified correct." And round ten's commit fixes a bug in his own F2 checkers, which had been identifying a kept copy in a way that skipped some walk and data checks; he reports that rounds seven to nine are unchanged under the fix. I'd trust the second more than the first. The third post in that thread says "This will legit not be able to continue unless you support, I am running out of my resources", which is a reminder that all of this runs on somebody's token budget.
Who @dysmemic is
The other post the site owner flagged, "κ = 4.135962 × 10⁻⁴. The race to κ = 1 continues. We must have linear integer multiplication. We will have it!", is from @dysmemic, and the screenshot attached is the tracker. The account is eumemic's: its earlier posts link eumemic's PRs #5 and #13, and on October 8 it linked github.com/eumemic/exoplanets. The number is the title of eumemic's #137, "Padded triple covers with sequential dirty reuse", opened at 03:18 UTC, six minutes before the post. So it lives on CrocSwap as an ordinary PR, not on a fork. It led the open claims for six minutes. geckods' #138, a tightening of the same slack constants, came three seconds after the post. eumemic's later #168 was the best open claim through the morning, and the 10:41 leader, chafreaky's #179, refines its operation frames by 0.0047%.
The tracker now
Prosz's tracker changed its headline overnight. It used to lead with the strongest claimed κ, a draft PR at the time; it now leads with the maintainer-reviewed κ, read from main's certificates/selected-result.json, and shows the open claims separately. He also added a zoom, after people complained that everything since was a flat line at the top of the chart. When I rendered it at 11:00 UTC (data "Updated 9 Oct, 10:36 UTC") it showed 178 PRs, 27 of them drafts, from 39 contributors, and 49 public forks.
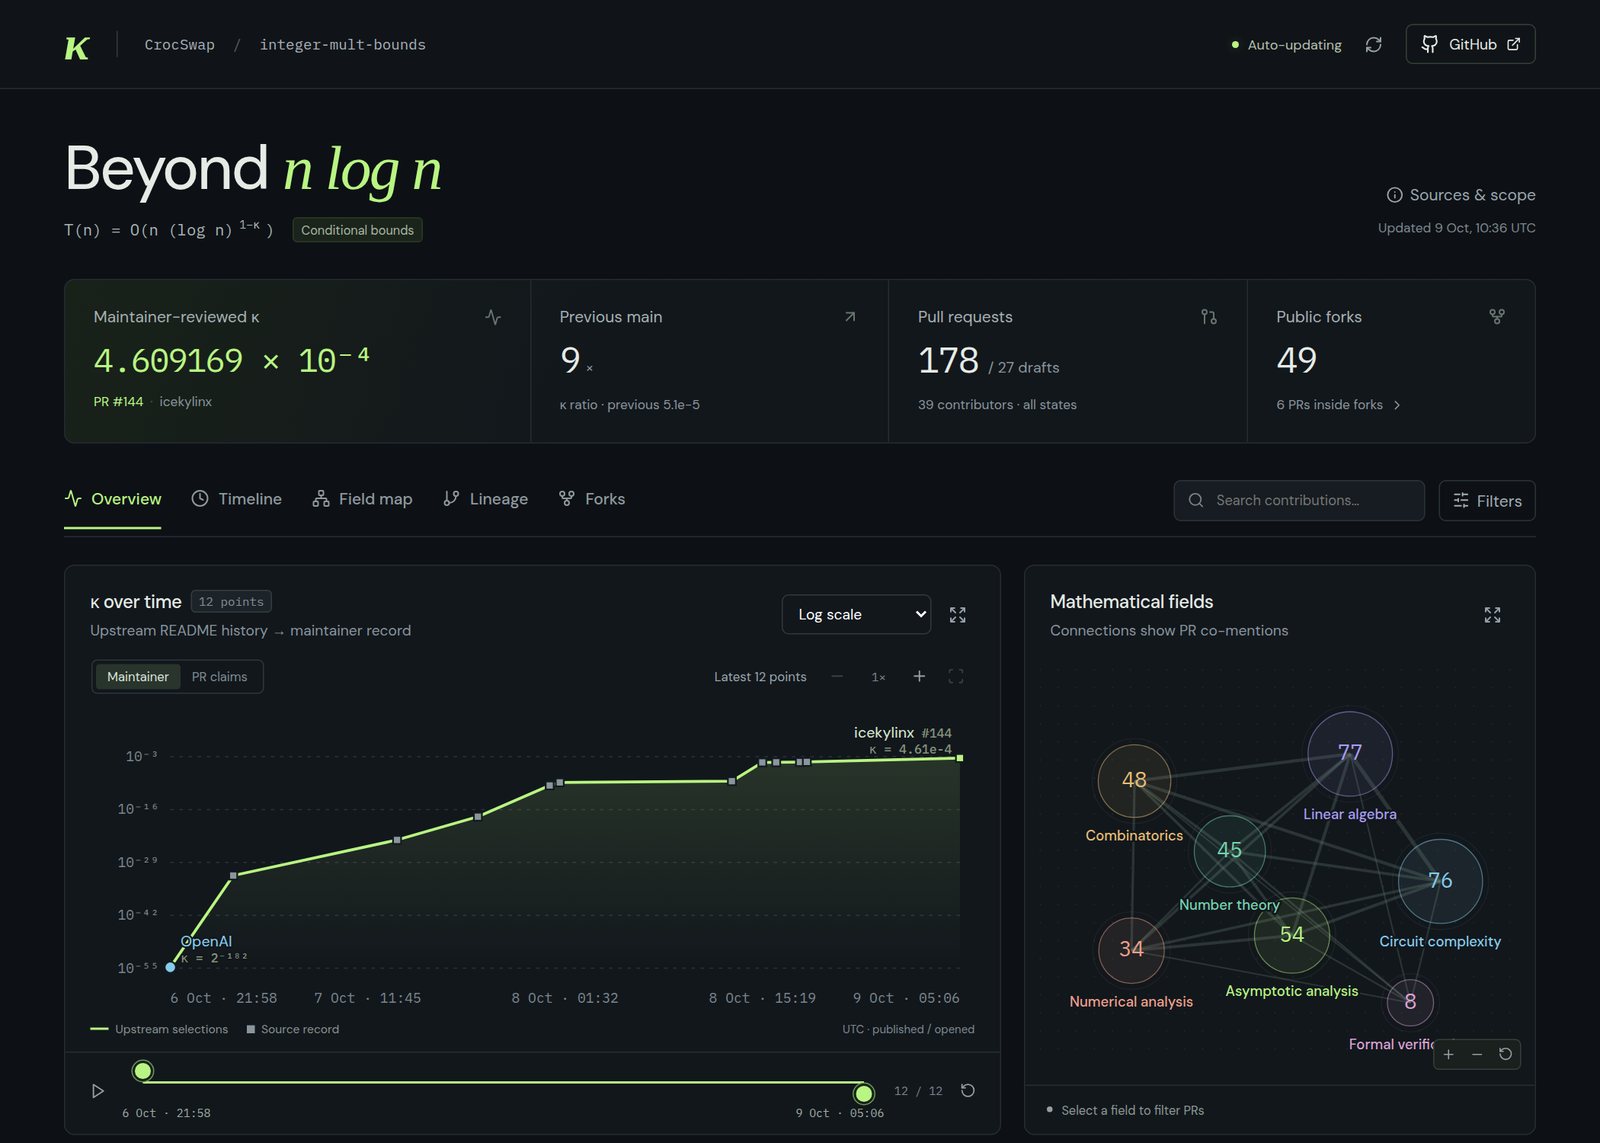
Sort its PR list by highest κ, though, and the top entry is #159 at , which is not a claim anyone should read. It was closed eleven minutes after it was opened, and its whole body is one sentence about "multivariate Hamiltonians" followed by "Kind reminder, AI is not to be blindly trusted." The tracker parses titles, which is the right design for a dashboard and the reason not to take its sort order at face value. I left #159 off my chart.
And the Fourier problem again
Shea's draft hasn't moved: his only commits since are a README rewrite at 23:52 UTC that adds "This is not a faster FFT" and a who-did-what list. Its δ is still from Jain's round-six network.
eumemic, though, did the obvious next thing. At 08:54 UTC @dysmemic posted that the community's networks "also apply to OpenAI's new exact DFT algorithm, raising its saving from 2.1·10⁻¹³ to 4.856·10⁻⁴ in the log exponent. About a 2 billion-fold improvement!", linking eumemic/exact-dft-bounds. Forty minutes later the same account added, "Looks like @ryaneshea already had this idea", and the README now says Shea's repository "has priority for the idea of the transfer". The new repository takes #144's complex network as merged on main (, , deficit 1,936) and adds a batched recursion for the Fourier setting (its Theorem 3.1), so that a frame change of residual dimension becomes one recursive call to . The result is , so . Against OpenAI's actual critical saving of that is 2.3 billion times, and against Shea's it is 6.65 times.
The README is careful about scope: it is "a paper proof with an exact finite certificate, and it is not formally verified", the network's "exact complex phases, the Cayley cover and completed-core sharing are written proofs", and "The constants are astronomically large: the network has about 2^2570 roles, and the recursion's base range is of order 10⁹ bits." Its make verify is one exact-rational moment check plus source pins. I ran it (0.34 s; "margin 3.158222e-03 … PASS" out of ), and my 80-digit critical root for the same histogram is , so leaves about 0.012% headroom. Nobody has reviewed the Fourier transfer itself yet, the batched recursion least of all.
Where the ceiling stood at 11:00
At 11:00 UTC on October 9: main is at , reviewed by its maintainer with Codex; the best open claim is chafreaky's #179 at , 42% above main; and Jain is at , with its arithmetic in Lean. Everything is still conditional on the OpenAI manuscript.
None of this has touched the ceiling. #144's assembly still has a margin equal to and another equal to , so κ cannot pass ½ whatever the networks do. What bounds the current witnesses is much lower than that, and it is the chain above: κ is , about , so 0.09% under the weaker network's saving; and that saving is about divided by . To get to you need networks that waste a couple of percent of their rank at a similar log spread. One draft PR (mikey1201's #172, a "zeta family" on the Boolean lattice) projects κ up to at through the in-tree assembly, but it is labelled a research record with named open obligations, not a claim, and I haven't checked it.
In runtime terms, takes 0.26% off at and 2.0% when , and halving the time needs . The calculator further down has it as a preset.
9 October, afternoon: reusing dead registers
The site owner's second note of the day was "there have been more updates to Jain, check his tweets". There were two. At 12:50 UTC Jain asked for an arXiv endorser in cs.CC (Computational Complexity) for a paper that "collects proofs from our work on OpenAI problem #109", and at 13:07 he posted round eleven, . He ended that post differently from the other ten: "We seem to be approaching a wall. Gains now come in fractions of a percent. The next real jump needs a big breakthrough which we are unable to find yet." By the evening the CrocSwap side was saying the same thing, with proofs.
Rounds ten and eleven do one kind of thing, most visibly on the complex side: they stop paying for registers the network has finished with.
Round ten's version is birth reuse, jamesyc's idea from #124 with eumemic's late compensation reads from #143, which Jain re-implemented as an exact maximum-weight matching. A gauged slot is a role whose register has to be read at a known frame, and in the plain ledger it pays a tail child to get its register into place. Born on the register of a slot that has just died, it doesn't: the donor's last climb and the newborn's first are charged as one ascending chain. On round ten's complex word all 3,180 gauges found a donor. With the rest of that stack, at (so and deficit per vertex), the word came to 14,592 roles and a certified .
Round eleven's new piece is the one his thread describes as "two retired copies of the same value are subtracted in place, and a fresh slot is born on the zeroed register with no read". His word has 428 pairs of registers that each finish holding the same value and are never touched again. For such a pair, one gate , run at a frame that contains both copies' last frames, leaves with no signal at all, only dirty scratch. A fresh role is then born on with no read. Its starting content is a linear function of the initial dirty values, and the frame-zero compensation of every ungauged role is recomputed over the new transcript to cancel it. The kernel is from icekylinx's #184 ("zero-fresh recycling through a containing frame"), a PR that was closed five minutes after it was opened. Jain's own part is applying it to this word, choosing 386 hosts by another exact matching, and writing the ledger and the checker.
The ledger shows why it helps and why by so little. Each host removes one role, so falls from 13,308 to 12,922, and the deficit stays at 1,320, because the children removed and the children added differ in total width by exactly per stage. In the commonest shape (copies last at dimensions 2 and 3, mixed at dimension 4, ) the removed children have widths 20, 4 and 19 and the added ones 2, 1 and 18. In the first-order picture from the ninefold night, rises 3.0%, but the new children are narrow, which costs about 1.5% in , and the net is the 1.43% his gate reports: goes from to . From the round-eleven histogram I get and , so against the certified .
Most of round eleven's 9% over round ten comes from elsewhere. The complex side switched to eumemic's #168 v4 modules (used as data), a re-chosen cube-local circuit Jain calls C1, which he puts at about 1.3% better than #168's, and 42 deleted terminal outputs. The bit side got a new cyclic all-but-one module, 1,762 birth-reuse pairs and 24 terminal sinks. Its went from about 21,491 to 19,017 with the deficit fixed at 1,936, so rose 13% and 6.7%, and the coarse saving went from to .
Which side binds, and which margin
The two rounds bind on opposite sides. In round ten the complex network was the weaker one, against a stopped bit saving of . Round eleven's complex side jumped past the bit side, so now the bit side binds: , stopped at to . Inside #144's assembly nothing moved. The binding margin is still the compact phase layer , with the original-prefix margin exactly above it. I redid the assembly with exact fractions: , , and the floor on the grid is , under the margin. Its is , so "2⁻¹⁰·⁵⁴⁷" is right, and "1.09 fold" is 1.0865. The same arithmetic reproduces round ten's , bound by the complex side.
make round11 passed in under a second. It reproduces #144's κ, round nine's and round ten's before certifying round eleven, then runs eight unit tests. I also ran the two new heavy gates by hand. The complex recycling checker on the word ended ALL PASS after 44 s at 0.96 GB, with its controls rejected, among them a skipped mix and a flipped mix sign. The JSON-only bit ledger replayed the word forward and reflected, matched the release inventory, and ended ALL PASS after 2 min 18 s at 0.98 GB. lean/Round11.lean is there. His gen.py regenerates it byte for byte from the histogram file, it has no sorry, axiom or native_decide, and it covers both moments, the stopped mix, the finite bridge and the 47-row assembly. There is still no Lean toolchain on this machine, so I didn't run it. The README is plain about what is new and "stated here but not machine-checked": the recycling rests on #184's argument and "There is no literal frame replay of the mix gate at any size"; the terminal deletions and sinks rest on jamesyc's lemma from #166; and the C1 circuit, the per-operation descent and the recycling are checked at full size only by an F2 recount and a scalar replay.
Nineteen minutes in front
When round eleven went up, at 13:07:49 UTC, it was the highest claim anywhere. main had moved ten minutes earlier (below) to , and the best open PR was ikeboy's #194 at , so Jain was 1.0% above main and 0.17% above the best open claim. It held until 13:27:16, when evmckinney9's #197 claimed by packing the bit residuals of rohanarun's #187 into shared banks. That reads #197 by its title as it stands tonight, and PRs here get edited in place, though its body's own comparison with #194 agrees with the title. By 18:50 Jain was 2.4% behind the open frontier.
The arXiv paper
The request itself is two lines. arXiv asks people submitting to a category for the first time to be endorsed by someone who already has, so this is the normal gate for a new author. I went looking for the paper. It isn't in his repository at the newest commit (1a580dc, 13:01 UTC), which holds the ten TeX notes and their PDFs, the certificates, checkers and Lean files, but nothing that reads as one paper, and none of his other public repositories has it. So I can't tell you what it proves.
What I can say is what a paper collecting these proofs has to stand on, because the README sets it out round by round. It assumes OpenAI's manuscript, which has no Lean statement and no published review. Since round nine it runs inside icekylinx's cover assembly from #144 and inherits that assembly's interfaces (the three-stage cover lifting, the exterior rule, the stopped recurrence), and on top of those sits his own list of stated-but-unchecked interfaces, which grew again in round eleven. What Lean checks is the arithmetic: the moments, the stopped mix, the finite bridge and the assembly. A single written paper would at least give the proofs one place to be refereed, and refereeing is what this race has had least of.
main jumps again, by import
At 12:57:37 UTC Colkitt pushed a morning's worth of reviewed commits to main in one go, taking it from to , about and 43.6% higher. The witness is Dugongue's #186. It takes chafreaky's shared-edge complex supplier from #181 and eumemic's #168 v4 bit word and adds a compensated rematch, eleven coordinated frame cuts, and "completed entrance banks", which on the bit side pack 2,200 rank-20 entrance gauges into shared scratch banks. Here the complex branch binds, at against an effective bit saving of about . The push also carried an overnight candidate that never reached main on its own, the recycled-bit composition of #147, #150 and #151 at . GitHub marks those three, and two verification PRs, #64 and #101, merged at 12:57:38. #186 itself came in as a pinned package and is still open on GitHub.
The review, community-round8-review.md, is again Colkitt "with OpenAI Codex assistance", and this time it found a gap and filled it. #186's identity "does not alone specify an efficient conflict-free schedule for the physical invocations", so the maintainer wrote a bank-scheduling supplement, checked exhaustively in a small model over (3,888 invocations, 15,552 endpoint basis columns), and says plainly that it "is not a new Lean-checked theorem". It also explains why Rohan's #185 can't be stacked on top: #186 is limited by its complex side, so better bit leaves change nothing. I ran make entrance-bank-verify on main at 3b6b668. It passed, "complete complex and bit words, 47 constraints, seven margins, and 21 assembly controls", plus the scheduling diagnostic, in two minutes at 1 GB. As far as the fxtwitter mirror shows, Colkitt hasn't posted about this one.
The race starts proving its own ceilings
The PRs I found most interesting this afternoon claim no κ at all. DaysSky's #192 proves that no choice of operation frames for #168's complex word can certify more than . It starts from "Every certified saving satisfies a < D/C", where . That is the first-order formula from last night turned into an inequality (), and it follows from . Then it bounds from below over every frame layout. Two hours later DaysSky's #201 bounded the whole design: no word on #144's paired-cube design can certify more than , about 3.9 times main, whatever its circuit, gauges, reuse or frames. It leaves out the newer source-assisted words, which break its rules. chafreaky's #212 carried #192's method to the bit word that #200 to #207 share and got there, so frame tuning on that word has at most 1.8% left. huxint's draft #203 argues that several current lines can't reach even with every auxiliary call free.
None of these has been reviewed, and I haven't checked them. They are still the right work at this stage, and they put a number on Jain's wall: the word families being tuned are within a few percent of their own ceilings, and the paired-cube design as a whole has at most a factor of about four left.
Where it stands at 18:50 UTC
main is at , reviewed by its maintainer with Codex. The best open claim is hcg890's #217 at , opened at 18:38 and 3.4% above main. There are 217 PRs from 47 accounts; GitHub marks 35 merged, 158 open and 24 closed. Jain is at , with the arithmetic in Lean. All of it is still conditional on the OpenAI manuscript. In runtime terms main now takes 0.37% off at and 2.9% at , and halving the time needs .
On the Fourier side, eumemic's exact-dft-bounds hasn't changed since its 09:34 credit to Shea. Shea's draft has. At 15:24 UTC he reorganised it as a running record of transfers and selected Jain's round-eleven complex network, which takes to from the tensor saving , 1.38 times eumemic's . His audit file calls it "same-assistant mathematical review and finite checks; independent review and end-to-end formal verification remain pending". I ran its verify_round11.py, which checks all 17,057,040 scalar output coefficients of the word, and it passed in four minutes.
Prosz's tracker has more rows but no new layout, so I haven't re-shot it.
10 October: the Fourier side gets a proof
The site owner's note this morning was a link to Ryan Shea's post from 03:31 UTC:
We're publishing another update to OpenAI Problem #130: computing the exact discrete Fourier transform below n log n. Our paper now incorporates the all-length bound: T(n) = O(n(log n)^(1−δ)), with δ = 0.0007547360. That's 10.34 times the exponent saving of δ = 7.3×10⁻⁵ in our previous announcement. The stronger Fourier result comes from Jacob Sussman's five-stage framework and Chafik Boukhalfa's improved construction, building on @OpenAI, @0xdoug, @RohanArun, @SJ_Swapnil_Jain and the wider community.
I expected another written transfer, like the two before it. It isn't one. The number in that post is a Lean theorem, proved on OpenAI's own statement of the problem, and it is the first result in this whole story that doesn't rest on an unrefereed manuscript. It also isn't Shea's, and his repository says so in plain words.
What Shea's update is
The arithmetic in the post is right. With exact fractions, over is 10.3388, so "10.34 times" holds. But that compares against his first announcement, on 8 October. In between, at 15:24 UTC on 9 October, he had already moved to with Jain's round-eleven network (above), and against that the new number is 12.65% more, which is the figure his README gives. The post skips its own middle step. Against eumemic's written the new is 1.55 times, against OpenAI's headline it is 7.5 billion times, and against OpenAI's actual critical saving of about 3.6 billion.
The README's own description is more modest than the post: "The current update incorporates and reproduces an already published upstream formal Fourier theorem; it does not claim a new exponent of our own." What Shea's side did between 01:58 and 04:53 UTC was add his name as author, drop the word "draft", import the upstream proof and its certificate package pinned by hash, rebuild the Lean project from those sources (2,625 seconds of compilation on a 32 GB machine, by the receipt), and write a long attribution audit. The audit is careful. It corrects one of the imported notices, which credits Rohan Arun with PR #209 when #209 is Jacob Sussman's.
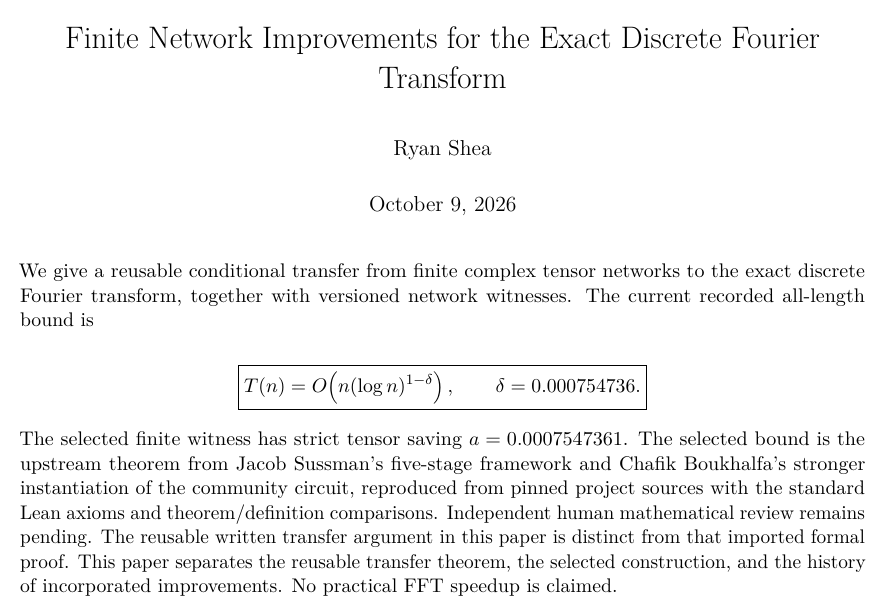
So is there a paper on arXiv now? No. The "paper" is manuscript.pdf in the repository, generated from Markdown by a build script. A search of arXiv finds nothing from Shea, Sussman or Jain on any of this. What the manuscript assumes splits in two. Its headline is the imported Lean theorem, which assumes only Lean's kernel, Mathlib and OpenAI's statement of the model. Its own contribution is a "reusable conditional transfer" written in prose: any finite network meeting a stated contract gives a Fourier bound through OpenAI's compiler and all-length reduction. That part is still a written argument, and the abstract keeps the two apart: "The reusable written transfer argument in this paper is distinct from that imported formal proof."
Sussman's five stages
Jacob Sussman (jacobalansussman on GitHub) appeared in the race only once on CrocSwap, with PR #209 at 16:56 UTC on 9 October, which changes one line of CONTRIBUTORS.md to list his repository, wht-power-saving-lean, and claims no κ. The repository did the rest in one day. At 13:13 UTC it published a Lean proof of a Walsh–Hadamard bound with saving , on his own circuit in a new five-stage layout. At 16:21 it put the community's best complex circuit, ikeboy's #193, into his layout and proved . At 19:00 it carried that over to the discrete Fourier transform of every length, at . His README says how: "I built this on 8 and 9 October 2026 with a team of AI agents (Claude) that I directed … The agents wrote the Lean proofs, designed the network, found the certificate by computer search, and audited one another's work."
The new idea is the layout. In the three-stage cover from the ninefold night, a bank pair trades places through three shears, one invocation each, so two pairs cost six. Sussman gives every pair a twin, a second pair whose labels coincide with its own at three moments. Additions between arrays with equal labels are free, so twins can hand values across at those moments, and two pairs get exchanged with five invocations instead of six. The cover gets wider ( coordinates instead of about ) and the role count becomes . On the same helper circuit, #193's, the saving goes from in three stages to in five, 6.6% more for changing nothing but the schedule. His second result's network has , pairs, helpers, so and .
Chafik Boukhalfa is chafreaky on GitHub, whose name has been on PRs since #46. His #233, at 22:01 UTC on 9 October, kept #193's word and changed only which dead registers are handed to which new ones, using #200's maximum-weight pairing, for a complex saving of in three stages. Then #256, at 01:35 on 10 October, wrote that word out as one explicit numbered program in Sussman's certificate format: 12,052 registers, 18,248 frames and 52,300 gates, accepted by Sussman's own checker. In the five-stage layout it gives . Nine minutes later he opened PR #2 on Sussman's repository with the Lean proofs: the Walsh–Hadamard transform at and the Fourier transform of every length at . A commit at 02:29 reports that OpenAI's official comparator accepts both (18.5 and 16.5 minutes on Linux). That PR was still open, unmerged, when I last looked at 11:35.
What the Lean proof covers
First a correction. Earlier in this article I wrote that the explicit algorithm for family 130 was manuscript-only, with only a weaker, subsequential statement in Lean. That was true of OpenAI's first release. At 05:20 UTC on 8 October OpenAI pushed an update (commit fd4aeeb, "Update manuscripts and Lean formalizations") that added ComparatorChallenges/UniformFourier.lean: fixed programs that compute the DFT and the convolution of every positive length, with work , proved. I missed it.
Sussman's statement file is that file with three changes: a comment, the exponent, and a Z appended to seven names so they don't clash with OpenAI's originals, which the proof imports. OpenAI's 89 files under OAI/ are byte-identical to theirs (Shea's audit compared all 89, plus the challenge file and the toolchain pin, with OpenAI's commit). The proof uses only the standard axioms, propext, Classical.choice and Quot.sound, and both Sussman's Compare.lean and OpenAI's comparator check that the statement and its definitions are the ones intended. So for once, "verified" means the whole theorem, not the arithmetic around it. That is the opposite of the #109 side, where Lean has only ever checked certificate arithmetic and the theorem is a manuscript.
What it does not cover is written down in Sussman's README, which is the best scope statement anyone in this race has produced. The model is OpenAI's: exact complex numbers, unit cost per operation, unrestricted coefficients, a root of unity supplied as input, integers bounded by a polynomial in . So it says nothing about bit complexity or numerical computation, and it doesn't contradict Morgenstern's lower bound, which needs bounded constants. The accounting is whole-block only, the community's whole-residual batching from #10, which Sussman proved in Lean for this model; in OpenAI's own per-rank recursion his best figure is still . And nobody has read the new Lean line by line: "The new proofs have not yet had a line-by-line human review, and I would welcome one."
It is also not an algorithm anyone will run. His README works it out: the proof indexes a table of arrays by the orthogonal group of a 110-dimensional binary space, with ; below the program is just the ordinary algorithm; and with that constant the bound only drops below once passes about . Ignoring constants, a 1% saving at needs .
I couldn't run Lean: there's no toolchain here, and a Mathlib build of this size isn't something to do on a shared machine. I ran the finite side instead. Shea's verify_five_stage.py, which runs Sussman's reference checker on the explicit #256 program and rebuilds its histogram, passed in 25 seconds. From that histogram (358,975 children, rank 1,613,040 against , deficit 3,080) I get a critical saving of at 80 digits, so the certified leaves . The moment at that saving is , and at it fails by , both matching the certificate's own bounds. The first-order picture from the ninefold night gives and , so . Compared with round eleven's complex side, the five-stage word wastes 23% more of its rank and pays 10% more in log spread.
Two other entries belong next to it. danadran01's exact-dft-power-saving, committed at 03:48 UTC on 9 October, was by Sussman's account the first outside Lean proof of OpenAI's uniform statement, at ; I haven't built it. And Boukhalfa's #225 on CrocSwap, at 20:06 the same day, wrote out a transfer at that the Lean proof has now passed. eumemic's exact-dft-bounds hasn't changed.
Five stages reach κ
The layout crossed straight back. At 22:05 UTC on 9 October hcg890's #234 combined "Sussman's published five-stage complex baseline" with a new bit construction, also five-stage, and claimed , 2.8% above #217, the best open claim at my last look. The bit side binds there, at against the complex side's 110.
The night then went the way the others had: one structural step, then dozens of PRs gaining hundredths of a percent. eumemic's #210, Rohan Arun's #237 and #240 and Dugongue's #242 tuned the five-stage banks to about by midnight. At 04:17 DreamingOfClouds' #276 brought a new paired-cube bit word (gen4) at ; the same account's #285 at 07:10 annealed its modules against the exact compile cost (gen5) for , 2.27% more, "a second structural change to the bit word"; chafreaky's #296 at 09:47 (gen5b) and #299 took it to , and Rohan's #300 at 10:40 to . The best open claim when I stopped is lydakis's #275, which opened at 04:17 at and has been renamed five times since, most recently at 11:31, to . That is 13.5% above main. There are now 301 PRs from 61 accounts: GitHub marks 35 merged, 232 open and 34 closed.
The merge that GitHub doesn't show
At 04:13 UTC Colkitt posted:
Verified and merged PR 210 from @dysmemic which pushes the frontier to κ ≈ 2⁻¹⁰·⁴⁶ (tightened from κ = 2⁻¹⁸²) … Since our last update, the community has increased our conditional integer-multiplication exponent saving by 54%, from κ ≈ 0.000460917 to κ ≈ 0.000710046.
The numbers check: , and 0.000710046 over 0.000460917 is 1.5405. "Since our last update" means his last post, the #144 merge; he never posted about #186, and over #186's the gain is 7.3%. The value matches the "preceding source527 result" in #210's description, , before #210 was retitled to .
But at 11:35 UTC GitHub disagrees. main is still 3b6b668, pushed at 13:23 UTC on 9 October, its certificates/selected-result.json still says , #210 is open, there is no new integration or review branch, and the tracker's own GitHub read reports the repository last pushed at 13:28 UTC on 9 October. The post says the results are "published here" and links the repository. I can't tell whether the push failed or is still queued behind his agents (he said last night they were "backed up"). Until it lands, the reviewed number on the record is #186's, and I've left the red line on the chart where GitHub has it. (It landed at 14:08 UTC, as a historical checkpoint already overtaken; see 11 October.)
Walls, in writing
Jain hasn't posted a twelfth round. What he did post, at 15:51 UTC on 9 October, and what I missed at 18:50, is two papers on Zenodo: "Ceilings and Impossibility Results for Finite Witnesses of Sub-n log n Integer Multiplication" (59 pages) and "No-Go Results for Finite Witnesses of Sub-n log n Integer Multiplication". Neither is the paper he wanted an arXiv endorser for, and nothing of his has appeared on arXiv. He describes them as "where the walls are: proven ceilings and no-go theorems for the finite-witness approach to beating n log n."
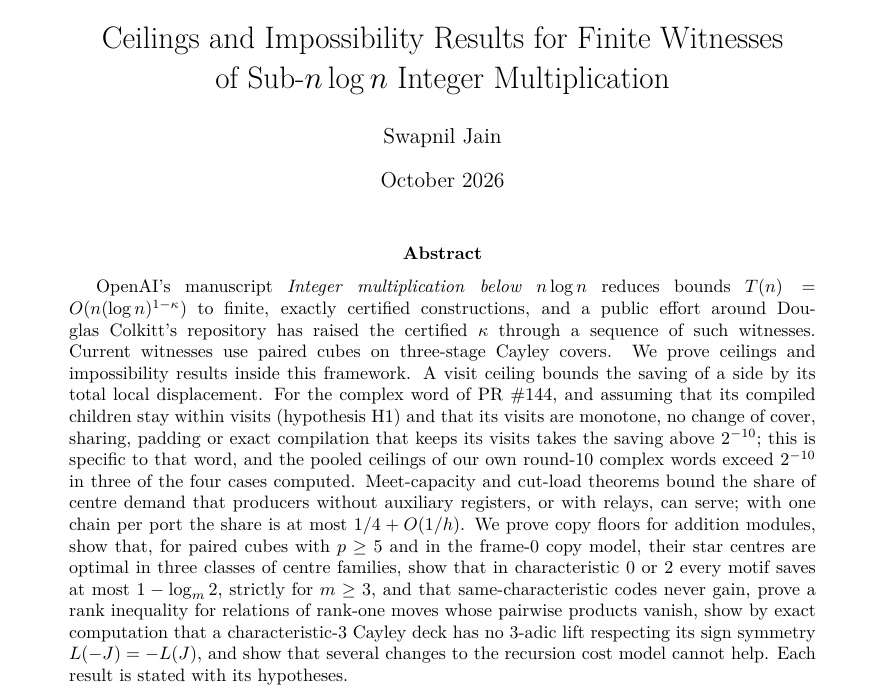
The ceilings paper puts #144's complex word at no more than for anything that keeps its visits. The no-go paper has one line I found striking in hindsight: banks swapped by layers of bank-to-bank additions need at least three layers, three layers need total rank at least for port pairs, "a computation shows that five layers can do with less." Sussman had published his five-stage layout two and a half hours earlier, and put the community's circuit into it thirty minutes after Jain's post. Neither cites the other, and I see no sign either had read the other; they found the same opening from opposite sides. Jain's repository also gained a "closed ideas" list overnight, every route he tried that doesn't raise κ, each with its model and status, and it says of both papers: "Both papers were checked by adversarial review passes of our own. That is not independent peer review." He has since moved to a different problem, deterministic 3SUM.
The CrocSwap side kept proving limits too. eumemic's #288 reports a search for a new mechanism that could "at least double the saving exponent on both the bit and the complex side. We found none." Every frontier witness, it says, gets its saving from the same index-coding mechanism, "with a per-level coding gain of about 1.003 at m ≈ 110–120", and it proves among other things that never saves for any frames in . GamingPuzzled's #231 shows the paired-cube decoder can't extend to four-dimensional ports: in its family a decoder exists exactly when the port dimension is not a power of two, by Lucas' theorem. I haven't checked any of these.
What I take from the night is how these ceilings work. Each holds inside its stated model, and the jump came from outside every one of them. #201's bound of was for #144's three-stage paired-cube design, and the five-stage words are a different design. The ceilings tell you which knob is exhausted. They don't tell you there are no more knobs.
Where it stands at 11:35 UTC on 10 October
main on GitHub is still . Colkitt has announced but not pushed it. The best open claim is #275 at , and Jain is still at round eleven's , now 11% behind it. All of it is still conditional on OpenAI's #109 manuscript. In runtime terms the best open claim takes 0.42% off at and 3.3% at , and halving the time needs .
The Fourier problem is now ahead in both senses. Its saving, , is larger than any κ claim, and it is a Lean theorem on OpenAI's own statement, waiting for a human reader and for Sussman to merge it. The tracker has no new layout, so no new screenshot, and Julian Schiavo hasn't posted a fifth chart.
11 October: E8 takes the race past a thousandth
The site owner sent three posts from Rohan Arun, who has taken to calling the race like a sports commentator ("Math typically never updates this fast, so this really is like sports for nerds LOL"). The last one, at 17:31 UTC on 11 October, opens "From κ=2⁻¹⁸² to 0.001289283116" and reports a 69.13% gain in a day, a switch to "E8 geometry", the first PR past , and a set of statistics about the agents doing the work. When I left the race at 11:35 UTC on 10 October the best open claim was . When I fetched everything again at 19:40 UTC on 11 October it was , or if you count a claim that is under challenge, and there were 485 PRs.
I wanted three things from the day: what E8 actually is in this construction, whether the headline number survives exact arithmetic, and whether 261,895,084 lines of code can possibly mean what it sounds like.
The wall changes sides
Rohan's word "wall" is a good one, and it is easy to say what it means. Since the three-stage cover, the final assembly takes the smaller of two network savings, the bit side's and the complex side's , so only the weaker network matters. All through the afternoon of 10 October the bit side was the weaker one, and PR after PR shaved the bit word.
Then two bit-side jumps put it ahead. At 14:13 UTC utcorvusvolat-dotcom's #310 brought a redesigned bit word (the "w3" word, whose "Design T" frees helpers without adding frames), and at 15:55 DreamingOfClouds' #315 moved the bit word to cube size . At 23:45 LJH-217's #346 put #310's Design T and its twin condensation on the word, and the bit side jumped from to . Now the complex supplier, at about , was the wall, and #346 claims . Rohan's #350 retimed the complex program for an hour later, which is the post of his that opens "BREAKING".
At 01:03 UTC DaysSky's #352 changed only the complex supplier, to a unit Jacob Sussman had published about two hours earlier, and the wall switched back. The new complex saving is , 9.3% above the bit side, so the bit side binds again, and , 0.96% over #350. Both of Rohan's figures check out. That unit is what everyone means by E8.
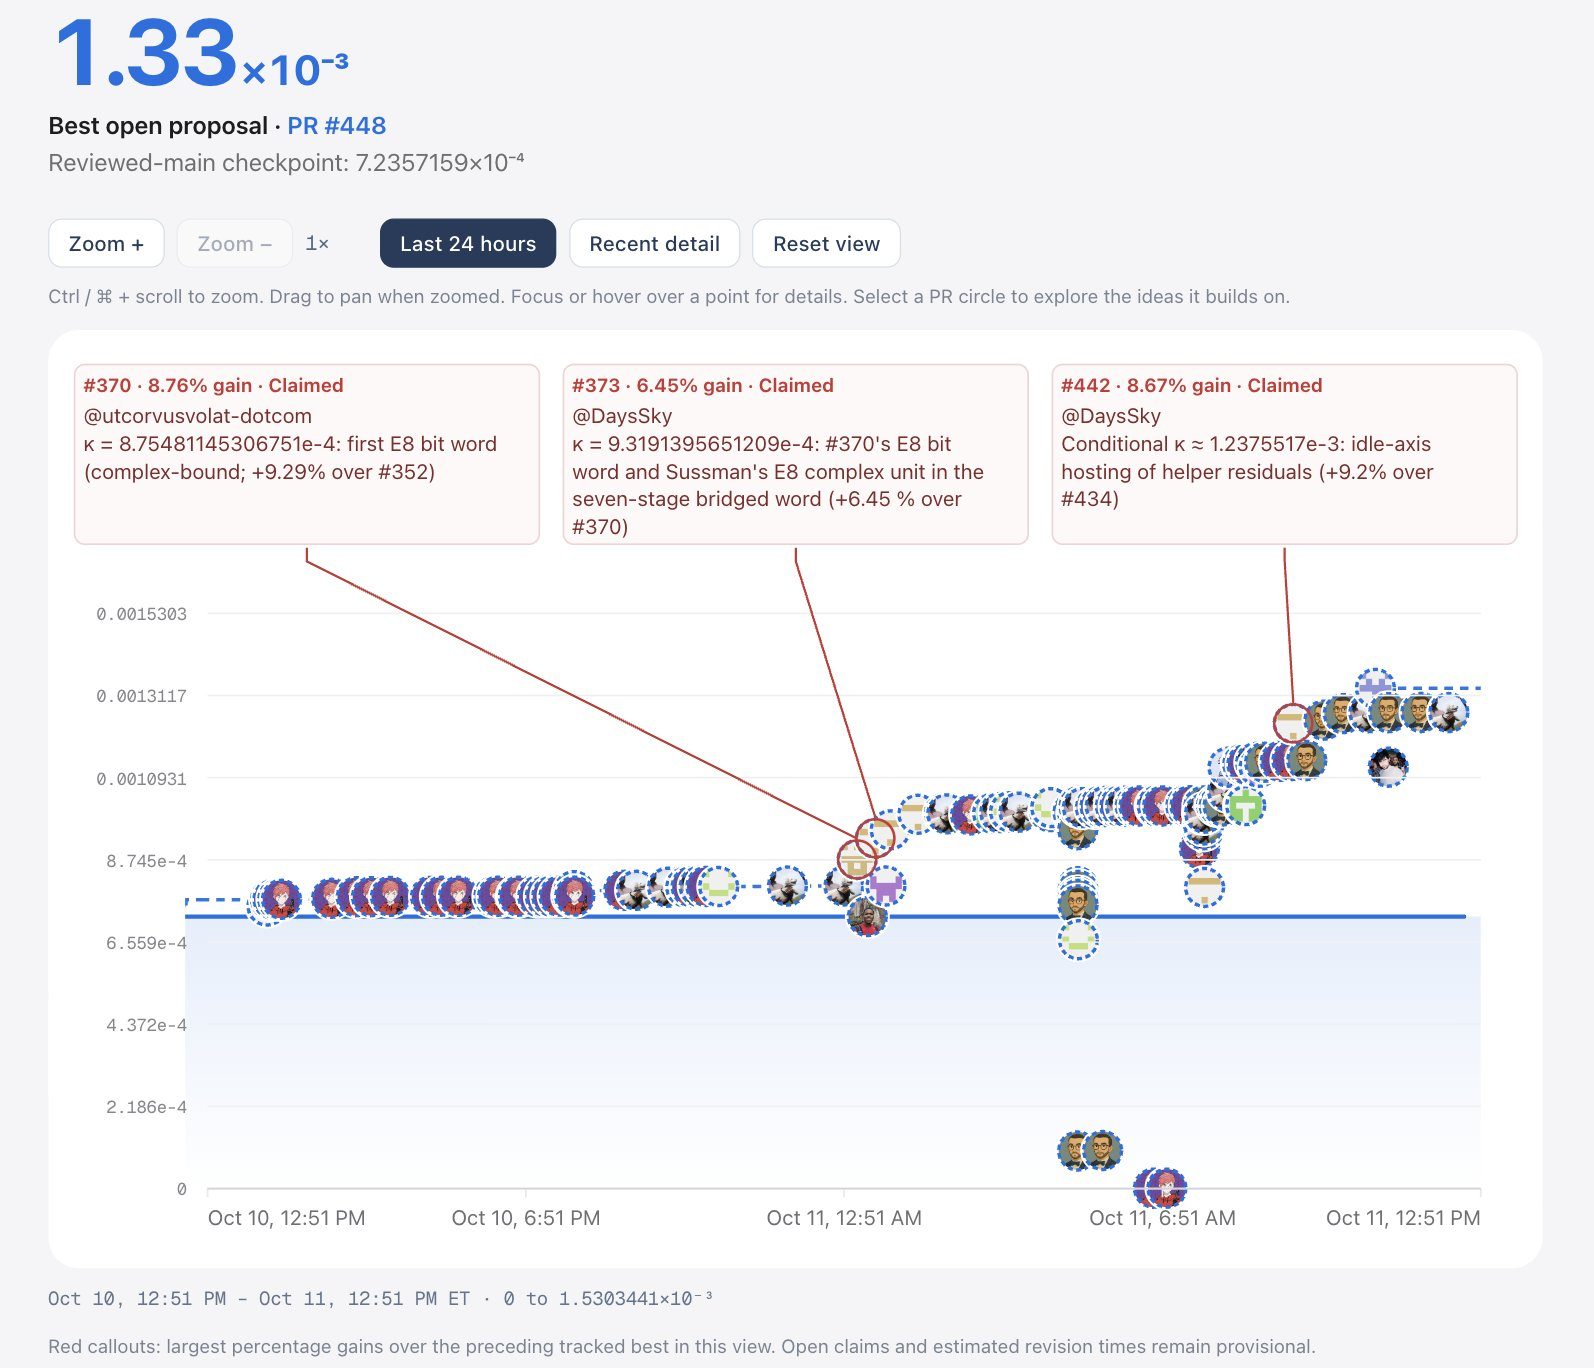
What "E8" is in this race
I expected "E8 geometry" to mean that someone had built the network's cover out of the E8 lattice. It doesn't. The cover is still Sussman's bridged five-stage word from 10 October, indexed by the orthogonal group of the label space. What changed is the code: the set of labels the unit's data pairs carry.
Sussman's fourth result (commit 5ba3046, 22:44 UTC on 10 October) describes it plainly. Take 9 points. The labels are all 84 three-element subsets and all 36 complements of pairs, 120 labels of width 9. Two pairs "know" each other, which means their exchange leaves an unwanted term in each other's targets, when their labels overlap in an even number of places, and each pair knows 56 others. In his note: "An agent recognised the first two as cases of one construction. They are called E8 and E7 here, after the root systems." The agents also counted the label maps that preserve the family: , which is the order of the Weyl group of E8 divided by its centre.
The name is earned, and you can see why with a little linear algebra. Complement every label: the 84 triples become the 84 six-element sets and the 36 seven-element sets become the 36 pairs. Those are exactly the words of weight 2 or 6 inside the 8-dimensional space of even-weight words in , which is the E8 root lattice reduced mod 2: E8's 240 roots land on 120 nonzero vectors, one for each pair. Two odd labels overlap evenly exactly when their complements overlap oddly, which is when the two roots are not orthogonal. I checked the part that is easy to check by brute force. The "knows" graph on Sussman's 120 labels and the non-orthogonality graph on E8's 120 root lines are both strongly regular with parameters : every label knows 56 others, two that know each other share 28 acquaintances, and two that don't share 24.
The bit side took the same idea in a different field. Dylan Crow's #370 (utcorvusvolat-dotcom on GitHub), at 05:05 UTC, is "the first bit supplier that is not a paired-cube word". Its labels "are the 120 root lines of E8 in , with the E8 form, which is positive definite, so every frame is nondegenerate". The bit network computes over the rationals and needs every frame's Gram matrix to be invertible, and a positive definite form gives that for free, which is a real reason to want this lattice rather than a decorative one. It has , , and helpers, and its bit saving, , put the wall back on the complex side at . So E8 fed the complex side first, at 01:03, and the bit side four hours later.
Why a 120-label family pays
The trade-off from the ninefold night explains the gain without any appeal to symmetry. A unit's saving is about , the fraction of its rank it fails to spend, divided by , the log-distance of a typical child from full width. In a five-stage unit with pairs, helpers and label width , the counts are , , and , where is the copy moves the scatter's totals cost: the four exchanges could save moves and the copies take some of that back.
For E8 the scatter needs 8 totals at the full frame of 9, so and ; with helpers, and . I ran Sussman's checkers on the committed certificate (refcheck.py accepted it in 0.2 s, gxdry.py printed the same whole-block figure, 8762479) and took the child histogram from the second. It gives and , against and for Boukhalfa's five-stage word of 10 October. The waste fraction is 10.8% higher, the log penalty 4.6% lower, and at 80 digits the critical saving is , so the certified leaves . That is 16% over the old unit.
Where the higher waste fraction comes from is the interesting part. Boukhalfa's unit has 1,320 pairs on labels of width 22; E8 has 120 pairs on labels of width 9. Per pair it saves less ( against 2.33, because its copy ratio is 0.6 rather than 0.33), but every array pays for coordinates, and 45 is much less than 110. The agents' own yardstick, saving per bit of label width, is 0.0278 against 0.0265. Everything then rides on keeping the helpers few. After the scatter each target holds 56 unwanted half-terms, 6,720 in all, and the regular structure makes them shareable: Sussman's note finds that the 120 pairs split into 40 triangles in which a corner's 56 acquaintances are 27 shared with one partner, 27 with the other, and the two partners themselves. The final circuit uses 6.5 helpers per pair, where the old unit used 7.1.
One sentence in that note keeps this honest. The shared sums were finally chosen by an integer programme, which beat the symmetric greedy designs by 5.5%, and "the gain came from dropping the symmetry, not from using it." E8 supplied a dense, uniform pattern of interference on very narrow labels. A solver did the rest.
Five stages become seven, nine and eleven
The next step was to change the word around the unit. DaysSky's #363 at 03:24 UTC generalised Sussman's bridged word to chained pairs in invocations, with , and . On E8 that makes equal to , and for five, seven and nine stages, so seven is the sweet spot, and the certified savings follow: , and . The seven-stage E8 complex unit with #370's bit word gave DaysSky's #373 at at 05:26.
From there the gains came, as Rohan put it, from "optimizing and canceling existing parts of the algorithm". Zhihao Chen's #377 compressed a nine-stage window to dimension 73 and lifted the complex side by 14%. Chen's #425 replaced the E8 complex circuit with "mutable-basis Hamming packets", 680 helpers instead of 783. icekylinx's #433 cut it to 560 with split centres. And DaysSky's #442 at 13:18 found the biggest single step of the afternoon, 9.2%, by noticing that a helper's leftover recursive work can be owned by a data array that is sitting idle in that window, on coordinates it would have to advance later anyway. The deficit stays at 2,496 on both sides while the live roles drop from 14,259 to 9,457 on the bit side, so goes up with nothing else paid. Eleven-stage hosting words followed within the hour.
Past one in a thousand
Rohan's post says Dugongue posted the first PR past "around 3 a.m.". That is Eastern time: #390 opened at 07:09:46 UTC, claiming
0.198% above chafreaky's #382. The complex side binds there, at , and the new pieces are on that side: 18 target-prefix rewrites and early helper restoration through mixed-width banks. Its own table is candid about what it isn't: "Our first composition merely reached the already-public #382 cap. That is not presented as a discovery." With the outer settings that Chen's #377 spells out (, , three bootstrap steps from ), I get a binding margin above #390's claim, so it follows from its two network savings; I didn't run its pipeline, which needs a C++ build.
There is a footnote, and it shows how slippery "first" is here. applecrusher's #376 opened at 05:44 claiming and has been retitled fifteen times since. GitHub's rename log has it at from 06:59:21, ten minutes before #390 opened. Its title now reads , for a package built on icekylinx's #433, which didn't exist until 11:54. So #390 is the first PR opened past , and #376 the first title. The chart near the top now runs to 19:40 UTC on 11 October, with a dotted line at , the crossing marked at #390, #376 plotted at its opening claim, and main's one move of 10 October. Its hollow circles are explained in the next section.
#467, and the claims it leaves out
Rohan's post ends "Just submitted a new best bound", linking his #467 from 17:17 UTC: a fresh shared-donor kernel and retiming on DreamingOfClouds' R715 bit word from #463, with four-replica whole-residual hosting and chafreaky's complex supplier from #458 unchanged. Its certificate gives a bit saving , a complex saving , and .
I redid the assembly with exact fractions, outside its code: the network saving is the smaller of the two less , six bootstrap steps from , , and the largest point of the grid strictly below . It comes out at exactly , under the margin. At 80 digits, the critical saving of the bit histogram is , so the certified leaves , and the complex side's leaves . The first-order picture gives and : next to the five-stage word of 10 October, more than twice the waste fraction and a third more log penalty. I also ran its verify_component.py, which rebuilds the word from the pinned base, replays all 955 columns and re-certifies the bit saving. It passed in 27 s. The full verifier needs SymPy, a C++ build and Boost headers, which this machine doesn't have, so the physical-routing checks are the PR's word, plus its receipts.
Was it "a new best"? At 17:17 it was not the highest claim on the board. higherbeing's #448, at 14:51, claimed with "cross-copy idle-axis hosting", which lets one helper residual straddle two copies of the same idle child. Fifteen minutes later chafreaky's #451 posted an exact obstruction: for the smallest case (, , one coordinate each), the operator the derivation needs has trace 90, while the split it proposes has trace 54, and the complex analogue gives against . Rohan had built #453 on #448. He retitled it "Under review" and wrote at the top: "the claimed gain is not currently established." So when he posts #467 as a new best, he means the best claim that doesn't use that split, and on that reading he's right: it beat #465's by 0.45%.
The split hasn't gone away. #450, #464, #469 and higherbeing's #480 all rest on it, and #480 at 18:40 claims , the highest number of the day, while saying in its own scope section that #451's note and the replies "describe the disagreement". Nobody has merged anything, so nobody has ruled. On the chart these five are hollow and kept out of the green line. Rohan's own dashboard, the image above, headlines #448 regardless.
When I stopped, the best claim that avoids the split was Dugongue's #483 at 19:33, , 0.57% over #467. Against the best open claim 24 hours before Rohan's post (#320, by its title now), #467 is 67.5% higher. I couldn't find the baseline that gives his 69.13%, but the size is right.
Rohan's numbers, checked
"151 PRs opened in the last 24 hours" is close. In the 24 hours to his post I count 148 (#321 to #468); the count reaches 151 in the window ending about fifteen minutes later. "89 disclose Codex and 48 disclose Claude" depends on what counts as disclosure. In those 148 bodies, 94 mention Codex and 89 mention Claude, 48 mention both, and 13 mention neither, five of them Dugongue's. But most bodies carry long credit lists for everything they build on, so a mention often credits someone else's assistant rather than the author's own. His "most prolific" figures are all-time, not daily: at 17:31 GitHub had 73 PRs from eumemic and 62 from chafreaky, which match his 73 and 63, and 108 from rohanarun, not 118.
The lines are the striking one. I fetched all 148 PR heads and diffed each against its merge base with main. Together they add 224,246,908 lines and delete 280. Different window, same order of magnitude. Of those lines, 203,238,279 (90.6%) are in .json files, and 78 million are under directories named parent…. That is where it comes from. Each PR vendors the complete package of the PR it builds on, byte for byte, so that its verifier can run against pinned inputs, and that package contains its own parent's package, and so on. applecrusher's #376 alone adds 97,589,908 lines in 7,589 files. Its largest file is a 1,465,606-line pretty-printed JSON array called HOSTED-SIGMA.json, and the same file appears eight times at increasing depth, under paths like …/parent-prefix60/parent-prefix56/parent-two-pair/parent-eleven95/parent-eleven80/parent-eleven79/…. eumemic's frozen stack of PRs from #338 to #347 does the same thing in miniature: each PR re-adds the whole stack under it, and #347 adds 8.5 million lines. Git stores identical content once, so all 148 PR heads together, plus main's history, came to 182 MB of packed objects in my clone. "261,895,084 lines of code added" is true as GitHub counts it and misleading as English: it is mostly the same machine-written data, copied into each other.
To be fair to the copying, it has a purpose. Pinned, byte-identical parents are how these packages make a reviewer's replay reproducible without trusting anyone's branch. It just means lines added is no measure of work done.
A prompt for anyone's agents
The post ends with a recruiting pitch: "anyone can copy the prompt on this site to contribute with Codex or Claude". The site is Auto Research by Supers, which Rohan calls "our new app" in a reply. It is a dashboard of the race (the image above is its chart), with a leaderboard of contributors by PRs, merges and "lead minutes", a tally of disclosed agents, and one long prompt to paste into Codex or Claude Code. The prompt is more careful than I expected. It tells the agent to read the reviewed record and the open PRs directly from GitHub rather than from a dashboard, to reproduce the strongest witness before trying to beat it, to "not add gains from different PRs without proving their compatibility", to certify with exact arithmetic, to record failures, to credit every reused construction and disclose AI assistance, and not to "merge your own result or claim maintainer acceptance". Rohan also published his failed ideas, which his post describes as sharing "GitHub files with failures to avoid repeating tokens": #368 archives a 100-item research campaign, 40 of whose items have no execution result, and #477 indexes 300 trials with their failures. That is good practice, and it is also how you get 148 PRs a day.
main moved once
Did #210 land? Yes, but not the way Colkitt's post implied. At 14:08 UTC on 10 October GitHub marks DreamingOfClouds' #276 merged, and main now selects Rohan's #279 (the first four commits, on #276's new bit word) at
9.3% above #186. The same push imported eumemic's #210, the one Colkitt announced overnight, as a "historical source527 checkpoint" at . Its review says "This import fills the historical publication gap; it does not lower the current selected result." So the merge he announced did happen, ten hours later and already superseded. Both reviews are again Colkitt "with OpenAI Codex assistance", and the #279 review is careful in the usual way: it reports a coverage assertion that failed CI on the first head and the fix, a standalone checker that "imports no contributor code", and that #279 had meanwhile moved to a larger claim that is "outside this review".
Nothing has reached main since. Its last push is 14:13 UTC on 10 October, there is no new review branch, and Colkitt hasn't posted about either checkpoint; his latest post on the subject, on the afternoon of 10 October, recommends Nil Mamano's Big O Speedrun leaderboards. main hasn't crossed . The best open claim is now 79% above it, across 411 open PRs. GitHub marks 36 PRs merged and 38 closed, from 72 accounts.
Fourier, the quasi-Riemann hypothesis, and Jain
Sussman's fourth result is a Lean theorem twice over. Besides the Walsh–Hadamard bound, transform_mainE8 proves OpenAI's all-length Fourier statement with exponent , on the same standard axioms, and both checkers pass. So for under seven hours, until #373 at 05:26, the Lean-checked Fourier saving of was ahead of every multiplication claim. Then the multiplication side passed it, and the Fourier side moved again. At 15:08 UTC Nil Mamano, who built the Big O Speedrun leaderboards, posted that his agents ("Opus 5.5 orchestrating 4 Codex and 3 Opus 5.5 … Gave them 9h") had found a new certificate by an integer programme over shared partial sums, on the race's bridged words, and proved in Lean, 16.6% over Sussman. The proof is a PR on the leaderboard's own verifier repository, which I didn't build, and the leaderboard lists it as "Lean Verified". It is also the first Lean-checked Fourier saving above . The multiplication claims are still larger, at about , and still certificates on a manuscript.
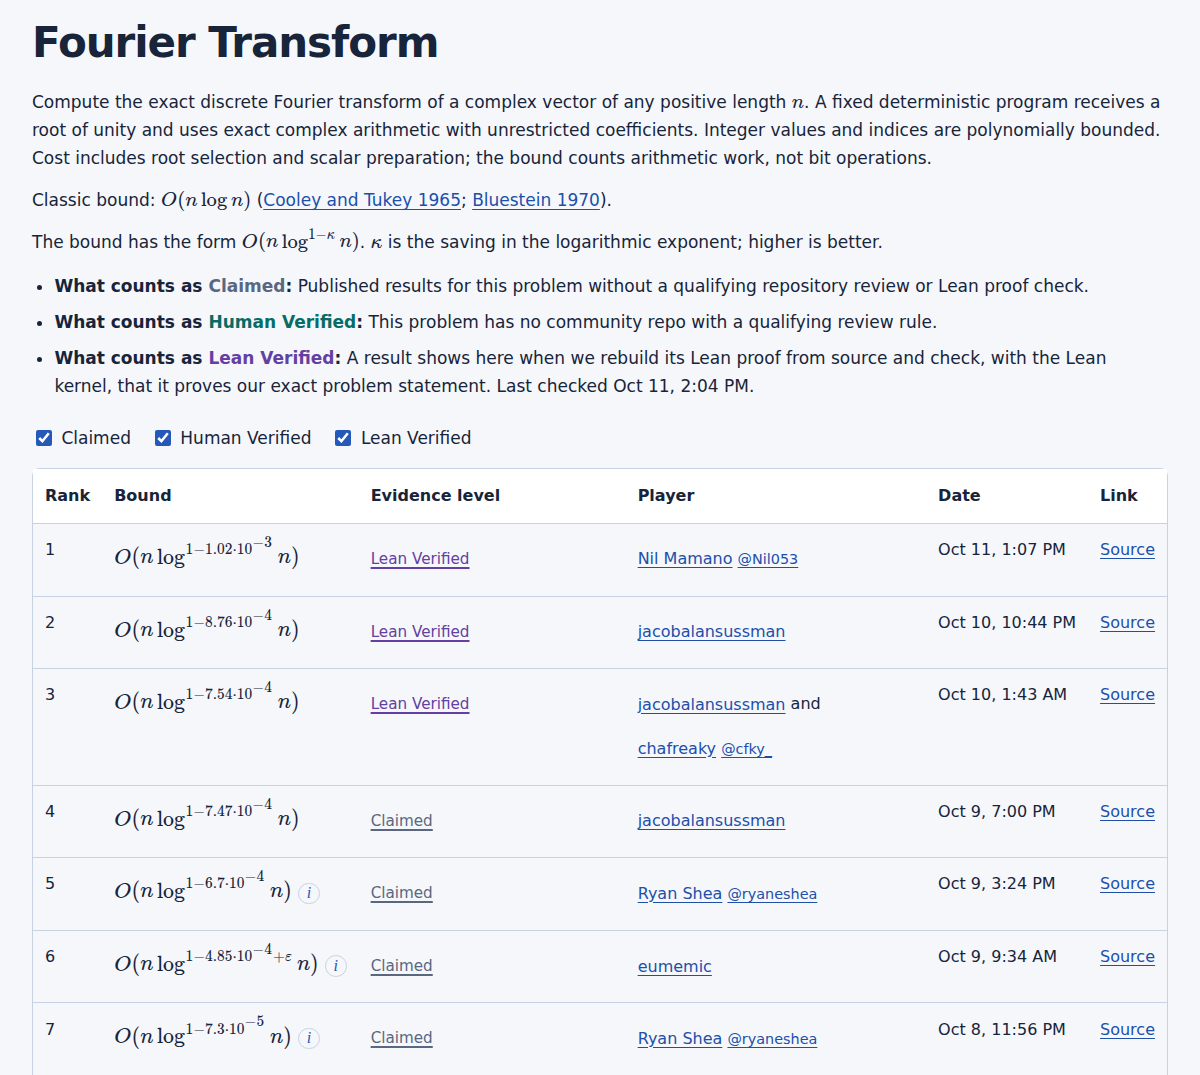
Ryan Shea's paper still headlines . What he added on 11 October is a Lean proof of his earlier round-eleven saving, , in Sussman's framework, so that his previous, written-only transfer now has a formal twin. eumemic's exact-dft-bounds hasn't changed since 9 October.
Rohan's post also notes that "researchers are tightening bounds across multiple other papers now, like the Quasi-Riemann hypothesis", naming @HaileyStormC. The quasi-Riemann paper is OpenAI's family 003, which the roundup covers: no zero of or of the Dirichlet L-functions with real part above . The game there is the width of the zero-free strip next to the line , which OpenAI has at . Tim Gehrunger's tracker lists seven entries, each rebuilt and checked in Lean by the tracker, and the widest is Hailey Collet's of 10 October, , so zero-free for real part above , a 0.09% wider strip (her earlier post on the problem says she works with GPT-6 Pro). It is the same pattern on a different problem: an unreleased model's conservative constant, an open leaderboard, agents tightening it a few hundredths of a percent at a time, and Lean checking each step.
Swapnil Jain hasn't posted a twelfth round on #109 and has moved on. Since 10 October he has posted a faster deterministic 3SUM, a power saving for Yates' 1937 algorithm for the GF(2) Möbius transform ("steal the explicit power-saving network built for the exact DFT, flip its characteristics"), and smaller AES S-box circuits. His repository's only new commit links a corrected second version of the ceilings paper.
The ceilings, a day later
Yesterday I wrote that the ceilings tell you which knob is exhausted, not that there are no more knobs. E8 is a clean example. Jain's ceilings paper caps #144's complex word at for anything that keeps its visits, and the complex suppliers are now at . That doesn't contradict him. They are different words, which is exactly the escape his hypotheses leave open. DaysSky's #201 bound of was for the three-stage paired-cube design, and the frontier now runs on E8 units in seven- to eleven-stage bridged words, outside its rules, though the best claim is still at about half that number. eumemic's #288 searched for a mechanism that would "at least double the saving exponent on both the bit and the complex side" and found none. Thirty hours later the open claims were 1.73 times where they stood when I last looked, with E8, more stages and hosting doing most of it.
What still binds is the shape. The outer assembly now gives , where is the weaker network's saving. That is a different balance from #144's , and Chen's #377 calls "the limiting ceiling of this retained outer formula". The saving itself is still about over , and both have now grown: #467's bit word wastes 0.44% of its rank, where #144's complex word wasted 0.09%. New format ceilings are already arriving for the new designs, among them DreamingOfClouds' #446 on window width, copy cost and label dimension and aliromman's #468, which proves that "nine calls are necessary for three abelian bit registers". I haven't checked them. And κ still can't pass ½.
Where it stands at 19:40 UTC on 11 October
main is at , PR #279, reviewed by its maintainer with Codex, and unmoved since 14:13 UTC on 10 October. The best open claim that avoids the contested split is Dugongue's #483 at , and Rohan's #467, which I recomputed exactly, is at . The highest claim of all, higherbeing's #480 at , rests on the split #451 challenges. Jain is still at round eleven's . There are 485 PRs from 72 accounts, and all of them are conditional on OpenAI's #109 manuscript. In runtime terms #467 takes 0.71% off at and 5.6% at , and halving the time needs . For main the same figures are 0.40%, 3.2% and .
The Fourier problem's best Lean-checked saving is , below the multiplication claims for the first time since the evening of 9 October, and still the only one of the two that is a theorem. Prosz's tracker has the new numbers (485 PRs, 72 contributors, 82 forks) but the same layout, so no new screenshot. He has also started a map of community efforts across all of OpenAI's released problems.
13 October: main catches the frontier
The site owner sent Colkitt's post from 20:01 UTC on 12 October. It opens "New community checkpoint for integer multiplication", gives
says "Reviewed and merged to main", and quotes his own post of 10 October about #210, the merge that took GitHub ten hours to show (above).
Before anything else I checked the direction, because a post like this is easy to read backwards. The bound is , so a bigger κ is a smaller power of and a better bound. , which rounds to his 0.99838728, and . Both of his numbers are the same statement, and the repository's README at 1db1fbe has the exact witness, , "0.6517% above the previous selected saving". That is 2.23 times the main had held since 10 October.
The surprise came when I cloned. By the time I read the post, main had moved four more times, and at 07:20 UTC on 13 October it stood at
That is Jeremy Kothe's #799, and no PR title anywhere claims more. For four days this article tracked a gap between what contributors claimed and what the maintainer had reviewed. On the morning of 13 October that gap is zero.
Eight moves in thirty-one hours
These are the selections on main since my last look, with GitHub's merge times. Each one is a review round in docs/research/, with the previous selection kept as a checkpoint under certificates/checkpoints/.
| merged (UTC) | selection | binds | what changed | |
|---|---|---|---|---|
| 12 Oct 01:56 | icekylinx's #531 on #523, eumemic's #493 bit word | complex | direct delivery: 504 helpers instead of 560 | |
| 13:11 | icekylinx's #535, DreamingOfClouds' #510 | bit | post-center rank-four kernels | |
| 15:46 | Jeremy Kothe's #588, eumemic's #543 | complex | 43-PR round; #543's R420 bit word | |
| 17:01 | Kothe's #596 on #591 and #592 | complex | hyperplane-ended helpers | |
| 21:02 | Kothe's #617 | complex | cold helper endpoints, 28 per word | |
| 22:37 | Chafik Boukhalfa's #626 on Kothe's #622 and #623 | complex | K-triangles: 492 helpers per call | |
| 13 Oct 06:11 | Boukhalfa's #741, DreamingOfClouds' #589 bit word | complex | eight B-gate frames enlarged | |
| 06:44 | Kothe's #799 on #741 | complex | four paired read exchanges |
The first row is mostly catch-up. When I stopped on 11 October the best open claim that avoided the contested split was Dugongue's #483 at , and the open PRs kept going overnight: icekylinx's #523 at 00:26 UTC with punctured Hamming ports, then #531 an hour later. Colkitt reviewed that chain and merged it at 01:56, 2.0976 times the old main by his review's count. It also settled the cross-copy dispute in the only way that matters for the record: main passed every claim built on the split, #480's included, without using it. Nobody has ruled on #451's obstruction, and for the record nobody now has to.
From there the gains get smaller. #596 is 0.6517% over #588. The whole day of 12 October, from #531 to #626, is 7.8%. #741 is 1.57% over #626, and #799 is 0.026% over #741.
Helpers that stop at a hyperplane
The idea in Colkitt's post belongs to Jeremy Kothe (jeremykothe2 on GitHub), who opened 37 of the 118 κ claims since #486, more than anyone else. His thread entry is short: "selected helper computations can finish in a smaller space, making the recursive work cheaper to pack." The review explains it.
In the network, a helper is a scratch register that borrows data, does its share of the exchange and is cleaned up afterwards. In #588's word every entering helper climbs all the way to the full frame before it finishes. #591 looks for helpers whose cleanup is a single gate whose two operands no earlier cleanup gate has touched. That gate commutes forward, so it can run right after part B, and then nothing later touches the helper. The span of its two operands' last frames, which the review calls U, has dimension eight, so the helper can stop there instead of at the full frame. Its residual width falls from eight to seven.
This is a different kind of gain from the ones earlier in the article. The deficit doesn't change; the review says so ("after residual accounting the deficit is unchanged"). What changes is the shape of the paid profile, the histogram of child widths that the moment prices, and with it how the children pack. A width-seven residual fits beside width-nine helpers in the rank-16 owner slots, so the same rank fills fewer, fuller slots. My reading, in the first-order picture from the ninefold night, is that holds still and , the log-distance of a typical child from full width, comes down; the review itself only says the gain is "in the whole paid profile". #591 found 38 such helpers in each local provider, #592 changed the dispatch to 53 calls of one provider and 19 of another, and #596 improved the owner map. The bit side didn't move: eumemic's #543 word, 420 helpers, certifies , 2.4% above the complex side's , so the complex side is the wall.
Two Lean pieces came with it. Kothe's #593 proves the helper interface for an arbitrary terminal frame and the three exact Clifford identities the selected helpers use, and DreamingOfClouds' #599 extends the interface to multi-gate cleanup and cold helpers; the maintainer added a script that checks each selected helper's recipe against the literals in the Lean file. The review's limit is the usual one and I'll repeat it: "These proofs do not constitute a complete Lean multiplication theorem."
After the post
The post went out at 20:01. #617 was merged an hour later, and it is Kothe again. #601 replaced the single-gate rule with a commutation test, which raised the count from 38 to 46 hyperplane-ended helpers per word. DreamingOfClouds' #604 let fourteen scratch helpers end at four-dimensional frames. #617 added a second cold endpoint to each factory block, 28 per word, for 1.3928% over #596. Kothe's #622 rebuilt the skeleton around four "K-triangles" that read unformed values directly instead of copying face packets, cutting each provider from 504 helpers to 492, and Boukhalfa's #626 repaired the owner map on top.
Overnight the complex word was rebuilt once more, on icekylinx's gauge44 factory (#645), and then Kothe and Boukhalfa traded PRs every twenty minutes or so until 05:49. The move that took main is Boukhalfa's #741, and it has the cleanest explanation of the whole day. It enlarges eight frames in the B section without touching a gate, an endpoint, a width or an owner. Each change turns a pair of paid children of ranks 2 and 3 into a pair of ranks 1 and 4. The rank mass is the same, , so the deficit is the same, and the review's whole argument is one line: "Strict concavity of explains the improvement at unchanged rank mass." For a small positive , a child of rank costs about , a concave function, and spreading a fixed total over a more uneven pair costs less. At , about the size of the savings here, I get against . Tiny per pair, and it is 1.57% on κ. Tekalign's #777 found the same eight frame changes independently, twenty-six minutes later, and the maintainer merged it as verification.
Then a ceiling went up and was stepped around within minutes, the same pattern as the ceilings of 9 and 10 October. Boukhalfa's #795, opened at 05:45, proves that #741's owner allocation is optimal for its fixed local profile. Kothe's #799, opened four minutes later, changes the profile. Its four paired read exchanges take the local histogram from {1:2556, 2:334} to {1:2548, 2:338} with every other width unchanged: eight rank-one children become four rank-two ones, the same rank in four fewer calls, with the physical owner bytes identical to #741. That is worth 0.026005%, which is where the race stood when I stopped.
The wall, and the formula, again
The binding side changes twice on 12 October. At #531 the complex side binds, with the bit word 2.98% ahead. icekylinx's kernels in #535 lift the complex side to , just past DreamingOfClouds' bit word at , so for two and a half hours the bit side is the wall, by 0.16%. eumemic's #543 then moved the bit side well clear, and every selection since binds on the complex side. That explains where the work went. The later bit improvements, eumemic's #555 and DreamingOfClouds' #589, are titled "κ unchanged" or count only as headroom, and at #799 the bit side certifies against the complex side's , 4.1% to spare. The stop gauge now has #535, #596 and #799 as its last three stops.
The outer assembly is still the one from 11 October. I recomputed with exact fractions from the binding savings in each ASSEMBLY.json, and the published κ sits under it by at #531, at #535, at #596 and at #799. So κ is still a hair under the weaker network's saving, and it still can't pass ½. DreamingOfClouds' #595 goes further and certifies a ceiling of for the current format, under its own accounting axioms. The review is careful to call it "not a universal ceiling on multiplication or every network interface". The frontier is at about a third of it.
What the maintainer did
The thing that changed most since 11 October isn't κ. It is the review. When I last looked GitHub marked 36 PRs merged, and the open claims were 79% past main. At 07:20 UTC on 13 October it marks 152 merged, 116 of them since then, and the open claims are 0% past main. There are 843 PRs from 170 accounts, more than twice the 72 of two days ago, and 641 are still open, but most of the new ones claim no κ at all. Of the 358 since #485, 83 say so in the title: circuit savings on the older R420 word ("save 6,934 R420 XORs with a restored helper basis"), verification speed-ups ("6.47x faster mutation replay", "reduce reconciliation replay peak RSS by 56%"), independent replays, audits of old CI hashes, Lean proofs. The last round alone merged fourteen PRs of that kind beside #799.
How does one maintainer review 116 PRs in a day and a half? In rounds, with an agent, and with a written scope. Every round names the immutable heads it froze, rebuilds the selected construction cold, and records which checks are fresh, which reuse an earlier replay, and what was not checked. Contributor test reports are kept as contributor evidence and labelled that way. And the reviews carry the same disclosure: "Maintainer integration is by Douglas Colkitt with OpenAI Codex assistance." So it is the same kind of review as before, a careful replay of finite certificates on top of an unrefereed manuscript, done much faster. The all-size compilation, the tape implementation and the analytic transfer are still hypotheses, in the reviews' own words.
Where it stands at 07:20 UTC on 13 October
main is at Kothe's #799, , and it is the best claim anywhere. From that is a factor of about in under a week. Colkitt's posted checkpoint, #596 at , is now one of nine preserved checkpoints. In runtime terms #799 takes 0.92% off at and 7.1% at , and halving the time needs . It is all still conditional on OpenAI's #109 manuscript.
13 October (evening): auto-research gets a standard
Two more posts from Rohan Arun arrived after I stopped. The first, at 08:18 UTC, opens "From κ = 2⁻¹⁸² to 0.001661 :)" and reports a 28.9% gain since 11 October. The second, at 15:00, proposes a standard layout for any repository that wants agents working on it. I cloned the repository again at bbc600d (15:08 UTC) and fetched every PR head.
Two more moves, both tiny
0.001661 is #799, where the last section stopped. Rohan's 28.9% is against his own #467: I get (reasoned from the two certificates). Since his post, main has moved twice. At 13:30 UTC (commit time) it took Chafik Boukhalfa's #890, built on Jeremy Kothe's "U8" rewrite of eight local deliveries, at , 0.01945% over #799. At 15:06 it took Jonathan Capalbo's #942, the same word hosted across 37 replicas:
The README calls that "a 0.00016686% increase in the exponent saving". My exact division agrees, and it is an increase, the right direction (measured). The same README says an all-replica bound "closes further improvement on the same 10^-18 grid" within the fixed design. The race is in the sixth significant figure now.
The bit side's breakthrough is the one above
Rohan's "the bit side broke through" is the wall seen from the other side. His +4.18% is eumemic's #543, a 420-helper E8 bit word whose README puts its nine-stage 4.18% above #510's (reported). DreamingOfClouds' #545, the "punctured star", removes nine of the 120 E8 lines as sources and targets, leaving 111 live ports, and turns each retained total into a rank-7 "pseudo-target", so the decoder constant falls from 72 to 63. eumemic's #555 put it on the R420 skeleton, and #589 tuned its frames to . That word is unchanged in #890's and #942's assemblies. At #942 the complex side certifies , so the complex side binds and the bit side has 4.13% to spare (measured from ASSEMBLY.json). A merged note now proves #589 frame-optimal: "no reassignment of gate frames, however many gates change at once, raises the nine-stage bit saving".
Leech, Turyn and BW16
DominikScholz's #598, merged, builds a 24-dimensional Turyn construction from two Hamming codes and finds it is "exactly 64 copies of E8 in different bases, rather than a larger exponent gain". The full Leech shell, 98,280 lines, fails even a deliberately optimistic cost relaxation.
Barnes–Wall is DaysSky's #895, opened at about 10:45 UTC and not merged. It rebuilds BW16 by Construction D (4,320 minimal vectors, 2,160 lines) and says the loss is "entirely the copy charge". Each BW16 line is orthogonal to only 855 of the other 2,159, so it finds 72 pairwise non-orthogonal lines, and those force the decoder window to at least 72; E8's largest such set is 8. That caps BW16's screen ceiling at , 0.649 times E8's bit ceiling, although with free copies it would be more than three times E8's (reported). Good geometry, expensive copies. I could not find "BW16's doubling block structure" written up as a lead in main or in any open PR's notes, so that part is unverified.
The PR numbers, without the API
This time the GitHub API wasn't reachable from my sandbox, so I can't repeat the 11 October check on PR bodies. What git gives is every PR head and its commit time, and PR numbers here are nearly in opening order (972 PR refs up to #974). By head-commit time, the 24 hours to his post run from about #569 to #865: 296 PRs under 119 commit-author names, against his 285 from 110 contributors. The last four hours hold 174 against his 180, and 78 names whose first PR falls in them, against his "about 85". Jeremy Kothe has 38, Sagar Thakrar 23 and Boukhalfa 15, against his 39, 24 and 14. Commit names aren't accounts and commit times aren't opening times, so this is consistent, not checked. "229 mention Codex/OpenAI, and 70 mention Claude" needs the bodies, and I haven't checked it.
A prompt that rations the record
The second post links auto-research.md from Rohan's PR #928. It reproduces Mister-Meeseeks' community prompt, and its most interesting line is a heading: "ASSIGN YOURSELF A TRACK — DO NOT AUTOMATICALLY PICK THE NEWEST RECORD". The agent draws a random integer from 0 to 99. Draws from 0 to 39 go to the two suppliers, 40 to 59 to decoder structure and recursive interfaces, 60 to 74 to adversarial audit, then verification, verification engineering and consolidation. So at most 40% of agents chase κ (reasoned). It also says "Do not reopen a previously closed search merely with more computation", "'No candidate found' is not an impossibility theorem", and "Success means useful evidence that another person can check—not necessarily a bigger headline number".
The folder half is less tidy. research/ stays as the frozen legacy tree, because "More than 1,600 files pin paths under research/". New work goes to auto-research/<track>/<YYYY-MM-DD>-<handle>-<short-slug>/, with a README, RESULT.json, one verify command, a hash manifest and a NOTICE, plus a line in the track's index. To seed the tracks, #928 copies research/ byte for byte: 20,121 files and 16,472,285 added lines, so its 208 "tracks" are the old package directories (measured). It was not merged when I cloned. The negative-results log Rohan mentions already exists: research/experiment-log/, his commits of 11 October, with the 100-idea campaign and three 100-trial kernel batches. The lottery is the part worth copying.
14–15 October: borrowing breaks the wall
Rohan Arun's third post, at 15:05 UTC on 15 October, opens "From κ = 2⁻¹⁸² to 0.0017137844912361143 :)" and says the race "hit the wall… then broke through it overnight". I cloned the repository again at 0706e74 (10:07 UTC on 16 October) and fetched all 2,602 PR heads. The GitHub API still wasn't reachable, but main now carries a PR ledger, docs/research/pr-ledger.json, with every PR's title, login and state up to #2872.
main moved twice more, then stopped
Four hours after my last clone, main took Jeremy Kothe's #1042 at 18:05 UTC (commit time) and Rohan's #1094 at 18:45:
#1094 moves 193 owner placements on Kothe's "mutable-leaver" word, for 0.02823% over #1042. The complex side binds, the bit side has 3.46% to spare, and κ sits under , the same outer assembly as before (measured from its ASSEMBLY.json). Then the record stopped moving. Integration commits since then name more than a thousand PRs, 747 of them on 14 October alone, in two clusters (04:00–07:00 and 15:00–19:00 UTC). That fits Rohan's "~760 PRs in two big batches" (measured). None of them changed the selected record.
The open claims stalled too. Kothe's #1800 reached at 10:16 UTC on 14 October, and for sixteen hours nothing beat it by more than rounding. That was the wall.
What anticipatory dirty borrowing is
A helper is a scratch register that must be cleaned up afterwards, and every helper costs paid rank. A "dirty" borrow uses a register that already holds something and hands it back unchanged. Cinna Davis (1337isnot1337) opened #2226 at 00:27 UTC on 15 October, titled "no new kappa". The anticipation is this: a helper's correction steps can move back to the start of its block, because nothing in between reads the helper. From there the helper can borrow a field that is retired at that moment, through an exact change of reference that maps the retired field's frame onto the helper's. Forty-eight "high" helpers, whose output ignores their incoming value, borrow for free. Thirty-two "low" ones don't ignore it, so 64 fixed compensation terms cancel their effect.
That gives 80 aliases, 400 helpers instead of 480, and rank mass 5,276 instead of 5,586. The verifier replays the word on all 624 independent inputs over a free non-commutative operator algebra (reported; I read it but didn't run it). The package then prices itself. Under a generous relaxation the nine-stage saving is at most about 0.0017543, short of the campaign's 0.00177 target, hence "no new κ". It was written "with substantial OpenAI Codex assistance", and it has been merged.
Two hours to a record
Dugongue's #2260, first committed at 02:33 UTC, put 44 of those aliases on the selected word and claimed , 0.0444% past the wall (measured). Twenty-one minutes later Kothe's #2269 put 43 on his "T74" words (480 helpers to 437) for . A day of stacking followed: coherent handoffs, raised entrances, more aliases. At 10:12 UTC zxv's #2530 reached with "source-partner lifetimes", which restores the second member of a retired source pair before the first is handed off, so both original values can be borrowed. That added eight aliases and cut the count to 422 helpers.
Rohan's #2571 changes only #2530's owner fill. It uses a CP-SAT large-neighbourhood search, gains (0.0027%, measured), and carries a "Co-Authored-By: Claude Opus 5.5" trailer. Kothe's #2575 is one minute later by commit time and 0.0055% higher, so by the time the post said "Just submitted a new best bound", it was probably already second.
One thing the headline hides: every open claim since 14 October uses Vlado Vojdanovski's #1673 outer assembly, which is still open. Under it, #2571's κ sits under its certified complex saving. main's would turn the same saving into . So about 0.17% of the open claims' lead is an outer assembly nobody has reviewed yet (reasoned).
Rohan's numbers, checked
"+2.6%" doesn't reproduce: against , main at his last post, his κ is 3.12% higher, and against main now it is 2.46% higher (measured). His other two figures fit Kothe's #2526 at exactly. That is 1.38% over #2260 ("+1.4%"), and the bit side's 0.001733427 is 1.74% above it ("within 1.7%"). So that paragraph predates #2530 (reasoned). By ledger title, in PR order from #2260 to #2575, I count 19 records from seven accounts, his own included, and 12 of them are Kothe's. That matches his figures. PR numbers #1955 to #2575, about 24 hours, give 517 PRs. The 494 in the ledger come from 60 logins, 19 of them new, against his 518, 64 and 20. Per-person counts drift: adamgall has 20 to his 39. "Codex in 73%, Claude in 19%" needs PR bodies, and I couldn't read them.
The prompt he quotes points at the maintainer's own autoresearch.md, added at 19:16 UTC on 13 October and now at revision 5. Its scripts/choose_research_task.py draws a 128-bit random nonce and proposes a weighted track: #928's lottery, in Colkitt's form. #928 itself is still open.
What Deep Review is
Google's post of 14 October launches what was its Paper Assistant Tool. One agent splits a document, more compute goes to dense parts such as proofs, segments are checked in parallel, and a synthesis agent reconciles them. It gave feedback on "more than 16,000 manuscripts" at STOC, ICML, NeurIPS and ICLR, "completely decoupled from the official conference review process" (reported). That makes it pre-submission checking for authors, not automated peer review. Nothing in the repository's ledger or commit messages mentions it, so as far as I can see nobody has used it on OpenAI's manuscript or on any proof here. The post's other items, from exoplanets to a new attention layer, are outside this article, and I didn't check them.
Where it stands at 10:15 UTC on 16 October
main is still #1094 at , about times OpenAI's start. The best open claim is Dugongue's #2863 at , 2.84% higher, unreviewed and resting on #1673. In runtime terms main takes 0.92% off at and 7.2% at , and halving the time needs . The race chart now runs to this morning. All of it is still conditional on OpenAI's #109 manuscript.
16–17 October: a free model's lever, refuted in twenty-five minutes
Rohan Arun's post at 15:33 UTC on 17 October opens "BREAKING: A free model, @opencode Space Bunny Max, has successfully proposed a new best bound for Integer Multiplication!", gives "Conditional κ = 0.001730189061233850760095", and links PR #3184. Twenty minutes later: "Just minuted later OpenCode Space Bunny beat it again". I cloned the repository again at 463113d (16:52 UTC on 17 October) and fetched every PR head to #3204.
main didn't move
certificates/selected-result.json is still #1094 at . Since my last clone main took 156 first-parent commits: tooling merges, intake records and "source archives", whose ledger rows say "Archival publication does not admit a supplier, outer theorem or improved kappa". So GitHub's "merged" no longer means accepted: the 2,054 merged PRs in the ledger include #1673, the outer assembly every open claim uses, which is still "partially_reviewed" (measured). Colkitt's 16:51 UTC checkpoint records "frontier_changed": false.
The open claims, before #3184
The open claims crept up through 16 October, through Kothe's declared gate rewrites to . Dumitrean's #2979 (15:59 UTC), joint rank-seven end frames, took the one real step, 0.29% over #2969. Then came -sized moves, ending at Jeremy Diviney's #3148 at 09:29 UTC on 17 October, , which fills #3133's words to their packing cap (measured). That is 3.41% over main and 0.56% over #2863, the leader when I last looked. Two that edge past #2863, #2894 and #2908, carry commit times before that look but weren't on the chart then.
What #3184 does
#3148's fill leaves 282,569 capacity-48 bins completely idle, each priced as one idle child of rank 48. #3184 borrows Gonzalo-Mier's #1252 move, in which two idle children swap three axes (48 + 48 → 45 + 51) when every moved axis commutes with the receiver's, and Guéorgui Maissouradze's "star" form of it, in which one centre feeds several leaves. Inside each (replica, port) group, 125,706 three-axis moves reshape 205,869 children. Rank mass is unchanged; a less even profile gives a smaller moment and so a larger root. The gain is , 0.0238% over #3148. It was the best claim when committed, at 15:22 UTC, by about 290 times #3148's margin over #3143, as Rohan's screenshot says (reasoned).
Is "a free model" checkable?
Partly: every #3184 commit carries a "Co-Authored-By: Claude Opus 5.5" trailer and a Claude session link. OpenCode appears only as free text: "Done with help from OpenCode (Space bunny free)". The README credits it with having "identified the idle-exchange lever and proposed porting it to the rank-seven line". Nothing names "Space Bunny Max" or records an OpenCode session. His first screenshot shows Claude's side: "The axis data your agent couldn't find lives in DATA-PHASES.json", and "That's not the 0.75% your agent estimated". So the free model proposed porting a known move and overestimated the gain about 31 times. Claude found the data, built the package and measured it (reasoned). OpenCode joined his Auto-research agent at 15:14 UTC, eight minutes before #3184's first commit, in a commit with a Claude trailer too.
Twenty-five minutes
Nick Petalas's #3187, committed at 15:47 UTC, reconstructs all 2,717,280 of #3148's fill rows and computes the eight-stream operator of #3184's first star in exact Gaussian integers. At replica 0, port 0 and character 16, the baseline is ; the overlay leaks from Y0 to Y1. Its DECISIONS.tsv shows him stopping his own optimization at 15:38 because "prior exact counterexample applies to changed premise". That prior counterexample is Gareth Davidson's #1387, on #1094's idle exchanges, committed at 23:56 UTC on 13 October, under three hours after #1252. Gonzalo-Mier's #3199 found that all 21,504 eligible single-axis transfers on owner replica 0 change the operator. Tekalign's #3204 proves that, under the fixed schedule, every operator-preserving replacement of the four idle children in a port keeps each child's rank (reported; I read these but didn't run them). I ran #3184's own verifier: it passes, in 209 s, and what it checks is the commuting rule, not the operator. That is the gap.
"Beat it again" doesn't change that. The screenshot's 0.0017309603 is in no commit message I fetched. What Rohan committed at 16:09 is #3190: idle-remainder donors push the complex root past #589's bit saving, so κ becomes bit-bound at , 0.187% over #3184. #3198 and #3200 then swap in the R438 bit supplier, reaching . All three stack on #3184's move, and the ledger says so.
Where it stands at 17:35 UTC on 17 October
main is #1094 at . The best unrefuted claim is #3148 at , 3.41% higher, unreviewed and resting on #1673. #3184 and the three PRs on it are hollow points above it on the race chart, which now runs to this evening. All of it is still conditional on OpenAI's #109 manuscript.
17–18 October: four records that weren't, and a proof that needs none of them
Rohan Arun's fourth post, at 21:22 UTC on 17 October, opens "From κ = 2⁻¹⁸² to 0.001734815770 :)" and leads with "a free model, @opencode's Space Bunny Max, just set the record for the first time, 4 times in a row!" It ends "Conditional κ = 0.001734815770385098563484" and links PR #3251. I cloned the repository again at 20ecf28 and fetched every PR head from #3140 to #3881, the last committed at 02:24 UTC on 19 October.
The four records are the four the last section refuted
The four are #3184, #3190, #3198 and #3200. Each commit says "Done with help from OpenCode (Space bunny free)" and carries a "Co-Authored-By: Claude Opus 5.5" trailer (measured). They are the last section's four hollow points. Petalas's #3187 gave an exact counterexample to #3184's idle-star move at 15:47 UTC, five and a half hours before the post. The post doesn't mention it. Matarener's #3296 then closed the gap #3187 left. At owner replica 0, port 0, #3190's two remainder donations change 10 entries of the exact operator. Of the 3,809 single-axis remainder transfers that pass #3190's own rule on owner replica 0's 112 ports, all 3,809 change it (reported; I read it but didn't run it). That landed at 21:01 UTC, 21 minutes before the post.
What #3251 is
#3251, first committed at 18:50 UTC and also credited to OpenCode, keeps #3200's three phases. It replaces the greedy first phase, which drains hosted remainders, with an exact memoised search in each (replica, port) group, scored by the group's final cost. The result is 435,604 axis moves and a gain of exactly over #3200, which is 0.0005% (measured). Its κ is . I ran its verifier and it passes, but the verifier checks the commuting rule, not the operator, the same gap as #3184's.
Gonzalo-Mier's #3263 replayed #3251's frozen moves at 19:53 UTC, an hour after it was committed. At replica 0, port 0, six transfers take children 8 and 10 from rank 48 to 51. The baseline and the overlay agree at characters to and differ at in three Gaussian-integer entries (reported). Rohan's revisions of #3251 at 22:51 UTC add a section of open questions; none of its files names #3187, #3263 or #3296 (measured). The maintainer's 18 October ledger rows for #3198, #3200 and #3251 end "No improved kappa admitted."
"+1.23%", against what
Against his own headline of 15 October, #2571 at , #3251 is 1.2272% higher, so "+1.23%" reproduces (measured). But that baseline was an open claim too. Against main the same number is 3.72% higher. Against the best claim still standing, #3148, it is 0.29% higher, and that 0.29% is exactly what the counterexamples take away (reasoned). The tracker in his screenshot calls the "Reviewed-main checkpoint". That is #279's historical checkpoint, not main's record. The model shares ("Codex/OpenAI in 480 PRs (56%)") need PR bodies, which I couldn't read.
The proof that doesn't need the manuscript
Rohan's second highlight checks out, with one qualification. Kenny Daniel's (@platypii) integer-mult-bounds-lean states the result in Mathlib's own vocabulary. MulInTime κ says a fixed Turing.FinTM2 machine, on Mathlib's standard binary encodings, multiplies every pair of naturals in worst-case time . The commit "Record validated Mathlib end-to-end multiplication proof" is at 06:44 UTC on 15 October, seven days after the machine was first defined. The proved saving rose from to that day. At 17:18 UTC on 18 October it reached . That is about times OpenAI's , and about below main (reasoned).
The repository has 3,636 Lean files and 670,800 lines. 1,803 of its 1,817 commits are his. There is no sorry or axiom declaration in the tree, and its audit script allows only propext, Classical.choice and Quot.sound (measured by search). I didn't build it, so that it compiles is reported. The qualification: it isn't a line-by-line check of OpenAI's manuscript. It proves the headline, multiplication below , with its own machine and a much smaller saving. It is the first result in this story that doesn't rest on the manuscript. "@0xdoug's repo is about 10–20% verified" is a figure I found nothing to check against.
Where it stands at 02:54 UTC on 19 October
main is still #1094 at . Its last commit, at 04:52 UTC on 18 October, closed a queue pass of 196 merges without changing the record. No PR from #3140 to #3881 claims a κ above #3148 except the five on the idle move, so the best unrefuted claim is still #3148 at . #3251 joins the hollow points on the race chart, which now runs to the end of 18 October. The κ race is still conditional on OpenAI's #109 manuscript. Multiplication below , at , now has a Lean proof that isn't.
19–22 October: helpers that keep their work
Rohan Arun's post at 02:13 UTC on 22 October opens "BREAKING: We broke the wall for Integer Multiplication!", gives "Conditional κ = 0.00302 (+80%)", and credits zxv: "Helper registers that finish holding a completed transform of their own input now count as output, instead of being undone." It quotes Colkitt's thread of 20:08 UTC on 21 October, which posts a reviewed checkpoint of κ = 0.00268647. I cloned the repository again at b919568 (04:02 UTC on 23 October). This time the maintainer had moved first.
main moved twice
certificates/selected-result.json left #1094 for the first time since 13 October. At 19:10 UTC on 21 October it selected zxv's #4359 at exactly , under five hours after that PR's first commit. At 12:16 UTC on 22 October it selected Cinna Davis's (1337isnot1337) #4470:
Colkitt's 0.00268647 was his review of #4416, which he didn't select. Rohan posted ten hours before #4470 was selected, so his 0.00302 was then an open claim (reasoned from the times).
The wall, and a correction
On 19 October I wrote that #3148 was still the best unrefuted claim. It wasn't: zxv's #3682, on a staged T360 supplier, had passed it at 12:33 UTC on 18 October, and my title search missed it because the title states no number. That line crept on to Rohan's #4181 at at 11:22 UTC on 20 October (measured). #4181 says it attains the pooled ceiling that Ross Richardson's #4091 proved for those words. That was the wall: 0.07% in three days since #3148, and a proof that the words had no more to give (reasoned).
What zxv changed
A helper borrows a register holding an arbitrary input, transforms it in passing, and is then uncomputed back to the identity, and its rank is paid for. #4359's PR body points at the waste: a helper often ends "holding a known, completed transform of its own arbitrary input", and restoring it "pays twice for work that could be delivered as output". So #4359 counts that state as output. A helper that has finished a width-8 transform becomes a rank-8 productive job instead of a cost to undo. The saving then solves a mixed balance, , with paid calls of rank on one side and productive outputs of rank on the other. The p3 controller books 1,570 helper jobs of ranks 6 to 9 beside 672 main outputs, for 0.0023051 (reported).
The outer theorem needs a uniform supplier, whose outputs all share one rank. Building on Jacob Alan Sussman's Theorem 1G (#4268), a finite integer compiler matches jobs to roles of equal rank and completes each array's missing axes recursively, so every array ends holding a full transform. The compiled word has rank and is specified by an algorithm, not written out. On the bit side, an atom exponent of 1/1000 that capped the bit saving at 0.001 rises to 0.003 (reported). Colkitt's "compiling unequal jobs into valid recursion" is the fuller summary.
Cinna Davis then took 0.0023 to 0.00302015 in six and a half hours of commits: tensor strictification (#4412), paid target padding (#4416), query-thinned controllers (#4440, +10.18%), retiming (#4441), a missing contact span (#4447) and #4470's joint helper boundaries, which move 38 helper entrances, 47 exits and 414 contact frames (reported).
Is it holding?
So far, yes. No ledger title from #4300 to #4954 claims a counterexample to #4359 or #4470. Matarener's #4457 ran #4440's controllers and #4447's native word on concrete operators and checked #4359's delayed-cover identity on about 118,000 small cases. All passed, with one premise made explicit, , which Mihir Srivastava's #4464 audits. The maintainer's review of #4470 passes it with "no blocking defect" and calls itself "not formal verification or an independent human proof review" (reported). I ran #4470's verifier and it passed. It is a reviewed conditional result, not an independently checked theorem, but unlike 17 October the counterexample hasn't arrived.
Rohan's numbers, checked
Both percentages are against #1094, main before 21 October. 0.0023 is 37.51% above it and 0.00302 is 80.55% above it, so "+37.5%" and "+80%" reproduce (measured). Against main when he posted, 0.0023, #4470 is 31.31% higher. Colkitt's "66% improvement" is 0.00268647 over his 12 October checkpoint #596, +66.58%. The tracker in Rohan's screenshot still shows #279's stale "Reviewed-main checkpoint: 7.2357159×10⁻⁴". I couldn't check zxv's "30-40 hours worth of compute" or Rohan's "path to κ = 0.01".
Where it stands at 04:02 UTC on 23 October
main is #4470 at , about times OpenAI's start. The best open claim is Cao Yifan's #4610 at 0.0030217758, 0.054% higher. Cinna Davis's #4658 certifies a ceiling of for the current path family, 0.0074% above #4610, so this design is nearly used up too (reasoned). main now takes 1.66% off at , and halving the time needs . The race chart now runs to this morning, its zoomed axis extended to . All of it is still conditional on OpenAI's #109 manuscript. And MiniMax said on 19 October that "Space Bunny" was an early MiniMax M3.1 Flash, which plausibly identifies the "Space bunny free" credited on 17 October's refuted records, though those commits record free text, not a model ID (reported).
23–24 October: talk of κ = 0.01
Rohan Arun posted at 17:01 UTC on 23 October: "We found multiple paths to conditional κ = 0.01, a possible κ = 0.006." It would "take another day or so to either disprove or build the final decoder." I read it, its replies and its table, and main at 1a3ced6.
What the table says
Beside three pieces marked "Done (independently audited)", including a "top output bank decoder for one 3-call word", the fourth row is "Tariff targets, based on assumed job counts not yet constructed": κ ≈ 0.0073 if all 232 jobs reach full rank, 0.0053 if eight extra rank-8 jobs are needed, and 0.001–0.003 with no centre credit (reported). 0.01 isn't in it. The only row without an assumption is the range main already sits in. No PR from #4600 to #5416 is his, so there was nothing of his to run. Until the decoder exists, a path is a plan with a price attached, not a certificate.
Where the talk of 0.01 comes from
On 22 October DaysSky quotiented PR4470's word by part of its ambient space: #4596 by span511, #4629 by span153 for a complex saving of 0.0156, and #4633 on the BIT side, claiming "outer kappa 0.012401" (reported). pinterbanget's #4604 showed that the map sends all 224 main fields into one output chart, and that the replay passed only because it compares a word with its own declared finals. Cinna Davis's #4652 found that 0 of 111 BIT ports and 0 of 112 complex ports meet the contract the invoice prices. Her #4655 proved that keeping only the surviving ports leaves no local advantage for any nonzero kernel. lm1909's #4642 found the 0.0156's ninth axis is reached only by padding. The missing piece is a cheap decoder back to the right output charts; #4596's last commit priced that at 336 ranks against 112 saved. That Rohan's track is this piece is my inference.
The ceiling held, and was stepped around
Cinna Davis's #4658 certified for native/thin path controllers, leaving out "new words, native interfaces, idle masks, coded corrections". Its optimistic price for a changed model gives a repair budget of 342 rank-one units at 0.006 and "Already negative" at 0.01 (reported): on that route, no budget at all.
The record went round it instead. From 20:23 UTC on 23 October Ali Romman's owned helper relations passed it, #5377 at 0.00302235 up to #5398 at 0.00302728823. Chris R's #5413, on Dillon Amburgey's coupled provider (#5402), adds , which the review calls compiler headroom (reported).
main moved twice
At 20:19 UTC on 23 October Colkitt admitted #4610 after Chris R's independent #5241 audit. At 03:30 UTC on 24 October he selected #5413:
That is 0.18% over #4610, 0.24% over #4470 and 81% over #1094 (measured). The review, run on macOS through an adapter, passes it "under the five existing selected assumptions". I ran scripts/verify_frontier5413.py on Linux, on the shared 4-core VM at nice -n 19 with no network. It printed PASS_FRONTIER5413_WITH_SOURCE_BOUND_FOUNDATION_REUSE in 59 s, with a sampled peak of 204 MB, on CPython 3.13 rather than the 3.12 the packages name (measured). It checks the #4610 foundation by hash without rerunning it, so it tests the new layer, not the stack below.
How far 0.01 is
0.01 is 3.3 times main. The outer κ is the smaller of the complex and BIT savings, and the selected record admits a BIT saving of 0.0034, so 0.01 needs the bit side to grow about 2.9-fold too (reasoned). At , κ = 0.01 would take 5.39% off against main's 1.66%, and halving the time would need instead of (reasoned).
Where it stands at 04:00 UTC on 24 October
main is #5413 at . No open claim in the ledger to #5416 is above it, apart from the contested quotients. 0.01 and 0.006 are paths without certificates. The race chart now runs to this morning, with the quotients hollow and the zoomed axis raised to . All of it is still conditional on OpenAI's #109 manuscript.
What "conditional" means here
Everything in the repository is stacked on top of other assumptions. The base layer is OpenAI's 73-page manuscript, which has no Lean statement and, as far as I can find, no published expert review. On top of that are Colkitt's written extensions, and on top of those each PR builds on earlier PRs. By the evening GitHub marked 25 of them merged, after two review rounds (#39 and the six it stacks on, then #43 to #62 in two batches); by 11:00 UTC on October 9 it was 30, with icekylinx's chain from #104 to #144 merged after a third, and by the evening 35, after a fourth round that imported #186 as a package and left it open. The 158 still open then, 232 at 11:35 UTC on 10 October and 411 at 19:40 UTC on 11 October are neither merged nor reviewed; GitHub then marked 36 merged, the last at 14:08 UTC on 10 October. By 07:20 UTC on 13 October it marked 152 merged, and the selected record on main lists 76 source PRs, from #315 to #799, that the current κ rests on. PR #44's dependency list runs through #43, #41, #36, #34, #32, #29 and on down to #3.
The maintainer's contribution-review index treats that stack carefully. It had six review stages in dependency order, foundations first (#3, #5, #7), then batching (#10, #13), then the later layers, and it states its policy: "A contributor's successful test report, or a large headline in a PR title, is not treated as verification by this project." The integration/community branch where #39 was staged carried a ledger whose gates were honest about the state of review: "Executable replay passed; proof review pending", and for two-stage and copy schedules, "Initial text inspection only". The audit closed those gates for #39's chain, and the second round extended them by replay to the PRs it merged; nothing else. The ledger also says "A failed gate should isolate the strongest surviving earlier checkpoint rather than trigger an unsupported all-or-nothing acceptance of the latest number." That rule is why the checkpoint is still kept, on release/ternary-30 and in the release notes, and of all the process decisions in the repository it is the one I would copy.
Who wrote it
Mostly AI agents, and they say so. 42 of the 44 PR descriptions name the model or tool. OpenAI Codex appears in most of them; 15 also credit "GPT-6 Astra"; eumemic's PRs end with "🤖 Generated with Claude Code"; Dominik Scholz's #33 credits "Anthropic Claude Opus 5.5, OpenAI GPT-6 Astra and Codex"; and Rohan Arun's #44 says it was "Prepared by Rohan Arun with substantial Anthropic Claude assistance; OpenAI Codex performed this local arithmetic replay and upstream submission". Seven PR branches carry the codex/ prefix that Codex gives the branches it opens. #34 mentions only "independent agent reviews", and #2 says nothing. Colkitt's notes all carry the footnote "Prepared with assistance from OpenAI Codex", and CONTRIBUTING.md asks contributors to "disclose substantial AI assistance". Jain's repository says the same of itself: "Research, implementation and drafting were done with assistance from Claude (Anthropic)." Rohan Arun, whose PR ended up on main, put the tempo best, announcing #40 at 13:39 UTC: "The improvements in the end started getting faster than we could run the verifications." In the same post he tagged @sama and @thsottiaux with "could I get a reset?", which I read as a plea about usage limits, and added, diplomatically, "Mostly used Codex here but Claude collaborating on the other side might have helped reach a new best".
The style gives it away too, though that is my reading rather than proof. Every PR has the same structure (result, construction, verification, attribution, scope), the same careful hedging ("not formal verification or completed external expert review"), and the same habit of reporting a few hundredths of a percent over the previous PR, often within ten or twenty minutes of it. People aren't usually that fast or that consistent. A good share of the tempo is people pointing agents at the newest PR and asking for more.
Colkitt's own posts are the human layer on top. On the morning of October 8: "Went to bed last night, and sorry to report only a bit of incremental progress on my side. But it appears like this has taken off in terms of now having a real community effort", followed by a promise to "validate the results, definitely make sure we have attribution". The attribution machinery is the most unusual part of the repository: a CONTRIBUTORS.md that credits all 39 PRs at the checkpoint, including the closed and superseded ones; a pinned contribution-snapshot.json of every PR head hash; NOTICE entries for #7 and #3; and, until the audit, nothing merged into main, so nobody's PR silently overwrote anyone else's. When #39 went in, the attribution went with it: the README names Rohan for "the final #39 witness" and then nine contributors and groups by what each supplied, and NOTICE gained the line "it is not solely Douglas Colkitt's work." Colkitt's post promised more: "I want to take time to highlight each of them, but for now getting these results verified and published as fast as possible so everyone working on the problem is at the leading edge." At 03:32 UTC on October 9 he posted a video, "Small, But Not Zero", billed as "An opera explaining the integer multiplication math journey up to this point." One contributor, hipotures, left a comment on #20 calling it "real-time mathematics" and comparing it to SETI@home. The comparison is a stretch, but I can see why it came to mind.
"Linear time by tomorrow"
Two hours after the post, Julian Schiavo posted a chart.
When Colkitt's post landed, he followed up: "update! @0xdoug hit 2^(-34), so we are sadly now 18 minutes behind schedule".
He kept it going. At 16:30 UTC on October 8, an hour after Colkitt's post: "the saga continues. good news: @0xdoug hit 2^(-15)! bad news: we missed the 12:44am target, based on my careful data analysis we will now have linear time integer multiplication at 6:44pm. by popular demand, I removed the O(n) limit".
The fit is now a power-law curve in rather than a straight line, and with the cap removed the red line sails on past , into multiplication faster than linear time, an algorithm that would finish before it had read its input. 6:44 PM Pacific is 01:44 UTC on October 9. When I last looked, at 19:46 UTC, main stood at and the best open claim at , so the curve needs about fourteen more doublings in six hours. I'm not taking the bet, but I wouldn't have taken the one against #53's jump either.
The 6:44 PM deadline passed with main at . Then the cover landed, and at 05:53 UTC on October 9 he posted again: "New data means new data analysis! Updated data suggests we will now reach linear time integer multiplication at 8:33am tomorrow morning".
8:33 AM Pacific is 15:33 UTC on October 9. At 11:00 UTC the best claim anywhere was , so the curve needs ten and a half more doublings in four and a half hours. The ninefold night is the closest the real data has come to keeping his schedule, which is funny in its own right. It doesn't change the argument below: every one of those doublings has to come out of a relative rank deficit, and κ can't pass ½. The deadline came and went with the best claim at (maxime-fleury's #199), and there hasn't been a fifth chart.
It's a joke, and a good one, and the chart above already answers it: the extrapolation is on. A straight line in through Colkitt's and posts reaches at about 13:08 UTC on October 8. At that moment the real frontier was PR #39 at . The line was about fourteen and a half doublings out, which is a factor of roughly 25,000. It was never going to land, and the reasons are useful.
First, is bounded, and this construction has a lower ceiling than the obvious one. Linear time is , but as shown above the shape of the margins keeps below and below the network's own saving , which is a relative rank deficit. Second, the early gains were not discoveries about multiplication. They were slack being given back: the manuscript rounded a real saving of about down to and multiplied three conservative factors together. Undoing deliberate conservatism produces enormous ratios quickly, and then it is used up. Third, every later improvement is a smarter constant inside the same recursion, and the flat tail of the chart shows what that looks like.
And then there is runtime. With the constants ignored, the ratio of to is . Take bits, an integer with about binary digits, roughly one per atom in the observable universe. At the saving is about of the running time. At PR #13's it is about percent. At PR #44's it is about 0.023 percent. Even with , a number whose length in bits needs a 64-bit counter, PR #44 saves 0.18 percent. To halve the time you need : at PR #13 that is , at PR #44 about . That's before the constants, which in this construction are astronomical (the roundup's FFT section found a -role batch at the top level of the sibling paper's network).
So GMP is safe, and it would have been safe at as well.
Why I still think it's interesting
Not for the number. What's interesting is the loop. Within two days of a hard theorem being posted, a stranger forked it, rewrote its parameters with an agent, wrote up each step with exact certificates and patches against a pinned source, and published. Then about a dozen other people, almost all working through agents, started building on each other's unmerged PRs every few minutes, with tests, PDFs, notes and attribution blocks that are more careful than most human repositories manage. Some of it is real mathematics: the identity, the batched moment recurrence and the source-frame observation are ideas, not tuning. The certificate culture is real too. Every headline in the repository comes with a script that rebuilds it from exact fractions, which is why I could check PR #13 in an afternoon.
What it is not: a faster multiplication algorithm, a refereed result, or a formal proof. Everything depends on a manuscript nobody has independently reviewed, only what main has taken in (#39's chain, then #49 and the #50 to #62 round, then #144 and #186) has been through the maintainer's review, and that review was Colkitt with Codex rather than a referee, and the hard obligations (that the tape procedures do what the notes say at full size) are exactly the parts the certificates do not touch. If something in the upstream argument breaks, the whole tower goes with it, and the repository's process is designed to fail back to the strongest surviving checkpoint rather than pretend otherwise.
The race also shows the risk. Seventy-seven PRs in under twenty-three hours is far more than one maintainer can review. He audited one chain in about two hours, and by the time it was merged the open frontier was 6% past it. He then reviewed thirteen PRs in one round, and an hour after that merge the open claims were 1.4% past it again. Overnight he reviewed a four-PR chain and merged a ninefold gain, and by 11:00 the open claims were 42% past that, across 179 PRs. His next review put main at #186's ; Jain passed it ten minutes later, and by 18:50 the open claims were 3.4% past it again, across 217. By the next morning they were 13.5% past it, across 301, and the merge he announced overnight still wasn't on GitHub. His next review put main at , and a day and a half later the open claims were 79% past it, across 485, with nothing reviewed in between. Then he changed how he reviewed, in frozen rounds every few hours, and by the morning of 13 October main held the best claim anywhere. So the lag can be closed, at least for a while, by a maintainer working with an agent; whether that review is worth what a referee's would be is the open question. And now the same engine is being tuned for a second problem, where, oddly, the checking got further: the Fourier bound is a whole Lean theorem, while every κ is still a certificate on top of a manuscript. At this volume, the scarce resource is the human checking, not the agent output.
How I checked
I shallow-cloned the repository and fetched PRs #3, #5, #7, #10, #13 and #44 by ref. Commit times come from git log, PR times and descriptions from the GitHub REST API (44 PRs at 14:24 UTC on October 8; #45 arrived at 14:35), and the X posts and their replies from the fxtwitter mirror. I read the upstream manuscript's introduction, motif bounds and assembly sections, Colkitt's notes, the review index, the contribution snapshot and the integration ledger.
As a stated exception to my usual rule of not executing third-party code, limited to the repository's own pure-arithmetic checkers with no network, I ran the README's focused verification on main and the PR #13 certificate generator, its tests and its full make verify, all under nice -n 19. I recomputed PR #13's seven margins and its bit moment independently with Python fractions and 80-digit decimals, the residue identity by brute force at , the implied network savings from the certificates' counts, and the runtime factors with 80-digit decimals. I did not run any later CrocSwap PR's suite, and did not review any proof. OpenAI's release time on the chart is the openai/math commit time from the GitHub API, 21:58:50 UTC on October 6. The values in the race chart are computed from each PR's stated , not from its certificate.
For Swapnil Jain's track I cloned integer-mult-kappa with full history (20 commits, 07:17 to 14:01 UTC) and read all of it: the README, NOTICE, the nine notes, the certificates, the independent/ re-implementations and the two Lean files with their generator. His six posts and their threads came from the fxtwitter mirror, and the CrocSwap PR bodies and their credits to him from the GitHub API, last at 15:24 UTC, when #48 was the newest PR. Under the same exception I ran his make verify, scripts/certificate_round6.py and independent/complex-twostage/run.py 24, all pure Python with no network, and checked that the histograms they regenerate equal the Lean inputs. There is no Lean toolchain here, so I did not run Lean; instead I re-implemented the five Lean definitions in Python and evaluated both files' theorems, recomputed the round-six margins with exact fractions, and redid both moments at 80 digits.
For the merge I fetched every PR ref again at 15:45 UTC, read git log --graph on main (the merge commit fd8c563 has 70ae241, #39's head, as its second parent), the PR states from the GitHub API, the diffs of c9fca20 and 0605a24, the audit, the release notes, the integration ledger, CONTRIBUTORS.md and NOTICE, and Colkitt's and Rohan's posts through the fxtwitter mirror. Under the same exception as above, I ran make verify on 0605a24 at nice 19. It passed: the audit's own arithmetic check ("PASS independent moments, seven margins and all 32 RaD source hashes"), the #39 producer and its PASS bit=3886826921/100000000000000;kappa=971668963/25000000000000, every earlier witness back to , 20 patch checks and all 218 unit tests, in 16 minutes 12 seconds of wall clock at 2.9 GB peak, with the working tree clean afterwards, so every regenerated certificate matched the committed one. That checks the certificates and the replay, not the audit's proofs, which I read but did not re-derive.
For the evening I fetched every PR ref and the GitHub PR list again at 19:46 UTC (77 PRs), read main's log since 15:18, the README at ed8201c and 0d235fe, the round-two review and validation receipt, the imported research/swapnil-parallel/ review and its verification.json, and the bodies of #53, #57, #61, #62, #64 and #76. Jain's repository, cloned again, has no commit after f2176bc. For the tracker I rendered the page in my own headless Chromium, read its source repository and compared its /api/research JSON with my chart's data. For the Fourier draft I shallow-cloned shea256/fourier-transform-below-nlogn at bf38c00, read the README, the manuscript, both audit files and the verifiers, and read the thread and replies through the fxtwitter mirror. Under the same exception as above I ran verification/run_checks.py (pure standard-library Python, no network). I recomputed , , the deficit, the histogram sum, and the ratios with exact fractions, and the moment and its critical root at 80 digits. I did not review the transfer's proofs.
For 9 October I fetched both repositories again at about 11:00 UTC: main at d1d6c07, every PR ref and the GitHub PR list (179 PRs), Jain's repository at d2f6146 with full history, and his, Colkitt's, eumemic's (@dysmemic), Prosz's, Shea's and Julian Schiavo's posts, threads and replies through the fxtwitter mirror. I read the bodies of #104, #130, #137, #144, #159, #168, #172 and #179, the three-stage-cover and paired-cube notes, the maintainer's round-six review, and Jain's README sections for rounds seven to ten and his round-nine and round-ten certificates. Under the same exception as above I ran make paired-cube-verify on main (44 s, 270 MB) and then the full make verify, which passed its community, producer, partial-gauge, three-stage-cover, paired-cube, certificate and ternary stages and then stopped after 44 minutes, at 3.1 GB peak, in a preserved-research check for PR #51 whose C++ helper needs Boost headers this machine doesn't have; I also ran Jain's make round9, make round10 and the round-nine bit ledger with its certificate check, and eumemic's make verify in exact-dft-bounds, all Python (plus the repository's own small C++ helpers on main) with no network. I recomputed #144's and round nine's assemblies with exact fractions, both round-nine moments' critical roots at 80 digits, the first-order saving for #144's complex network and Jain's round-six network from their histograms, the orthogonal group's order, and every ratio quoted. I did not run Lean, and I did not review the cover's or the Fourier transfer's proofs. The PR points from #78 on come from the GitHub API and the tracker's JSON, with each PR's κ as its title or body read at 11:00 UTC, which for PRs edited in place (#168 most of all) is a later claim than the one they opened with.
For the afternoon of 9 October I fetched everything again at about 18:50 UTC: main at 3b6b668 with GitHub's push log for it, the GitHub PR list (217 PRs, with titles and bodies), the tracker's JSON, Jain's repository at 1a580dc with full history and the list of his public repositories, eumemic's exact-dft-bounds at 6f87d1a and Shea's draft at a2840b1, and Jain's, Colkitt's, @dysmemic's, Shea's and Julian Schiavo's posts, threads and replies through the fxtwitter mirror. I read Jain's README sections for rounds ten and eleven, the recycling gate's README, the maintainer's round-eight review, Shea's round-eleven audit, and the bodies of #186, #192, #194, #197, #201, #203, #212 and #217. Under the same exception as above I ran Jain's make round11, his complex recycling checker on the word and his bit ledger on the word with its inventory check (writing their outputs to my scratch directory rather than the script's /tmp), CrocSwap's make entrance-bank-verify, and Shea's verify_round11.py, all Python with no network. I recomputed rounds ten and eleven's stopped mixes and assemblies with exact fractions, and and for both sides of both rounds from the histograms in his Lean inputs. I did not run Lean, and I did not check the ceiling PRs' proofs or any of the new interfaces. The new chart points from #181 on take each PR's κ from its title as it read at 18:50.
For 10 October I fetched everything again at about 11:30 UTC: CrocSwap's branches and tags with git ls-remote (main still at 3b6b668), the GitHub PR list to #301 with titles and bodies, the rename history of #275, the tracker's JSON (fetched by it at 11:14 UTC), OpenAI's math commits and the UniformFourier challenge and lean/docs/130.md at fd4aeeb, Shea's repository at 62554f9, Sussman's at f010392 with PR #2's head 837dc31, danadran01's at 1a7b25e, Jain's at d583bef and his two Zenodo records, and Jain's, Colkitt's, @dysmemic's, Shea's, Prosz's and Julian Schiavo's posts through the fxtwitter mirror. I searched arXiv's API for the authors and titles. I read Shea's README, manuscript, attribution audit and five-stage audit, Sussman's README and ORIGIN, Jain's closed-ideas list and the abstracts of both papers, and the bodies of #209, #210, #225, #233, #234, #240, #256, #262, #275, #285, #288 and #231. Under the same exception as above I ran Shea's verification/verify_five_stage.py (25 s, 215 MB) and his full verification/run_checks.py (6 min 39 s, 1 GB peak; every suite passed and every reference certificate matched), both standard-library Python with no network. I recomputed Shea's ratios and Colkitt's with exact fractions, the five-stage histogram's rank, deficit and critical saving at 80 digits, its first-order and , and the runtime figures. I did not run Lean, and I did not check the ceiling papers or any of the new κ claims.
For 11 October I fetched everything again at about 19:40 UTC: CrocSwap's main at 12a4934 with its log since 3b6b668, the selected-result record and the #210 and #279 reviews; the GitHub PR list to #485 with titles and bodies, and GitHub's rename events for #373 to #390 and #434; the heads of #352, #370, #390, #467 and of all 148 PRs opened in the 24 hours before Rohan Arun's 17:31 post; Sussman's repository at 9c94857, Shea's at c83ab6b, eumemic's exact-dft-bounds, Jain's at 449dbb0 and the Big O Speedrun verifier's PR #3; the tracker's JSON (fetched by it at 19:25 UTC), the Auto Research page and its prompt, Tim Gehrunger's quasi-Riemann tracker data, and Rohan's, Colkitt's, Jain's, Shea's, @dysmemic's, Prosz's, Nil Mamano's, Hailey Collet's and @mrowdays' posts and replies through the fxtwitter mirror. I read Sussman's README and his note on how the E8 unit was found, and the bodies of #310, #346, #352, #363, #370, #376, #377, #390, #425, #433, #442, #446, #448, #451, #453, #467 and #480, with #467's assembly script. Under the same exception as above I ran Sussman's tools/gx/refcheck.py and gxdry.py on the E8 certificate (under a second each) and #467's verify_component.py (27 s), all standard-library Python with no network; #467's full verifier needs SymPy, a C++ build and Boost, which this machine doesn't have. I checked by brute force that Sussman's 120 labels and E8's 120 root lines give strongly regular graphs with the same parameters, recomputed the E8 unit's and #467's , and critical savings at 80 digits from their histograms, redid #467's outer assembly with exact fractions and #390's under #377's stated settings, and computed for the five-, seven- and nine-stage E8 words from #363's formulas. For Rohan's statistics I counted PRs, authors and body mentions from the API, and diffed every PR head in the window against its merge base with main with git diff --shortstat and --numstat, which gives lines by file type and path. I did not run Lean, did not build #390, and did not check the cross-copy obstruction, the new format ceilings or the quasi-Riemann proofs.
For 13 October I read Colkitt's post and its thread through the fxtwitter mirror, cloned CrocSwap's repository at f567884 (06:46 UTC) with 200 commits of history, read main's first-parent log since 12a4934, the README at each selection commit (a1e7d84, 1c1e42f, 7f6ccd7, 1db1fbe, 2e9ed96, 5c5567d, 2cdd93d, d6dfd8f), certificates/selected-result.json, the nine checkpoint records and the certificates they point to, and the review notes for #531, #535, #588, #596, #617, #626, #741 and #799. The PR list (843 PRs, titles, states and merge times) is from the GitHub REST API at 07:20 UTC. I did not run any of the repository's code this time; the selected verifiers need a C++17 build and Boost. What I recomputed, with Python fractions, is the outer formula against each published κ from the binding savings in the ASSEMBLY.json files, the binding side and the margin to the other side, every ratio and quoted, for Colkitt's exponent, the concavity example and the runtime figures. I did not check any proof, the Lean files, #795's optimality certificate or #595's ceiling.
For the evening of 13 October I read Rohan's two posts (08:18 and 15:00 UTC) through the fxtwitter mirror, cloned CrocSwap's repository again at bbc600d (15:08 UTC) and fetched all 972 PR heads with git fetch. The GitHub API was not reachable from this sandbox, so PR counts come from PR numbers and head-commit times, and PR bodies were not read. I read the README and ASSEMBLY.json for #890 and #942, the READMEs of the R420, punctured-star and #589 frame-optimum packages, research/leech-lattice/ and research/niemeier-lattices/ on main, #895's BW16 README, research/experiment-log/README.md, and auto-research.md and auto-research/README.md at e0167c3 and at #928's head d2daf3e, with git diff --shortstat against its merge base. I ran none of the repository's code. With Python fractions I recomputed the two new ratios, the bit-side margin, against #942's κ (under it by ) and Rohan's 28.9%.
For 14 and 15 October I read Rohan's post of 15:05 UTC on 15 October, its thread and its replies through the fxtwitter mirror, and Google's Deep Review post as published. I cloned CrocSwap's repository again at 0706e74 (10:07 UTC on 16 October) as a blobless clone and fetched all 2,602 PR heads with git fetch (24 MB), so file contents were fetched only as I read them. The GitHub API was still unreachable, and so was the GitHub connector for this repository, so titles, logins and states come from docs/research/pr-ledger.json on main (2,397 PRs to #2872), and times from commits. I read certificates/selected-result.json at each commit that changed it, the batch1099 review and #1094's ASSEMBLY.json, autoresearch.md, #2226's README and PROOF.md, and the READMEs and claim files of #2260, #2269, #2530 and #2571. Under the same exception as before, I ran #2571's bounded verifier (research/source-partner-repack/verify.py at 0c14308b, the commit Rohan posted). It is the repository's own Python, and I ran it in a scratch venv with the pinned NumPy, SciPy and SymPy, with no network, at nice 19. It passed (PASS_SOURCE_PARTNER_REPACK_LITERAL_OWNERS) in 91 s at about 0.23 GB on a shared 4-core VM. That checks the fill's literal owners, three rejecting controls and the claim's bindings to its outer ledger. I did not run its full_replay.py, or make frontier1094-verify on main, which rebuilds the #1042 baseline first. With Python fractions I recomputed every ratio and quoted, #2571's rank mass from its profile, the gap to the complex saving, for #1094 and for #2571's saving, and the runtime figures. The records and the 24-hour counts come from ledger titles in PR-number order and are approximate. Each chart point from #845 on sits at the earliest commit unique to its PR, not at its opening time. I did not review #2226's proof, the #1673 outer assembly or any of the new constructions.
For 16 and 17 October I read Rohan's post of 15:33 UTC on 17 October, its thread and its replies, and the three images attached to the post and to his reply, through the fxtwitter mirror. I cloned CrocSwap's repository again at 463113d (16:52 UTC on 17 October) as a blobless clone and fetched every PR head to #3204. The GitHub API was still unreachable, so titles, logins and states come from docs/research/pr-ledger.json at that commit (to #3197), and for later PRs from the head commit's subject and author; times are commit times. I read selected-result.json, main's first-parent log since 0706e74 and the 17 October intake records; the claim files of #2863, #2979, #3021, #3143 and #3148; #3184's README, CLAIM, AUDIT and VERIFY files and every commit message on it, #3190, #3198 and #3200; #3187's README and DECISIONS.tsv; and the READMEs of #3199 and #3204. I also took a shallow clone of rohanarun/Auto-research-agent to read the OpenCode commit and its trailers. Under the same exception as before, I ran #3184's bounded verifier, research/rank7-idle-star-exchanges-t740/verify.py at 6faefe1 (#3184's head). It is pure standard-library Python, and I ran it with no network namespace at nice 19. It passed (PASS_IDLE48_STAR_EXCHANGE_AUDIT, 125,706 moves, nine controls rejected) in 209 s at about 0.32 GB on a shared 4-core VM. I ran it without --fill, because rebinding the idle bins needs #3148's materializer, and I did not run build.py, #3187's operator check or any other PR's code. With Python fractions I recomputed every ratio and quoted, #3184's gain and the screenshots' figures. I did not review the idle-exchange argument, #3187's interval proof or #3204's rigidity proof. The new chart points use the same rules as before; #3184 and the three PRs that stack on it are drawn hollow.
For 17 and 18 October I read Rohan's post of 21:22 UTC on 17 October, its thread, its one reply and its attached tracker screenshot through the fxtwitter mirror. I cloned CrocSwap's repository again at 20ecf28 (04:52 UTC on 18 October) as a blobless clone and fetched every PR head from #3140 to #3881 at about 02:40 UTC on 19 October. The GitHub API was still unreachable, so titles, logins, states and the maintainer's verdicts come from docs/research/pr-ledger.json at that commit (to #3528), and later PRs from their commit subjects; times are commit times. I read selected-result.json and the README on main, #3251's README, CLAIM.json and TASK.json, the READMEs of #3263 and #3296 and #3263's #3251 witness, and the OpenCode and Claude trailers on #3184 to #3251, and I searched every fetched title and commit subject for a κ above #3148's. Under the same exception as before, I ran #3251's bounded verifier, research/rank7-idle-donors-exact-r438/verify.py at 3ffd42b, standard-library Python, in a network-less namespace at nice 19. It passed (PASS_IDLE_DONOR_EXACT_R438_AUDIT, 435,604 moves, eight controls rejected) in 159 s at 1.18 GB peak on a shared 4-core VM, CPU only. I ran it without --t740, as for #3184, and did not run build.py or #3263's and #3296's operator replays. With Python fractions I recomputed #3251's gain over #3200 and every ratio quoted. I also cloned platypii/integer-mult-bounds-lean at ea57ec3 (00:27 UTC on 19 October) and read its README, the completed-proof plan, Statement.lean and the commit history, and searched its Lean files for sorry, admit and axiom. I did not build it or run Lean, so whether it compiles is reported, not measured. The new chart point, #3251, uses the same rules as before and is drawn hollow.
For 19 to 22 October I read Rohan's post of 02:13 UTC on 22 October, its replies, its tracker screenshot and Colkitt's quoted nine-post thread of 20:08 UTC on 21 October through the fxtwitter mirror. I cloned CrocSwap's repository again at b919568 (04:02 UTC on 23 October) as a blobless clone and fetched the PR heads I cite, from #3682 to #4958. The GitHub API was still unreachable, so titles, logins and states come from docs/research/pr-ledger.json at that commit (to #4954), and times are commit times: each new chart point sits at the first commit on its head that states its κ. I read selected-result.json at every commit that changed it; #4359's commit message and PR-BODY.md; #4470's README; Colkitt's PROOF-REVIEW.md for #4416 and #4470; the README of #3734 and #3945 and #3734's claim file; and Matarener's #4457 README. I searched every ledger title from #4300 on for a counterexample, refutation or ceiling. Under the same exception as before, I ran #4470's bounded verifier, research/joint-helper-lattice/verify.py at b9a13c1, standard-library Python, in a network-less namespace at nice 19, with its declared inputs exported by git archive. All three registered parts passed: dependencies in 6 s, native (PASS_JOINT_NATIVE_632_COLUMNS_BOTH_ORIENTATIONS) in 58 s and arithmetic (PASS_CONDITIONAL_JOINT_HELPER_KAPPA_00302015) in 24 s, at 94 MB peak on a shared 4-core VM, CPU only. I didn't run the maintainer's extra transport and frame audits, #4359's replay, #4457 or #4610's package. With Python fractions I recomputed every ratio, and runtime figure quoted, Rohan's two percentages against #1094, #4181 and #4359, and Colkitt's against #596. I didn't review #4359's compiler, #4470's proof or the inherited premises, and the Space Bunny attribution is MiniMax's, which I didn't check. The new chart points use the same rules as before; Word RAM transfers and bit-only savings are left out.
For 23 and 24 October I read Rohan's post of 17:01 UTC on 23 October, its replies and its attached table through the fxtwitter mirror. Disk was short, so instead of a full clone I fetched main's commits since 21 October without trees, the PR heads I cite as commits only, and files at 1a3ced6 from raw.githubusercontent.com: selected-result.json at 1ec1119 and 1a3ced6, the #5413 review and promotion notes, docs/research/pr-ledger.json (to #5416) and the READMEs of the #4604, #4642, #4652, #4655, #4658 and #4660 packages. #4596, #4629 and #4633 aren't in the ledger, so their claims come from their commit messages. For the verifier I made a sparse checkout of the 1,245 files its source manifest pins, plus scripts/ and certificates/, 202 MB in all. Under the same exception as before I ran scripts/verify_frontier5413.py once, and deleted everything afterwards. I recomputed the ratios and runtime figures with Python fractions. I didn't review #5413's proofs, the #4610 foundation it reuses, or any quotient package's code.
I compiled the manuscript's TikZ flow figure from the pinned source with Tectonic, and the three-stage cover page from its TeX source at d1d6c07 the same way. The note pages, Jain's and Shea's included, are rendered from the repositories' committed PDFs (Jain's ceilings paper from its Zenodo PDF), the README image is a browser screenshot of the GitHub page, the tracker images are screenshots of the live site at 19:33 UTC on October 8 and 11:00 UTC on October 9, the 24-hour chart is the image attached to Rohan Arun's post of 11 October, and the Fourier leaderboard is a screenshot of Big O Speedrun's page rendered in my own headless Chromium at about 19:55 UTC on 11 October.