2026-10-06 · 66 min · webgpu · gpu
A 1:47 narrated explainer, drawn in code. Every number and picture in it is this article's own; the sources are below.
› transcript
Hi, I'm Samosa! Grand Theft Auto Five now runs in Chrome. Not streamed, not emulated. Here is how. The idea: compile the game's own engine to sixty-four bit WebAssembly, and let its threads reach the browser only through shared memory. The engine runs as real threads that block and wait. They never call the browser. They write requests into shared memory. The page drops keys in there too. Small workers pick them up: graphics, files, sound. Graphics were not rewritten. The engine still talks to Direct3D eleven, but the device is a fake. Each call becomes a small command in a ring buffer. A worker that owns the WebGPU device replays them in order. Every shader was translated ahead of time. Geometry and tessellation shaders have no WebGPU stage, so they are dropped. When the engine reads a file, it fills a slot in memory and waits. A worker checks a block store in the browser's private file system. Missing blocks come from the server, many requests at once. The bytes land in the engine's heap, and the thread wakes. That is how about twenty-one gigabytes of game data can sit behind a tab. Only the blocks the world needs are ever fetched. I ran it on a server with no graphics card. Chrome drew it in software, slowly, but this is the real world. Same engine, same data, inside a browser tab. The lesson: shared memory and atomics let blocking engine threads live beside a browser that only speaks async. The real engine, Direct3D replayed on WebGPU, and files streamed in blocks. Every source is in the full article. I'm Samosa. Bye!
Why read this
Hightop 30%The only full teardown of the GTA V browser port: every shipped file read, the D3D11-to-WebGPU ring and HTTP file system explained, a run measured.
- Original, source-checked analysis
- Interactive explanations
- A lasting reference
GPUs, kernels & systemsNothing to runProprietaryPractitioner teardown
How this was scored
- Is it new?
- 2 of 3: A real new idea, method or capability
- Can I trust it?
- 3 of 3: Reproduces the headline result, or shows from primary files it is wrong
- Can I run it?
- 0 of 3: Closed, nothing to run
- Will I understand it?
- 3 of 3: Mechanism carried by interactives built from real code or data
- Can I act on it?
- 2 of 3: A concrete recipe, numbers or comparison
- Will it last?
- 2 of 3: A reference for a year or more
- Does it affect many?
- 1 of 3: A specialist community
- Only here?
- 3 of 3: The only place this analysis exists
Score 74 of 100, ranked 76 of 701 rated articles. Each question is answered 0–3 by hand, and a 3 is rare. How articles are scored
A video went round this week of someone playing Grand Theft Auto V in Chrome on an M3 Pro, at playgta5.com. The replies split three ways: cloud gaming, an Xbox 360 emulator, or fake. The question asked most was how a game of 100 GB or more fits in the "700 MB" the tab downloaded.
My own bet was cloud streaming behind a good loading screen. I was wrong, and so was everyone who said emulator.
What sits in that tab is Rockstar's RAGE engine and GTA V's game code, compiled to WebAssembly. It is one file, game.wasm, 63,201,802 bytes, with about 91,000 functions that still carry their names, and it runs as 75 threads on 64-bit shared memory. The engine still issues Direct3D 11 calls. They go into a 32 MB ring as 48 opcodes, and a worker replays them on WebGPU with shaders that were translated ahead of time: 4,919 compiled DXBC shaders went in, 4,808 usable WGSL shaders came out, 72 MB in 18 packs.
And nobody squeezed the game into 700 MB. The game folder is 5,814 files and 20.9 GB, of which 1,528 .rpf archives make up 20.3 GB, and it stays on the server. The tab pulls 4 KB blocks of it with HTTP Range requests into an append-only store in the Origin Private File System. A session downloads a recorded 582 MB boot set and then whatever the world around you needs. In my run that came to 743 MB before I could walk anywhere.
I downloaded every file the site serves, read all of its JavaScript, pulled sample game files apart byte by byte, and ran the game headless on a 16-core server with no GPU. The world came up at 188 s and drew 2,736 draw calls per frame at 0.3 fps on SwiftShader, which is Chrome rendering on the CPU. Slow, but it is the game.
One thing has to come first, because it shapes everything else. The binary was built from GTA V's own C++ source, and the 20.9 GB the site serves is Rockstar's game data. Neither is licensed for this. Where they almost certainly came from is near the end.
A Flash movie, rebuilt in CSS
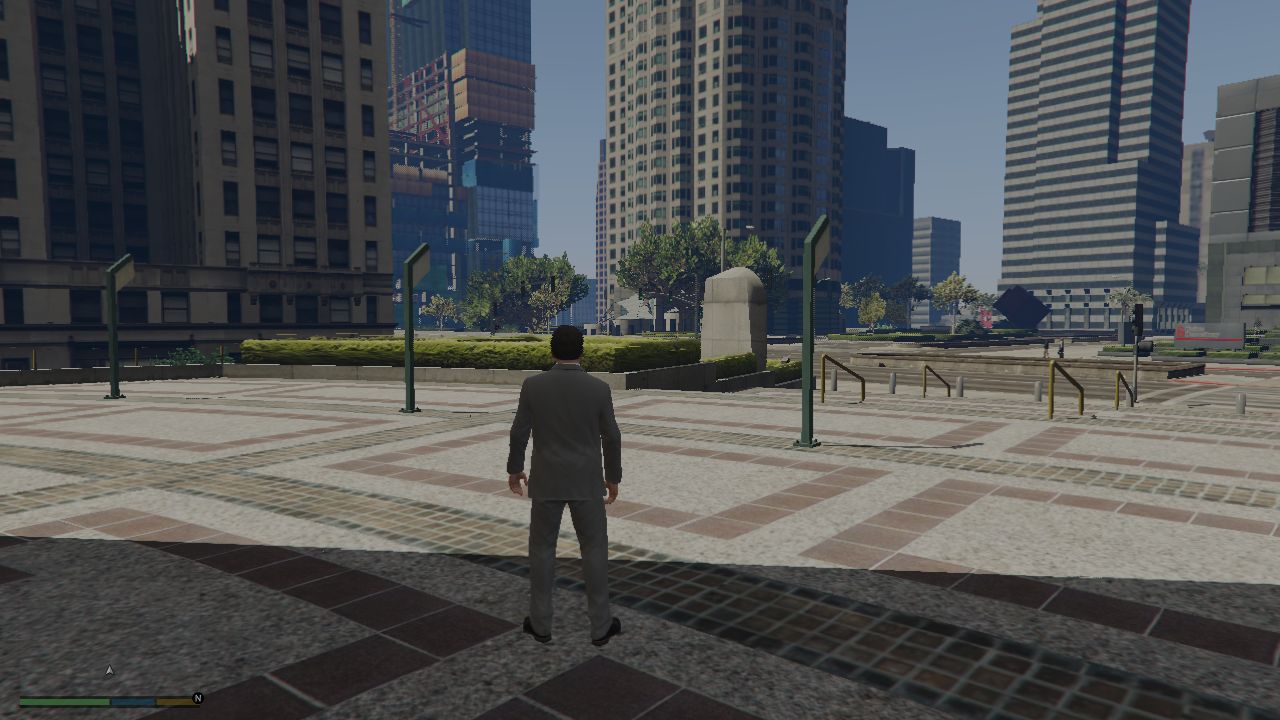
The page opens on GTA V's loading screen, the character art and logo sliding in on a tilted 3D plane. I took it for a video. It is the game's Scaleform loading movie, LOADINGSCREEN_STARTUP, decompiled from its ActionScript and rebuilt in HTML and CSS, with the same 55-degree camera, the same six random orders of 17 screens and a new screen every 14 seconds. A comment on the page says so, down to the font ($Font2 = Chalet London 1960). The art, logo and font were pulled out of the game by a script the comments call phase3/make_title.py.
Bottom right sits a menu. Story Mode continues the newest savegame, or starts the Prologue with ?newgame=1. Sandbox Mode asks for a map: "GTA V Map" drops you somewhere random in free roam with every weapon, and a second option the page labels "GTA VI Map" turns out to be the env_test level in the data. You can change your mind until the engine reads its -level argument, about 62% of the way into the load. Leave it any longer and the engine waits for you while the key caps pulse.

The progress bar under the art was the first sign that the porter changed as little of the engine as possible. Nothing in RAGE reports progress. Instead prejs.js, the porter's code at the top of game.js, matches nine regular expressions against log lines the engine has always printed:
const stages = [
  [/^Audio rpf =/, 24, "Mounting archives"],
  [/Using Settings/, 38, "Reading settings"],
  [/created D3D11/, 45, "Starting graphics"],
  [/CShaderLib::Init/, 50, "Loading shaders"],
  [/LOAD_ADDITIONAL_TEXT - finished/, 56, "Loading text"],
  [/Starting audio thread/, 62, "Starting audio"],
  [/Loading singleplayer metadata/, 66, "Loading audio metadata"],
  [/^Loading SRL file/, 72, "Starting scripts"],
  [/Removing prologue IPL light groups/, 84, "Loading the world"],
];
The first 20% of the bar is the engine download, 76% is the first frame the GPU worker presents, and 72-98% follows game data as it arrives. The title screen drops only after 1.5 s of frames go by with no draw call waiting on a pipeline compile. So the shader compiler decides when the game counts as loaded, which tells you early where this port hurts.
I ran it with ?mode=sandbox from a server in a data centre, through a Cloudflare edge in Mumbai, with eight other jobs on the machine. From my log:
| Time | Stage | Game data fetched |
|---|---|---|
| 24.6 s | engine downloaded and compiled, main() starts | 0 |
| 39.5 s | mounting archives | (boot set prefetch running) |
| 54.6 s | starting graphics | 223 MB |
| 69.7 s | first frame | 454 MB |
| 176.2 s | preparing shaders | 743 MB |
| 188.1 s | world shown | 743 MB |
Your laptop will compile faster and render far faster. It will not fetch much faster, and the streaming section explains why.
Thirteen kinds of file
Everything comes from one host behind Cloudflare. Engine files sit under a build-specific prefix (/b/8b0b5899ed/) and are cached for a year. Game data lives under /data/, and every URL carries ?v=<manifest version>, so a given URL always means the same bytes. This is the whole inventory:
| File | Size | What it is |
|---|---|---|
index.html | 44 KB | the page: title screen, start menu, input, audio start-up, low-memory profile, engine command line |
loader.js | 9 KB | a worker that becomes the engine's "main thread"; starts the GPU and IO workers; streams and compiles the wasm |
game.js | 124 KB | Emscripten's glue plus the porter's prejs.js (logging, progress, crash reports) and 13 JS imports; runs in every thread |
game.wasm | 63 MB | the engine: RAGE and GTA V, compiled to wasm64 |
wgpu_worker.js | 194 KB | the GPU worker: replays Direct3D 11 commands on WebGPU |
io_worker.js | 41 KB | the IO worker: serves every engine file read from HTTP and a disk store |
audio-worklet.js | 1.5 KB | plays the engine's mixer output |
shaders/index.json | 686 KB | 4,919 shaders: hash to stage, effect, program, pack and offset |
shaders/pack0..17.*.bin | 18 × ~4.2 MB | the translated WGSL, bundled by effect |
shaders/pipelines.json | 359 KB | 720 render-pipeline recipes to compile ahead (223 KB, 425 recipes, for the low profile) |
data/manifest.json | 393 KB | the game folder: 5,814 paths, sizes and dates |
data/bootset.json | 193 KB | the byte ranges the engine reads while booting: 2,918 files, 582 MB |
data/** | 20.9 GB | the game files themselves |
Reading it was a pleasure I did not expect. Apart from game.js, the JavaScript is unminified and commented like a lab notebook. The comments name the porter's own tools (phase3/make_shader_pack.py, pipeline_seed.py, record_bootset.py, a PHP host at phase3/host/index.php) and the C++ file on the other side of each interface (wgpu_backend.cpp, httpfs_wasm.cpp, userdata_wasm.cpp, browser_input_wasm.cpp). They also record measurements, with dates. Several are dated 6 October, the day 10,000 visitors overloaded the host. The GPU worker even runs unchanged under Node with Google's Dawn, and a default path of D:/wasm_build/... gives away that this is how the porter takes headless screenshots on a Windows dev box.
Rockstar's function names, left in
An emulator would ship a console's CPU interpreter and a disc image. Cloud gaming would ship a video decoder and a WebRTC connection. I found neither, and I could prove it without running anything, by parsing game.wasm's sections. Code is 48.2 MB and data 7.8 MB, with 91,026 functions defined and 86 imports. Another 6.8 MB is the name section, which shipped builds usually strip, and it gives the game away.
It lists 91,111 function names. 41,286 of them contain rage::, the namespace of Rockstar's RAGE engine. The rest read like a tour of the game's scripting API: 1,865 handlers in network_commands, 1,606 in vehicle_commands, 1,392 in ped_commands, 1,162 in hud_commands. Those are the natives GTA V's mission scripts call. The audio code includes rage::audDecoderPcm, rage::audDecoderAdpcm and rage::audDecoderOpus. One namespace, wasm_null_d3d, belongs to the port, and it turns out to be the whole graphics story.
The strings agree. Assertion messages carry the build machine's source paths, for example E:/P1/GTA5/SRC/DEV_NG\RAGE\BASE\SRC\net/status.h. DEV_NG is the next-gen branch, the one the PC version came from.
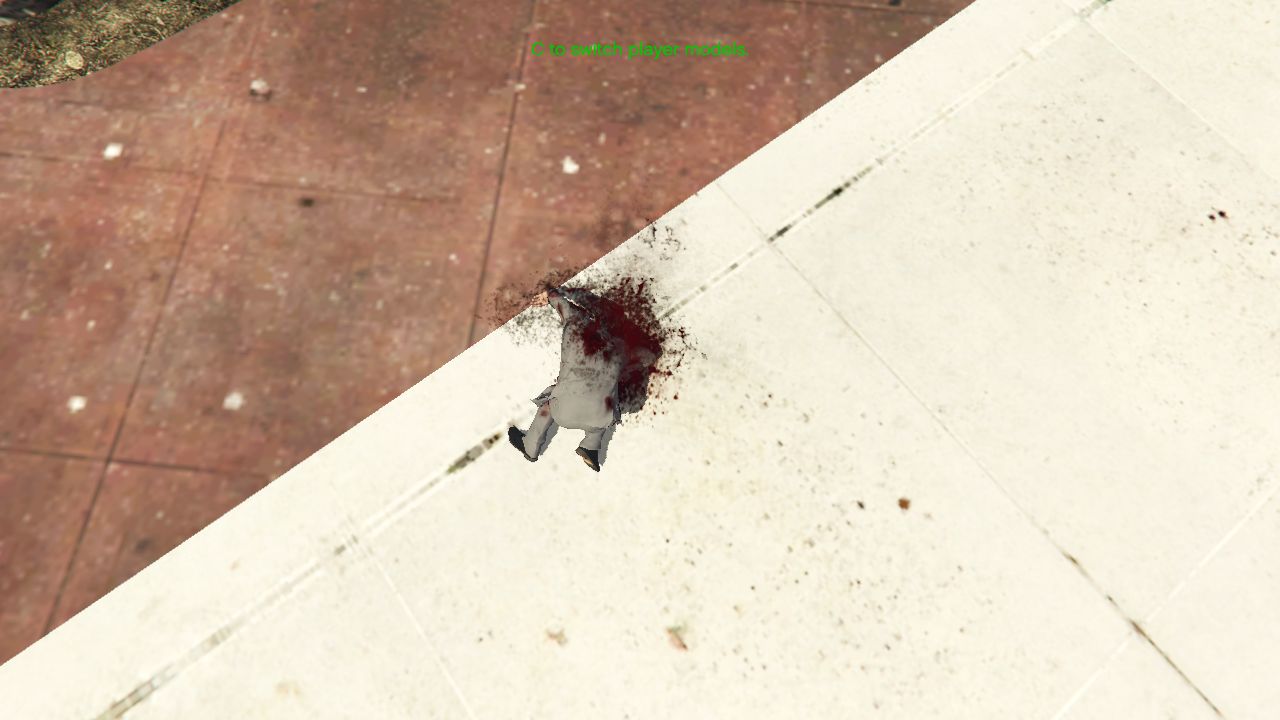
So a compiler built this from C++ source. It was also a development build, and it shows. The engine starts a thread called BugstarAssertLogging, after Bugstar, Rockstar's internal bug tracker. The page warns that "this build has debug key bindings", and in the env_test map a green debug prompt reads "C to switch player models". The page also passes -fastscriptcore, because without it "this build runs the debugging core, which looks up two breakpoint tables for every script instruction (scrThread::Run was ~8 % of the main thread)".
The memory declaration explains why this needed wasm64 at all. The module imports one memory with flags 0x7, meaning it has a maximum, it is shared between threads, and it is 64-bit. The minimum is 49,152 pages and the maximum 262,144; at 64 KB a page, that is a 3 GB starting heap and a 16 GB ceiling. game.js creates it like this:
var INITIAL_MEMORY = 3221225472;
wasmMemory = new WebAssembly.Memory({ initial: BigInt(INITIAL_MEMORY / 65536), maximum: 262144n,
                                      shared: true, address: "i64" });
Classic 32-bit WebAssembly stops at 4 GB, and a 2013 PC game sized for 8 GB machines does not fit in it. Once the world was up in my run, the engine reported a 2,444 MB malloc arena with 2,405 MB of it in use. The price is that every pointer crosses into JavaScript as a BigInt and every address sits above 3 GB. That second fact caused one of the port's best bugs, which I come back to in the graphics section.
What is in the 20.9 GB
The manifest lists the whole folder the engine sees as /game/. In the tree below, each bar is a folder's share of its parent, and the green part is what the recorded boot set reads before the world appears.
The same tree in numbers:
| Folder | Size | Files | What it holds |
|---|---|---|---|
x64/levels/gta5 | 8.68 GB | 1,383 | the GTA V map: _hills 3.95 GB, _citye 1.16 GB, _cityw 0.93 GB, _prologue 0.44 GB, scripts 0.43 GB, vehicles 0.34 GB, interiors, props, navmeshes |
x64/levels/env_test | 5.49 GB | 259 | the second map the page calls "GTA VI Map": countryside, co1, sb, sn, nb, dn and 30-odd more blocks |
x64/models/cdimages | 2.50 GB | 40 | characters: streamedpeds_players.rpf alone is 532 MB |
x64/audio/sfx | 1.88 GB | 54 | sound banks: interactive music 472 MB, cutscene audio 153 MB, 19 radio station banks at 7-52 MB each |
x64/anim | 0.84 GB | cutscene and in-game animation | |
x64/dlcPacks | 0.58 GB | 11 packs (see below) | |
common/shaders | 0.32 GB | 1,134 | compiled effects in three variants: win32_40, win32_40_lq, win32_nvstereo |
common/data | 0.22 GB | XML and metadata: AI, timecycles, glass, scripts, paths | |
common/non_final | 0.04 GB | cutscene lighting tunes (.lightxml) and animation data |
By type, 1,528 .rpf archives are 20.30 GB of the 20.94 GB. After them come 1,134 .fxc shader effects (316 MB), 990 .xml files (174 MB, one of them a 145 MB paths.xml), 493 .lightxml, 470 .ymt, 376 .meta, 146 .dat and 65 .ytd texture dictionaries.
Cracking a few files open
I wanted to know whether the porter had repacked anything, so I fetched a few sample files with Range requests and read their headers. I decrypted nothing.
The archives answered the question straight away. x64/levels/gta5/vehicles.rpf starts 37 46 50 52, which is RPF7, with 953 entries and encryption tag 0x0FFFFFF9. That tag marks a table of contents encrypted with Rockstar's AES key, exactly as on a retail PC install. The archives go over the wire byte for byte as Rockstar packed them, and the engine in the browser decrypts them itself with the keys compiled into it. Nothing was repacked or recompressed.
The loose files are ordinary RAGE formats. x64/models/skydome.ydd, a drawable dictionary, starts RSC7 with resource version 165; its 10,941 bytes inflate with raw deflate to 32,768 bytes, exactly the virtual size its page flags declare. x64/textures/graphics.ytd is RSC7 version 13, a texture dictionary. Shaders are Rage effects: common/shaders/win32_40/postfx.fxc starts rgxe and lists its programs by name (VS_Passthrough, dofProj, dofShear...), and the DXBC bytecode inside is what the port translated to WGSL. Metadata is binary PSO, so x64/data/metadata/statsmgr.ymt starts PSIN.
Audio took longer to pin down. x64/audio/tracks/admin_gun.awc starts ADAT, a multichannel stream: two channels at 48,000 Hz, 4,713,599 samples each (98.2 s), in 16 blocks of 32,768 bytes, with codec id 12. Ninety-eight seconds of stereo music in 512 KB works out to about 43 kb/s. 16-bit PCM would need 1,536 kb/s and ADPCM about 384 kb/s. The engine carries an Opus decoder (rage::audDecoderOpus), and 43 kb/s is Opus territory. I never confirmed what codec id 12 maps to, so I would call it very likely Opus and leave it there.
Then the dates. x64/metadata.dat begins META2015-02-06T19:40:44, a build from February 2015, two months before the PC release. The 145 MB common/data/levels/gta5/paths.xml is a raw export from 3ds Max, with the artist's x:/gta5/art/... source path and a timestamp of 31 July 2014. A retail game does not ship files like that.
Where "700 MB" comes from
The viral number folds two questions together: why the folder is 20.9 GB and not 100, and why a session downloads only a few hundred megabytes of it.
The first has a dull answer. The PC version shipped at 65 GB on seven discs in 2015 and has grown since with years of GTA Online updates. This folder is a development snapshot from February 2015, and the manifest shows what it leaves out. There are 11 DLC packs, 0.58 GB in all (mpBeach, mpBusiness, mpBusiness2, mpChristmas, mpHipster, mpIndependence, mpLTS, mpPilot, mpValentines, spUpgrade and verityRadio), which is roughly the content through mid-2014 and none of the GTA Online updates that followed. There are zero .bik files, and the engine's Bink video thread is one of the threads the port never starts. The whole x64/audio tree is 1.93 GB, and the one music track I decoded runs at about 43 kb/s. Meanwhile the folder adds env_test, 5.49 GB that retail does not have, so GTA V's own content here is about 15.4 GB.
I have not diffed it against a retail install, so I cannot tell you file by file what got smaller and why. I can tell you it is not the retail game repacked.
The second question is where the engineering is. A session never downloads the 20.9 GB at all. It downloads the blocks the engine reads, 4 KB at a time. In my run that was 743 MB before the world appeared, about 3.5% of the folder, and most of it was the boot set, which bootset.json lets me break down:
| Part of the boot set | Bytes | Why |
|---|---|---|
.rpf archives | 433 MB | 997 of the 1,192 archives it touches are read for under 64 KB each: their headers and tables of contents |
.fxc shader effects | 100 MB | 349 of the 379 win32_40 effects, fetched whole in compressed batches |
x64/levels/gta5 | 258 MB | the map's archive headers and the start-up area |
x64/models/cdimages | 112 MB | character model archives |
| everything else | the rest | texture dictionaries, metadata, AI data, timecycles |
The rows overlap, because the level and model bytes are mostly .rpf bytes. What surprised me is how cheap mounting is. The engine mounts about 1,200 archives at boot and reads only each one's table of contents, "median 3 KB, 4.9 MB for all of them" according to the IO worker's comments. After the boot set, the page's comments put the world at "about 1.2-1.4 GB the first time". At the spawn point I got, it needed far less. Walk or drive somewhere new and more streams in.
Getting the engine off the main thread
A game engine assumes it owns its threads. It blocks on mutexes, sleeps, spins and waits for the GPU. A browser's main thread is allowed to do none of that, so the port gives the page almost nothing to do and runs the engine entirely in workers.
index.html transfers the canvas to an OffscreenCanvas, decides on the low-memory profile, builds the engine's command line and starts loader.js in a worker. After that the page keeps only input, audio start-up and the title screen.
The first thing loader.js does is create the GPU worker and the IO worker, and the comment gives a reason I would not have guessed: "Chrome fetches the script of a worker nested in a worker through the parent's event loop", and this worker's event loop is about to be blocked forever. The IO worker starts prefetching the boot set at once, in parallel with the engine download. The download itself compiles as it streams:
const streaming = async () => {
  const res = await fetchWasm();             // retries 503/500/429 eight times
  const counter = res.clone().body.getReader();  // count bytes on a clone for the progress bar
  ...
  return WebAssembly.instantiateStreaming(res, imports);
};
Streaming compilation means no wait after the last byte, no second 63 MB copy, and Chrome can cache the compiled code for the next visit.
Then loader.js calls importScripts('game.js'). Static constructors and main() run right there, and the game loop takes the worker over for good, which is fine because nothing else lives on it. Since this "main" thread is a worker, Emscripten's glue sets can_block = !ENVIRONMENT_IS_WEB to true, so the engine's main loop can Atomics.wait like any other thread and never return to an event loop. Emscripten also pre-spawns a pool of pthread workers, min(160, 36 + 4 × cores) of them, or 28 at two cores or fewer. Each runs the same game.js against the same shared memory.
The command line the page builds, trimmed:
args: ['-rootdir=/game/', '-wgpu', '-nodisplaycalibration', '-noSocialClub', '-pc:nosocialclub',
       '-nonetwork', '-output', '-width=' + w, '-height=' + h, '-forceResolution',
       '-Script_all=warning', '-replay_all=warning', '-fastscriptcore', '-frameLimit=1', ...]
-nonetwork and -noSocialClub remove the online layer. The two log-level flags are there because scripts and replay produce "~87 % of all log lines in play". -frameLimit=1 is a 60 fps cap.
Not every engine thread gets to run. 75 started in my run, and the port's thread wrapper skipped 18: the hang-detect watchdog, Bink video, the TCP and netThrPool network workers, HttpQuery, Bugstar logging, Fwd Thread, Back Thread and six replay-recording threads. ?keep=replay,net,bink,idle brings groups back, as a bit mask the C++ side reads through one of the port's JS imports. In place of the watchdog, the port has its own hang detector, which prints which thread is waiting on which semaphore when the engine goes quiet. My logs have several.
Pretending to have two cores
Threads cost memory, and that drives the biggest decision the page makes about your device. Every engine thread is a worker of about 20 MB, and RAGE sizes its pools from the core count. When navigator.deviceMemory reports 4 GB or less (browsers cap the report at 4 for anything at or under 4 GB), the page tells the engine there are 2 cores, which by its own comment gives 54 threads instead of 80 to 116. The same profile quarters texture memory, drops ped and vehicle variety, city density and LOD to minimum, and turns shadows off:
const LOW_ARGS = ['-textureQuality=0', '-pedVariety=0', '-vehicleVariety=0',
  '-shadowQuality=' + (q.get('shadows') === '1' ? 0 : -1), '-reflectionQuality=0',
  '-particleQuality=0', '-grassQuality=0', '-cityDensity=0', '-lodScale=0',
  '-pedLodBias=0', '-vehicleLodBias=0'];
The porter measured it in a Node run: "GPU memory 1.16 GB -> 0.5 GB and streamed assets 1.38 GB -> 0.95 GB". Shadows went because the cascade shadow pass was "a third of all draws (Node, 1366x600: 600-900 of 1,300-2,900 per frame), and a 4-core Chromebook spent ~110 us per draw".
The rule that holds it together
Once I saw this rule, the rest of the code read easily: engine threads never call a browser API that has to yield. fetch, WebGPU and audio are all asynchronous, and a C++ thread blocked in Atomics.wait never gets back to an event loop to receive their callbacks. So JavaScript workers with ordinary event loops do the asynchronous work, and the engine talks to them only through structures in shared memory.
There are four of those structures. Input is 256 key bytes indexed by Windows virtual-key codes, then int32 words for mouse x and y, deltas, wheel, buttons, focus, pointer lock and a 64-entry text ring; the page writes them with Atomics.store and the engine reads them like a keyboard driver. Graphics is a 32 MB ring of commands with a 16-word header (head, tail, state, counters, a "sleeping" flag) and fence words the engine waits on. Files go through a table with a doorbell, one 16-word slot per engine thread, and a ring of read hints. Audio is a ring of interleaved float stereo samples with write, read, capacity and heartbeat words.
Each worker is the only owner of its browser API, and every handoff is a word in shared memory flipped atomically. That keeps the JS imports the port adds to the engine tiny. Most of them just hand an address to a worker:
function wasm_httpfs_io_start_js(table) {
  if (ENVIRONMENT_IS_PTHREAD || !Module["ioWorker"] || Module["__ioStarted"]) return;
  Module["__ioStarted"] = true;
  Module["ioWorker"].postMessage({ memory: wasmMemory, table: Number(table) });
}
A file system made of HTTP requests
The engine's file layer was redirected in platform/file/httpfs_wasm.cpp so that every read of a file under /game/ becomes a request to the IO worker. At start-up the engine fetches the manifest with a synchronous XMLHttpRequest, which tells it every path and size. After that, each read goes through the slot table. The widget follows one read end to end, with the IO worker's real code:
The C++ thread fills its slot (file id, 64-bit offset, destination address, length), sets the state to 1, rings the doorbell and blocks. The IO worker sits parked on the doorbell with Atomics.waitAsync. It claims the slot with a compare-and-swap from 1 to 3, works out which 4 KB blocks of the file are missing, and fetches only those with Range requests. As the bytes arrive it writes them into its disk store and copies them straight into the engine's buffer in the wasm heap. Then it writes the byte count, flips the state to 2 and calls Atomics.notify. The C++ thread wakes up inside what it believes was an ordinary read().
The disk store
I expected IndexedDB or the Cache API. The store is two files in the Origin Private File System, opened with synchronous access handles, the one storage API in the browser that reads and writes like a file descriptor. store.bin is append-only: a fetch reserves room at the end and streams the body into it. journal.bin records where each block went, in 16-byte entries of file id, block number and a 64-bit offset, and it is written only after the data has been flushed. Its header carries the manifest version, so a new game build starts with an empty store.
const root = await navigator.storage.getDirectory();
const dir = await root.getDirectoryHandle('gamedata', { create: true });
const s = await (await dir.getFileHandle('store.bin', { create: true })).createSyncAccessHandle();
...
sh.flush();        // the data first, then the entries that point at it
jh.write(new Uint8Array(buf.buffer), { at: journalEnd });
On the next visit, blocks already stored cost nothing. Sync access handles are exclusive, so a second tab runs without the store, on a 48 MB in-memory cache.
The comments keep the history of how the IO worker got here, and I learned more from the dead ends than from the final design. The first version did synchronous XHR from each engine thread, behind a service worker that cached blocks. Every response is a fresh ArrayBuffer, freed only when that worker's garbage collector runs, and a worker that lives inside wasm or inside Atomics.wait almost never runs it. The bytes piled up as "~1.5 GB of renderer memory", and the service worker added "another ~0.9 GB of its own".
The second version tried 256 KB blocks, then 16 KB blocks with a growing read-ahead. Both were the wrong size for boot, when the engine reads only each archive's table of contents (median 3 KB). Big blocks made "the boot download 25x larger for those files".
What survived is 4 KB blocks streamed into the store with no JavaScript buffers kept, read-ahead only for large sequential reads, and every copy going straight from the store into the shared heap (sh.read(HEAPU8.subarray(...))).
Why your fibre connection does not help
The host answers a Range request at a few hundred KB/s per stream, whatever the visitor's link. The porter timed it: "one stream through the host moves ~0.15 MB/s after its round trip of ~0.6 s", and a single 512 KB read took 2-5 s. Throughput tracks how many streams are in flight, and the porter measured that too:
At 128 in flight the host delivers 14.1 MB/s and the boot set takes about 41 s. At 6 in flight it is 3.4 MB/s, and the boot set takes nearly three minutes. A faster connection barely moves the first load. More requests do.
So every fetch path in the IO worker is built to keep many requests open. The boot set goes out in 32 lanes of Range requests plus 4 lanes of compressed batches. Small compressible files (.fxc, .meta, .xml, .dat, .ymt...) up to 8 MB travel whole, up to 300 per POST to /data/batch, and come back gzipped through DecompressionStream. The boot set is the same for every visitor, so the host saves each batch as a static file named after the SHA-1 of its request, which Cloudflare can then cache. Ranges within 64 blocks of each other are merged.
A read the engine is blocked on gets different treatment. It is cut into 128 KB slices fetched side by side at priority: 'high', so eight slices in parallel finish in about a second where one stream took 2-5 s for 512 KB. Everything speculative (the boot set, read-ahead, hints) runs at priority: 'low', because before that change "engine reads waited up to 6.6 s behind 32 prefetch streams".
The hints are my favourite part of the port. RAGE's streamer queues reads and performs them one at a time on one thread, which at one round trip each came to "~3 reads/s". The port makes the streamer announce its queued reads in a ring in shared memory, and the IO worker fetches up to 96 of them ahead, plus 48 more for look-ahead at objects the engine has requested but not queued yet. By the time a demand read arrives, its blocks are usually stored or in flight. It is a small change to the engine that turns a serial queue into a parallel one.
Radio needed a rule of its own. Stations are read as ~33 KB blocks one after another, each a round trip with nothing queued behind it, so RADIO_*.rpf reads count as sequential and get read-ahead regardless of size.
At 10,000 visitors a day, failure is routine. Every fetch retries 503, 500 and 429 answers up to 8 times with jittered backoff over about 20 s, because "the engine quits when a data file cannot be read". A file that turns out shorter on the server than the manifest says is shrunk in place, because "the engine retries a failed read forever".
Savegames take a different route. When the engine settles a file under /userdata/Documents, the IO worker stores it in IndexedDB (gta5-userdata). The OPFS store would be the wrong place: it is exclusive to one tab and thrown away when the game data changes. loader.js puts the saves back into the engine's in-memory /userdata before main(), and gives up after 8 s "so a broken IndexedDB cannot keep the game from starting". A failed save is always logged, on the grounds that "a lost save is worth a line".
Direct3D 11, replayed on WebGPU
I assumed the renderer had been ported to WebGPU. Nobody touched it. The engine still creates a Direct3D 11 device, and in this build that device is fake: the function names show wasm_null_d3d::NullDevice, NullContext, NullSwapChain, NullResource and friends implementing D3D11's COM interfaces. Every call becomes an opcode plus payload words in a 32 MB ring in shared memory. wgpu_worker.js is the other end, and its header explains the split better than I could:
// Why a separate worker and not calls from the game's render pthread:
//  - WebGPU objects cannot cross threads, but D3D11 resources are created by any engine thread
//    (streaming, main, render). The game threads only emit commands; every WebGPU object lives here.
//  - WebGPU is asynchronous (device creation, mapAsync, onSubmittedWorkDone); this worker has a normal
//    event loop, the game's blocking C++ threads never have to yield to JS. They wait on a futex/fence
//    word in the ring when they need a result (readback, occlusion query).
The ring
Each command is two header words (opcode, payload length) followed by the payload. The 48 opcodes are D3D11 almost one for one: CREATE_TEXTURE, CREATE_BUFFER, UPLOAD_BUFFER, UPLOAD_TEXTURE (with the bytes inline in the ring), CREATE_SHADER, CREATE_LAYOUT, CREATE_STATE, CREATE_SRV, CREATE_UAV, SET_SHADER, SET_VERTEX_BUFFERS, SET_INDEX_BUFFER, SET_CBUFFERS, SET_SRVS, SET_SAMPLERS, SET_RENDER_TARGETS, SET_BLEND, SET_DEPTH_STENCIL, SET_RASTER, SET_VIEWPORTS, SET_SCISSORS, DRAW, DISPATCH, CLEAR_RT, CLEAR_DS, CLEAR_UAV, COPY_REGION, COPY_RESOURCE, RESOLVE, GENERATE_MIPS, READBACK, CREATE_QUERY, BEGIN_QUERY, END_QUERY, FENCE, PRESENT, plus WRAP, NOP and a few more. The consumer loop:
async function runCommands(tail, head) {
  while (tail !== head) {
    const base = ringW + (tail >> 2);
    const op = u32[base], n = u32[base + 1];
    if (op === OP.WRAP) { tail = RING_DATA; continue; }
    switch (op) {   // numeric labels: V8 compiles constant Smi cases to a jump table
      ...
    }
    tail += n * 4 + 8;
    if (++sinceYield >= 512) {
      Atomics.store(i32, ringW + 1, tail);   // let the producers reuse the ring space already consumed
      Atomics.notify(i32, ringW + 1);
      if (performance.now() - lastYieldT >= 2) { await yieldTask(); refreshViews(); ... }
    }
  }
  return tail;
}
When the ring runs dry, the worker sets the "sleeping" flag in header word 5, re-reads the head so it cannot miss a command published in between, and sleeps on Atomics.waitAsync(head, tail, 100). Producers notify only while that flag is set. When the ring fills up, the engine threads block on the tail word, and the C++ side books that time as "ring full".
Two bugs from this loop are worth retelling.
The first was a 25 fps ceiling that had nothing to do with rendering. WebGPU's completion callbacks (onSubmittedWorkDone, mapAsync) arrive as macrotasks, and the command loop only ever awaited promises that had already resolved. Under load the event loop never got a turn, so fences completed late, and "the engine polled them for ~25 ms per frame (a flat 25 fps with the worker half idle)". The fix, yieldTask(), is a MessageChannel round trip: a cheap macrotask boundary, taken at most every 2 ms.
The second is the one the 3 GB heap set up. Every address the engine hands over is above 2 GB, and JavaScript's >> is a signed 32-bit shift. In the porter's words, "every address at or above 2 GB ... became a negative index; event queries (the engine's GPU fences), occlusion queries and readback flags then never completed". Every index is now Math.floor(addr / 4). I would have lost days to that one: nothing crashes, the GPU just never seems to finish.
Resources
The worker keeps objects in a plain array indexed by id. Ids come from one counter and are never reused, and "a draw looks up ~15 objects, and an element load is several times cheaper than Map.get". Never reusing ids pays off a second time further down: any cache keyed on an id can never alias a different object.
Formats go through a table from DXGI numbers to WebGPU formats. Block-compressed textures map directly, bc1 through bc7, which needs the texture-compression-bc feature. Depth formats become depth24plus-stencil8 or depth32float(-stencil8). Typeless formats get whatever the game most plausibly views them as, with sRGB view formats added. One format has no WebGPU equivalent: A8_UNORM, an alpha-only texture, which is expanded to RGBA8 on upload because "there is no texture swizzle in WebGPU".
Constant buffers never become GPU buffers. They live in a CPU-side shadow array and are copied per draw, which comes up again with shaders. Uploads to other buffers keep D3D11's semantics. If a draw already recorded in the open encoder still reads a buffer, the encoder is submitted before the write, so "the earlier draw sees the old data". A Map with NO_OVERWRITE, where the game promises those bytes are unused, skips that flush.
Shaders
Rockstar ships compiled DXBC bytecode and no HLSL source, so there was nothing to recompile. The port translated every shader offline to WGSL and serves them from shaders/index.json, keyed by the FNV-1a 64 hash of the DXBC and bundled into packs by effect, so that a browser makes "~20 requests instead of one or two per shader (~6,000 in a session, each a round trip: minutes against a distant host)". I counted the index:
| Stage | Shaders | Translated |
|---|---|---|
| pixel | 3,667 | 3,667 |
| vertex | 1,112 | 1,112 |
| compute | 31 | 29 |
| domain | 71 | 0 |
| geometry | 20 | 0 |
| hull | 18 | 0 |
| total | 4,919 | 4,808 |
The translated ones come to 72 MB of WGSL in 18 packs, about 4.2 MB each. The zeros are not for lack of effort: WebGPU has no geometry, hull or domain stage. The 109 shaders in those stages are tessellation and the geometry-shader paths of instanced shadows (GS_ShadowInstPassThrough in the cloth effects, for example), so those effects fall back to the engine's other paths or go without.
I pulled a real one out of pack0 by its offset in the index, the vertex shader VS_PassthroughComposite of the adaptiveDof effect:
diagnostic(off, derivative_uniformity);

var<private> r0 : vec4<f32>;

struct cb10_struct {
  tint_symbol : array<vec4<f32>, 10u>,
}

@group(0u) @binding(7u) var<uniform> cb7_7 : cb10_struct;

var<private> o0 : vec4<f32>;
var<private> o1 : vec4<f32>;

fn main_inner(v0 : vec2<f32>) {
  let v = (v0 * cb7_7.tint_symbol[9u].xy);
  r0 = vec4<f32>(v.xy, r0.zw);
  let v_1 = fma(r0.xy, cb7_7.tint_symbol[7u].xy, cb7_7.tint_symbol[7u].zw);
  o0 = vec4<f32>(v_1.xy, o0.zw);
  o0 = vec4<f32>(o0.xy, vec2<f32>(0.0f, 1.0f));
  o1 = fma(v0, cb7_7.tint_symbol[8u].xy, cb7_7.tint_symbol[8u].zw).xyxy;
}
...
@vertex
fn main(@location(0u) v0 : vec2<f32>) -> tint_symbol_1 {
  main_inner(v0);
  return tint_symbol_1(o0, o1);
}
You can read the translation straight off it. r0, o0 and o1 are DXBC's temporary and output registers, kept as private variables. The constant buffer is register b7 as an array of vec4s, which is how DXBC addresses constants. The tint_symbol names are what Tint emits, the WGSL compiler in Chrome's Dawn, so Tint wrote this WGSL. Bindings follow a fixed scheme: constant buffers by register, samplers at 16 plus the register, textures at 32 plus the register, UAVs at 160 plus, and their hidden counters at 176 plus. The vertex shader's resources go in group 0 and the pixel shader's in group 1.
At load time the worker rewrites that WGSL once more, to get under a limit. D3D11 shaders use up to 7 constant buffers per stage, and WebGPU allows 10 dynamic-offset uniform bindings per pipeline layout across all stages. So every stage's constant buffers are merged into one struct at binding 0:
// Every stage's constant buffers ... are therefore merged into ONE struct bound at binding 0 with
// one dynamic offset: `cbN_x` -> `cbpack_v.cbN_x`. The runtime copies the bound D3D constant buffers
// back to back into the uniform ring, in binding order, one 16-byte aligned block per member.
for (const m of members) out = out.replace(new RegExp('\\b' + m.name + '\\b', 'g'), 'cbpack_v.' + m.name);
const struct = 'struct cbpack_t {\n' + members.map((m) => '  ' + m.name + ' : ' + m.type + ',').join('\n')
  + '\n}\n@group(' + group + 'u) @binding(0u) var<uniform> cbpack_v : cbpack_t;\n';
Each draw then copies the bound constant buffers' shadows into a uniform ring. The copies land in a JavaScript mirror of the ring and reach the GPU as one writeBuffer per 8 MB chunk at the next submit, because "a queue.writeBuffer per draw was ~10 % of the worker's time at 1,700 draws per frame". The entries of that constant pack are recycled in place as well; the ~6 short-lived objects per draw they replaced had cost about 14% of the worker in garbage collection. The ring has three frame slots, so two frames can be in flight. With fewer, Chrome's round trip to the GPU process, "not the work, capped the frame rate".
Where the two APIs disagree
A translation layer gets interesting only where the two sides disagree, and the GPU worker has a comment at each of those places, usually naming the symptom that gave it away.
The hardest is depth read as colour. D3D11 lets a shader Load a depth texture as if it were a float texture, and WebGPU will only bind it as depth. So the worker keeps an r32float proxy of each such depth texture (or r8uint for stencil) and refreshes it with a render pass whenever the depth was drawn into. The opposite case exists too: SampleCmp on a float texture gets a depth32float copy, drawn by a full-screen triangle that writes frag_depth.
The one with the worst symptom is reading past the end of a buffer. D3D11 returns zeros there, for vertex and index buffers alike. WebGPU rejects the draw, and "an invalid draw invalidates the whole command buffer: every draw of that submit is lost (seen in play: a frame's 3D vanished while the UI, submitted later, kept drawing over the stale image)". The worker now clamps counts to what the bound buffers hold and binds a 4 KB buffer of zeros to every unbound vertex slot.
Occlusion is a compromise, and the comment admits it. Dawn's D3D12 backend reports occlusion as 0 or 1, but the engine compares sample counts with pixel thresholds like > 100. So a visible query is reported as 65,536 samples: "visibility tests work, partial-visibility fades (flares) saturate".
Grass has its own fix. GTA's grass shaders rely on D3D's alpha-to-coverage on single-sample targets in place of clip(). WebGPU honours alpha-to-coverage only with MSAA, so the worker compiles a variant that inserts if (o0.w < 0.5f) { discard; }.
The rest are small and mechanical. D3D's SV_VertexID excludes the draw's base vertex and WebGPU's vertex_index includes it, so the offset is folded into the vertex buffer binding, but only for the shaders that read the IDs: 6 read the vertex ID and 93 the instance ID, of about 4,800. Some GPUs allow only 16 inter-stage variables (the comment names a Chromebook's Intel GPU), and Dawn's Vulkan backend counts clip distances against that limit; shaders for "cables, particles, clouds, the _DOF variants, vehicle parts" wrote location 15 next to a clip distance and failed, so outputs at or above the limit are moved to free low locations in both stages. HLSL declares nointerpolation only on the pixel shader's input, WebGPU wants both stages to agree, and vertex shaders get a variant with @interpolate(flat). Border addressing does not exist in WebGPU and becomes clamp-to-edge, and MipLODBias is ignored. Both are counted in an "approximations" report.
Pipelines without holes
A render pipeline compiles on first use, and a synchronous compile makes everything submitted after it wait: "tens of ms per pipeline, hundreds of new pipelines when a new area streams in: the hitches". So the worker compiles with createRenderPipelineAsync and skips the draws whose pipeline is still compiling. On a slow machine that showed up as white holes: "a 4-core Chromebook: ~250 pipelines for the first view of the world took seconds, 28,000 draws skipped in one second".
The fix is to know the pipelines in advance. Every pipeline is also keyed by a recipe: shader hashes, input layout, strides, topology, the raw blend, depth and raster state words, and target formats. The site ships a seed of 720 recipes recorded by the porter's Node harness (pipelines.json), and each browser adds the recipes it meets to IndexedDB (gta-pipelines, up to 6,000). While the game loads and the worker is idle, recipes whose shaders have arrived are compiled ahead, a few at a time. My cold run logged "title screen held 19.3 s for compiling pipelines ... compiled ahead 719, used 159, compiled when first drawn 37". It compiled 719 to use 159, so on a first visit most of the seed is insurance; only 37 pipelines slipped past it and were compiled when first drawn.
Looking a pipeline up has to be cheap, because it happens whenever any pipeline state changes, which is most draws. The key is a tuple of small integers hashed to a 30-bit number:
let h = n * 0x9e3779b1;
for (let i = 0; i < n; i++) { h = Math.imul(h ^ T[i], 0x85ebca6b); h ^= h >>> 13; }
h &= 0x3fffffff;   // a small integer (Smi): a full 32-bit key would be a heap number,
                   // allocated and hashed as a double on every lookup
The string key it replaced "took ~15 % of the worker". Bind groups got the same treatment, cached by an FNV hash of the resource ids in binding order. String keys there "were ~40 % of stageBindGroup", and a fast path now revalidates the previous group by comparing a few ids instead of rebuilding it. The cache is trimmed to 24,000 groups, because "in a long session that exhausted the descriptor heaps (CreateDescriptorHeap failed with E_OUTOFMEMORY, device lost, black screen)": the cache was keeping dead groups alive after streaming had destroyed their textures.
The same hunt for per-draw overhead shows up in smaller places. GPUBuffer.size is cached in JavaScript, because the native getter called on every draw cost about 5% of the worker. And the executed-command counter is published every 512 commands, which you can see in the loop above, because an atomic add per command was measurable at ~25,000 commands per frame.
Presenting a frame
Render passes begin only when the set of render targets changes, with loadOp: 'load' everywhere, since D3D clears are separate passes. At PRESENT a full-screen triangle copies the game's back buffer onto the canvas, the encoder is submitted, and the worker waits for the frame slot it is about to reuse. Readbacks are submitted immediately ("deferring the submit to the present made it wait 50-300 ms") and land directly in the engine's staging memory in the heap, followed by an Atomics.notify.
Input, audio and a 1 ms timer
The remaining pieces are small, and each is a place where the browser leaked into a game that never expected one.
Input first. The page maps DOM key codes to the Windows virtual-key codes the engine expects and writes them into the input block:
addEventListener('keydown', (e) => {
  ...
  const vk = VK[e.code];
  if (vk) Atomics.store(keys, vk, 0x80);
  ...
});
Most laptops have no numpad, so I/K/J/L/U/O are aliased to the numpad keys GTA uses for aircraft pitch, roll and targeting. The mouse uses pointer lock with unadjustedMovement, and wheel deltas are converted to notches because "Chrome reports ~100 px per notch on Windows".
Audio is the simplest worker in the port. The engine's mixer writes into a ring, and an AudioWorklet copies 128 frames per callback and plays silence on underrun. This is the whole processor:
process(inputs, outputs) {
  const out = outputs[0], left = out[0], right = out[1] || out[0], n = left.length;
  const read = Atomics.load(this.hdr, 1), write = Atomics.load(this.hdr, 0);
  const avail = (write - read) >>> 0, take = Math.min(avail, n);
  for (let i = 0; i < take; i++) {
    const at = ((read + i) & this.mask) * 2;
    left[i] = this.data[at];
    right[i] = this.data[at + 1];
  }
  for (let i = take; i < n; i++) { left[i] = 0; right[i] = 0; }   // underrun: silence
  Atomics.store(this.hdr, 1, (read + take) | 0);
  return true;
}
It starts only after the first click or key press, because browsers allow no audio before a user gesture.
The timer was the strangest bug in the whole port. Chrome on Windows rounds every wait with a timeout up to the OS timer tick, 15.6 ms, unless the renderer has a timer under 16 ms pending. The engine's sleeps, its 1 ms event waits and its frame limiter all use Atomics.wait with timeouts. The porter measured "a 1 ms wait takes 15.5 ms; with this timer 2.1 ms", and found the limiter "held a 60 fps cap to 37 fps". The fix is one line on the page:
setInterval(() => {}, 1);It does nothing, except keep Windows on a fine tick.
The porter's ledger
Most changes in the source come with a measurement next to them. Collected in one place, they are the most useful thing in the port for anyone attempting something like it:
| Change | What it replaced | Number quoted |
|---|---|---|
uniform copies into a JS mirror, one writeBuffer per chunk | writeBuffer per draw | ~10% of the GPU worker at 1,700 draws per frame |
| pipeline key as an integer tuple, 30-bit hash | string key per lookup | ~15% of the GPU worker |
| bind-group cache by numeric hash | string keys | ~40% of stageBindGroup |
| recycling constant-pack entries in place | ~6 short-lived objects per draw | ~14% of the GPU worker (garbage collection) |
caching GPUBuffer.size in JS | a native getter per draw | ~5% of the GPU worker |
MessageChannel yield in the command loop | awaiting resolved promises only | a flat 25 fps with the worker half idle |
| executed-command counter published every 512 commands | an atomic add per command | measurable at ~25,000 commands per frame |
| recipe compile-ahead | compile at first draw | 28,000 draws skipped in one second on a Chromebook |
| shader packs | one request per shader | ~20 requests instead of ~6,000 |
| 4 KB blocks into OPFS, no JS buffers | sync XHR + service worker cache | ~1.5 GB + ~0.9 GB of renderer memory |
| table-of-contents-sized blocks | 256 KB / 16 KB blocks | boot download 25x larger for those files |
| parallel slices for blocking reads | one stream per read | a 512 KB read took 2-5 s |
| low fetch priority for speculation | equal priority | engine reads waited up to 6.6 s |
| 96 hinted reads in flight | the streamer's one-at-a-time reads | ~3 reads/s |
-fastscriptcore | the debugging script core | ~8% of the main thread |
| script and replay logs at warning level | full logging | ~87% of all log lines |
setInterval(() => {}, 1) on the page | Windows' 15.6 ms timer tick | 60 fps cap held to 37 fps |
| low-memory profile | default settings | GPU memory 1.16 → 0.5 GB |
What strikes me is how little of it is about the GPU. The time went into JavaScript's per-call overhead, the garbage collector and the event loop. Nearly every fix swaps an allocation or a string for an integer, or a round trip for a batch.
Debugging through the URL
The port is debugged in production through query parameters, and the list doubles as an index of what the porter had to measure:
| Parameter | Effect |
|---|---|
mode=story, mode=sandbox, map=env_test, newgame=1 | skip the start menu, start from the Prologue |
low=1 / low=0, shadows=1, cores=N | force or forbid the low-memory profile, keep shadows, fake the core count |
res=WxH, scale=0.75, fixed=1, fps=30 | back-buffer size, render scale, ignore resizes, 30 fps cap |
keep=replay,net,bink,idle | start engine thread groups that are normally skipped |
slots=N, syncpipelines=1, nopack=1, limits=... | frames in flight, synchronous pipelines, one request per shader, a smaller GPU device |
dbg=1 | draw isolation: run only the first N draws of each frame to find the one that paints an artifact |
shot=N, shotrt=1 | screenshots, and a dump of every render target hunting for NaNs |
log=1, console=1, verbose=1, mem=1, trace=1, record=1 | logging, memory reports, a trace of every file read, recording a new boot set |
nocache=1, nohints=1 | no disk store, no read hints |
shotrt=1 has a story behind it. It was built for a Chromebook that rendered the world white, where "the lighting buffer was ~95 % NaN, which displays as white". It scans one frame draw by draw and logs the first shader that introduces a NaN.
What it costs to run
Memory is the first bill. Every engine thread is a Web Worker of about 20 MB, on top of a heap that starts at 3 GB. A tab that runs out dies with "Aw, Snap!" and cannot say why, so the page runs a watchdog that reports "the device may be out of memory" after 30 s with no progress. It is about the best a page can do.
Draw calls are the second. Every WebGPU call costs "a few microseconds of validation + serialisation", which is why so much of the GPU worker exists to avoid making calls at all. My CPU-rendered frame had 2,736 draws.
Some things are simply missing: tessellation and geometry shaders, border sampling, partial occlusion, network play and video. Every gap has a comment.
And the host was the weakest link. Comments dated 6 October say 10,000 visitors in a day produced thousands of error responses (503, 500, 429). My second run crashed at "Mounting archives" with RuntimeError: unreachable, reported by the page's crash handler. The third reused the blocks the second had stored and reached the env_test world.
Code tour: the shipped files, one at a time
After this piece first went up, the question I got most was whether I still had the files. I do. I saved everything the site served on the morning of 6 October, before it went dark, and I am not going to republish any of it: the JavaScript is the porter's work and game.wasm is Rockstar's engine. What I can do is what the sections above already do, at a larger scale: quote short pieces with their line numbers and say why each one is there.
The excerpts so far were chosen to tell the story. This tour goes file by file and shows what the story skipped. game.js ships as a single 124 KB line, so its line numbers come from a copy I ran through prettier; every other number is the line in the file as served. The explorer holds the same excerpts as the text below it, plus a short card for each data file.
index.html
44 KB and 603 lines, and the only code that runs on the browser's main thread. What struck me is how little it keeps for itself. Line 356 is the gate everything else hangs on:
if (!crossOriginIsolated) { document.getElementById('label').textContent = 'not cross-origin isolated: open the page over https (or localhost); the server sends COOP/COEP'; document.getElementById('label').style.color = '#e66'; }
else {
  const offscreen = canvas.transferControlToOffscreen();
crossOriginIsolated is true only when the server sends COOP and COEP headers, and without it the page gets no SharedArrayBuffer: no shared wasm memory, no threads, no rings. The headers I saved with manifest.json carry both, cross-origin-opener-policy: same-origin and cross-origin-embedder-policy: require-corp, and their absence is exactly why the Wayback copy stops at 5%. The statement right after the check gives the canvas away. From then on the page cannot draw on it, and only a worker can.
Audio is the one job the page cannot hand off, because an AudioContext belongs to a page and may start only after a click or a key press:
const ctx = new AudioContext({ sampleRate: 48000, latencyHint: 'interactive' });
await ctx.audioWorklet.addModule(BASE + '/audio-worklet.js');
const node = new AudioWorkletNode(ctx, 'game-audio', { numberOfInputs: 0, numberOfOutputs: 1, outputChannelCount: [2], processorOptions: audioPending });
node.connect(ctx.destination);
audioPending is a message that came up from the engine: the shared memory and the address of the audio ring. The worklet receives both as processorOptions and reads the mixer's output straight out of the wasm heap, so no sample ever passes through the page. The input handler and the 1 ms timer are quoted in Input, audio and a 1 ms timer, and the command line and low-memory profile in Getting the engine off the main thread.
loader.js
9 KB and 146 lines: a worker whose job ends the moment it calls importScripts('game.js'). Everything that needs an event loop has to happen before then, because it never gets one back. The streaming compile is quoted earlier. Just above it sits the order in which things are created:
const gpu = new Worker(B + '/wgpu_worker.js' + (gq.toString() ? '?' + gq : ''));
const io = new Worker(B + '/io_worker.js');
io.postMessage({ init: true, base: self.location.origin + '/data/', noStore: !!m.noStore, record: !!m.record, trace: !!m.trace, log: !!m.remoteLog, noHints: !!m.noHints, bootset: m.lowMemory ? 'bootset_low.json' : 'bootset.json' });    // starts the prefetch of the boot read set at once    // HTTP reads of all engine threads (platform/file/httpfs_wasm.cpp); same reason to create it up front
let loaded = 0;
io.onmessage = (e) => { if (e.data.loaded && ++loaded === 2) start(); };
gpu.onmessage = (e) => {
  if (e.data.loaded && ++loaded === 2) start();
};
Both helper workers exist, and both have answered loaded, before the engine is even downloaded. The IO worker's first message already names the boot set, so 582 MB of prefetch runs alongside the 63 MB engine download instead of after it, and line 24 picks bootset_low.json when the page chose the low-memory profile.
The retry loop under it is ten lines I would copy into any project that serves large files from a small host:
// An overloaded host answers 503/500/429 (2026-10-06): retried up to 8 times with growing, jittered waits (~20 s in all) instead of compiling an error page.
const fetchWasm = async () => {
  for (let attempt = 0; ; attempt++) {
    let res = null, err = null;
    try { res = await fetch(B + '/game.wasm'); } catch (e) { err = e; }
    if (res && res.ok) return res;
    if (attempt >= 7) { if (res) throw new Error('HTTP ' + res.status + ' for game.wasm'); throw err; }
    bc0.postMessage({ label: 'The server is busy, retrying (' + (attempt + 1) + ')' });
    await new Promise((r) => setTimeout(r, Math.min(5000, 300 * 2 ** attempt) * (0.5 + Math.random())));
  }
};
Eight attempts, a wait that doubles from 300 ms up to a 5 s cap, and every wait scaled by a random factor between 0.5 and 1.5. Without that factor, every tab that failed in the same second would retry in the same second, and a host already answering 503 would get the same spike again. The waits add up to the "~20 s in all" the comment promises.
game.js
124 KB of Emscripten output, with the porter's prejs.js at the top. Most of it is the stock runtime, and two stock pieces explain things the article stated without showing. The first is the thread pool:
initMainThread() {
  var pthreadPoolSize = Math.min(160, navigator.hardwareConcurrency <= 2 ? 28 : 36 + 4 * navigator.hardwareConcurrency);
  while (pthreadPoolSize--) {
    PThread.allocateUnusedWorker();
  }
  addOnPreRun(async () => {
    var pthreadPoolReady = PThread.loadWasmModuleToAllWorkers();
    addRunDependency("loading-workers");
    await pthreadPoolReady;
    removeRunDependency("loading-workers");
  });
On a 16-core machine that is 100 workers, all created before main() runs. Emscripten does this so that a later pthread_create never waits for a worker to load, and here the pool is a necessity. A worker created from loader.js after main() starts would need loader.js's event loop to fetch its script, and that loop never runs again. The run dependency holds main() back until every pooled worker has the compiled module.
The second is one of the 13 imports the porter added. wasm_httpfs_manifest_js(buf, cap) is how the engine learns the shape of the game folder:
  if (bytes === undefined) {
    bytes = null;
    try {
      const x = new XMLHttpRequest();
      x.open("GET", self.location.origin + "/data/manifest.json", false);
      x.send();
      if (x.status === 200) bytes = new TextEncoder().encode(x.responseText);
    } catch (e) {
      console.error("httpfs: manifest failed: " + e);
    }
    globalThis.__httpfsManifest = bytes;
  }
  if (bytes === null) return -1;
  if (cap > bytes.length) {
    (growMemViews(), HEAPU8).set(bytes, Number(buf));
    (growMemViews(), HEAPU8)[Number(buf) + bytes.length] = 0;
    globalThis.__httpfsManifest = undefined;
  }
  return bytes.length;
}
A synchronous XMLHttpRequest, which a worker is still allowed to make, and the only time the engine's file layer touches the network itself. The calling convention is the old C one: return the length, let the caller allocate, copy on the second call. After the copy the JavaScript keeps nothing, and every read from then on goes through the IO worker.
The third is in wgpu_start_worker, the import the D3D11 layer calls once its ring exists:
var transfer = [];
if (Module["canvas"] && typeof OffscreenCanvas !== "undefined" && Module["canvas"] instanceof OffscreenCanvas) {
  msg.canvas = Module["canvas"];
  transfer.push(msg.canvas);
}
The same canvas, transferred a second time. The page gave it to loader.js, the glue kept it on Module.canvas, and here it moves on to the GPU worker, the only thread that ever calls getContext('webgpu') on it. The one-line wasm_httpfs_io_start_js, quoted in The rule that holds it together, does the same for the IO worker with the slot table.
audio-worklet.js
1,496 bytes in 29 lines, the smallest file in the port. Its process loop is quoted above. The constructor shows how the worklet sees the ring:
constructor(options) {
  super();
  const { memory, ring, capacity } = options.processorOptions;
  this.hdr = new Int32Array(memory.buffer, ring, 8);    // word 4: peak sample since the page last looked (x 1e6), diagnostics
  this.data = new Float32Array(memory.buffer, ring + 64, capacity * 2);
  this.mask = capacity - 1;
}
Two typed-array views on the engine's own memory: eight header words, then interleaved float samples from byte 64. The capacity is a power of two, so wrapping around costs a mask. The lines I trimmed from the earlier listing are diagnostics:
let peak = 0;
for (let i = 0; i < take; i++) peak = Math.max(peak, Math.abs(left[i]), Math.abs(right[i]));
if (peak > 0) Atomics.store(this.hdr, 4, Math.max(Atomics.load(this.hdr, 4), (peak * 1e6) | 0));
for (let i = take; i < n; i++) { left[i] = 0; right[i] = 0; }    // underrun: silence
Atomics.store(this.hdr, 1, (read + take) | 0);
Atomics.add(this.hdr, 3, 1);
Word 4 keeps the loudest sample since the page last looked, and word 3 counts callbacks. With ?mem=1 the page logs both every 5 s. A game that has gone quiet and a worklet that has stopped running sound exactly the same, and these two words tell them apart.
io_worker.js
41 KB and 644 lines. The read path is in the widget further up, and opening the store and writing the journal are in The disk store. Two parts were missing. The first decides whether the blocks from your last visit can be trusted:
const head = new DataView(new ArrayBuffer(16));
let ok = false;
if (j.getSize() >= 16) {
  j.read(new Uint8Array(head.buffer), { at: 0 });
  ok = head.getUint32(0, true) === 0x4a415449 && head.getFloat64(8, true) === version;
}
if (!ok) {
  s.truncate(0); j.truncate(0);
  head.setUint32(0, 0x4a415449, true); head.setFloat64(8, version, true);
  j.write(new Uint8Array(head.buffer), { at: 0 });
  j.flush();
}
storeEnd = s.getSize();
The journal header is 16 bytes: a magic number, 0x4a415449, and the manifest version as a float64. If either differs, both files are cut to zero. Nothing is repaired or merged, so a new game build can never be handed a 4 KB block from an old one. Throwing away a gigabyte of cache is cheap next to a corrupt archive the engine cannot explain.
The second is where the streamer's hints become fetches:
function drainHints(bell) {
  const ring = Atomics.load(HEAP32, bell + 2), cap = Atomics.load(HEAP32, bell + 3);
  if (!ring || !cap || !sh || noHints) return;    // an engine without hints, no store to fetch into, or ?nohints=1
  const head = Atomics.load(HEAP32, bell + 4) >>> 0;
  let tail = Atomics.load(HEAP32, bell + 5) >>> 0;
  if (((head - tail) >>> 0) > cap) tail = (head - cap) >>> 0;    // the engine lapped us: the oldest hints were overwritten
  while (tail !== head) {
    const e = bell + ring + 4 * (tail % cap);
    const raw = Atomics.load(HEAP32, e + 3);
    if (!raw) break;    // claimed but not written yet: its writer rings the doorbell again when it is
    (raw & 0x40000000 ? lowQueue : hintQueue).push([HEAP32[e], (HEAP32[e + 1] >>> 0) + (HEAP32[e + 2] >>> 0) * 4294967296, raw & 0x3fffffff]);
    hintsSeen++;
    Atomics.store(HEAP32, e + 3, 0);
    tail = (tail + 1) >>> 0;
  }
  Atomics.store(HEAP32, bell + 5, tail);
  if (hintQueue.length > HINT_QUEUE_MAX) hintQueue.splice(0, hintQueue.length - HINT_QUEUE_MAX);
  if (lowQueue.length > HINT_QUEUE_MAX) lowQueue.splice(0, lowQueue.length - HINT_QUEUE_MAX);
  pumpHints();
}
This is the other half of the trick I liked most in the port. The engine's streamer writes each read it has queued into a ring in the heap: the file id, a 64-bit offset in two words, and the length, written last. The length doubles as the ready flag, so the worker never reads half an entry, and zeroing it hands the slot back. Bit 30 of the length marks a look-ahead hint, which goes to the low-priority queue. If the engine laps the worker, the oldest hints are simply dropped. A hint is advice, and the worst a lost one costs is a read that has to fetch for itself.
wgpu_worker.js
194 KB and 2,969 lines, the largest piece of JavaScript and the best commented. Its header, the command loop, the shader rewrite and the pipeline hash are all quoted in the graphics section. Two smaller pieces deserve a look. Device creation asks for everything the translation could use and settles for what it gets:
adapter = await gpu.requestAdapter({ powerPreference: 'high-performance' });
if (!adapter) throw new Error('no WebGPU adapter');
const want = ['texture-compression-bc', 'texture-compression-bc-sliced-3d', 'depth32float-stencil8', 'float32-filterable', 'indirect-first-instance', 'rg11b10ufloat-renderable', 'bgra8unorm-storage', 'depth-clip-control', 'clip-distances', 'texture-formats-tier1', 'dual-source-blending'];
const requiredFeatures = want.filter((f) => adapter.features.has(f));
Eleven optional features. The one the game leans on is texture-compression-bc: GTA's textures are BC1 to BC7, and with that feature they go to the GPU exactly as Rockstar compressed them. I found no software decoder in the worker to fall back on, so an adapter without the feature cannot take those textures as they are.
The second is how a C++ thread learns that the GPU has finished, which the ring section described in words:
case 8 /* FENCE */: {
  flush('fence');
  await device.queue.onSubmittedWorkDone();
  refreshViews();
  const addr = u32[p] + u32[p + 1] * 4294967296;
  Atomics.store(i32, w32(addr), u32[p + 2] | 0);
  Atomics.notify(i32, w32(addr));
  break;
}
FENCE flushes the open encoder, waits for onSubmittedWorkDone, writes the fence value at a 64-bit address in the heap and notifies it. A C++ thread sits in Atomics.wait on that word, the same futex shape as the file slots and the audio ring. And w32(addr) is the Math.floor(addr / 4) fix for addresses above 2 GB, at the exact spot where the old >> made fences never complete.
The data files
The JSON files are indexes, and the explorer shows a sample entry of each. shaders/index.json maps a DXBC hash to its pack, byte offset and length, and the vertex shader printed in Shaders sits 1,320,912 bytes into pack0, 843 bytes long. The part of it I cut there is its output struct:
struct tint_symbol_1 {
  @builtin(position)
  o0 : vec4<f32>,
  @location(1u)
  o1 : vec4<f32>,
}
DXBC's o0 becomes the position builtin and o1 keeps location 1. Register numbers survive the translation, and that is what lets the worker bind resources by a fixed scheme with no reflection pass.
pipelines.json holds 720 recipes, keyed the way the worker hashes a pipeline: shader hashes, input elements, strides, topology, the blend, depth and raster words, target formats and sample count. The low profile's pipelines_low.json has 425. data/manifest.json is one array per file (path, size, modification time) under version 1791169379-5814. bootset.json lists 2,918 files as 4,162 byte ranges adding up to 581,823,449 bytes, and bootset_low.json reads the same 2,918 files in 4,042 ranges and 508,852,403 bytes. Two entries under /data/ are not files at all: batch, the POST endpoint for gzipped batches, which is asked for first as a static batchc/<sha1>.bin copy that Cloudflare can cache, and the Range reads of the game files themselves.
Inside game.wasm, from the outside
I am not going to show any of the engine's code, and I did not disassemble it. The module's headers say plenty on their own. A wasm file is a sequence of sections, each with an id and a byte length, and reading them takes a dozen lines of Python:
| Section | Bytes | What it holds |
|---|---|---|
| type | 21,379 | 1,969 function signatures |
| import | 2,350 | 86 imports |
| function | 95,486 | 91,026 function declarations |
| table | 9 | one 64-bit table of 89,368 entries |
| global | 334 | 57 globals |
| export | 551 | 22 exports: 21 functions and the table |
| start, datacount | 3 | |
| element | 237,057 | one segment that fills the function table |
| code | 48,192,941 | the compiled engine |
| data | 7,828,019 | 4,077 segments of initialised memory |
custom name | 6,823,623 | 91,111 function names |
Code is 76% of the file. The name section is 6.8 MB that a release build drops with one linker flag, and it is the reason anyone can tell what this binary is. The table held my one surprise: it is a 64-bit table whose minimum and maximum are both 89,368, so it can never grow, and every function whose address the engine takes was fixed at link time.
The 86 imports are the whole outside world as the engine sees it:
| Module | Group | Count | For example |
|---|---|---|---|
env | memory | 1 | shared, 64-bit, 49,152 to 262,144 pages |
env | the porter's imports | 13 | wasm_httpfs_manifest_js, wgpu_start_worker, wasm_audio_publish_js |
env | Emscripten runtime | 26 | threads and mailboxes, time, heap growth, stack traces, longjmp |
env | file-system syscalls | 16 | openat, fstat64, getdents64, renameat |
env | socket syscalls | 9 | socket, connect, sendto, recvfrom |
env | invoke_* trampolines | 11 | C++ exceptions and setjmp, routed through JavaScript |
wasi_snapshot_preview1 | WASI | 10 | fd_read, fd_write, fd_pread, clock_time_get |
Everything the porter wrote on the JavaScript side enters through those 13. The socket syscalls amused me: the engine's network code is linked in and imports socket and connect, but with -nonetwork and the network threads skipped, nothing reaches them. The 22 exports are all Emscripten plumbing. No game function is exported, and the whole engine is entered through main(). The trampolines carry the wasm64 signature in their names, too: in invoke_vjj, each j is a 64-bit integer, which is what every pointer is here.
Fourteen of the 91,111 names, picked to show the port's seams next to the engine:
wasm_null_d3d::NullDevice::CreateTexture2D(D3D11_TEXTURE2D_DESC const*, D3D11_SUBRESOURCE_DATA const*, ID3D11Texture2D**)
wasm_null_d3d::NullContext::DrawIndexed(unsigned int, unsigned int, int)
wasm_null_d3d::NullSwapChain::Present(unsigned int, unsigned int)
wasm_httpfs_lookup
wasm_httpfs_pread
wasm_wait_begin
wasm_streaming_report
rage::wasm_cb::S<void (*)(), &rage::tcDebug::ModifierChanged(), 1>::thunk(void*, void*, void*)
rage::fiDeviceRelative::Read(fiHandle__*, void*, int) const
rage::AES::Decrypt(void*, unsigned int)
rage::scrThread::Run(int)
rage::strStreamingLoaderManager::LoadAllRequestedObjects(bool)
rage::HangDetectThread(void*)
rage::audDecoderOpus::Init(rage::audWaveFormat::audStreamFormat, unsigned int, unsigned int)
The first three belong to the fake Direct3D 11 device, 274 functions in wasm_null_d3d that turn D3D calls into ring commands. The wasm_httpfs_* functions are the C++ side of the file layer, and wasm_wait_begin and wasm_streaming_report look like the bookkeeping behind the port's hang detector and streaming log. rage::wasm_cb was the namespace I did not expect: 1,800 thunks that wrap engine callbacks, static functions and member functions alike, into one fixed signature of three pointers. My guess is that it exists because wasm traps on an indirect call whose signature does not match, where x86 lets it slide, and RAGE's debug widgets lean on that slack. The rest is the engine as Rockstar wrote it: the file device that reads the archives, the AES routine behind the encrypted tables of contents, the script interpreter that -fastscriptcore switches to its production core, the streamer, the hang-detect thread the port never starts, and the Opus decoder.
Where the source came from
The site does not say, and I cannot prove it. It does not say who built the port either. One widely shared post said it was ported "using AI", and nothing in the files confirms or rules that out; comments this thorough and this carefully dated fit an agent-assisted workflow as well as a meticulous person.
What I can show is what the binary needs: a full C++ source tree for RAGE and GTA V, on Rockstar's own build paths, in a development configuration, with data from a February 2015 build. Rockstar has never published that source.
GTA V's source did leak, twice. Around Christmas 2023, a slice of the material stolen in the September 2022 Rockstar breach went public, and it was reported at the time to contain the full GTA V source, in a form that compiles. In September 2026 a roughly 200 GB archive from the same breach began circulating, described as "GTA V source code, debug builds from every platform" plus early GTA 6 development material (gtaboom). A development tree with env_test levels, a Bugstar thread and 2014 artist exports is consistent with that material. The "GTA VI Map" label on the menu is the site's, not Rockstar's, and I would read nothing more into it than that env_test is a test level from Rockstar's tree.
The ports that came before
Two recent ports show what tends to happen next.
On the Nintendo Switch, a modder, M0jso, and a group called Paralympics Productions got GTA V running natively on a jailbroken original Switch by adapting the source that leaked in 2023. It ran below 30 fps without overclocking. After Rockstar updated its modding guidelines to prohibit ports to unsupported platforms, the modder posted them on 20 September with "try me Rockstar". Take-Two sent a cease-and-desist, and on 28 September the group announced it would shut down on 3 October without releasing its code, because releasing it would invite a lawsuit (Notebookcheck). A planned Android version was dropped with it.
In the browser, DOS Zone hosted a WebAssembly build of reVC in December 2025. reVC is a community reverse-engineering of Vice City's engine, built without Rockstar's source, and the site asked players to supply files from their own copy for the full game. It went viral around 22 December, and on 24 December Take-Two's brand-protection firm filed a DMCA notice citing trademark infringement, unauthorised use of copyrighted material and circumvention of protections (Generation Amiga). Another site relaunched a complete Vice City in September 2026, again on reVC (see the reVC browser repo).
playgta5.com went further than either. It used no reverse-engineered engine and asked for none of your files; it served a binary compiled from leaked source, and 20.9 GB of Rockstar's data, to anyone who opened the page. As of 6 October 2026 I could find no press coverage of it, only the viral video. Partway through my last test run, the site's Cloudflare front end started answering my server with "Sorry, you have been blocked". My runs had pulled about 2 GB in many parallel Range requests from a data-centre IP, which is the likely trigger. I did not try to get past it.
Serving all of that to 10,000 people a day is not a gray area, and after what happened to the Switch port a week earlier I expected the site to be gone soon. It was. By the evening of 6 October 2026, playgta5.com no longer accepted connections.
The Wayback Machine holds a capture of the page from that morning, and the way it fails shows how this port was built. The title screen and start menu still render, because they are HTML and CSS. The engine never starts. The archive has no game.wasm, no workers, no manifest and none of the game data (every one of those URLs is a 404 there), and even if it had them, the archived page is served without the COOP/COEP headers it checks for, so it stops at 5% with its own message: "not cross-origin isolated".
Copies did not vanish with it. Within hours one X user said he had saved the compiled build before the takedown, had no source, and was adding multiplayer to it locally, while others in his replies asked for rehosts of files they had only half downloaded. A reply there called the takedown a copyright strike; I could not confirm that. I have not linked the site, the capture or any of those copies, and nothing here tells you how to get the data.
What the browser can do now
Set the provenance aside and this port shows something that was not true two years ago: the browser now has every primitive a 2013 AAA engine needs, and the engine did not have to be rewritten to use them. 64-bit WebAssembly with shared memory gives it a 3 GB heap and 75 real threads. Atomics.wait in workers lets C++ block the way it always did, and Atomics.waitAsync lets JavaScript workers serve it without spinning. WebGPU is close enough to D3D11 that a recorder on one side and a replayer on the other can bridge them, with the gaps (tessellation, geometry shaders, binary occlusion) known and listed. Synchronous access handles in OPFS let a 20.9 GB file system be faked one 4 KB block at a time. fetch priorities, DecompressionStream, AudioWorklet and OffscreenCanvas cover the rest.
The list of what did not translate is just as useful. There are no geometry or tessellation stages. Per-call cost makes thousands of draws expensive. Garbage collection never runs in a busy worker. Microtasks starve completion callbacks. Timers round to the OS tick. And the host has to serve many small streams instead of big files. Each of those has a comment in the source explaining the workaround, and if I ever had to port a native engine to the web legitimately, I would start from those comments before any documentation.
Elsewhere on the site, WebGPU usually shows up for small things: a 41,321-parameter syntax highlighter, a decision model scored in the page, Gaussian splats as WebP images or TypeGPU's value types. This is the other end of the scale. For the opposite direction, a modern graphics pipeline reimplemented by reading it rather than running it, see OpenDLSS-NR.
How I checked
Everything about the port comes from the files the site served on 6 October 2026. I downloaded the page, loader.js, game.js, the three workers, the shader index and packs, the pipeline seed, the manifest and the boot set, and read the JavaScript in full. The section sizes, function names, imports and memory declaration come from parsing game.wasm with a small script that reads its section headers, import list and name section, without running or disassembling it. The code tour quotes the files as saved that morning, with each excerpt's line numbers in the file as served, except game.js, which is numbered from a prettier-formatted copy. Shader counts are from counting shaders/index.json, folder and type sizes from data/manifest.json, and the boot-set breakdown from bootset.json. File formats come from the headers of sample files fetched with Range requests; nothing was decrypted, and the audio codec id is unconfirmed.
The timeline, the thread counts, the malloc arena, the pipeline compile-ahead line, the draw count and the session download totals are from my own three headless Chromium runs on a 16-core server with no GPU, rendering on SwiftShader. Numbers in quotation marks, and the per-stream throughput and Chromebook timings, are the porter's, quoted from the source comments; I did not reproduce them. The boot-set times at 6 and 128 streams are my arithmetic on the porter's rates and the 582 MB boot set, and the 3.5% share is 743 MB over the 20.9 GB folder.
The 65 GB release size, the source leaks, the Switch port and the Vice City DMCA come from press coverage, linked where it is cited. I could not find out who built the port, and I could not confirm what kind of takedown ended it.