2026-10-06 · 70 min · retrieval · multimodal · on-device · benchmarks · small-models
Why read this
Essentialtop 10%Recounts EmbeddingGemma 2 to 744M from its header, hashes its audio tower as Gemma 4's, and finds the 30 s and 32-frame defaults behind the 327 s claim.
- Original, source-checked analysis
- Runs on a phone
- A guide you can follow today
Vision & multimodalApache-2.0Practitioner model
How this was scored
- Is it new?
- 2 of 3: A real new idea, method or capability
- Can I trust it?
- 3 of 3: Reproduces the headline result, or shows from primary files it is wrong
- Can I run it?
- 3 of 3: Open, permissive, runs on reader hardware with instructions
- Will I understand it?
- 2 of 3: Mechanism from first principles with figures
- Can I act on it?
- 3 of 3: A decision guide a practitioner can follow today
- Will it last?
- 2 of 3: A reference for a year or more
- Does it affect many?
- 2 of 3: A widely used model, tool or lab release
- Only here?
- 3 of 3: The only place this analysis exists
Score 88 of 100, ranked 5 of 701 rated articles. Each question is answered 0–3 by hand, and a 3 is rare. How articles are scored
Sundar Pichai's post called EmbeddingGemma 2 a "lightweight, modular 740M parameter form factor" that handles text, code, images, video and audio. The word I didn't understand was modular. A multimodal embedding model is usually either one big network that reads everything, or a set of separate towers glued together by a contrastive loss. "Modular" could mean either, and the two behave very differently when you try to put one on a phone.
So I read the files. The model card, the
safetensors header (fetched with two HTTP range requests, no weights downloaded), the
embedding_gemma2 model code in transformers, the processors that turn a JPEG or a WAV into
tokens, and Google's three launch posts. The short version: every input, whatever it started as,
ends up as a sequence of 512-wide vectors fed through one small text encoder, and that encoder is
the only part you can't remove. The vision and audio towers are front ends. And the audio front
end turned out to be something I didn't expect: it is Gemma 4's audio encoder, unchanged, down to
the byte.
| Weights | google/embeddinggemma-2, one 1.49 GB bf16 model.safetensors |
| Licence | Apache 2.0 (EmbeddingGemma 1 shipped under the Gemma terms) |
| Output | 768 dimensions, Matryoshka cuts at 512, 256, 128 |
| Context | 8,192 tokens shared by every modality |
| Launch posts | Google blog, developer guide, AI Edge post |
| Paper | none yet; the closest is EmbeddingGemma 1's report |
- architecture
- EmbeddingGemma2Model
- task
- feature-extraction
- library
- transformers
- license
- apache-2.0
- safetensors
- 1 shard
- largest file
- 1.49 GB
- files
- 15
- downloads
- 364
- likes
- 114
- languages
- multilingual
The header holds 744,371,992 parameters: 271.0M text, 167.8M vision, 305.6M audio.
repo last modified 2026-10-06
What is in the 744 million
The safetensors header is a JSON index of every tensor with its shape. Summing them gives 744,371,992 parameters, all bf16. The Hub's own counter says 744,371,512. The 480 missing are scalars: the audio tower stores a minimum and maximum for the input and output of every clipped linear layer, 40 per conformer layer across 12 layers, each a zero-dimensional tensor that the Hub's counter skips. Either way, 740M is a fair rounding.
Grouped by which module the tensor belongs to:
| Module | Parameters | What it is |
|---|---|---|
language_model.embed_tokens | 134,217,728 | the vocabulary table, 262,144 tokens x 512 |
language_model.ple, embedding_projection, final norm | 6,685,696 | per-layer input projection, and the 512 to 768 output head |
language_model.layers (24) | 130,099,224 | the transformer |
vision_tower + embed_vision | 167,757,824 | 16-layer ViT, 768 wide, and a 768 to 512 projection |
audio_tower + embed_audio | 305,611,520 | 12-layer conformer, 1,024 wide, and a 1,536 to 512 projection |
That matches the card's own split to within rounding: a 130M transformer, a 140M "embedder", a 170M vision encoder and a 300M audio encoder. Two things stood out.
Half of the text model is one lookup table. The 262,144-token vocabulary times a 512-wide embedding is 134.2M of the 271.0M. The transformer that does the actual reading is 24 layers of about 5.25M each (6.3M for the four global-attention layers, which have wider heads). This is the usual shape for a small Gemma: a huge multilingual vocabulary on a narrow model.
And the audio tower is the largest single module in the file, bigger than the whole text model. If you want audio, you are carrying 306M parameters for it.
An image is 280 words the vocabulary does not have
The mechanism is easiest to see in EmbeddingGemma2Model.forward. The processor writes the text
with a placeholder for every piece of media: <|image|>, <|video|>, <|audio|>. It then
expands each placeholder into as many placeholder tokens as the media will produce, wrapped in
begin and end markers. The model embeds the text tokens normally, runs each tower, projects its
output to 512 dimensions, and overwrites the placeholder slots with those vectors:
# transformers/models/embedding_gemma2/modeling_embedding_gemma2.py:797-799
inputs_embeds = inputs_embeds.masked_scatter(
    image_mask.to(inputs_embeds.device), image_features.to(inputs_embeds.device)
)
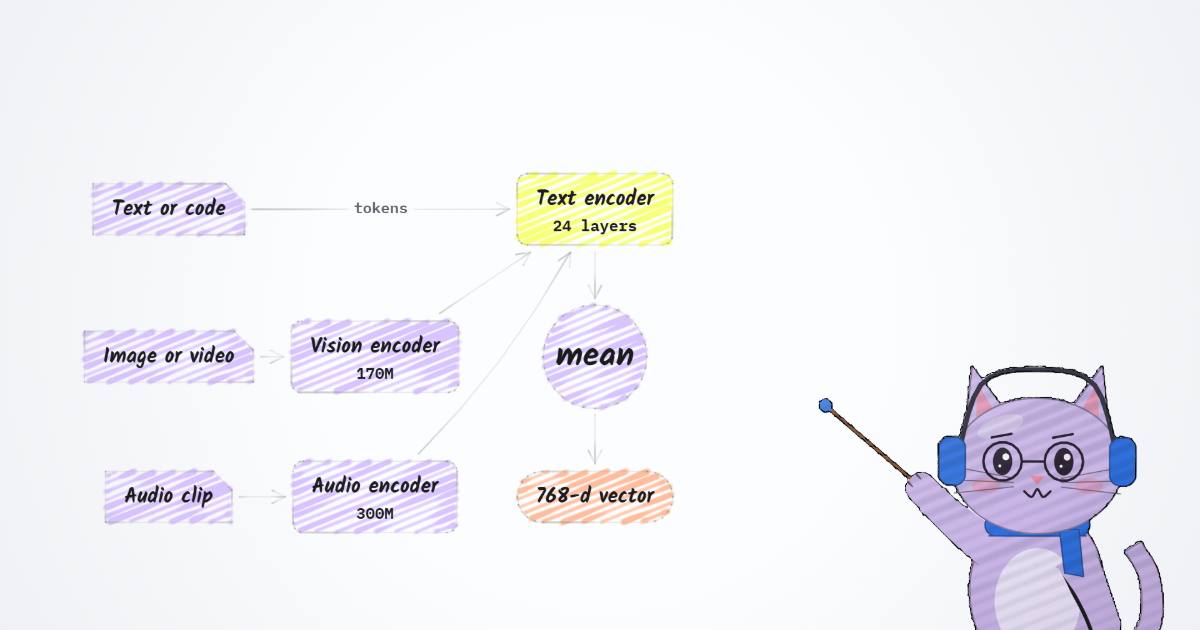
After that line, the text encoder can't tell a word from a patch of a flamingo. It sees one sequence of 512-wide vectors and reads all of it with the same 24 layers. Google's own diagram draws it that way, with the encoders feeding a single box labelled 270M:
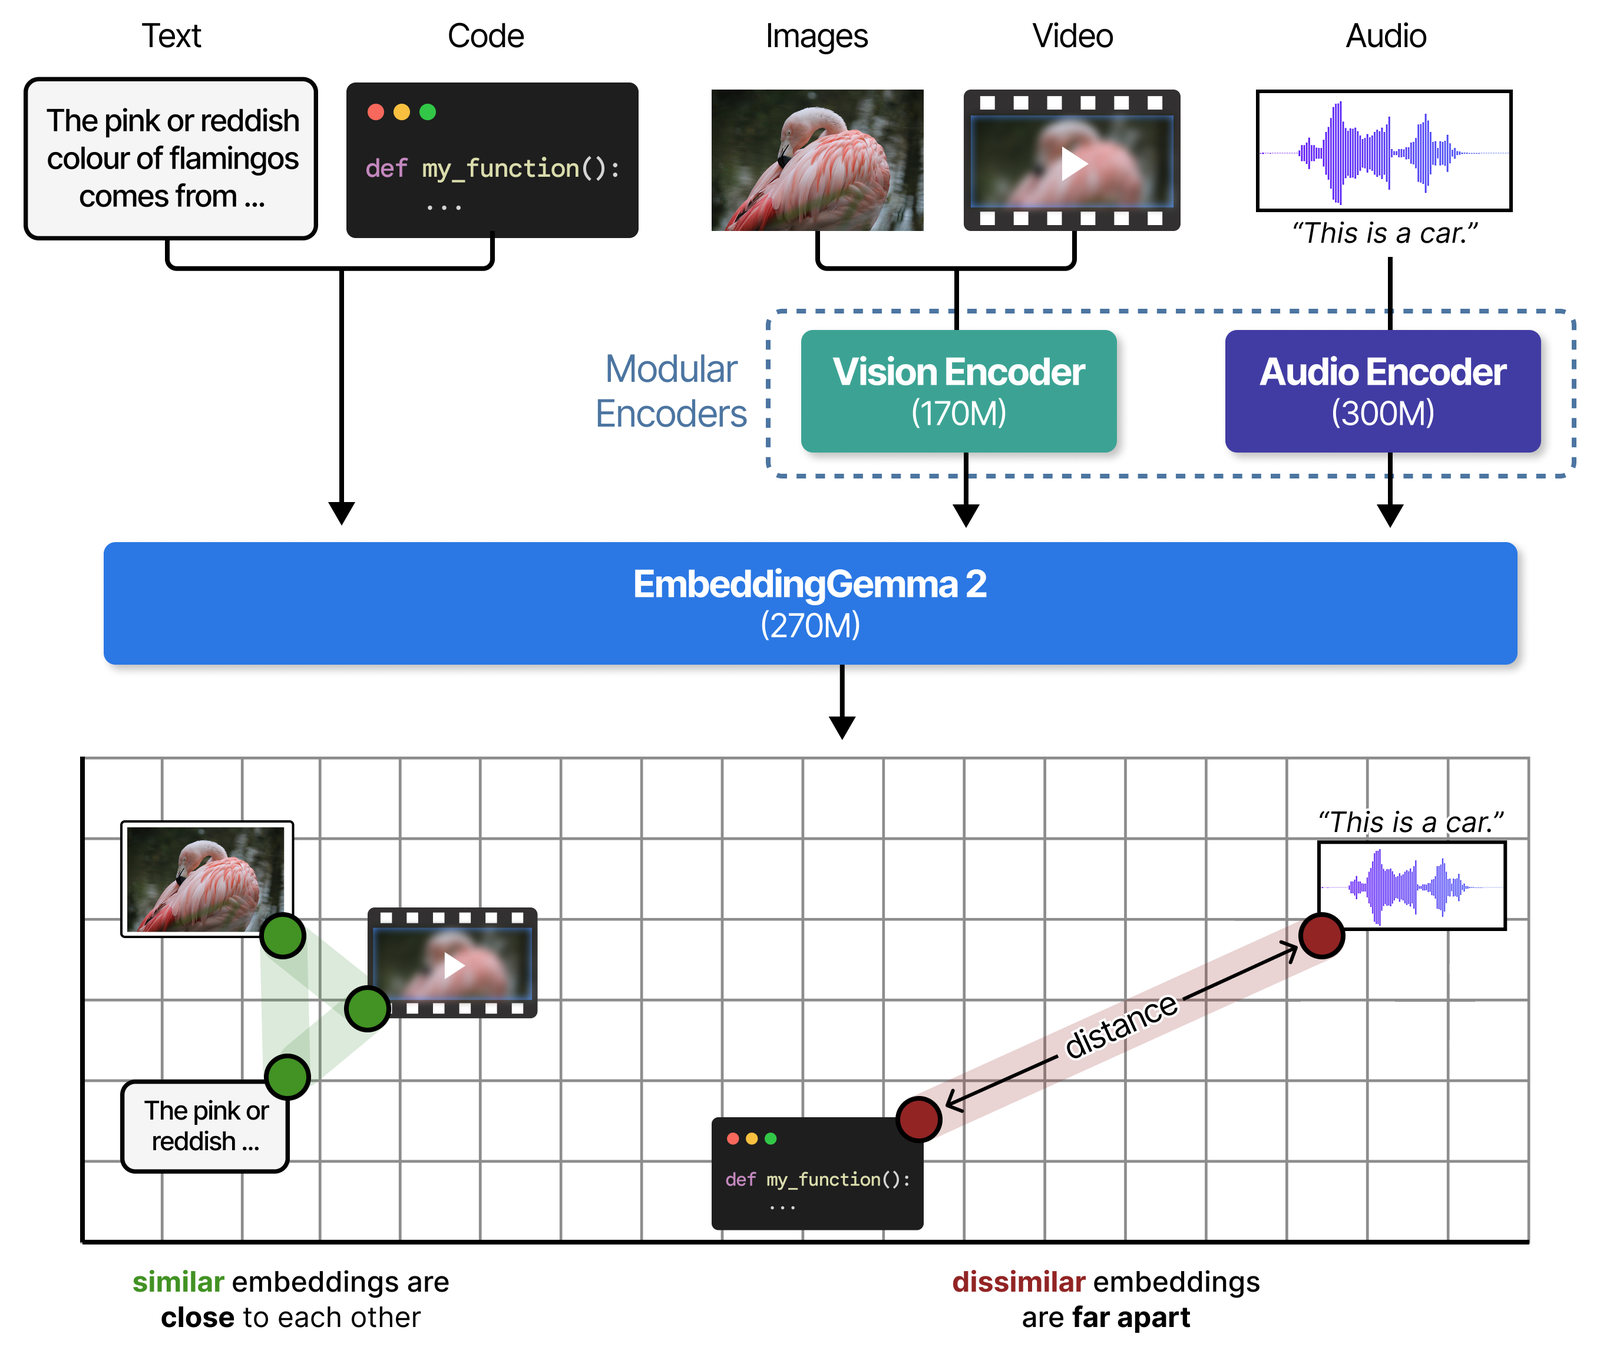
How many slots each piece of media takes is decided by the towers.
Images go through a 16-layer ViT with 16-pixel patches. Its output is pooled three by three, so each output token stands for nine patches. At the default budget of 280 tokens an image gets up to 2,520 patches, roughly an 800 x 800 picture at its own aspect ratio. The budget can be set anywhere from 70 to 1,120, the same ladder Gemma 4 uses, which I covered in the Gemma 4 piece. Video is the same tower run on frames, sampled at one per second, at 140 tokens a frame.
Audio is resampled to 16 kHz mono and turned into 128-bin log-mel frames every 10 ms. Two
stride-2 convolutions shrink that by four, so one audio token covers 40 ms: 25 tokens a second.
The conformer's attention is chunked and local (attention_chunk_size: 12,
attention_context_left: 13, attention_context_right: 0 in the config): a token attends within
its own 12-token chunk, 480 ms, plus about half a second of the past, and never past the end of
its chunk. It was built to stream. Any
understanding of a whole clip has to come from the text encoder, which sees every audio token at
once.
The text encoder itself is a Gemma 4-style stack turned bidirectional. The attention class sets
self.is_causal = False (line 331) and the masks come from create_bidirectional_mask. Five
sliding-window layers alternate with one global layer, 24 in all. The config says
sliding_window: 512 while the card says 1,024, and both are right: the bidirectional window
lets a token see 512 positions on each side, about 1,024 in total. The global layers use one
key-value head (multi-query attention) with 512-wide heads; the local ones use two key-value heads
with 256-wide heads.
The last step is the one that makes it an embedding model. The final hidden states are normalised
and projected from 512 to 768 per token, then sentence-transformers takes the mean over every
position, prompt included (include_prompt: true in 1_Pooling/config.json), and L2-normalises
it. The code comments why projecting before pooling is allowed:
# modeling_embedding_gemma2.py:504-505
# Projecting per token is equivalent to projecting after mean pooling
self.embedding_projection = nn.Linear(config.hidden_size, config.embedding_dim, bias=False)
A linear map commutes with an average, so it costs more compute but gives the same vector. That head is one 512 x 768 matrix with no bias. EmbeddingGemma 1 used two dense layers after pooling, 768 up to 3,072 and back down to 768, according to its report. The new model is narrower inside (512 against 768) and has a simpler head.
Mean pooling has a consequence worth stating plainly. The embedding is an average over positions, and a default image is 280 positions while a caption is twenty. Attention mixes them all before the average, so a 280-to-20 split is not a 93% share of the meaning, but the media does dominate the arithmetic. I come back to this when budgeting the context window below.
Per-layer embeddings without the lookup table
One detail in the text encoder took me a while, and it is the most interesting design choice in the file.
Gemma 3n and the small Gemma 4 models use per-layer embeddings (PLE): besides the normal embedding table, every token id also looks up a small extra vector for every layer, from a second, very large table, and each layer mixes its slice into the residual stream. It is how Gemma 4 E2B keeps 5B parameters on disk and runs like a 2.3B model, as I explained in the Gemma 4 article. The catch, for an embedding model fed images and audio, is that a soft token has no token id. There is nothing to look up for a patch of a flamingo.
EmbeddingGemma 2 keeps the per-layer signal and drops the table. The per-layer inputs are computed from the input embeddings themselves, through one linear layer:
# modeling_embedding_gemma2.py:193-200 (EmbeddingGemma2TextPLE)
def forward(self, inputs_embeds):
    per_layer_projection = self.per_layer_model_projection(inputs_embeds) * self.per_layer_model_projection_scale
    per_layer_projection = per_layer_projection.reshape(
        *inputs_embeds.shape[:-1], self.num_hidden_layers, self.hidden_size_per_layer_input,
    )
    return self.per_layer_projection_norm(per_layer_projection)
The class docstring calls it "projection-only PLE: the signal is derived from inputs_embeds
alone, with no token-identity lookup". The projection is 512 to 24 x 512, which is the 6.29M
per_layer_model_projection in the header. Each layer then gates its slice in with a small
bottleneck after attention and the MLP (hidden_states * per_layer_input at line 224).
This works the same for a word and an image patch, because both arrive as a 512-wide vector before the projection. It also explains part of why the text model is 271M and not several billion: there is no per-layer table to carry. I'd read it as a requirement of native multimodality more than a cost trick, though Google doesn't say which.
Modular means the front end, not the model
Now the word from the post. In EmbeddingGemma2Model.__init__, each tower is built only if its
config exists:
# modeling_embedding_gemma2.py:646
self.vision_tower = AutoModel.from_config(config.vision_config) if config.vision_config is not None else None
Pass config_kwargs={"vision_config": None, "audio_config": None} to SentenceTransformer and
neither tower nor its projection is constructed; the loader is told to ignore their weights
(_keys_to_ignore_on_load_unexpected, line 637). What is left is the 271M text encoder. Add
vision for 440M, audio for 570M, both for 740M. Those are the card's four configurations, and the
header sums agree with them.
The part that matters for an index: a text input never touches either tower. The placeholder masks
are empty, the masked_scatter calls are skipped, and the same 24 layers run on the same token
embeddings. So a text embedding from the 270M configuration is the same vector as one from the
full model, and the developer guide says exactly that: "Embeddings you have already computed do
not need to be re-computed." You can index a document store with the small configuration on a
laptop today and add photos to the same index later with the full one.
What you can't do is drop the text encoder. An image embedding is the mean of the text encoder's output over the image's soft tokens. There is no vision-only embedding path, and the vision tower alone produces nothing you can compare. "Modular" here means a model with swappable front ends and one shared reader, not a set of independent towers.
The audio encoder is Gemma 4's, byte for byte
The launch blog says EmbeddingGemma 2 "shares its text tokenizer and audio encoder" with Gemma 4, so that the two can run together "with a lower combined total memory footprint". The developer guide softens that to sharing the "audio encoder architecture". Those are different claims: one means the same code, the other means the same weights you could load once.
I checked the weights. Safetensors stores each tensor as a contiguous byte range listed in the
header, so I fetched the same tensors from google/embeddinggemma-2 and google/gemma-4-E2B
with range requests and hashed them. All 36 audio tensors I sampled, three from each of the 12
conformer layers (attention projections, convolution input projections and the clipping bounds),
plus the tower's output projection, were byte-identical. They are also identical in
gemma-4-E2B-it and gemma-4-E4B. The tokenizer vocabulary is the same 262,144 entries in the
same order.
The vision tower is a different story. Same shapes, different bytes: none of the eight vision
tensors I sampled matched Gemma 4 E2B's. So the vision encoder was trained for embeddings, and the
audio encoder was either frozen throughout or never trained here at all, with only the 1,536 to
512 projection (embed_audio) and the text encoder learning to read it.
Two practical consequences. If you run Gemma 4 E2B for generation and EmbeddingGemma 2 for retrieval on the same device, the 305M audio tower can, in principle, be loaded once; whether a runtime does that is up to the runtime, and I couldn't check what LiteRT does. And EmbeddingGemma 2's audio understanding is bounded by what Gemma 4's speech encoder already captures, which is mostly speech. That fits the benchmark numbers below.
How it was trained, as far as the files say
There is no EmbeddingGemma 2 paper. The model card covers data (web text in over 140 languages, code, images, video, speech and sounds, paired cross-modal samples, a January 2025 cutoff) and nothing about the loss or the stages. So what follows is partly inference, and I'll mark it.
EmbeddingGemma 1's report describes the recipe that this almost certainly builds on: a
noise-contrastive loss over in-batch negatives with harder negatives weighted up, a spread-out
regulariser that penalises squared dot products between unrelated embeddings in a batch, a loss
that matches the student's embeddings to Gemini Embedding's, Matryoshka versions of those losses
applied to nested prefixes of the vector, a large pre-finetuning stage on unlabelled pairs, a
finetuning stage with hard negatives on several mixtures, and a final model that averages the
checkpoints from those mixtures. The card's task prefixes (task: search result | query: ) are
the same family as EmbeddingGemma 1's, and the blog says EmbeddingGemma 2 is "built from the same
technology as Gemini Embedding models".
For the multimodal part, the contrastive loss itself doesn't care what the positives are. A batch can pair a spoken question with a passage, a caption with a photo, or a text query with a video, and InfoNCE pulls each matched pair together and pushes the rest apart. I walked through that loss, and the two failure modes a shared index has (the right concept in the wrong modality, and a modality gap that clusters captions with captions), in the Ovis-Embedding article.
What the files do tell me: the audio tower didn't move, the vision tower did, the text encoder is a new 512-wide network rather than EmbeddingGemma 1's 768-wide one, and MRL is trained in: the card says so, and its truncation table degrades gently down to 256, which plain truncation of an untrained vector would not. The AI Edge post adds that quantization-aware training produced the int4 and int8 versions. Everything else about the recipe, including whether a Gemini Embedding teacher was used for images and audio, I couldn't check.
Spending the window
The card advertises an 8,192-token context "capable of processing minutes of audio or video", and a table: about 29 images, 58 video frames or 327 seconds of audio. Those are 8,192 divided by 280, 140 and 25. They describe the window, not what the shipped preprocessing will actually feed it.
The video processor in transformers has max_frames = 32 and overflow_strategy = "uniform"
(video_processing_embedding_gemma2.py:192-193). Hand it two minutes of video at one frame per
second and it keeps 32 frames spread evenly, one every 3.75 seconds. The audio side goes through
Gemma 4's feature extractor, whose __call__ defaults to max_length=480_000 samples with
truncation on, which is 30 seconds at 16 kHz. A five-minute recording becomes its first 30
seconds. Both caps can be overridden, and the LiteRT runtime streams audio in its own way, but the
default model.encode({"audio": ...}) path is what most people will run first. I couldn't run it
to confirm the end-to-end behaviour, so treat this as a reading of the code with a test to do,
not a measured result.
There is also a third number in the repo's own processor_config.json, audio_seq_length: 280,
which caps the token count reported by _compute_audio_num_tokens (the helper serving engines
call to reserve placeholder slots) at 280 tokens, 11.2 seconds. The class default is 750. I don't
know which value vLLM ends up using; if long audio fails to embed there, this is where I'd look.
None of this is a defect. A single vector is a poor summary of five minutes of anything, and Google's own Video Moments Finder demo indexes chunks of a video, not the whole file. The practical rule is to chunk long media yourself, a few seconds of audio or a handful of frames per embedding, and let the index hold many vectors per file.
The planner below adds up a single input. It also shows the share of positions each modality contributes to the final mean, which is where interleaved inputs get surprising.
In numbers: text costs one token per subword, an image its budget plus two marker tokens, a video frame 142, and an audio clip 25 per second plus two. A product listing with a 40-token description and two photos at the default budget is 604 tokens, about 7% of them text. Add 20 seconds of video and it is 3,444 tokens and the text is about 1%. If the words matter, I'd embed the description on its own as well and keep both vectors, or lower the vision budget to 70 for the photos in an interleaved input.
The benchmark claims
The card's headline table, all at 768 dimensions and full precision:
| Benchmark | Metric | EmbeddingGemma 2 | EmbeddingGemma 1 |
|---|---|---|---|
| MTEB multilingual v2 | mean over tasks | 61.36 | 61.15 |
| MTEB code v1 | nDCG@10 | 78.68 | 68.76 |
| MIEB lite | mean over task types | 64.64 | – |
| MMEB v2 image | Hit@1 | 57.28 | – |
| MMEB v2 visual documents | nDCG@5 | 67.84 | – |
| MMEB v2 video | Hit@1 | 50.67 | – |
| MSEB retrieval | MRR@10 | 69.54 | – |
| MAEB | mean over tasks | 49.39 | – |
Text is flat: 61.36 against 61.15 is a 0.21-point gain, which the blog fairly calls matching. Code is where the text model improved, by 9.92 points, the "14%" in the developer guide (9.92 / 68.76 is 14.4%). For scale on text, Qwen3-Embedding-0.6B's own card reports 64.33 on MTEB multilingual and 70.70 on MTEB English v2 against EmbeddingGemma 2's 61.36 and 68.46. Qwen's is a 600M text-only model against a 271M text path, so I don't read it as a loss, but EmbeddingGemma 2 isn't the strongest small text embedder; its case is that the same index takes pictures and sound.
The "outperforms some specialist models more than twice its size" line comes from three charts in the launch blog, each scoring models against size on a log axis. I read every dot's value off its pixel position against the tick marks, which is good to about half a point.
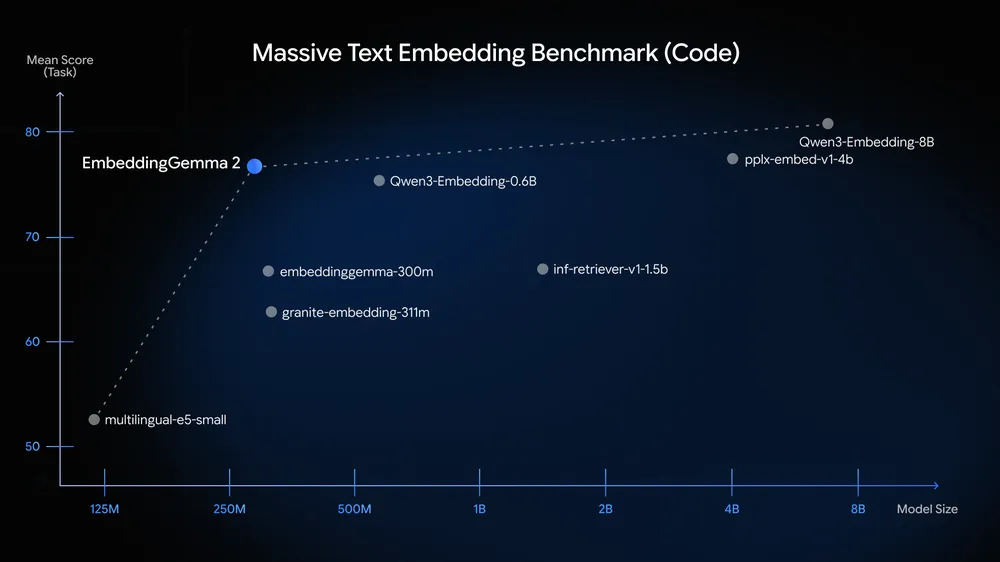
On code the chart places EmbeddingGemma 2 at its text size, near 270M, and its nearest rivals are Qwen3-Embedding-0.6B (about 75.3) and inf-retriever-v1-1.5b (about 67.0). One oddity: the blue dot sits at about 76.7, not the card's 78.68, and EmbeddingGemma 1's dot sits at about 66.7 against its card value of 68.76. The gray dots line up with published values (Qwen3-Embedding-0.6B reads about 75.3 against the 75.41 in Qwen's own README), so the axis is fine. Both Gemma dots are about two points low, which looks like the chart and the table came from different evaluation runs. The table is the better number to quote, and either way the ranking on the chart doesn't change.
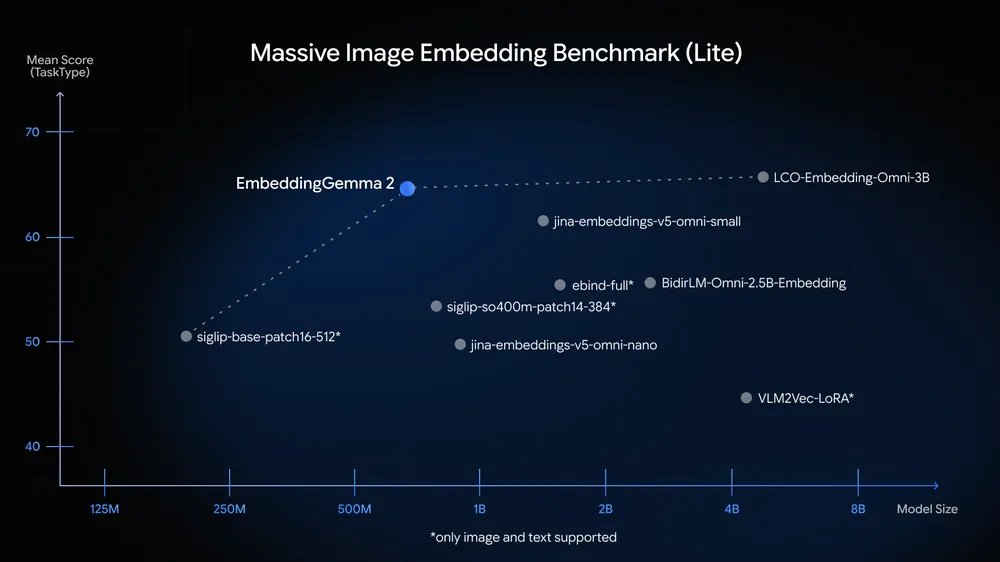
On images the claim holds cleanly. EmbeddingGemma 2 reads about 64.5, which matches the card's 64.64. jina-embeddings-v5-omni-small, 1.63B parameters by its own header count and so 2.2 times EmbeddingGemma 2, reads about 61.4. BidirLM-Omni-2.5B reads about 55.5, VLM2Vec-LoRA about 44.6. Only LCO-Embedding-Omni-3B, about four times the size, is higher, by about one point.
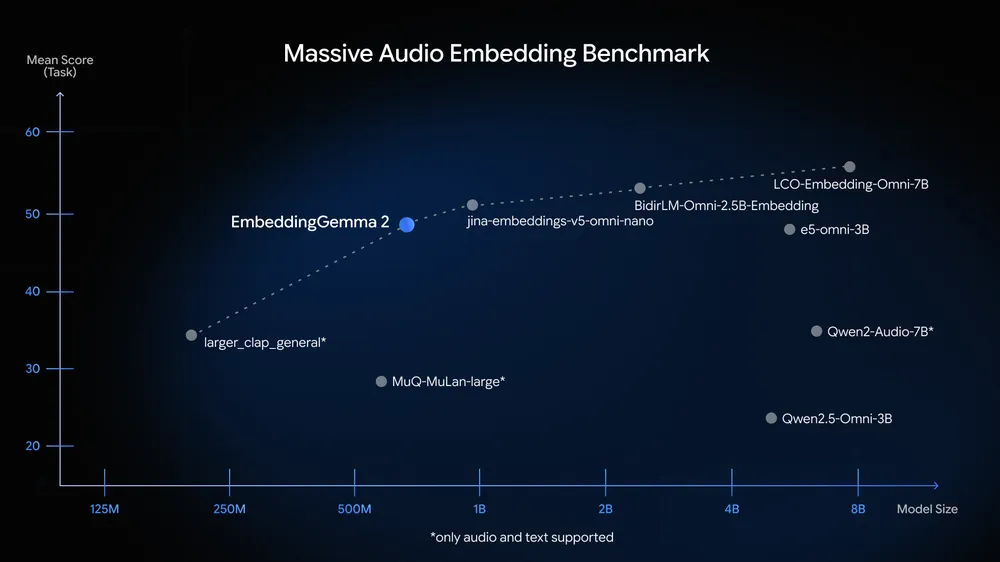
Audio is where I'd push back. EmbeddingGemma 2 reads about 48.6 (card: 49.39) and does beat e5-omni-3B (about 48.1), Qwen2-Audio-7B (about 34.8) and Qwen2.5-Omni-3B (about 23.6), all well over twice its size. But the blog also says it "achieves leading scores among sub-1B multimodal embedders" on MAEB, and its own chart shows jina-embeddings-v5-omni-nano above it at about 51. That model's header holds 985,984,512 parameters, under a billion. It is licensed CC-BY-NC-4.0, so if "leading" quietly means "leading among models you can ship commercially", the claim survives. As written, it doesn't, on Google's own figure.
The pattern across the three charts is consistent with the audio tower being Gemma 4's speech encoder: strong on code and images, where the trainable parts did the work, and mid-pack on general audio, where the encoder was inherited.
Shorter vectors
Matryoshka training means the first 512, 256 or 128 numbers of the 768-dimensional vector are themselves a usable embedding, once renormalised. The card's truncation table shows how much each benchmark keeps.
The cost is uneven. At 256 dimensions every benchmark keeps at least 95% of its full score, and storage drops threefold: a million vectors go from 3.07 GB to 1.02 GB in float32, or 1.54 GB to 512 MB in bfloat16. At 128 the text rows keep 94% to 96% of their scores (multilingual text goes from 61.36 at full width to 57.89 cut), but the multimodal average, MMEB v2 overall, falls from 59.01 at full width to 45.65 cut, about 77%, and MSEB spoken retrieval from 69.54 to 56.71. The card's own advice is "128d is best suited to text-only workloads", and the numbers back it.
Two small inconsistencies in the launch material. The AI Edge post says MRL cuts index footprints "by up to 8x"; 768 to 128 is 6x, which is what the card and the main blog say. And the card's re-normalisation warning is worth taking seriously: a cut vector is no longer unit length, and cosine scores on unnormalised prefixes still look plausible while ranking worse.
Ten million vectors in 0.4 GB, and what that leaves out
Added 7 October 2026.
The day after launch, Qdrant's Shivendu (@KShivendu_) posted the storage side of the story: "We pushed 10M of Google's EmbeddingGemma 2 vectors from ~30GB of RAM down to ~0.4GB", by quantizing each dimension to one bit with TurboQuant and then cutting the vector to 256 dimensions with the Matryoshka truncation above. "77x less RAM for a ~5% drop in quality." The Qdrant blog post behind it has the numbers, and most of them hold up. Two things about how they're framed don't, so here is the arithmetic first.
Ten million 768-dimensional float32 vectors are 10,000,000 x 768 x 4 bytes, which is 30.72 GB. The blog says 30.7, the post rounds to 30. At one bit a dimension, 768 dimensions are 96 bytes, but the blog gives 104 bytes a vector; at 512 dimensions it gives 72, where the bits alone are 64; at 256 it gives 40 against 32. So every quantized vector carries 8 bytes beyond its bits. Qdrant's TurboQuant write-up says what goes in them: per-vector scalars, as far as I can tell a stored length and RaBitQ's correction for how much quantization shrank the vector, which the scoring multiplies back in. That accounts for the whole gap you'd otherwise puzzle over. Bits alone would give 96x at 256 dimensions; 3,072 bytes over 40 is 76.8x, the "77x". The post's own "30 GB to 0.4 GB" is 75x, but that is just the rounding of 30.72. At 768 dimensions the same overhead turns a 32x bit ratio into 29.5x, which the blog calls "30x".
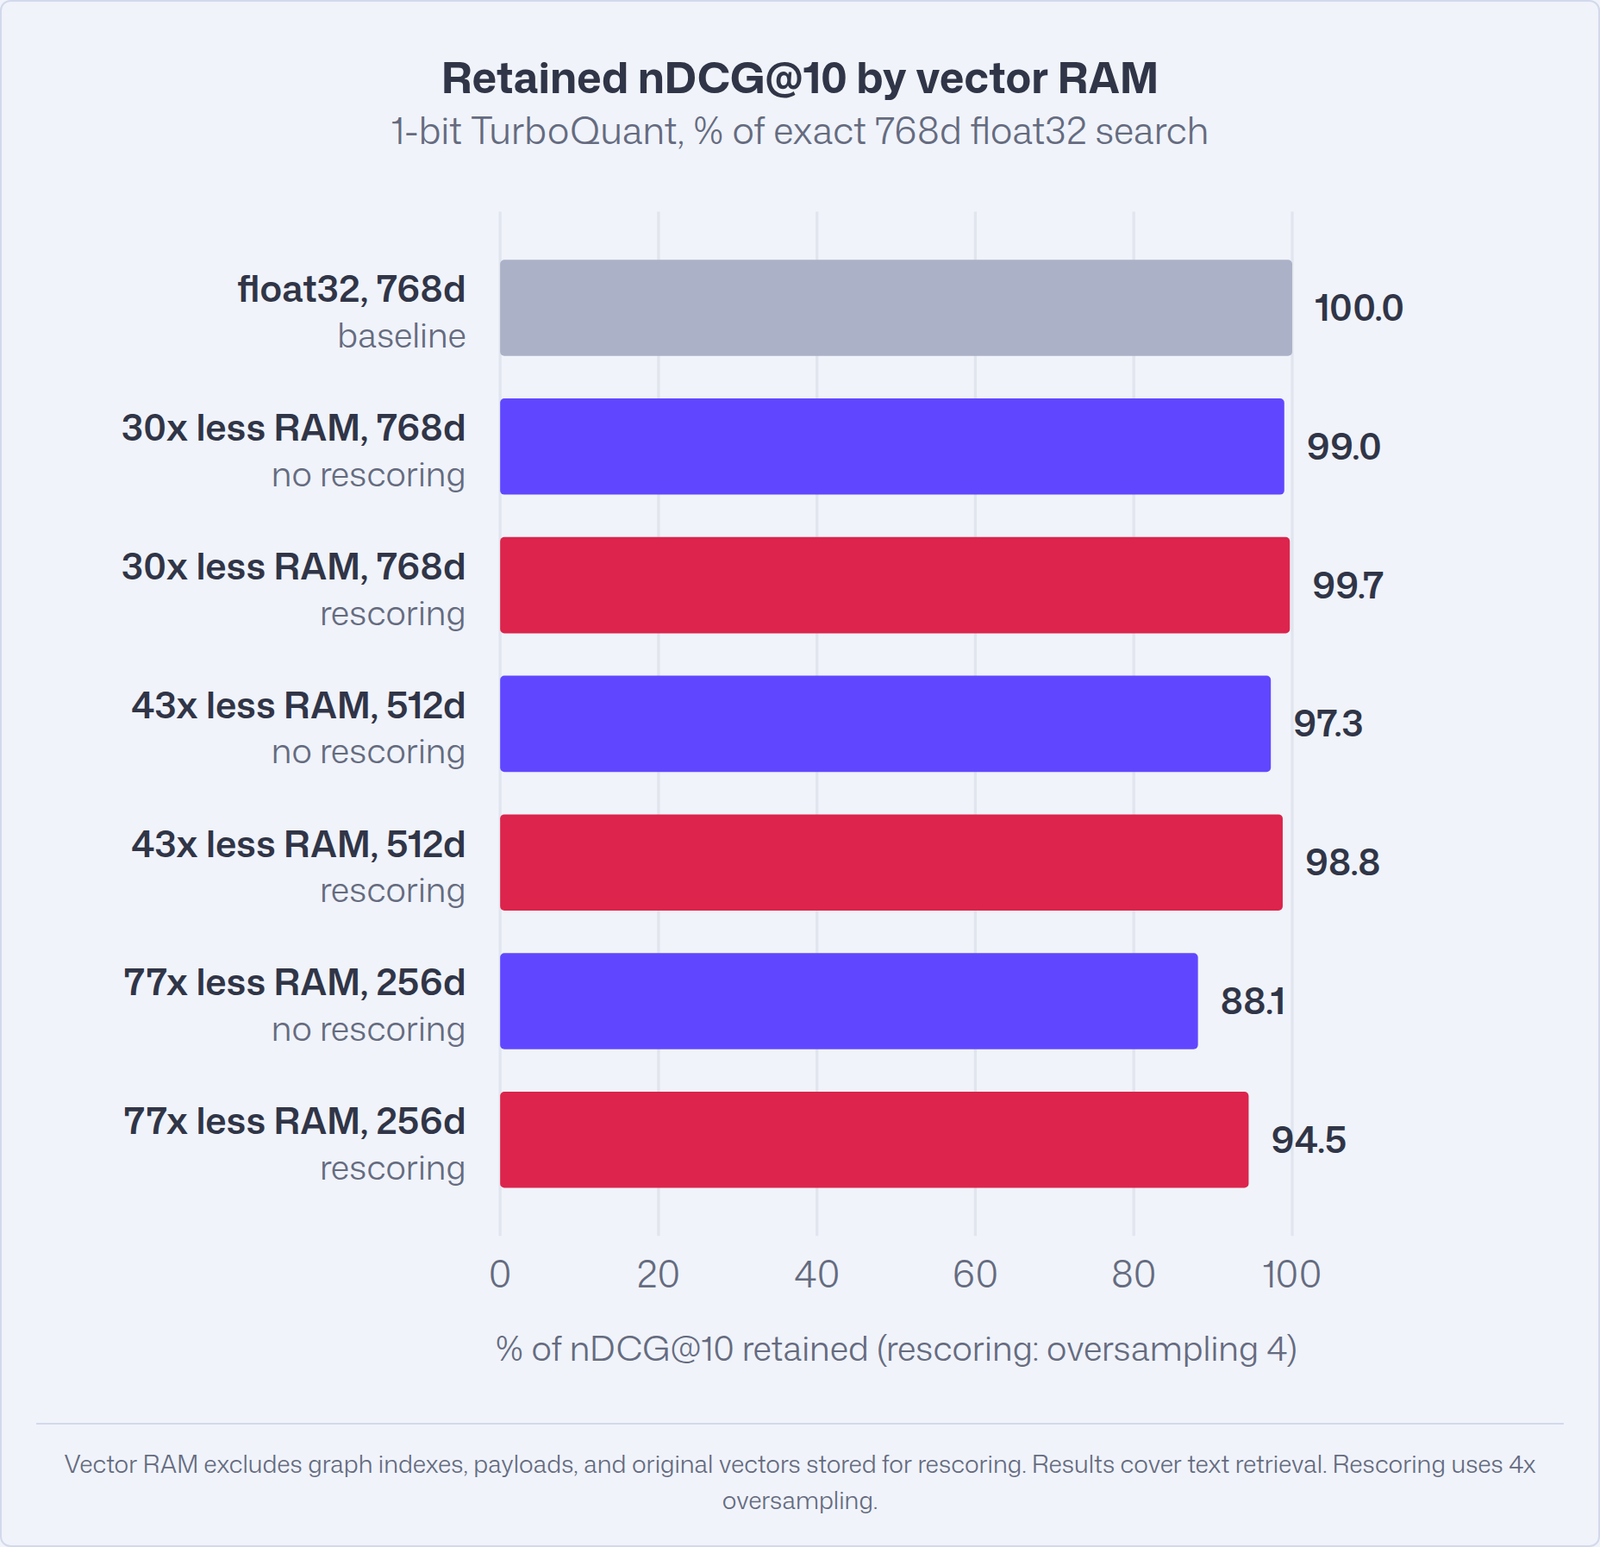
The footnote on that chart is the first thing I'd hold onto. "Vector RAM excludes graph indexes, payloads, and original vectors stored for rescoring." The 94.5% belongs to the rescoring bar, and rescoring means Qdrant fetches 40 candidates with the 1-bit codes and ranks them again with the original vectors, which have to be stored somewhere. At 256 dimensions in float32 that is another 10.24 GB, normally on disk and read on every query. So "0.4 GB of RAM with 94.5% kept" is true of the RAM, and the 94.5% also needs ten gigabytes of originals the RAM figure doesn't count. Without rescoring the same 0.4 GB keeps 88.1%, which is a 12-point drop, not 5.
The graph is the other thing left out, and at this compression it is the bigger one. Qdrant searches an HNSW graph, and with its usual m = 16 each vector keeps up to 32 neighbour ids of 4 bytes at the bottom layer. That is up to 128 bytes a vector, three times the 40-byte vector itself, and about 1.28 GB for ten million. That is my estimate of an upper bound, not a number Qdrant published, and real graphs fill fewer links than the maximum, but once vectors get this small the index structure around them is what you're actually paying for.
None of that makes the result bad. The configuration the blog itself recommends starting with is the full 768 dimensions at 1 bit with rescoring off: 104 bytes a vector, about 1 GB for ten million, and 99.0% of the baseline's nDCG@10. On Quora's 523,000 documents Qdrant reports it took less than half the query time of float32 search. That is the number I'd take from the post, more than the 77x. Two caveats the blog states itself. The retention is an average over five small BEIR sets (SciFact, NFCorpus, ArguAna, SCIDOCS and FiQA), so the ten million is a byte calculation, not a measured run. And 99% of the nDCG is not 99% of the same results: without rescoring, about 74% of the top 10 matched exact search.
The comparison I found most useful is one the blog makes in passing. At 72 bytes a vector you can have 512 dimensions at 1 bit, which kept 97.3%, or 128 dimensions at 4 bits, which kept 84.0%. Same memory, thirteen points apart. Cutting bits is cheaper than cutting dimensions, which fits the MRL table above: at 128 dimensions the model itself has already thrown away what the extra bits would have preserved. Qdrant's results are all text retrieval. Shivendu says in the replies that MRL and TurboQuant "work on any kind of embeddings", and mechanically they do, but the card's own table has the multimodal scores falling much faster under truncation than the text ones, so for an index of photos and recordings I'd keep 512 or 768 dimensions and take the savings from the bits.
Whose 1-bit quantizer it is
TurboQuant (Zandieh et al.) rotates each vector by a random orthogonal matrix so that every coordinate follows the same known distribution, then quantizes each coordinate with one fixed Lloyd-Max codebook. I walked through it for the KV cache in the TurboQuant article, and for vector search in TurboVec. At four or two bits the codebook is the interesting part. At one bit it isn't: the optimal one-bit quantizer for a symmetric distribution is the sign, so 1-bit TurboQuant stores the sign of each rotated coordinate. That is also exactly what RaBitQ stores.
Qdrant's own write-up is candid about this. The 8 bytes of per-vector scalars come from RaBitQ's length renormalization, not from the TurboQuant paper, and "The 1-bit scoring path follows RaBitQ as-is, without specific modifications": the query is scalar-quantized into bit planes and scored against the stored signs with an AND and a popcount per plane. One reply to the post, from @gaoj0017, quoted that line and called the "TurboQuant" label misleading. Going by Qdrant's own documentation, I agree. Every configuration in the EmbeddingGemma 2 chart is a 1-bit one, so what was measured is a RaBitQ-style 1-bit code with a Hadamard-type rotation in front of it. The name is the only thing wrong. Where Qdrant's TurboQuant does add something is at two and four bits, and its own benchmark shows the 1-bit version beating its older binary quantization on every dataset it tried.
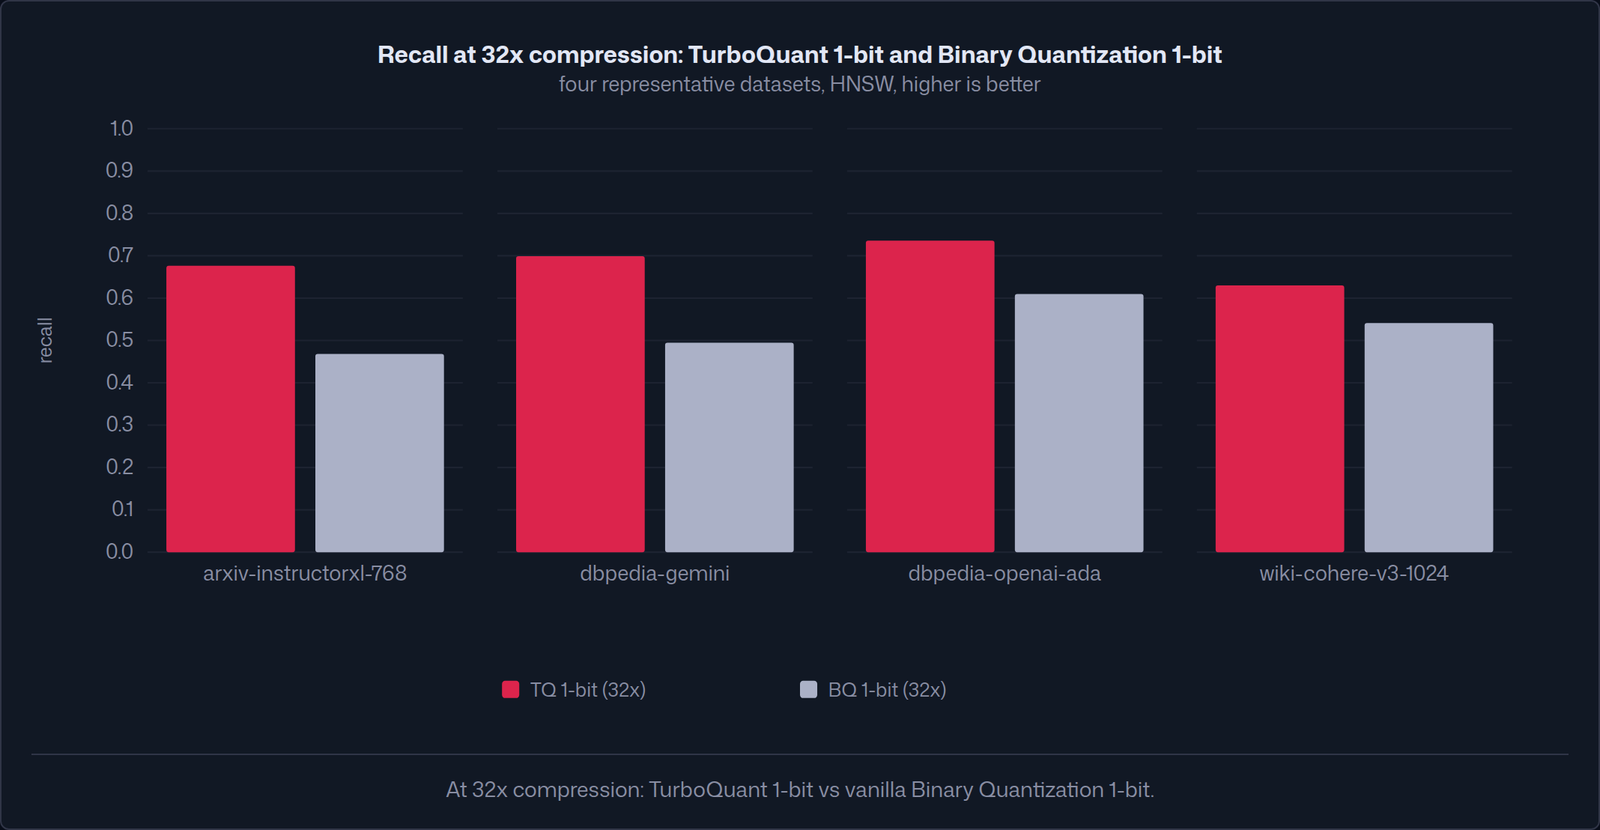
That chart is the honest summary. Plain binary quantization takes the sign of the raw coordinates; a random rotation first, plus a length correction and a multi-bit query, is worth 9 to 21 points of recall at the same 32x. Whoever's name goes on it, it is why 1-bit storage of EmbeddingGemma 2 vectors keeps 99% of the ranking quality. One other reply linked arXiv 2608.30384; that is RSLM, a separate training-free rotate-and-Lloyd-Max codec, not the TurboQuant paper.
On a phone
The LiteRT bundles use quantization-aware training: int4 per-channel for the transformer and the embedding table, int8 for the vision encoder, and a mix of int2, int4 and int8 for the audio encoder. The downloads are 165 MB for text only, 388 MB for text and vision, and 485 MB for everything.
The AI Edge post gives per-image vision latency across devices. The text-only number on the LiteRT card is the one I find most useful: 8.3 ms on a Pixel 11 Pro's TPU and 41.8 ms on an iPhone 18 Pro's CPU, both for a 128-token input.
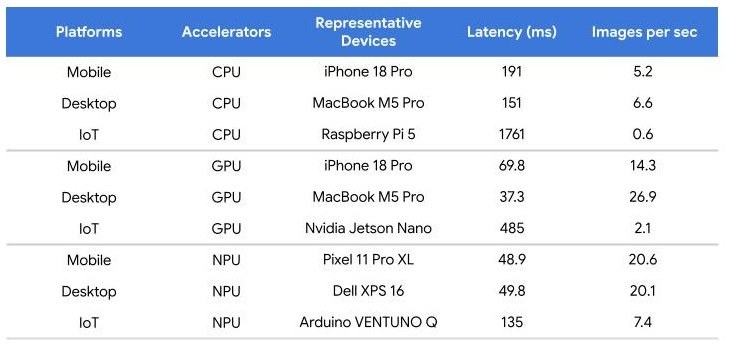
Note the 70-token budget in that table: a quarter of the default. The LiteRT bundles only expose 70 and 140 soft tokens per image, so the on-device model is running images at lower resolution than the benchmark table, which was measured at full precision with default settings. I couldn't find on-device quality numbers at 70 tokens.
The memory figures don't line up across sources. The blog says "~191MB active RAM for text-only weights and ~567MB for the full multimodal model" on a Pixel 11 Pro. The LiteRT card's Pixel 11 Pro row reports 112 MB and 127.5 MB, but it measures CPU memory only and says accelerator memory is excluded. The S26 Ultra on CPU reports 334 MB and 811 MB. I'd budget from the CPU rows for your own platform, not the headline.
Using it
The card's calls, put together the way I'd start a text index. I haven't run this here; it is
assembled from the card's and the developer guide's own examples, and needs
sentence-transformers 6.1.0 or later.
import torch
from sentence_transformers import SentenceTransformer

# bf16 or fp32 only: the card says fp16 overflows and returns NaN or degraded vectors
dtype = torch.bfloat16 if torch.cuda.is_available() and torch.cuda.is_bf16_supported() else torch.float32

# Text and code only: the vision and audio towers are never built (271M parameters)
model = SentenceTransformer(
    "google/embeddinggemma-2",
    config_kwargs={"vision_config": None, "audio_config": None},
    model_kwargs={"torch_dtype": dtype},
    truncate_dim=256,
)

files = {"pool.py": "def mean_pool(h, mask):\n    return (h * mask[..., None]).sum(1) / mask.sum(1, keepdim=True)"}

# Documents: format the title yourself; prompt_name="Document" would write "title: none"
docs = [f"title: {name} | text: {code}" for name, code in files.items()]
doc_emb = model.encode(docs, normalize_embeddings=True)

# Queries: the task prefix matters, and queries and documents must share a width
q_emb = model.encode("average token states ignoring padding", prompt_name="CodeRetrieval", normalize_embeddings=True)
print(model.similarity(q_emb, doc_emb))
Later, the same index takes photos and recordings from the full model, without re-embedding the text:
full = SentenceTransformer("google/embeddinggemma-2", model_kwargs={"torch_dtype": dtype}, truncate_dim=256)

photo = full.encode({"image": "IMG_0412.jpg"}, normalize_embeddings=True)    # no text prefix for media
memo = full.encode({"audio": "memo_16k_mono.wav"}, normalize_embeddings=True)  # chunk long audio first
listing = full.encode({
    "text": "Waterproof trail shoe. <|image|> Grip test on wet rock: <|video|>",
    "image": "shoe.jpg",
    "video": "grip.mp4",
}, normalize_embeddings=True)
The prefixes are listed in config_sentence_transformers.json: SearchQuery, QuestionAnswering,
FactChecking, CodeRetrieval, Classification, Clustering, SentenceSimilarity and
Document. Retrieval is asymmetric (a query prefix on one side, title: … | text: … on the
other); classification and similarity put the same prefix on both. Media go in without a prefix.
Because the pooling includes the prompt, the prefix changes the vector; mixing prefixed and
unprefixed text in one index is a quiet way to lose recall.
Half a gigabyte, and which half
A few hours after launch Unsloth posted that EmbeddingGemma 2 "runs locally on 0.5GB RAM", in the same breath as "740M parameter ... combines a 270M text model with vision (170M) + audio (300M)", and linked its own GGUFs and a guide. Read together, that sounds like the whole multimodal model in half a gigabyte. I wanted to know which configuration the number belongs to, so I read the GGUF headers of both repos the same way I read the safetensors one: range requests for the first few megabytes, then a parse of every tensor's name, shape and type.
The ggml-org conversion, made by the
same people who merged EmbeddingGemma 2 support into llama.cpp (pull request 30054, merged on
launch day), has four files: a text model in BF16 and Q8_0, and an mmproj in BF16 and Q8_0.
Unsloth's repo has those four with byte-identical tensors (same 413 and 963 tensor lists, same
types, the last 4 MB of each pair hash the same; the files differ by 64 to 96 bytes of name
metadata), plus three "UD" text quants, Q4_K_XL, Q5_K_XL and Q6_K_XL, and F16 copies of both
files. That is the whole difference.
| File | Size | What is inside |
|---|---|---|
| text, UD-Q4_K_XL (Unsloth) | 175.7 MB | 271,002,648 params; Q4_K almost everywhere |
| text, UD-Q5_K_XL (Unsloth) | 210.1 MB | Q5_K, with Q6_K on attn_v and ffn_down in 12 of the 24 layers |
| text, UD-Q6_K_XL (Unsloth) | 248.8 MB | Q6_K throughout |
| text, Q8_0 (both) | 309.9 MB | Q8_0, the per-layer projection kept in BF16 |
| text, BF16 (both) | 558.0 MB | unquantised |
| mmproj, Q8_0 (both) | 554.8 MB | 473,369,344 params: vision 167.4M, audio 304.8M, two projections 1.2M |
| mmproj, BF16 (both) | 982.1 MB | unquantised |
The text file is exactly the 271M path from the safetensors header: token table, 24 blocks, the
projection-only PLE (per_layer_model_proj, 512 x 12,288) and the 512-to-768 output head, stored
as output.weight. There is no per-layer token table in it, which confirms the reading above from
a second, independent implementation; llama.cpp's graph comments the function "this model has no
per-layer token embeddings, the per-layer inputs come only from the projection". The header also
answers the window question from earlier: it stores sliding_window = 1024, and llama.cpp's
symmetric mask divides it by two, masking anything more than 512 positions away on either side.
Same window, written down two ways.
Two things in the files surprised me. About 15.8 MB of every text GGUF, 9% of the Q4 file, is
not weights at all: it is the header, holding the 262,144-token vocabulary and 514,906 BPE merges.
And the Q4_K_XL is less exotic than the "UD" label suggests. Every large matrix, the embedding
table included, is plain Q4_K; what gets more bits are the small pieces, the per-layer gate and
projection in every block (Q8_0), the PLE projection (Q5_K) and the output head (Q6_K). For a
model whose last step is one 512 x 768 matrix that every embedding passes through, protecting
that matrix is the sensible choice. The quantisation was calibrated with an importance matrix
over 230 chunks of a text file (quantize.imatrix.dataset = data/calib.txt in the metadata),
which is fine for a text index and says nothing either way about how image or audio tokens fare,
since images and audio pass through the same quantised blocks.
On the multimodal side there is only one mmproj, and it holds both towers. I checked what
llama.cpp does with that: clip_init builds a vision context if the file has a vision encoder
and an audio context if it has an audio encoder, with no switch to skip either (the only
exception in the code is Gemma 3n). So the four configurations from the model card collapse to
two in this runtime, text only or everything. The 440M "text and vision" setup doesn't exist in
GGUF form; you carry the 305M audio tower whether you use it or not. The smallest mmproj is Q8_0,
and even that one is 70.5 MB of F32, most of it the vision tower's 768 x 10,240 x 2 position
table (62.9 MB), upcast from the BF16 it was stored in.
The arithmetic for 0.5 GB
For an embedding model llama.cpp builds no KV cache (build_attn_inp_no_cache in the
gemma-embedding2 graph): every input is read once, in one batch. So the memory is the weights
plus whatever the forward pass needs at once, and the forward pass has one large resident:
the per-layer inputs. They are computed for every position before the first layer runs and kept
until the last, 24 layers x 512 values x 4 bytes, which is 49,152 bytes per token.
At the 2,048-token context Unsloth's guide uses, that tensor is 100.7 MB. Add the 175.7 MB Q4 file, and the scratch for one layer (the 2,048-wide feed-forward activations are about 34 MB; the global layers' attention scores, if flash attention is off, are 4 heads x 2,048 x 2,048 x 4 bytes, 67 MB), and the total comes out around 0.4 GB. So for text and code, at that context, "0.5 GB" is believable. At the full 8,192 tokens the per-layer inputs alone are 402.7 MB, and a text-only Q4 run is already past half a gigabyte before anything else.
With pictures and sound it isn't close. The smallest files that can embed an image are the Q4 text model plus the Q8_0 mmproj, 730.5 MB on disk before a single activation. The figure that does fit the full model is Google's own: about 567 MB of active RAM for the full multimodal model on a Pixel 11 Pro, but that is the LiteRT bundle, whose audio encoder is partly int2, not a GGUF.
So I'd read Unsloth's 0.5 GB as true of the 271M text configuration at a modest context, and of Google's LiteRT build for the whole model. Through Unsloth's own files, the whole model needs about 0.73 GB before it starts. These are sums from the headers and the graph code; I didn't run llama.cpp here, so the scratch sizes are an estimate of what its allocator holds, not a measurement.
One more thing the repo contains that I wouldn't use: F16 copies of both files. The model card says EmbeddingGemma 2's activations exceed float16's range and come back as NaN or silently degraded, and Unsloth's own guide repeats "Do not use FP16". In ggml's CPU path an F16 weight matrix is multiplied against activations converted to F16, so the F16 GGUF is the one file where that warning plausibly applies. Take BF16 or Q8_0.
Running it
Unsloth's llama.cpp recipe serves text and code only. The part worth copying is the flags:
# unsloth.ai/docs/models/embeddinggemma-2, "Run EmbeddingGemma 2 GGUFs in llama.cpp"
./llama.cpp/build/bin/llama-server \
  --model "embeddinggemma2-gguf/embeddinggemma-2-UD-Q4_K_XL.gguf" \
  --alias embeddinggemma2 \
  --embeddings \
  --pooling mean \
  --ctx-size 2048 \
  --batch-size 2048 \
  --ubatch-size 2048 \
  --parallel 1 \
  --host 127.0.0.1 \
  --port 8080
--pooling mean matches the sentence-transformers pooling; the GGUF also carries
pooling_type = 1, which is mean. The three sizes have to move together because a non-causal
model can't split one input across batches: every token attends to every other, so an input has
to fit in one physical batch. And the server does nothing about prompts. The guide's request
writes them by hand, task: search result | query: ... for the query and title: none | text: ...
for the document, and that is required: as noted above, the prompt is part of the mean.
The guide's closing hint is honest about the rest: "For images, video or audio, use a runtime with explicit support for those encoders and their processor files." I didn't check whether llama-server's embeddings endpoint feeds an mmproj today. If you need media embeddings outside Python, LiteRT is the path Google tested.
Unsloth also wired EmbeddingGemma 2 into Unsloth Desktop as the embedding model for its document chat. The settings screenshot in the guide labels it "Not downloaded · 135 MB". That matches none of the files: the smallest GGUF is 175.7 MB and the safetensors is 1.49 GB. I couldn't find which artefact it refers to.
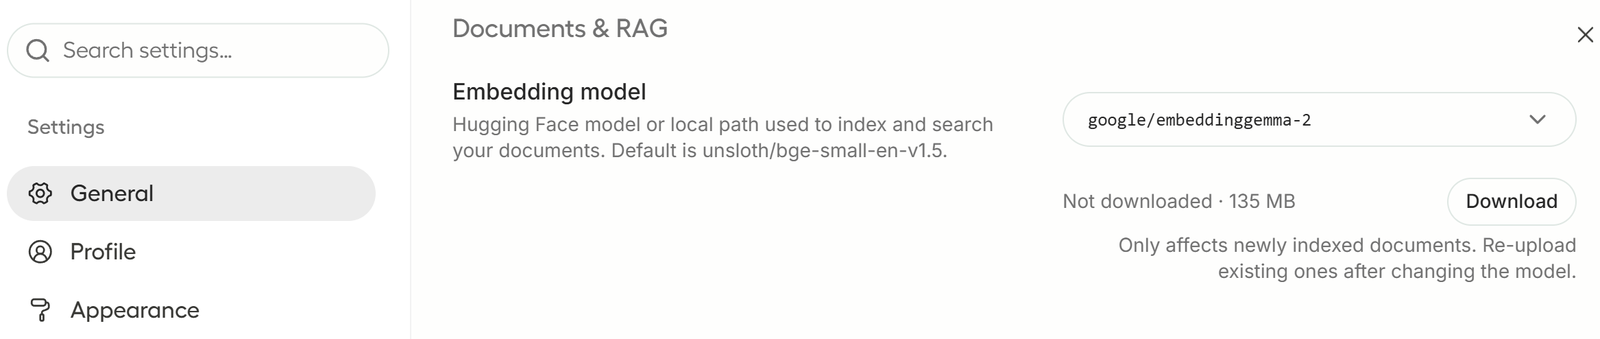
That last line in the screenshot is the right instinct, and it leads into the fine-tuning part.
Fine-tuning moves every modality at once
Unsloth's guide trains the text model with LoRA. It saves the text-only configuration first, then loads it in 4-bit and attaches adapters to every attention and MLP projection:
# unsloth.ai/docs/models/embeddinggemma-2, "Prepare the model"
model = FastSentenceTransformer.from_pretrained(
    model_name = "embeddinggemma2-text",
    max_seq_length = 1024,
    dtype = torch.bfloat16,
    load_in_4bit = True,
    load_in_16bit = False,
    full_finetuning = False,
)

model = FastSentenceTransformer.get_peft_model(
    model,
    r = 16,
    target_modules = [
        "q_proj", "k_proj", "v_proj", "o_proj",
        "gate_proj", "up_proj", "down_proj",
    ],
    lora_alpha = 32,
    lora_dropout = 0,
    bias = "none",
    use_gradient_checkpointing = "unsloth",
    random_state = 3407,
    task_type = "FEATURE_EXTRACTION",
)
Training is sentence-transformers' SentenceTransformerTrainer with
MultipleNegativesRankingLoss, which is the in-batch-negatives contrastive loss from the training
section above, a no-duplicates batch sampler (so a repeated query never becomes its own negative),
bf16=True and the query and document prefixes applied to the training columns. The guide's
advice to hold out queries and compare before and after is the part people skip and shouldn't.
Two remarks on the recipe. Loading a 271M model in 4-bit saves about 0.4 GB of weights, which is small next to the activations at a training batch; the text notebook's own log puts peak reserved memory at 11.3 GB on a T4. Plain 16-bit LoRA costs little more here and trains against the weights you will actually deploy. And the adapters don't reach the per-layer gates, the PLE projection or the 512-to-768 head, which is fine for adapting a domain.
The bigger point follows from the architecture. An image embedding is the text encoder's average
over the image's soft tokens, and so is an audio one. LoRA on q_proj through down_proj of the
text model therefore changes the vector for every photo and recording too, even though the
training data was only text. The "embeddings you have already computed do not need to be
re-computed" property from the modular section holds for adding towers, not for training the
reader: after a fine-tune, everything in the index has to be re-embedded, and the image-text
alignment has been nudged by a loss that never saw an image. If the index is mixed, train on
mixed pairs, or keep the fine-tuned model for text and test cross-modal recall before swapping it
in.
Unsloth does have mixed-pair notebooks. The image one trains on 3,000 Flickr8k images with five
captions each and tests on the Flickr30k 1K split, adding finetune_vision_layers = True so the
vision tower gets adapters too; the audio one trains on Clotho clips with
finetune_audio_layers = True. Note what the second does to the claim about sharing an audio
encoder with Gemma 4: once those adapters are merged, the tower is no longer byte-identical to
Gemma 4 E2B's, and a runtime that loads it once for both models can no longer do so.
None of the three notebooks shows an EmbeddingGemma 2 result yet. The image and audio ones have no saved outputs. The text one does, but they come from the earlier model: its log reads "Fast Gemma3 patching" with transformers 4.57.3, and "Trainable parameters = 13,074,432 of 315,937,536". Rank-32 LoRA on EmbeddingGemma 1's 24 layers (768 wide, 1,152 MLP) is 8,355,840 parameters, and its two dense head layers, 768 x 3,072 each, add 4,718,592; together that is exactly the 13,074,432. The NDCG@10 of 0.9267 before and 0.9351 after on the medical set are EmbeddingGemma 1 numbers, in a notebook titled for EmbeddingGemma 2.
What else the launch blog says
A few things in Google's launch post I haven't covered. EmbeddingGemma 1 passed 20 million downloads, which is the context for a second version. The 8K window is four times EmbeddingGemma 1's. Besides LiteRT there is a MediaPipe Decision Task API for classification and routing on top of the embeddings, and a Foresight app that pairs EmbeddingGemma 2 retrieval with Gemma 4 generation, which is where the shared-audio-encoder argument would pay off. The blog lists day-one support in transformers, sentence-transformers, MLX, vLLM, llama.cpp, SGLang, Ollama, LM Studio, transformers.js and Qdrant, and points to Unsloth for fine-tuning. Omar Sanseviero's launch post summed up the release as "Modular, going from 270m to 740m parameters", which after reading the llama.cpp loader I'd amend to: in GGUF, 271M or 744M, nothing in between.
Typed Decision: a decision head on the 271M
Added 12 October 2026.
Five days after launch, Manuel Romero (mrm8488) published Typed Decision, the text encoder fine-tuned to answer typed questions about a piece of state: a choice among named options, a level on a rubric, or a yes/no probability, the three System One primitives this site has followed since Jev. His post put it at "76.4% on typed-decisions, ~6 pts behind a 27B LLM with ~100× fewer params". One of the first replies asked the obvious question: the AI Edge post above already sells EmbeddingGemma 2 as a zero-shot "decision engine", so what does the fine-tune add? The answer is in the code, and it's a nice small design.
The state, each question and each option are embedded separately by the same 271M text encoder,
with the task: classification | query: prompt and mean pooling. Before embedding, the state is
flattened from JSON into key: value lines, so {"trace_summary": {"constraint_violations": 1}}
becomes trace summary · constraint violations: 1, which an embedding model reads far better than
braces. Every option is embedded as a whole sentence,
question: <instructions> | answer: <key>: <description>; a score level becomes level 2 of 3: significant risk, and a yes/no question is
just two options whose answers are "no" and "yes". Then a head of about a million parameters turns
those vectors into one logit per option:
# modeling_gemmadecision.py:210-222
S, Q, O = self.state_proj(s), self.question_proj(q), self.option_proj(o)
f = self.field_norm(self.field(torch.cat([S, Q, S * Q], -1)) + self.type_emb(kind))
On = self.option_norm(O)
...
joint = self.log_joint_scale.clamp(max=cap).exp() * F.cosine_similarity(f, On, dim=-1)
residual = self.residual(torch.cat([f, On, f * On, (f - On).abs()], -1)).squeeze(-1)

anchor = F.normalize(s + q, dim=-1).unsqueeze(-1)
prior = self.log_prior_scale.clamp(max=cap).exp() * (F.normalize(o, dim=-1) @ anchor).squeeze(-1)

logits = prior + torch.sigmoid(self.gate) * (joint + residual)
If that formula looks familiar, it is Cloudflare's Clef joint-schema head, the one
Unsloth vendored: a fixed prior,
plus a gated sum of a learned cosine and a small MLP over the usual matching features. The
difference is what feeds it. Clef reads an LLM's hidden states, where each option's tokens can
attend to the whole prompt. Here every text is pooled into one 768-wide vector before the head
sees it, so the option never reads the state; the only place they meet is a 256-wide layer in
the head. And the prior term is exactly the reply's answer: the cosine between an option's
embedding and the normalised sum of state and question is what an untrained embedding model does
when you use it as a zero-shot classifier. The fine-tune keeps that and learns a correction on
top.
I read the trained scalars out of the safetensors file with range requests. The prior's scale is 20.5 and the joint scale 11.0, both close to where they were initialised (20 and 10). The gate went from -2.0 to -1.92, so the learned term is still multiplied by σ(-1.92), about 0.13. The residual MLP's output is unbounded, so I can't say from the weights alone how big the correction gets on a real input. But the card's own numbers suggest where the gain came from. Training the head alone on frozen embeddings scored 67.7%; unfreezing the encoder lifted it to 76.4%. Most of the work went into making the encoder's cosines sharper, with a head that barely opened its gate.
The header totals 272,120,354 values: the 271.0M encoder (half of it, 134.6M, is the token embedding table, which phase 2 kept frozen), a head of 1,117,700 parameters, and the three temperatures. The card says the head is "~0.5M"; the file says about twice that.
There's a deployment property here that the card doesn't mention. A case in the test split needs
22 to 26 texts embedded (one state, five questions, their options), and the test split has only
four distinct schemas. Everything except the state is the same for every case of a workflow, so a
server could embed the schema once and pay one 271M forward pass per new state. The shipped
decide() doesn't cache across calls, it re-embeds the schema each time, but the design allows it,
which an LLM-backed head never can.
Checking the numbers
The 76.4% is on the right split: LocalLLaMA/typed-decisions, subset all, the 400-case test set,
argmax against the gold label. The per-type figures add up. Weighting 71.2% on 600 choice
decisions, 74.0% on 800 score decisions and 84.8% on 600 yes/no decisions gives 1,528 of 2,000,
which is 76.4%. Score questions are the weakest, and the card says why: numbers inside the state
are hard for an embedding model.
Two qualifiers belong next to it. It was trained on that benchmark's train split, so it belongs
in the leaderboard's second table, the fitted models, not next to zero-shot rows like Jev's 0.727.
And the card says plainly that "hyperparameters were chosen while looking at the test split, so
treat these numbers as slightly optimistic". I respect that sentence; few cards carry it.
The 27B LLM isn't named anywhere on the card. The only 27B on the benchmark's Hub leaderboard is
Darwin-27B-ZTC-v5, released on 11 October, the
same day, at 0.812, and also fine-tuned on train. Against that the gap is 4.8 points, not six.
The Hub counts 25.6B parameters in it, about 94 times this model's 272M, so "~100×" is fair. Its zero-shot sibling,
Darwin-27B-ZTC, scores 0.743, which this model beats; the comparison only flatters the 27B when you
pick the fine-tuned one, which is the right one to pick.
Then there's the Laya row this site has quoted since the relational-choice
piece: "Laya (fine-tuned), 2,000 typed decisions, 0.766". Same
benchmark, same test split, same train-fitted table, same accuracy definition, both
self-reported. So the two are directly comparable, and Typed Decision is 0.764 to Laya's 0.766,
four decisions out of 2,000. It isn't the same number travelling under a new name; Laya is a 421M
ModernBERT-large, this is EmbeddingGemma 2. It's a coincidence, and a gap that size is noise. In
the same fitted table soft-decider-421m reports 0.774 and OpenDecider-nano, a 400M encoder, 0.796.
Typed Decision is a respectable mid-table entry for its size, not a new high.
What "calibrated" rests on
The card reports a soft cross-entropy of 0.887 and a Brier score of 0.065, against 0.968 and 0.113 for the frozen-encoder phase. It reports no ECE and no KL. Calibration in the training recipe is one temperature per question type, fitted on held-out training rows, and the three stored in the file are 1.005 for choice, 1.144 for score and 1.056 for yes/no: the fitted model was already close to calibrated on held-out rows and needed only a slight softening of its score answers.
The benchmark's leaderboard ranks KL from gold, not cross-entropy, but one converts to the other. KL is cross-entropy minus the gold distribution's own entropy, and I computed the mean entropy of the 2,000 test gold distributions: 0.767 nats. If the card's 0.887 is a mean over the same 2,000 decisions in nats, the KL is about 0.12. That puts it level with Aplomb 1 (KL 0.123, Brier 0.065 on its own submission) and behind the best fitted rows, which sit near 0.08 KL and 0.043 Brier. The Brier looks like the leaderboard's definition, squared error summed over options: the code's loss sums it that way, and the same definition reproduces the leaderboard's uniform reference of 0.238 on the test gold. I couldn't check the evaluation script itself; it isn't in the repo.
The card's limitations section makes the point I'd want every decision-model card to make: on this benchmark "calibration means 'matches annotator disagreement'". The gold is the mean of three samples from a teacher, so a 43% answer where the teacher split 43/28/25 is correct, and the model is being calibrated against a roughly 4B-class teacher's uncertainty, not against the world. The benchmark's own README adds that its teacher only agrees with itself 73.5% of the time, which 76.4% is already above.
Would I use it? For a fixed set of workflows on a phone or a CPU, yes, ahead of a prompted LLM: one forward pass per state, typed output that can't fail to parse, and Apache 2.0 like the base. The multilingual claim is backed by one probe, cosine between English/Spanish translation pairs moving from 0.869 to 0.901, which shows the encoder didn't forget Spanish, not that the decisions transfer; the card itself says the head was trained on English schemas only. I would not expect it to answer a question where one option's meaning depends on another; with every option pooled on its own, it has the same blind spot Jev showed on relational choice.
An embedding model that transcribes, and what it actually runs
Added 13 October 2026.
On 12 October Shahir (@TslShahir), an on-device ML engineer, posted that he had "turned EmbeddingGemma 2, an embedding model, into a speech-to-text model", and that on a base M3 MacBook Air it "transcribes an hour of audio in about 13 seconds: 288× real time". The pitch is the one Google makes for the model: a spoken word and a written word land next to each other in the shared space, so you ought to be able to read a transcript straight out of it. His follow-up post gives the recipe in one line. The model stays untouched, and "a small reader on top takes each slice of audio, finds the nearest of ~229,000 words in the model's own text space, and strings them together."
My first reaction was that this can't work as described. Embedding a 20-second clip with EmbeddingGemma 2 gives you one pooled vector, and one vector can't hold a sentence. So the reader has to be getting at something before the pooling. The code isn't public yet ("Soon", he replied when asked), but the free Mac app downloads its models from a public manifest, and Core ML packages describe themselves. I read those instead.
Four files and a dictionary
The current manifest (version 5, 714,975,724 bytes, which is the "715 MB download") holds four networks and one big table. I sized each from its Core ML metadata and weights file:
| File | What it is | Size on disk |
|---|---|---|
eg2_audio_l11 | EmbeddingGemma 2's 12-layer audio conformer, 2,000 mel frames in, 500 vectors of 1,024 out | 227 MB, 6-bit palettes |
reader_P6 | a 12-layer, 768-wide transformer, 86.45M parameters by its own config | 66 MB, 6-bit palettes |
word_unit_f16.bin | 229,457 words × 768 dimensions, float16, unit length | 352 MB |
scorer_blk_d128… | a 768-to-128 projection and a 128-wide copy of the word table, for shortlisting | 59 MB |
punct_headonly | punctuation and capitalisation from the word vectors | 7 MB |
The 352 MB is exactly 229,457 × 768 × 2 bytes, so half the download is a dictionary, kept at 16-bit. The "6-bit" in his reply about resource use covers the two networks, not the whole thing.
Then the part I'd been suspicious of. The encoder is cut at its last conformer layer: the graph's
output is called l11 and is 1,024 wide, and nothing in it is 1,536 wide, so the tower's output
projection isn't there. Nor is embed_audio, the 1,536-to-512 layer that hands audio to the text
encoder, nor the 271M text encoder itself. The parts of EmbeddingGemma 2 that put sound into the
shared space aren't in the app. The reader takes the conformer's raw 40 ms frames (500 per 20-second
window, the same 25 a second as in Spending the window), runs full attention
across all 500 of them, and emits, for each frame, a 768-wide vector and a single "blank" score.
That shape is CTC, the non-autoregressive recipe behind most fast recognisers: every 40 ms slice
either says "nothing new here" (blank) or names a word, and a cheap pass collapses the repeats. The
twist is the output layer. A normal CTC head learns a weight row per vocabulary item. Here the rows
are frozen: they are the 229,457 unit vectors in word_unit_f16.bin, and the reader's config
carries a temperature of 39.86 and an offset of -0.46 to turn cosines into scores. The dictionary
even has a <rep> entry, which looks like a marker for a word said twice in a row. Of all 229,457
entries only one contains a digit (dev2), so numbers come out spelled.
Why the temperature matters is visible in the table itself. I pulled a few rows with range requests. "cat" sits 0.944 from "kitten" and 0.872 from "dog", but also 0.73 from "the": everything in this space is close to everything. The homophones the reader must split are closer still, "two" at 0.869 from "too" and 0.845 from "to". Multiplied by 39.86, the 0.07 between kitten and dog becomes about 2.9 logits, enough for a softmax to pick a winner. The vectors behave like text embeddings, which fits his description, but I didn't run EmbeddingGemma 2's text encoder to confirm they came out of it.
Scoring 500 frames against 229,457 words in full would be a 500 × 768 × 229,457 matrix multiply per window. The scorer does it in 128 dimensions instead (a learned projection, not a Matryoshka cut; it isn't the identity on the first 128 columns), groups the words into blocks of four, and keeps the 16 best blocks per frame. That leaves 64 candidates to rescore at full width, which he says happens on the GPU while the networks sit on the Neural Engine.
Untouched, as far as I can tell
The app's NOTICE says "EmbeddingGemma 2's audio encoder was fine-tuned". The post says it stayed
untouched. The weights side with the post. The encoder's normalisation vectors are stored as plain
float16, so I compared four of them in each of layers 0, 5 and 11 against google/embeddinggemma-2:
identical, every value. The big matrices are stored as 6-bit indices into small lookup tables, so I unpacked
the query projections of layers 0 and 11, the value projection of layer 6 and the second
feed-forward matrix of layer 11 and compared them too. Also identical, with zero error.
Zero error from a 6-bit palette surprised me until I looked at Google's weights. Each row of those matrices holds at most four distinct values; the audio tower already shipped quantised that hard, so a 64-entry table per 16 rows loses nothing. And since I showed above that this tower is Gemma 4's, byte for byte, the encoder in this app is Gemma 4's speech encoder.
That changes how I read the headline. Gemma 4's audio tower was trained to feed a language model that transcribes speech, so the frames coming out of layer 11 should already carry what was said. What the app proves is that an 86M reader trained in under two hours (his figure, on 8×H100) can decode those frames into a fixed word list, and that EmbeddingGemma 2's text space makes a good fixed word list. It doesn't show that the pooled embedding contains a transcript. "An embedding model turned into speech-to-text" is true of the download; "read straight out of the embedding model" is a nicer story than the graph tells.
I still think it's a clever piece of engineering. A frozen 229,457-way output layer means the vocabulary is just a file: add a word by embedding it, no retraining. That's also why it can be fine-tuned in minutes, as he says it can, on an hour of your own audio. Only the 86M reader moves.
The 288×
The arithmetic doesn't close at first. An hour in about 13 seconds is 3,600 ÷ 13, about 277×, not
288×. The site that hosts the app has the exact figure, "1 hour in 12.6 s", and 3,600 ÷ 12.6 is
286×, still short. The clip settles it. The test file is speckled-band-librivox-1h.wav, and it is
60 minutes 30 seconds long: 3,630 ÷ 12.6 = 288.1. So the 288× is honest; the "hour" is 30 seconds
longer than an hour and the 13 is rounded. The progress bar also counts 202 windows for that file,
one every 18 seconds of audio, which suggests 20-second windows with about 2 seconds of overlap.
Two things in the same material don't line up as neatly. The run in the clip isn't the 12.6-second one; it finishes in 15.7 seconds at 231×, which is 3,630 ÷ 15.7 again. A screen recording running at the same time would explain the gap, but that's my guess. And the speed table's comparison row, IBM Granite Speech 5.0 TurboCTC on the same Air, reads "~150×" over "1 hour in 25.7 s", which is 141× on 3,630 seconds and 140× on 3,600. The "about twice as fast" holds either way (25.7 ÷ 12.6 is 2.04). The three Parakeet rows come from FluidAudio's published benchmarks on M4 Pro and M5 Pro machines with different audio, and the table's own footnote calls them "a rough guide, not a like-for-like ranking", which is right.
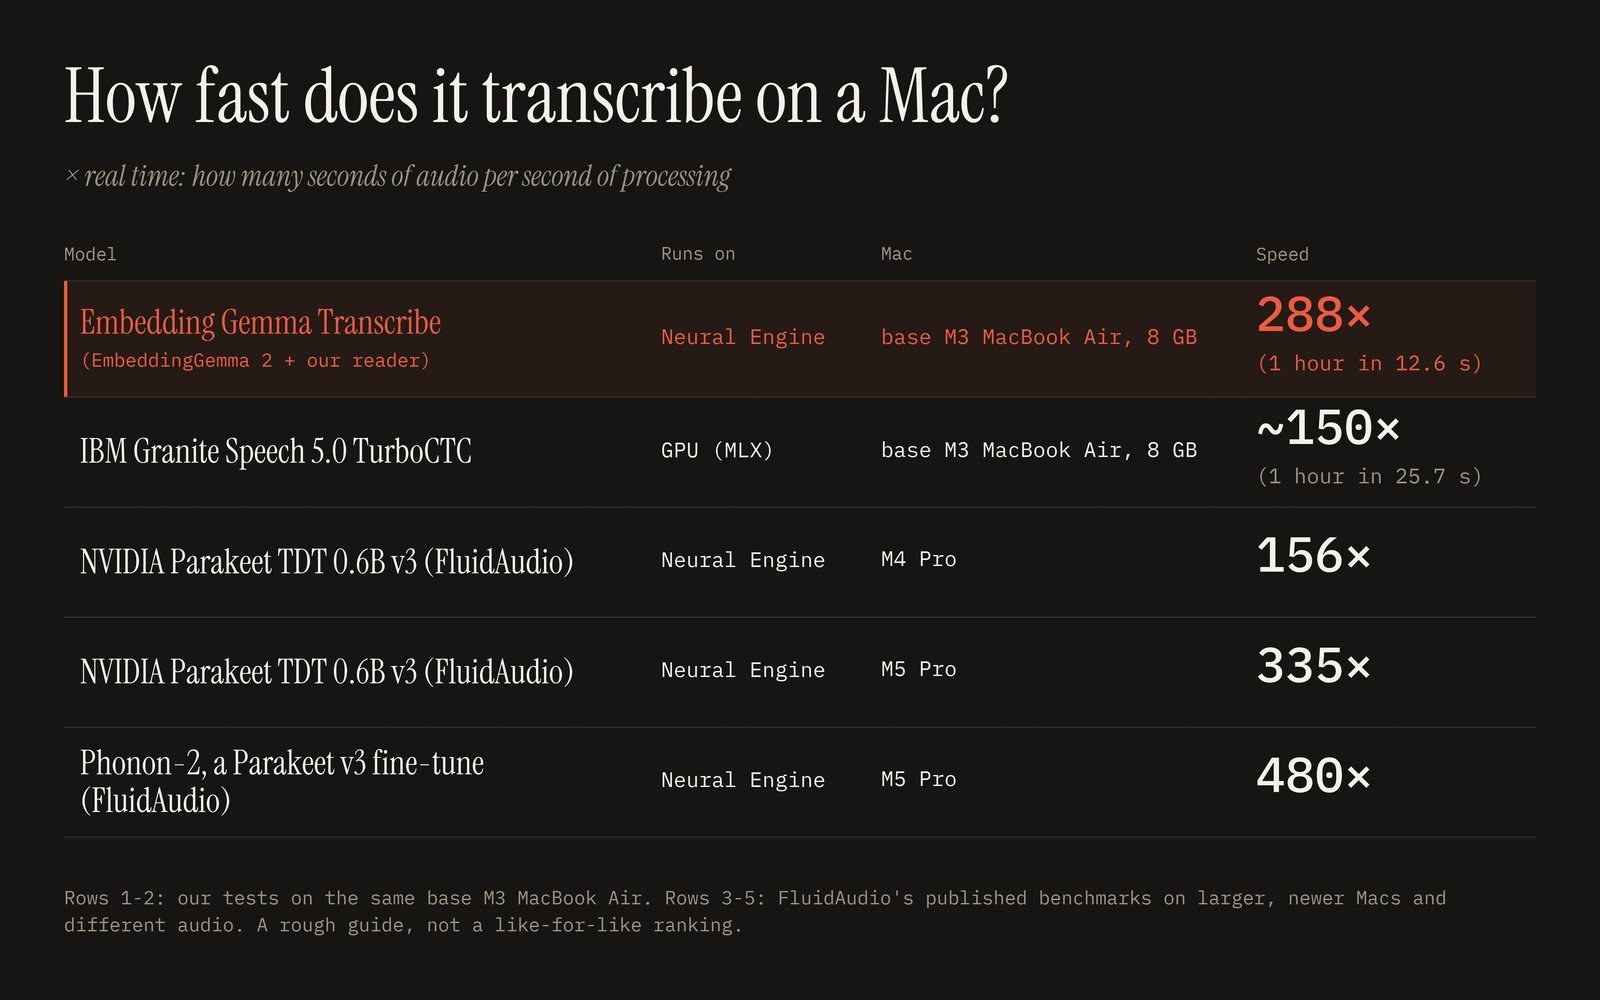
None of the speed figures is something I could check: I have no Mac here, and the app is a binary. Neither is the accuracy. In replies he gave 5.18% word error rate on LibriSpeech test-clean and "about 11.5-11.8%" on "the harder test", presumably test-other, against "2–3% for leading STT models". In another reply he said "5% is on synthetic voice", and on his own recordings "around 10". I can't tell which set the 5% belongs to. The clip itself shows the kind of mistakes you'd expect from a word-level reader without a language model: "the sorcerer of milk" for the saucer of milk, "at any raid" for at any rate, "grimes's roylott" a few lines after it got "grimesby roylott" right. The transcript in the clip is all lowercase and unpunctuated, even though the punctuation model is in today's manifest. English only, for now.
For a sense of where 288× sits: the reply that brought up Desert Ant Labs said their compressed Parakeet runs faster still, and someone else quoted 150-200× for faster-whisper's small.en on a 6 GB GPU. Neither is on the same machine, so I won't rank them. What I'd say is that the speed comes mostly from being CTC on the Neural Engine, with no decoder loop, about 62 ms per 20-second window if you divide 12.6 s by 202, and less from the embedding model.
A list of what people built in the first week
Feiteng (@FeitengLi) collected the community projects into awesome-EmbeddingGemma. It says plainly that it reviewed sources and didn't test the runtimes. I cloned the apps it lists and read them. The three worth knowing about are the same idea on three systems.
DigUp is the original: a menu-bar search for a Mac's files,
running ggml-org's Q8_0 GGUFs through llama.cpp on Metal (309,855,456 bytes for the text model plus
554,821,024 for the image and audio encoders, the "865 MB" it downloads). Two details show its author
read the model closely. Audio is cut into 30-second windows with a 25-second hop, and the comment on
audioWindow in Model.swift:66 reads "the model silently ignores audio past 30 s of one input",
the same default I found in the processors. And ranking adds a z-scored cosine to a bonus for exact
word matches; a comment in Searcher.swift:177 says that beat reciprocal-rank fusion on both of its
evals (R@1 0.88 against 0.73 on a synthetic set, 0.86 against 0.82 on real files).
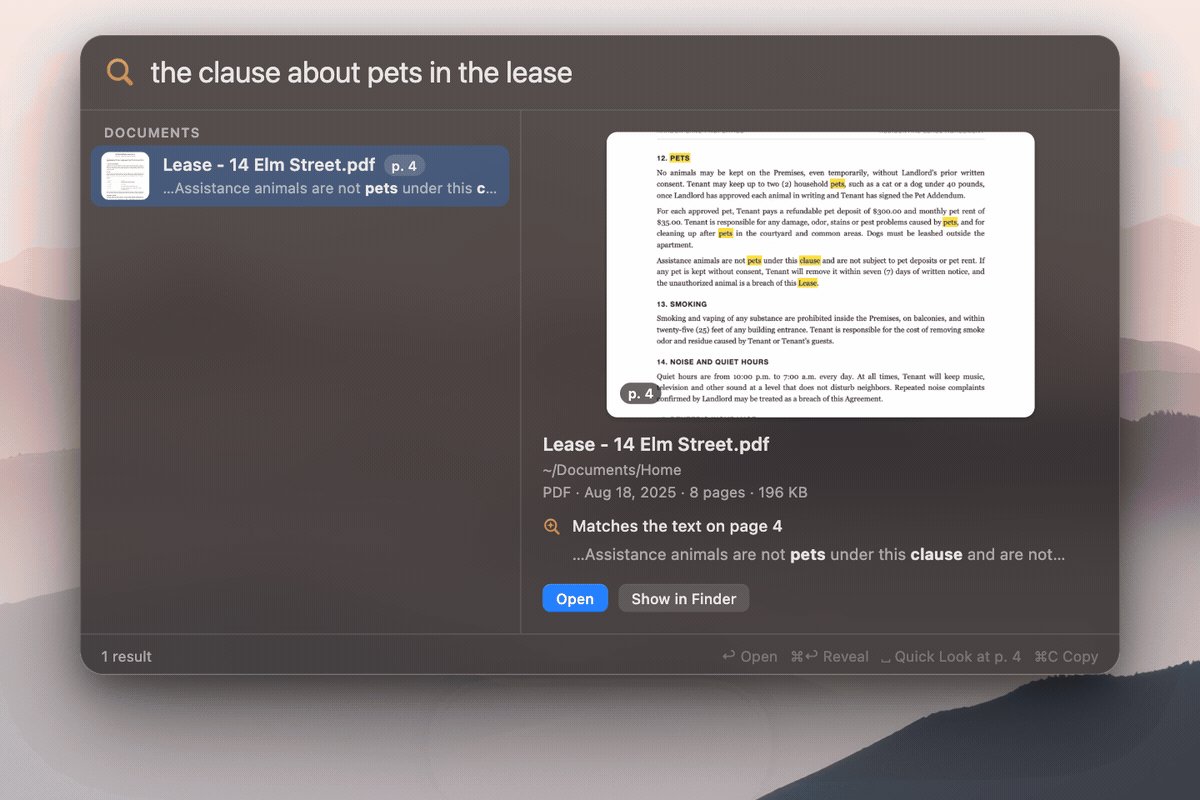
Recall says it "started from DigUp" and ports the design to Linux: a Rust engine over llama.cpp with CUDA, Vulkan or CPU backends, and a GTK 4 front end. Its README reports R@1 0.95 on 22 questions over a generated set of company files, which is a smoke test, not a benchmark, and a 3.2× indexing speed-up on an integrated Intel GPU over the CPU. Its limits section has the sentence that ties this update together: "Sound is matched as sound, not transcribed: Recall finds the moment, but can't quote what was said." A word reader like the one above is the missing piece.
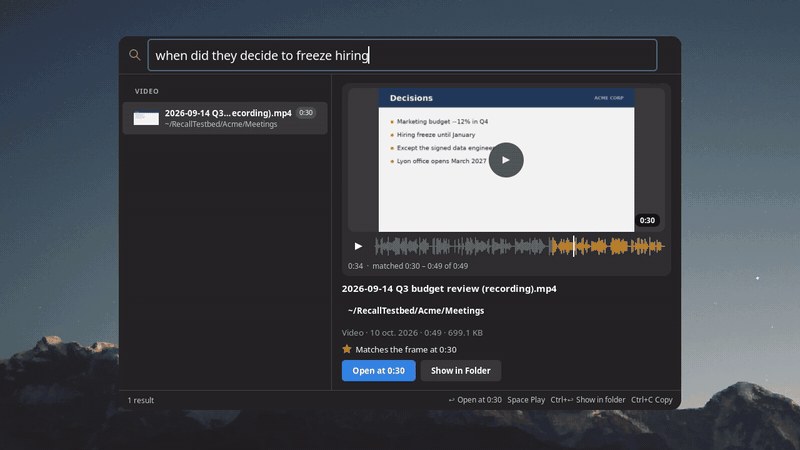
VectorDash does the same on Windows 11, credits DigUp in its acknowledgements, and ships an unsigned installer, as the list warns. The list also points to Local Search, which exposes a Mac index to coding assistants over MCP (snippets then leave the machine), and to Typed Decision, where its entry repeats the card's "roughly 0.5M-parameter head"; the file says about 1.1M, as the section above found.
The runtime table is the useful part for anyone shipping. LiteRT-LM has three separate artifacts, text only (270M), text and vision (440M) and the full 740M, which is the modular loading from earlier done as three downloads; ONNX for Transformers.js from 4.3.1; MLX through mlx-vlm; llama.cpp from pull request 30054; and embeddinggemma.c, a native server whose published benchmarks, the list notes, are still for the first-generation 300M model.
22 October: Google reposts the transcriber, and an open copy runs
Added 23 October 2026.
On 22 October Google's Gemma account asked
"Can you use EmbeddingGemma 2 for Speech-to-Text?" and answered with Shahir's app from the section
above: the experiment "uses
EmbeddingGemma 2's unified audio-text vector space to match speech against text via vector
similarity", and transcribes "an hour of audio in about 13 seconds". The second post in the thread
links Shahir's breakdown. Nothing new is released by Google. The 26-second video is Shahir's own
promo, the same 60 min 30 s speckled-band-librivox-1h.wav, with "not affiliated with Google" in
its last frame; its counter's last visible reading is 13.4 s, which is 271× on 3,630 seconds
(reasoned). So the 288×, the 5% word error rate and the Mac-only binary are still his claims, and I
still can't run them.
What changed since 13 October is that someone else rebuilt it in the open. eg2-transcribe (Apache-2.0) calls itself "an independent reproduction for phones" of Shahir's idea, with training code, an Android app on LiteRT, an iOS and Mac app, and the weights on Hugging Face.
- license
- Apache-2.0
- branch
- main
- tests
- 20 files
- source
- 582.0 kB
- commit date
- 2026-10-16
by size of tracked source at this commit, file counts in brackets; docs, data and vendored trees excluded
local clone, 2026-10-23 at e9c1c26 — branch, commit, commitDate, fileCount, hasTests, languages, license, licenseFile, shallow, testFileCount
shallow clone: counts describe the pinned tree, not the history
The recipe is the one I reverse-engineered from Shahir's app, with one difference in where it taps
the model. The audio tower runs frozen, and its output goes through embed_audio to the 512-wide
"soft tokens" that would normally be fed to the text encoder, 25 a second. A 6-layer, 19.6M-parameter
transformer (reader v2) turns each token into a 768-wide unit vector and a blank score; the logits are
a learned scale (216.35) times the cosine to each of 200,000 frozen word vectors, the LibriSpeech
lexicon embedded by EmbeddingGemma 2 itself with the query prompt. Greedy CTC, no language model. The
repo reports 4.21% WER on LibriSpeech test-clean and 10.42% on test-other, trained on the 960 hours
of LibriSpeech on Colab A100s (reported). Shahir's reader reads layer 11 instead, before embed_audio;
both skip the text encoder at inference.
- task
- automatic-speech-recognition
- library
- litert
- license
- apache-2.0
- largest file
- 307.2 MB
- files
- 10
- downloads
- 0
- likes
- 1
- languages
- en
repo last modified 2026-10-15
This one I could run. On a shared 4-core cloud VM (Intel Xeon at 2.8 GHz, two threads, CPU only,
float32, transformers 5.19.0), with the released reader and google/embeddinggemma-2:
- The repo's numbers reproduce exactly (measured). On its 20 test-clean fixture utterances I got
3.70% WER, 18 substitutions, 1 deletion and 1 insertion over 541 words, the same counts as its
RELEASE.md, with the same errors ("titian holborn" for Holbein, "kio" for chiaroscurists, a word that isn't in the 200,000). On 60 test-clean utterances, 1,314 words, 4.19%, beside its 4.21% for the whole set. - Slow on a CPU (measured). 477 seconds of audio took 364 seconds, 1.3× real time: 0.34 s per audio second in the encoder and 0.42 s in the reader, most of that scoring every frame against 200,000 words. Peak memory was 3.6 GB once I dropped the unused text encoder. The repo's 548× is an M4 Max with the reader on the Neural Engine (reported); the speed is the accelerator's, as I argued above.
Then the question Google's wording raises. Does the shared space match speech to text without the trained reader? Partly, and this surprised me (all measured on the 20 fixtures):
- My own text pipeline reproduces the repo's word table to a cosine of 1.0000, so the words really are EmbeddingGemma 2 text embeddings, the thing I couldn't confirm for Shahir's table.
- Whole-clip retrieval works: each clip's pooled audio embedding picks its own transcript out of 60, 20 out of 20 (cosine 0.86 against 0.62 for the others).
- The pooled vector is a topic, not a transcript. Its ten nearest words average 1.35 that occur in the clip, and they are clusters like "stewed, stew, stews" or "uncontrollable, uncontroll'd".
- A reader with no trained weights at all, pooling 15 soft tokens (0.6 s) through the text encoder, hopping 8, taking the nearest word and merging repeats, gives 80.6% WER. That sounds useless until you read it: "he'e hoped would'st stoved dinner turn's turnip carr's carrots brews pottered potatoes … thick pepper peppered flowered flower fattens sauce" for "he hoped there would be stew for dinner turnips and carrots and bruised potatoes … thick peppered flour fattened sauce".
So Google's sentence is closer to true than I gave Shahir's headline credit for: short stretches of speech do land near their words. What the 19.6M-parameter reader buys is timing and choice, which 40 ms frame owns which word and which of "carr's" and "carrots" was said, and it takes the error rate from about 81% to about 4%. It also answers the reply asking whether you need the candidate text up front: you need a vocabulary, not the transcript, and a word outside the 200,000 can never come out.
One more reply is worth a line. Mohamed Maslooh says the same recipe, with LoRA on the audio encoder and a small CTC head, gives 14% WER on his own Egyptian Arabic at about 160× real time on an RTX 4060. He links no code or data, so it is unverified, but it is the only report so far of the idea working outside English, and it needed the encoder unfrozen to get there.
What I'd do with it
I'd use it for a personal or on-device index of mixed media: notes, screenshots, photos, voice memos, a codebase. The text-first workflow is the real feature. Start with the 271M configuration at 256 dimensions, which is small and keeps 98% to 99% of its text scores and about 97% on code, and add the vision tower when images show up, without touching what is already indexed. If the index outgrows RAM, I'd cut bits before cutting more dimensions; Qdrant's numbers favour 1 bit a dimension at a wider width over a narrower vector with more bits.
I wouldn't pick it for a text-only search service where model size doesn't matter; there are stronger text embedders at 600M. I'd test general-audio retrieval on my own data before relying on it, since the audio tower is a speech encoder that didn't train here and MAEB is its weakest benchmark. And I'd chunk long video and audio deliberately rather than trust the 8,192-token window, because the default preprocessing already does a cruder version of that for you, silently.
Related reading on the site: Gemma 4 for the backbone family and per-layer embeddings, SigLIP 2 for how a contrastive image-text tower is trained and what a Core ML port of one measures, Ovis-Embedding for the 3B omni embedder that reads its vector off the last token instead of averaging, and jev-semgrep for the case against cosine similarity as a search primitive at all.
How I checked
- Parameters. Read the
model.safetensorsheader from the Hub with two range requests (8 bytes for the length, then the 171,296-byte JSON), summed every tensor's shape, and grouped by module prefix. Compared with the Hub API'ssafetensors.total. - Shared weights. Fetched individual tensors' byte ranges from
google/embeddinggemma-2and fromgoogle/gemma-4-E2B,gemma-4-E2B-itandgemma-4-E4B, and compared SHA-1 hashes: 36 audio tensors and the audio output projection (all identical), eight vision tensors and the vision patch projection (all different). Compared the twotokenizer.jsonvocabularies entry by entry. - Mechanism. Read
modeling_embedding_gemma2.py,processing_embedding_gemma2.pyandvideo_processing_embedding_gemma2.pyfrom transformers' main branch as of 6 October 2026, plus Gemma 4'sfeature_extraction_gemma4.py, and the repo'sconfig.json,processor_config.json,1_Pooling/config.jsonandconfig_sentence_transformers.json. Line numbers above refer to those files on that date. I did not run the model. - Charts. Located each dot's centre in the launch blog's 1,000-pixel chart images and interpolated between the y-axis tick marks. Checked the axis against Qwen3-Embedding-0.6B's published MTEB code score. Parameter counts for jina-embeddings-v5-omni-nano and -small come from the Hub API's header totals.
- GGUFs. Parsed the header of every file in
unsloth/embeddinggemma-2-GGUFandggml-org/embeddinggemma-2-GGUFfrom range requests (the text headers are 15.8 MB, the mmproj ones under 60 KB), summed parameters and bytes per quantisation type, and hashed the last 4 MB of each file that both repos ship. Read llama.cpp'ssrc/models/gemma-embedding2.cpp, the symmetric window mask inllama-hparams.handclip_initintools/mtmd/clip.cppat the merge commit of pull request 30054. Comparedunsloth/embeddinggemma-2withgoogle/embeddinggemma-2: the safetensors and tokenizer have the same LFS hashes, so it is a mirror. - Unsloth guide and notebooks. Read the guide's Markdown and the three EmbeddingGemma 2
notebooks in
unslothai/notebooks, including their saved outputs, and checked the text notebook's trainable-parameter count against EmbeddingGemma 1's shapes. I ran none of them. - Qdrant's storage numbers (added 7 October). Read the Qdrant EmbeddingGemma 2 blog and its TurboQuant article, and rendered both charts in a headless browser to capture them. Derived the 8-byte per-vector overhead from the blog's 104, 72 and 40-byte counts; the HNSW link figure is the layer-0 maximum for m = 16, an estimate, not a Qdrant number. Read the X thread and replies through the fxtwitter mirror and looked up arXiv 2608.30384's abstract page. I ran no Qdrant benchmark.
- Typed Decision (added 12 October). Read the model card,
config.json,modeling_gemmadecision.pyandconfiguration_gemmadecision.pyfrommrm8488/embeddinggemma-2-ft-typed-decision; summed the safetensors header's shapes and fetched the byte ranges oftemperatures,head.gateand the two scale scalars. Read the X post, its replies through the fxtwitter mirror, discussions 2, 10 and 17 onLocalLLaMA/typed-decisions, the dataset README and the Hub leaderboard API for that benchmark. Pulled the 400 test rows from the datasets-server API to compute the mean gold entropy, the uniform Brier reference and the texts per case. I did not run the model, and the KL of about 0.12 is derived, not reported. - EG2 Transcribe (added 13 October). Read the post, its thread and the replies through the
fxtwitter mirror. Unpacked the app's DMG with 7-Zip without running it and read the NOTICE and the
binary's strings. Fetched manifests v1 to v5 from
haku-models.tslfiles.org/eg2demo/, and from the current one the Core MLmetadata.jsonandmodel.milof the encoder, reader, scorer and punctuation model, the reader's JSON config and the word list; sizes come from the manifest. Pulled eleven rows ofword_unit_f16.binand the scorer's projection with range requests. Compared 12 float16 norm vectors and four palettized matrices (unpacked from their 6-bit indices and lookup tables) against the same tensors ingoogle/embeddinggemma-2. Read the speed figures off the thread's table, the app's web page and frames of the clip. I ran neither the app nor any model, so the speed, memory and word error rates are his. - awesome-EmbeddingGemma (added 13 October). Cloned the list and the six application repos it
links (DigUp, Recall, VectorDash, SemanticSearchMCP, embeddingGemma2-jeff, embeddinggemma2-search)
and read their READMEs, plus DigUp's
ModelFiles.swift,Model.swiftandSearcher.swift. The two screenshots are single frames of their README animations. I ran none of them. - Google's repost and eg2-transcribe (added 23 October). Read the post, its thread and replies
through the fxtwitter mirror and pulled frames of its video. Cloned
john-rocky/eg2-transcribeate9c1c26and read its README,reader/RELEASE.md,reader_config.jsonand the training, decoding and soft-token code; checked the Hugging Face reader files against theirSHA256SUMS. Ran the released reader v2 withgoogle/embeddinggemma-2in float32 on a shared 4-core Xeon VM (two threads, CPU only, torch 2.14.1, transformers 5.19.0, whose default audio attention the repo requires; 5.20.2 refused it) on the 20 fixture utterances and 40 more from the start of the LibriSpeech test-clean shard the repo names, scoring lowercased words with jiwer. For the zero-shot checks I ran the text encoder on hand-built<|audio>sequences and mean-pooled, which reproduces the word table to cosine 1.0. Downloads were about 2.2 GB and the scratch directory peaked at 3.7 GB; all of it was deleted afterwards. I did not run Shahir's app, the phone apps, or anything on an accelerator. - Not checked. Anything about the training recipe beyond what the files imply; on-device quality at 70 vision tokens; whether vLLM or LiteRT apply the 280-token or the 750-token audio cap; the 191 MB and 567 MB memory figures; the real resident memory of llama.cpp with these GGUFs (the 0.4 GB is a sum, not a reading); whether llama-server embeds images or audio through an mmproj; what the 135 MB in Unsloth Desktop refers to.