2026-10-06 · 31 min · training · pretraining · theory · backpropagation · optimization · transformers
Why read this
Solidtop 85%Derives Dust's per-token zeroth-order estimator, runs a toy that shows why per-token rewards carry it, and prices one update at a few thousand backprop passes.
- Original analysis
- A lasting reference
- A new technique
Training & RLNeeds datacenter GPUsMITResearch paper
How this was scored
- Is it new?
- 2 of 3: A real new idea, method or capability
- Can I trust it?
- 2 of 3: Measures key facts from files, code or configs
- Can I run it?
- 1 of 3: API-only, gated or restrictive licence
- Will I understand it?
- 2 of 3: Mechanism from first principles with figures
- Can I act on it?
- 1 of 3: General advice
- Will it last?
- 2 of 3: A reference for a year or more
- Does it affect many?
- 1 of 3: A specialist community
- Only here?
- 2 of 3: A teardown or measurement few others did
Score 59 of 100, ranked 447 of 701 rated articles. Each question is answered 0–3 by hand, and a 3 is rare. How articles are scored
"Backprop has been the only credit assignment algorithm capable of training large neural nets." That is how Samip Dahal opens the thread announcing Dust, from Q Labs, written with Bishwas Mandal, Serdar Gülbahar and Akshay Vegesna. The claim that follows is that Dust is "the first zeroth-order method to pretrain transformers to approach and sometimes even exceed backprop with large amounts of computation", and that it is "on the order of 1,000 to 10,000x more compute efficient than EGGROLL".
Zeroth-order means the optimizer only ever sees loss values. That family has a well-earned reputation for collapsing in high dimensions, so this is worth taking apart.
I read the post, its appendix, and the released code (qlabs-eng/dust, MIT, commit 2fdb01b). I did not run it: the paper configuration wants eight GPUs per run. Numbers below are labelled reported (Q Labs' figure, not re-run), measured (I read or computed it from a file, the code, or the toy on this page), or reasoned (my arithmetic on the other two).
What a zeroth-order gradient is
Start with any loss over parameters. Nudge the parameters in a random direction by a small step . To first order,
One scalar, the loss change, tells you how much of the gradient lies along . Multiply it back onto and average over directions:
Because , the expectation of is the gradient. That is the evolution-strategies estimator of Salimans et al. (arXiv 1703.03864) and the random gradient-free method Nesterov and Spokoiny analysed. Evaluating as well and using the difference of the pair (antithetic sampling) cancels the even-order terms, so the curvature does not leak into the estimate.
The catch is variance. Each sample is the true gradient's component along one random direction plus everything else that direction carries. For an isotropic Gaussian, the error of has squared norm of roughly , so the cosine between estimate and truth is about
To get a cosine of one half you need evaluations. Dust's base model has 37.7M parameters (reported). Weight-space ES on it would need about 12.6M forward passes per update for a cosine of 0.5, and at 16,384 forward passes the cosine is about 0.02 (reasoned, from the formula above). That is the wall every weight-space method hits.
EGGROLL (arXiv 2511.16652) attacks the cost per member: it makes each perturbation a rank- matrix, so a whole population of perturbed models runs as one batched inference at up to 91% of plain inference throughput (reported, in its abstract). It does not change . Every member is still one sequence of the batch, and the population is still bounded by the forward passes you can afford.
Perturb the activations, not the weights
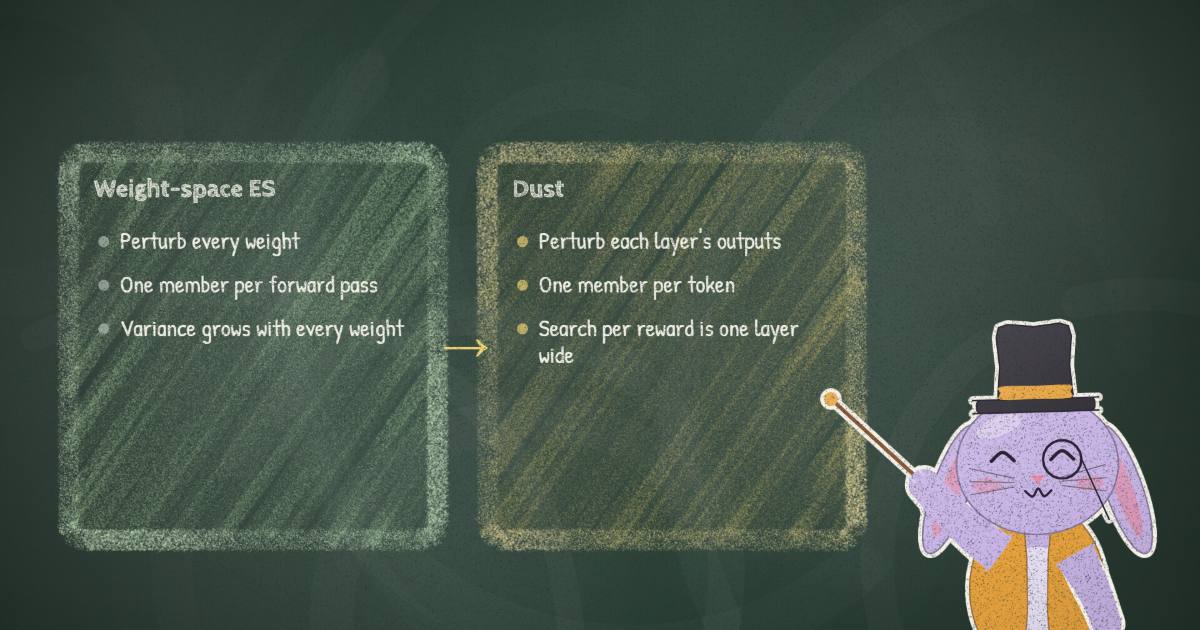
Dust moves the noise. Take one linear layer, , at token . Backprop's weight gradient for that layer is
The input is free: the forward pass already computed it. The only hard part is the output error , which backprop gets from the chain rule. Dust estimates it by jittering the layer's output instead: with , at every token, in one forward pass. The post writes the reward at token as the loss reduction there, plus the decayed reductions at later tokens that the jitter reaches through attention:
Here is the centred loss reduction at token , is the number of draws (one draw is one independent jitter of all tokens), and is a credit decay that is zero for everything except the attention internals. The last equation is the same outer product backprop forms. Only the source of the error differs. This is node perturbation, which Widrow and Lehr described in 1990 and Werfel, Xie and Seung analysed in 2003; the post cites both.
The textbook argument for node perturbation is dimension: a layer's output has numbers and its weights have . The post is candid that this argument, read naively, fails for a transformer. Noise on one sequence is a tensor, which has at least as many entries as the weight matrix once . If you reward that whole tensor with one scalar, you are back to searching a space as big as the weights.
What rescues it is the per-token reward. Each token's loss mostly reflects its own jitter, so each token's noise is scored by its own number. The search per reward is then -dimensional, and the tokens of a sequence are separate population members evaluated in the same pass. Q Labs calls that a virtual population. A sequence of 2,048 tokens is 2,048 members, where EGGROLL gets one.
Try it: three estimators, same forward passes
The widget below is a toy, not the paper's model. One linear layer, 32 tokens, a quadratic loss at each token. Three estimators get the same number of forward passes :
- weight-space ES, with antithetic pairs, so pairs, each scored by the summed loss;
- activation noise with one reward per pass: every token's output is jittered, and all of them are credited with the summed loss change;
- activation noise with one reward per token: Dust's direct draws with , each token's noise credited with its own loss change.
The two activation estimators rebuild the weight gradient exactly as Dust does, as . The curve is the cosine to the true gradient.
The toy reproduces the post's dimension argument (measured, one seeded run per width). At width 16, with 256 forward passes, weight ES reaches a cosine of 0.536 and the one-reward activation estimator 0.511, because the second searches 512 numbers per reward against the first's 256. They are equally hopeless. The per-token estimator is at 0.968 with the same passes. At width 64 the gap is wider: at 2,048 passes weight ES sits at 0.442, one reward per pass at 0.557, one reward per token at 0.984. The per-token curve barely moves as the width grows, because what it searches per reward is , not and not .
The toy is kind in two ways. Its token losses do not interact, so the per-token estimator suffers none of the cross-token interference attention creates in a real model; that interference is what most of Dust's engineering is for. And its loss is exactly quadratic, which flatters antithetic weight ES, since the pair difference is then exactly the directional derivative.
What the released code actually does
The repository is small: dust.py is 607 lines and model.py 201 (measured). The model is the modded-nanoGPT kind of decoder: eight pre-norm blocks of width 512, squared-ReLU MLP, rotary embeddings with normalised queries and keys, value embeddings on alternate blocks, a soft-capped untied head (reported in the appendix, and it matches model.py). It is the nanoGPT speedrun lineage. Nothing in dust.py calls backward(): the model is built with requires_grad_(False) and the update runs under torch.no_grad() (measured).
One update in DUST.step, as I read it:
- A clean forward caches every
LinearandEmbedding's input and output through forward hooks, plus the per-token losses. - Direct draws.
direct_errorssets a jittersigma * aon the chosen sites, reruns the forward, and computesreward = clean_loss - perturbed_lossper token. When several draws share one forward (the batch repeatednreptimes), the reward is centred across them; withnrep = 1it is not. The error estimate accumulates-reward * a / sigma. These rewards use the token's own loss only, so . The attention and MLP output projections (the "writers" into the residual stream) are jittered together in one stream, the MLP's first layer in another, all at . - Attention outputs, block by block, with in the first half and in the deeper half, because, in a code comment's words, "The deeper half moves the loss too little at 0.2 for a readable reward". These estimated errors become targets.
- Attention internals (queries, keys, values, the value-embedding gate and the value embeddings) never touch the loss.
local_errorsrecomputes only that block's attention from cached activations with a jitter and scores the change against the estimated attention-output error, the post's . Keys, values, gates and value embeddings sum the scores of later tokens decayed by ; queries keep their own token's score. - The head is jittered on the cached logits, one 256-column slab of the 4,096-token vocabulary at a time, recomputing only the cross-entropy from cached partial sums.
- The 2L residual-mix scalars are the only weights trained by weight-space ES, with two-sided pairs.
reassembleturns each error into a weight gradient withtorch.einsum('btd,bti->di', error, x), or a scatter-add for an embedding. Every estimate is divided by the token count, written into.grad, and SGD with momentum takes the step.
So the gradient with respect to the weights is not inferred from weight noise at all. It is the outer product backprop forms and the animation shows, with only the error vector coming from the population.
The population count is narrower than it sounds. In recipe(), at population 256 the writer and MLP-hidden streams each get 110 draws spread over the eight blocks (38, 32, 16, 10, 6, 4, 2 and 2, tilted toward the first blocks), the attention outputs 26 and the token embedding 10, which sums to 256 (measured). At 16,384 everything scales by 64: 7,040 + 7,040 + 1,664 + 640 = 16,384, matching the appendix's Table 3 (measured). The head's 65,536 slab draws and the attention-internal draws are on top of ; the post says they are a small share of an update's compute (reported).
One oddity: the token embedding trains at a learning rate of 1000 under SGD, for Dust and backprop alike (measured in make_optimizer, matching the appendix).
The results, checked against the tables
The setup (reported): FineWeb with a 4,096-token BPE tokenizer, batches of 8 sequences of 2,048 tokens, one epoch, SGD with momentum at a constant learning rate, three seeds per cell, every method tuned per token budget and population. In the released config, the 1M-token budget is 61 steps and the 10M budget 610 (measured).
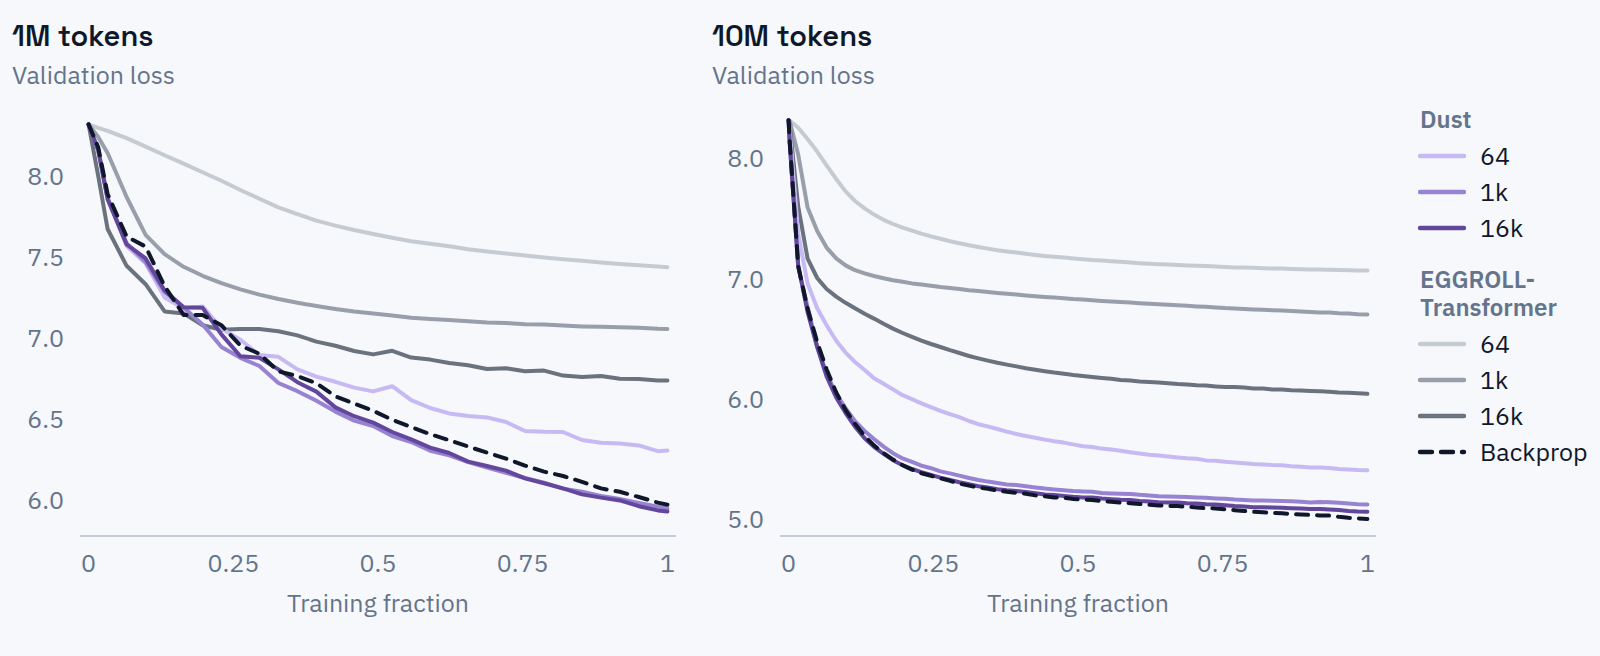
The headline ladder is Table 1 in the appendix. Test loss at the best-validation checkpoint (reported):
| Budget | Dust, 64 | Dust, 1k | Dust, 16k | Backprop | EGGROLL, 16k |
|---|---|---|---|---|---|
| 100k tokens | 7.240 | 7.151 | 7.170 | 7.216 | 7.263 |
| 1M tokens | 6.290 | 5.934 | 5.916 | 5.959 | 6.708 |
| 10M tokens | 5.397 | 5.111 | 5.049 | 4.989 | 6.033 |
| 20M tokens | 5.265 | 4.960 | 4.802 | 4.633 | 5.865 |
"Beats backprop at 100k and 1M tokens" holds in the table. The best Dust cell is 7.151 against 7.216 at 100k, and 5.911 (at 4k draws) against 5.959 at 1M, margins of 0.065 and 0.048 nats (reasoned). "Close at 10M and 20M" holds too, with gaps at 16k draws of 0.060 and 0.169 nats (reasoned). The 20M claim that the asymptote sits below backprop rests on a power-law fit through five cells that are still falling: limit 4.431, 95% interval 3.89 to 4.58, against backprop's 4.633 (reported). The post itself reads that as "evidence that the gap keeps closing with population rather than as a measured limit". So should you.
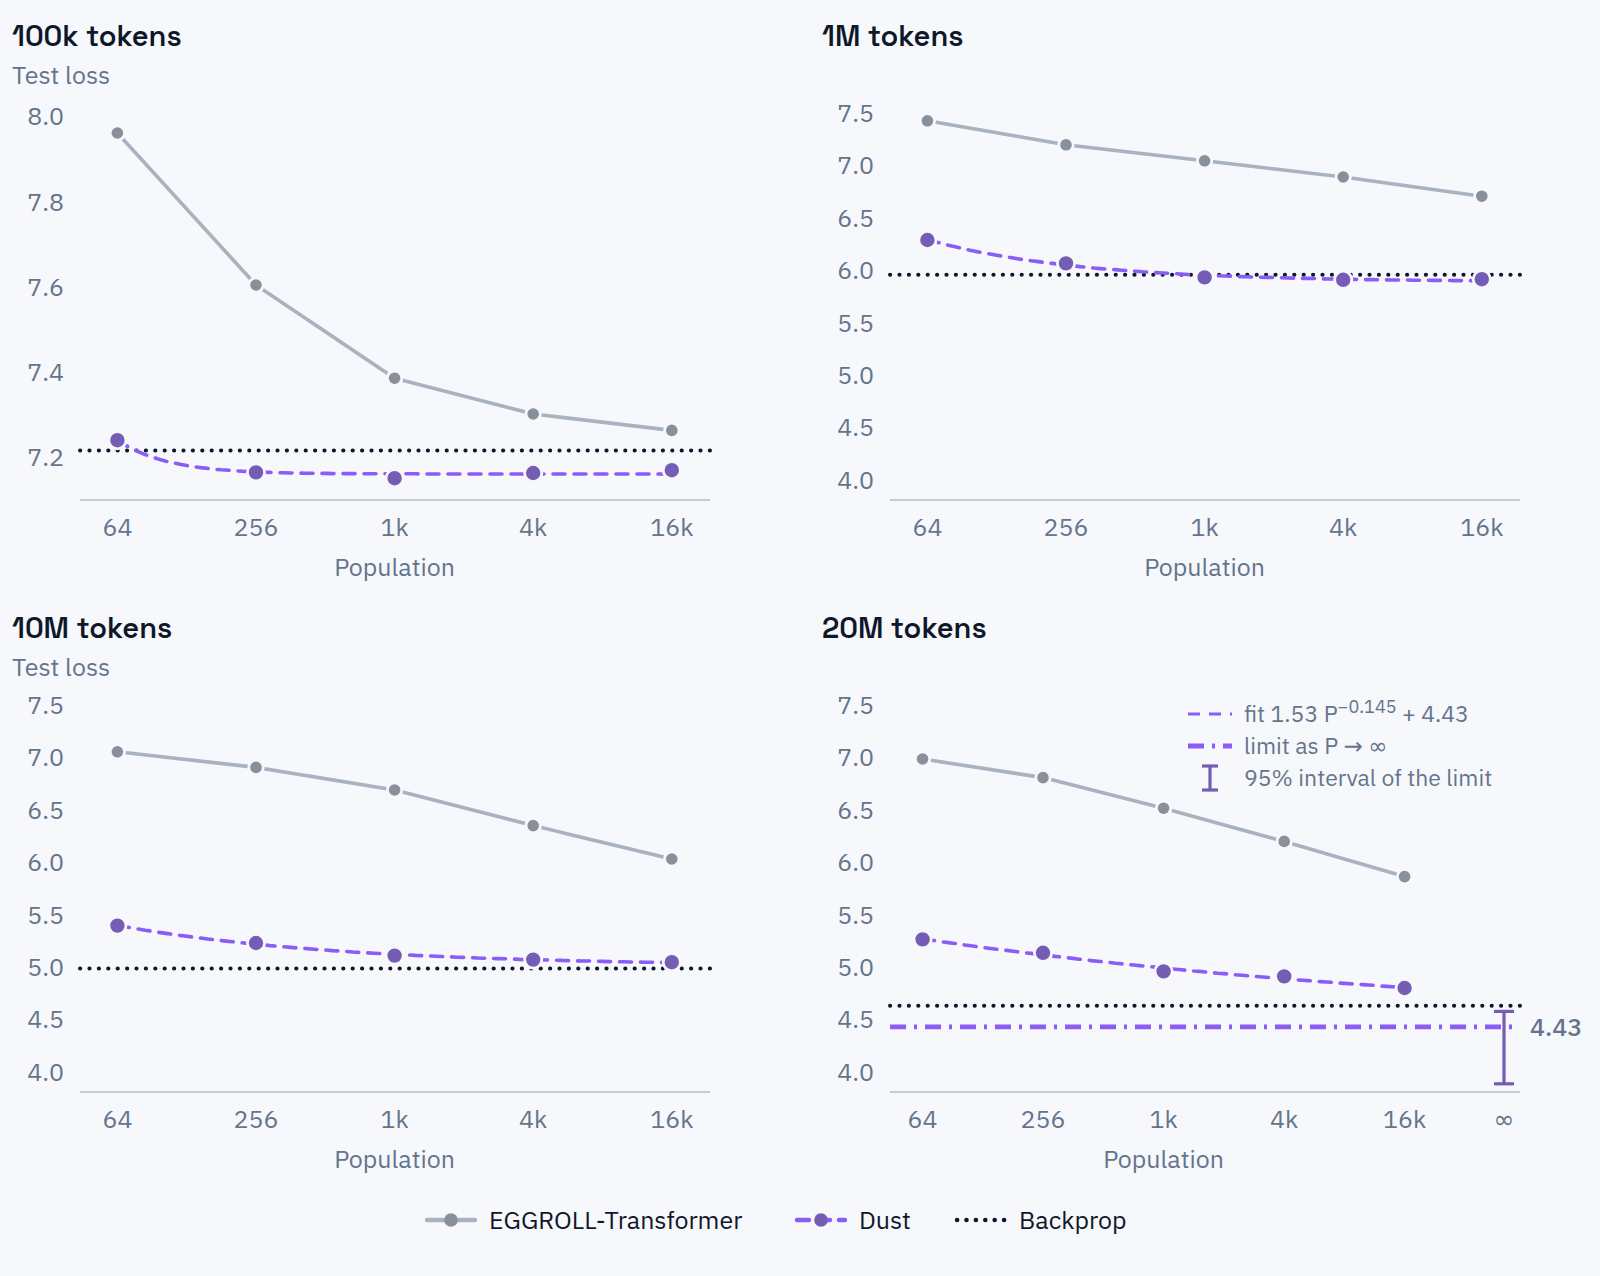
The EGGROLL comparison is two different claims. The measured one is in the table: EGGROLL at 16k forward passes never reaches Dust at 64 draws at any budget. At 100k tokens it is 7.263 against 7.240, 0.023 behind, which the post rounds to "within 0.02"; at 1M, 10M and 20M it is 0.4 to 0.6 nats behind (reported). The "1,000 to 10,000x" figure is not measured; the post says "based on our extrapolations". Appendix Table 2 extends EGGROLL's ladder by four kinds of fit to the population it would need to match Dust at 64 draws. The main fits put it between 3,100x and 23,000x that population. Refitting with one population left out widens the range to 54,000x at 10M, and one such refit at 1M never gets there at all (reported). Q Labs' own caveat is that, from 256 draws up, a Dust draw costs less than an EGGROLL forward pass, so the comparison is lenient to EGGROLL (reported).
Under Adam, at 1M tokens only, the shape repeats. Dust's power-law limit is 5.248 with an interval of 5.17 to 5.30, below backprop; EGGROLL's Adam ladder lands within 0.01 of its SGD ladder at every population (reported). That is one budget, and the Adam runs give the token embedding extra draws, about 1.4x the listed population in total.
Bigger models need fewer draws, up to a point
The claim I found most interesting is the one about size. The variance argument above says a bigger model needs a bigger population. Q Labs trained four sizes at a fixed 10M tokens: 2.0M, 7.3M, 38M and 243M parameters (2, 4, 8 and 16 blocks at widths 128 to 1024).
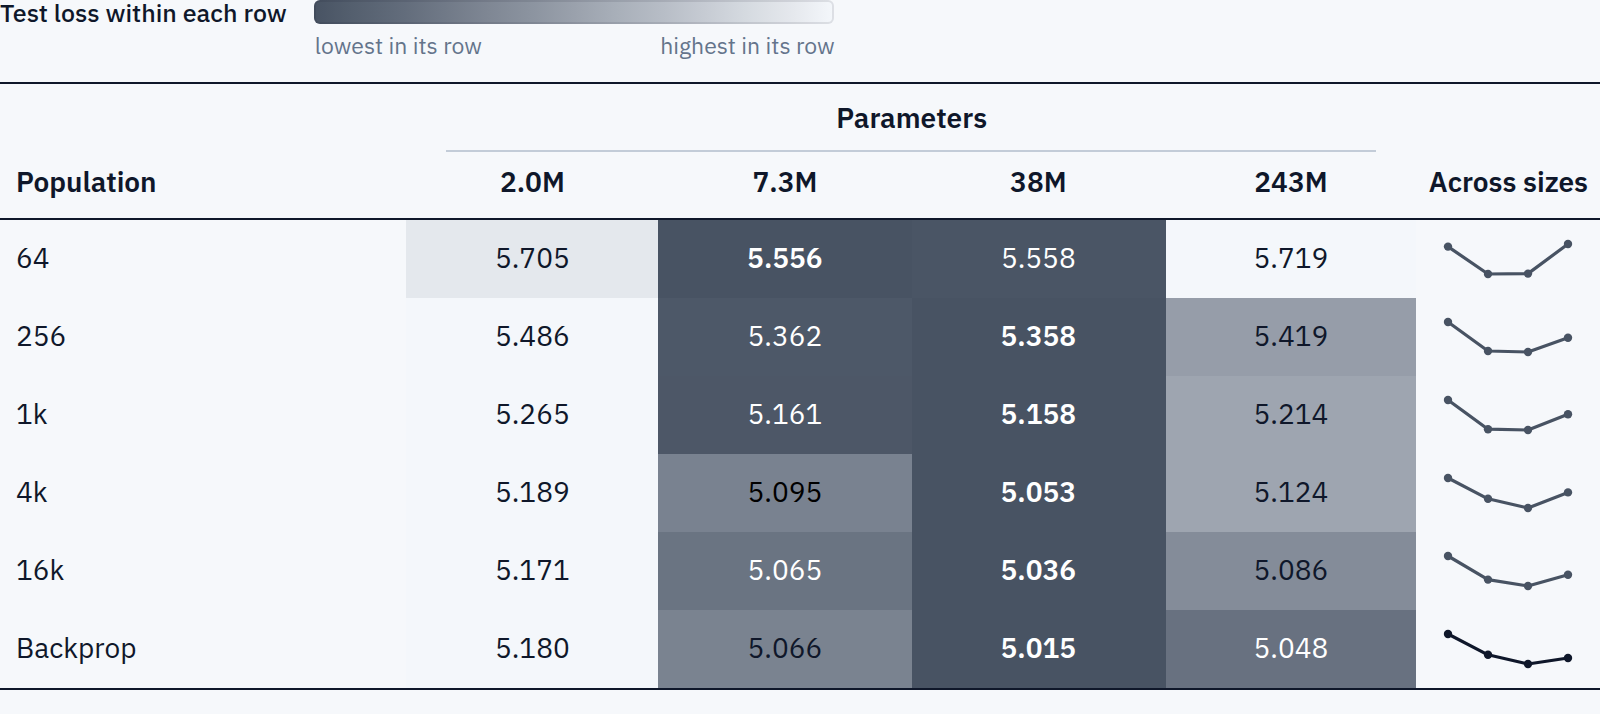
Read straight off the table (measured from the published cells):
- The 243M model beats the 2.0M model at four of five populations; at 64 draws it loses, 5.719 to 5.705. "Beats one 120x smaller at most population sizes" holds. The ratio is 121.5x (reasoned).
- The best size from 256 draws up is 38M, not 243M. The 243M model is worse than both 7.3M and 38M at every population. So loss falls with size "up to a point", as the post says, and the point is 38M at this budget.
- From 1k to 16k draws, the two larger models improve by 0.122 and 0.128 nats and the two smaller by 0.094 and 0.096, about 30% more (reasoned; the post says "about 30% more").
- The gap to backprop at 16k draws grows with size: Dust at 2.0M is 0.009 nats below backprop, at 7.3M 0.001 below, at 38M 0.021 above, at 243M 0.038 above (reasoned). The post calls this growth "barely noticeable".
Q Labs' reading is that overparameterization gives search "a bigger space with better geometry". My reading is narrower. Per-token rewards make the search dimension per reward the layer's output width, which for square layers grows roughly like rather than like , so the variance penalty for size is mild. A wider model is also a better model at a fixed token count, and that gain can outrun the penalty. One more caveat from the appendix: the size study predates the main protocol and uses the old token-embedding learning rate, chosen because at 1000 "backprop shows no clear separation between model sizes".
Backprop-like gradients, measured as a cosine
The last claim is that backprop-like gradients emerge from the population. Q Labs measured the cosine between Dust's estimate and the exact backprop gradient on the same batch, on backprop-trained checkpoints at 10M, 100M and 1B tokens, with populations from 64 to 128k.
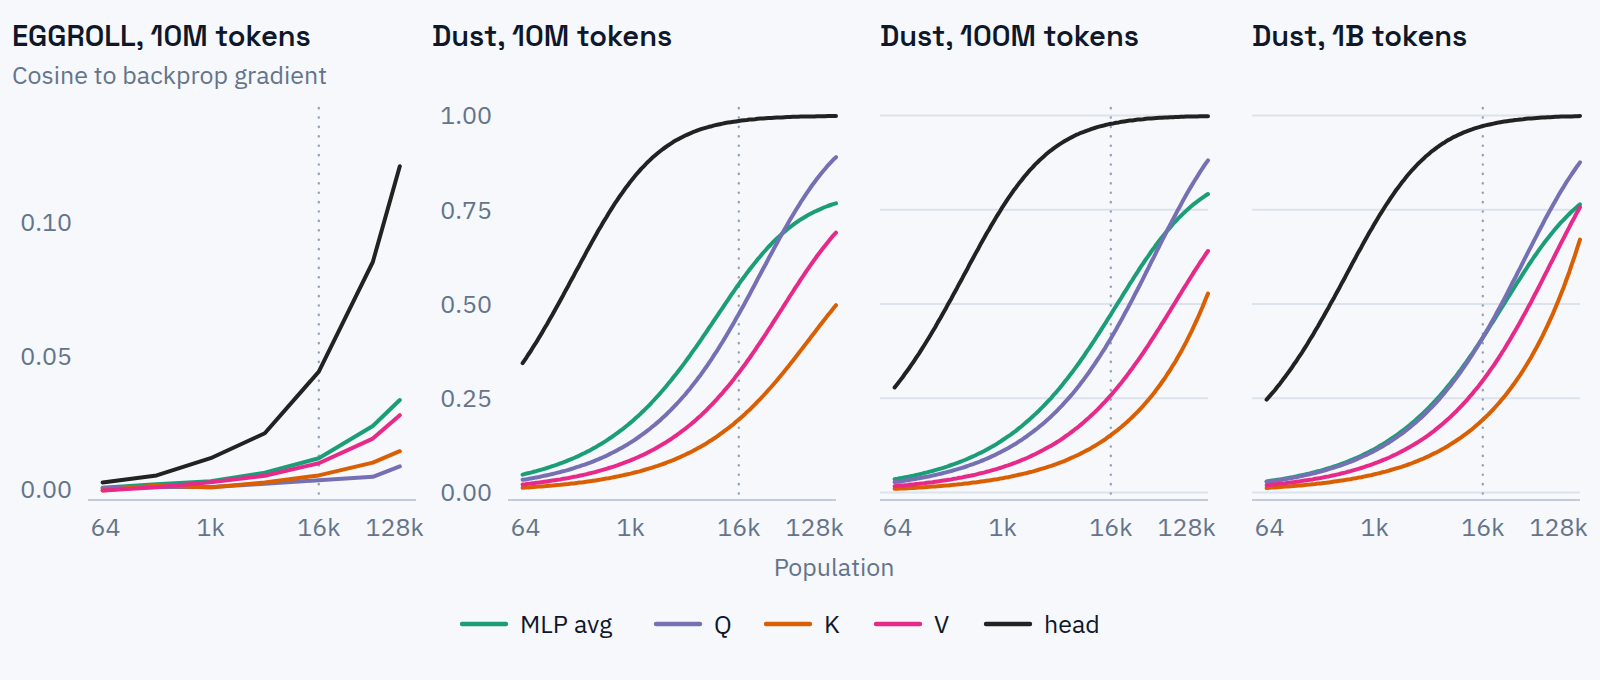
A two-parameter law, , fits each layer type with RMSE under 0.06 (reported). It is the same shape as the estimator variance above, with playing the effective dimension and a ceiling below one. Plugging the appendix's Table 8 fits for the 100M-token checkpoint into the law at the training population of 16,384 (reasoned): MLP output 0.51, attention output 0.57, token embedding 0.49, attention values 0.26, attention keys 0.16, and the head 0.98. The keys' fitted is 616,595, which is why their curve has barely left the floor at 16k. EGGROLL, measured the same way, stays below 0.05 at 128k for every layer type except the head (reported).
Two things to keep in mind. These are cosines on backprop's checkpoints, not along Dust's own trajectory. And a cosine of 0.5 is a modest alignment; SGD with momentum averages over steps, which is part of why it trains anyway. The post's further point, that Dust's gradients are "useful but different" and that the difference is sometimes better, is an observation from the ladders, not something the cosine study tests.
What it costs
This is where the result needs the most care. The post says it plainly: "We must have orders of magnitude more compute efficiency before Dust becomes a practical alternative to backprop at current levels of compute." Neither the post nor the code reports wall-clock time against backprop.
From the code I can estimate the forward work per update (reasoned). A draw at block only needs blocks through 8 rerun, and counted that way, with the 1M-token allocation at 16,384 draws, the writer and MLP-hidden streams, the attention outputs and the token embedding cost about 13,000 forward-equivalents, in units of one full eight-block forward. The released dust.py does not take that shortcut, though: direct_errors calls the whole model for every draw, so the real count is 16,384 full forwards (corrected 2026-10-13; I first wrote that a draw reruns only the later blocks). Backprop costs roughly three forwards' worth. That puts Dust at about 4,400 to 5,500 times backprop's compute per update, depending on whether the shortcut is taken, before counting the head and attention-internal draws. At 256 draws the same arithmetic gives 207 to 256 forward-equivalents, around 70x to 85x. The paper's eight-GPU runs split the draws across GPUs; they do not make them cheaper.
The regime is also early. The best losses here are 4.6 to 4.8 nats at 20M tokens, against a uniform-prediction loss of (reasoned). One reply to the thread made the point that at 5 nats most of the signal is still pushing unlikely tokens down, and that feature learning has barely started. The tuned grid matters too: backprop here is SGD with momentum at a constant rate, not a tuned Muon or AdamW schedule. The Adam ladder helps, but only at 1M tokens.
A week later: Noise
Seven days after Dust, Samip Dahal posted again: "Replacing backprop with zeroth-order optimization is inevitable. Introducing Noise: a speedrun for pretraining without backprop." The pitch is that another 1,000x on top of Dust is possible, and that getting it "will require co-designing credit assignment, optimizers, architectures, and eventually, hardware". Noise is the harness for that, from Serdar Gülbahar and Bishwas Mandal as core contributors, with Akshay Vegesna and Dahal (qlabs-eng/noise, MIT, and a short post).
I went back to it for one reason. Last week I said I wanted to see a budget where backprop gets below 4 nats. Noise publishes exactly that number, and it is not flattering to Dust.
What the rules pin down
The model, the data and the score are frozen at Dust's 10M-token cell. Final weights have to load into utils/model.py with a strict state-dict match, so the architecture is the 37.7M-parameter GPT from above and nothing else. Training reads data/train.pt, 4,880 sequences of 2,048 predictions (9,994,240 tokens), and each sequence may feed at most one update. The score is utils/eval.py: mean next-token cross-entropy over the 1,114,112 predictions in data/val.pt, computed on the final weights. prepare_data.py checks both files against pinned SHA-256 hashes of their tokens, so two people's "same data" really is the same.
Two tracks share those rules. Track 1 is the lowest validation loss after one epoch on one 8xH100 node, with no time limit. Track 2 is the shortest time on that node to reach 4.2, timed from the first update to the end of the last, with an untimed warmup allowed as long as training then restarts from a fresh state. A record is a PR, and the training script is the record. That is the modded-nanoGPT recipe, transplanted, and I think it is the most useful thing Q Labs could have shipped after the paper: a ladder like Dust's is easy to argue with, a script that loads into a fixed model and gets a number is not.
The one rule that needs judgement is the obvious one. No backpropagation means "no autograd (reverse or forward mode) and no hand-written backward pass", and entries are "judged by the spirit of this rule". Banning forward mode matters. A Jacobian-vector product gives an exact directional derivative for the price of about one forward, which is the forward-gradient trick, and without that clause it would be the first thing anyone submitted. What stays allowed is everything Dust already does: initialization, batch size, data order, and how you spend your forward passes are all free.
One difference from the paper is easy to miss. Dust's tables report test loss at the best-validation checkpoint, averaged over three seeds. Noise scores the final weights of one seed-0 run, with checkpoint selection on validation loss banned. So Noise's numbers and the paper's don't line up exactly: Dust with SGD at 16k is 5.058 here against 5.049 in Table 1, and backprop with SGD 5.007 against 4.989. That is the protocol, and the final-weights version is the stricter one.
The board as released
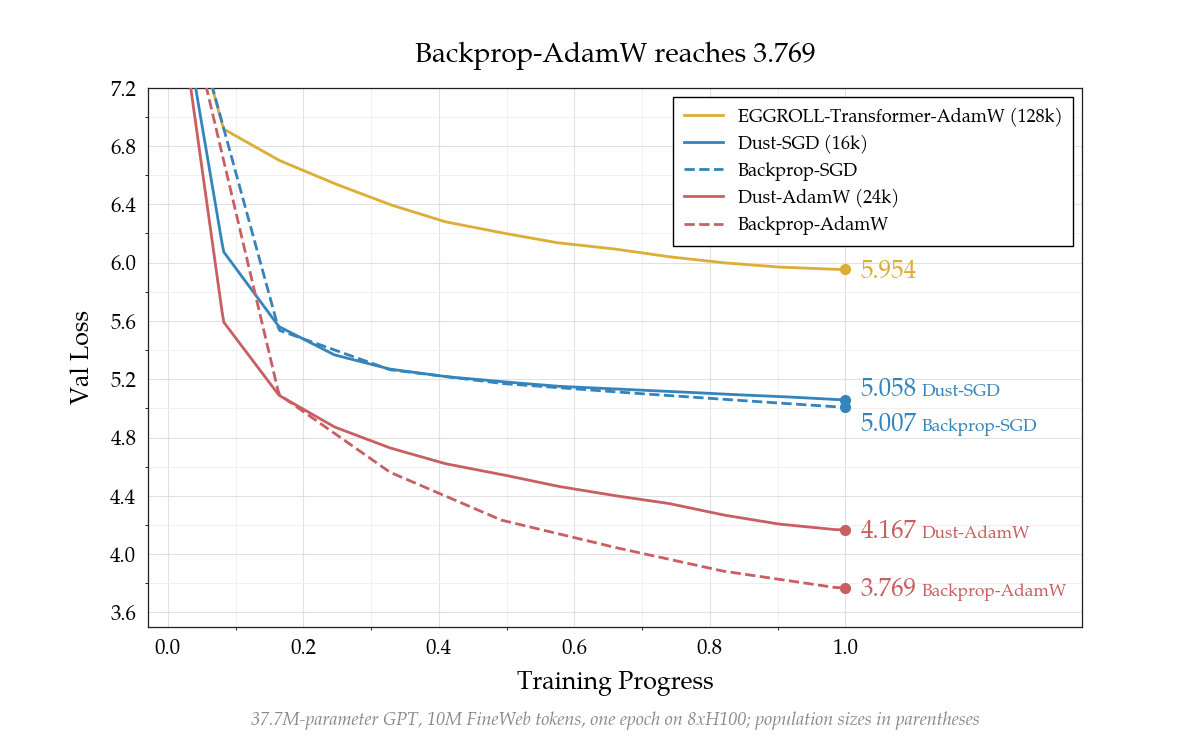
The README lists three track-1 entries. EGGROLL with Adam and 128k antithetic pairs reaches 5.954 in 5.33 hours. Dust with SGD at 16k, which is the released dust.py unchanged, reaches 5.058 in 1.32 hours. Dust with Adam at "24k population" and a learning-rate cooldown reaches 4.167 in 1.76 hours, and holds both tracks. Backprop sits outside the competition as a reference: 5.007 with SGD, 3.769 with Adam and a cooldown.
Put those side by side and the story of last week shifts. Under SGD, Dust is 0.051 nats behind backprop, which is the "rivals backprop" result. Under AdamW it is 0.398 behind. Adam bought backprop 1.238 nats and Dust 0.891. So most of the "matches backprop" headline was a statement about SGD with a constant rate being a weak optimizer, which I suspected last week and which Noise now measures. Q Labs doesn't hide this: the README says Dust "still trails backprop under Adam", and the post's own chart is titled with backprop's number. It also sits awkwardly with the paper's Adam result, where Dust's fitted limit at 1M tokens landed below backprop's. Ten times the tokens and a final-weights score, and the gap is open again. Those are different budgets and protocols, so this is not a contradiction, but it is the first time the Adam comparison has been made at a budget where the model learns something.
The speedrun target, 4.2, sits 0.033 nats above the only entry that reaches it. Track 2 is therefore "beat 1 hour 46 minutes", for now. Backprop with AdamW, reading its dashed curve off the chart, crosses 4.2 a little past the halfway point of the epoch; nobody lists how long that takes in wall-clock, which leaves the reply that asked "What's the wallclock time vs backprop?" unanswered.
What changed inside the Dust baseline
The record script is train/val/run.py, 584 lines; train/speedrun/run.py differs from it only in a TARGET = 4.2 constant and the logging. I diffed it against the released dust.py, and the changes are worth more than the README's one-line description of them.
The optimizer is AdamW with betas of 0.7 and 0.95, a base rate of 0.0015, no weight decay, the token and value embeddings at 300 times the base rate and the residual-mix scalars at 30 times. The rate holds for the first 70% of the epoch and then decays linearly to zero. The comment on that warmdown field is the most interesting line in the file: "the noisy estimate leaves a loss floor that decaying the rate lowers". A zeroth-order gradient has a variance floor that no amount of steps averages away at a fixed rate, and annealing is the classic answer to it. Low betas fit the same picture: 0.7 for the first moment is short memory, which you want when the estimate is noisy but unbiased and you'd rather not drag stale noise forward.
Every jitter doubled. The direct draws use where dust.py used 0.2, the deep attention outputs and the token embedding 0.8, the head and the attention internals 0.1 instead of 0.05. The code's own reason is short ("Noise scales are twice the SGD recipe's under Adam"). My reading is that Adam divides each coordinate by its running RMS, so the overall size of the estimate stops mattering and only its signal-to-noise does; a larger jitter moves the loss further above bfloat16 rounding, at the price of more curvature bias, and Adam lets them take that trade.
The first block now uses the credit decay from the post's formula on its direct draws, a reward-to-go with , because, as the comment puts it, "its jitter mostly pays off at later tokens". In dust.py every direct draw used , so this is the first time the decayed reward reaches anything outside attention.
The allocation flattened. The SGD recipe tilted draws toward early blocks; under Adam every block gets the same count, the MLP hidden layer and the attention outputs get twice the writers' draws, and the token embedding gets a quarter of what the tuned 16k cell had, because "at 10M tokens the cut costs nothing while saving about 30% of the time". The value embeddings take 4,608 of the 7,168 attention-internal draws per block at that cell's scale.
I tried to reproduce "24k" from recipe(1.5) and couldn't. The direct-loss draws come to 3,072 for the writers, 6,144 for the MLP hidden layers, 6,144 for the attention outputs and 3,072 for the token embedding, 18,432 in all, plus 73,728 head draws on cached logits and 10,752 attention-internal draws per block. "24k" reads as 1.5 times the "16k" name of the cell the recipe scales, and the Dust post already warned that its Adam runs counted the token embedding's draws differently. It is a label, not a count.
The biggest change is plumbing. dust.py adds jitter through forward hooks and calls the whole model for every draw. run.py caches each block's input on the clean pass and reruns only the blocks from the jittered one onward, through a torch.compiled block_forward. Only the token-embedding draws still pay for the full network. Counting the work that way, one update is about 11,712 forward-equivalents over the 8-sequence batch, against 16,384 for the SGD baseline, even though Adam's recipe has more draws. At 1.76 hours over 610 updates, it runs at about 10.4 seconds an update on eight H100s.
The EGGROLL baseline, for the record
train/val/eggroll.py is the weight-space comparison, rebuilt for this model. Every matrix and embedding gets a rank-1 perturbation , the perturbed weights are never formed (it computes instead), members come in antithetic pairs, each pair is evaluated on one training sequence, and z-scored pair differences weight the noise into a gradient that Adam follows. The chart's "128k" is pairs: 131,072 of them, so 262,144 one-sequence forwards per update, or 32,768 forwards over the full batch. With almost three times Dust's forward work and three times its wall-clock, it ends 1.787 nats behind. The weight-space wall from the start of this article is still there.
What I make of it
The rules are good and the baseline is honest. What I'd push on is the framing. "Inevitable" is a prediction, and the evidence on the board is a 0.4-nat gap at a few thousand times backprop's forward work per update. Backprop's whole epoch here is about PFLOP, which is seconds on one H100 at realistic utilisation; Dust's record takes 1.76 hours on eight. The "another 1,000x" in the announcement doesn't say 1,000x of what, but if it means compute, a thousandfold cut on roughly 11,700 forward-equivalents per update lands at about 12, within a factor of four of backprop's three. That would be a real result. It would also be about three orders of magnitude from where the code is today.
The README states the goal plainly: "beat backprop by a large margin." The record to watch is therefore not 4.2 but 3.769. And the constraint I most want relaxed is the fixed architecture, because the argument for searching instead of differentiating was always about models backprop can't train, and a fixed differentiable GPT is the one place where backprop is guaranteed to be the better tool.
Where it sits
Dust is honest about its lineage. Node perturbation dates to Widrow and Lehr; GEMINI (Le Cun, Galland and Hinton, 1988) injected noise into hidden layers; Ren et al. scaled forward gradients with local losses; MeZO fine-tunes with forward passes alone; and Zoop used output perturbations for fine-tuning; a reply to the thread linking that paper said they tried "something very similar last year but only saw it working on finetuning". Another reply pointed to Nesterov's random gradient-free methods and to a functional version for infinite-dimensional spaces (arXiv 2512.20566), from one of the authors of the functional gradient descent paper covered here. That work is a related estimator, not a source for Dust.
What is new is the combination: per-token rewards as a population axis, separate passes per layer type to keep interference down, attention internals credited through an estimated local target, and a tuning loop that maximises cosine to backprop on one batch before any training. The post's motivation is not efficiency. It is that a search-based optimizer does not need differentiability, so it could train looped or program-in-the-loop models that backpropagation through time struggles with. None of that is tested here. On a smaller scale, the same trade, evaluations instead of gradients, shows up in Sakana's Fugu, where CMA-ES tunes a coordinator over ten thousand parameters.
Last week I asked for three things: a budget where backprop gets below 4 nats, wall-clock next to backprop on the same GPUs, and a model only Dust can train. Noise delivered the first, at 3.769, and Dust sits 0.398 nats behind it under the same optimizer. The other two are still open. Dust remains the best evidence I have seen that zeroth-order credit assignment can follow backprop through transformer pretraining; Noise makes it measurable how far it still has to go, and what it costs is still its main problem.
How I checked the Noise update
I read the announcement thread and its replies through the fxtwitter mirror, the Noise post, and the repository at commit 00ca1d2: the README's rules and tables, both track scripts (which diff shows are identical apart from the target and logging), eggroll.py, utils/eval.py and utils/prepare_data.py. I compared the record script line by line against dust.py at b20f7c0, whose dust.py is unchanged from the 2fdb01b I read last week. The draw totals and forward-equivalents are my arithmetic on the recipes, with a draw at block of 8 costing of a forward when only the blocks from on rerun. I ran nothing: every loss and time in this update is Q Labs' own, from a single seed-0 run per entry. The chart frame is the final frame of the README's GIF, and the video is the one attached to the post.